What the Transformer Paper Actually Says
The 2017 paper "Attention Is All You Need" by Vaswani, Shazeer, Parmar, Uszkoreit, Jones, Gomez, Kaiser, and Polosukhin is 15 pages long and changed how every major language model gets built. It introduced the Transformer architecture, which replaced recurrent and convolutional structures with pure self-attention mechanisms. Before this paper, sequence-to-sequence models relied on LSTMs or GRUs with an encoder-decoder structure and a bottleneck context vector. The Transformer removed that bottleneck entirely. It also introduced multi-head attention, positional encodings, and the decoder stack that still underpins GPT-style models today. If you are looking for the paper itself, a freely available copy can be found at arxiv.org/abs/1706.03762. Search for Attention Is All You Need Pdf if you want a local copy, but the arXiv link is the canonical source and stays up to date.
How the Architecture Actually Works
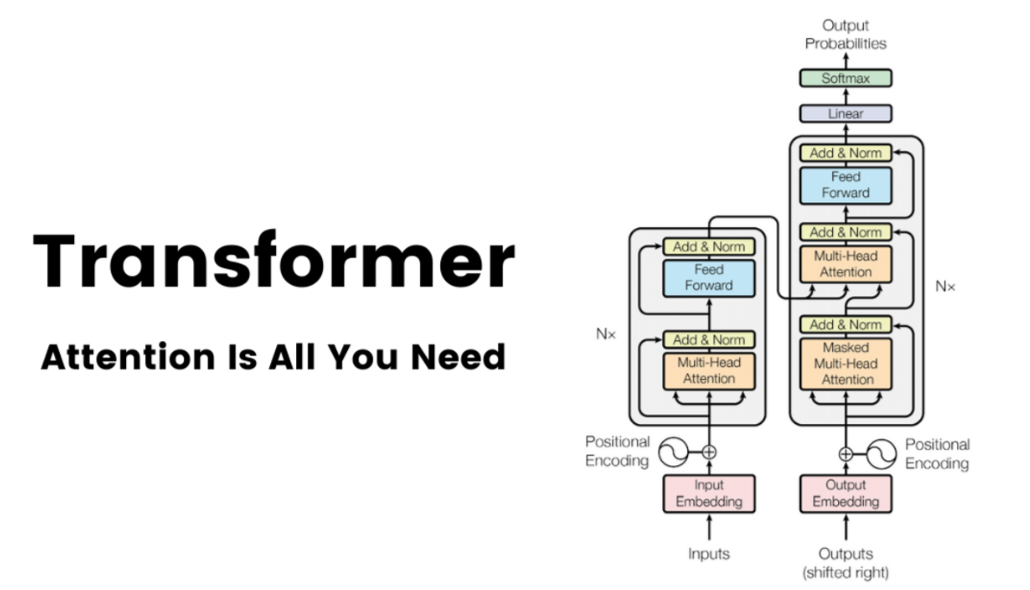
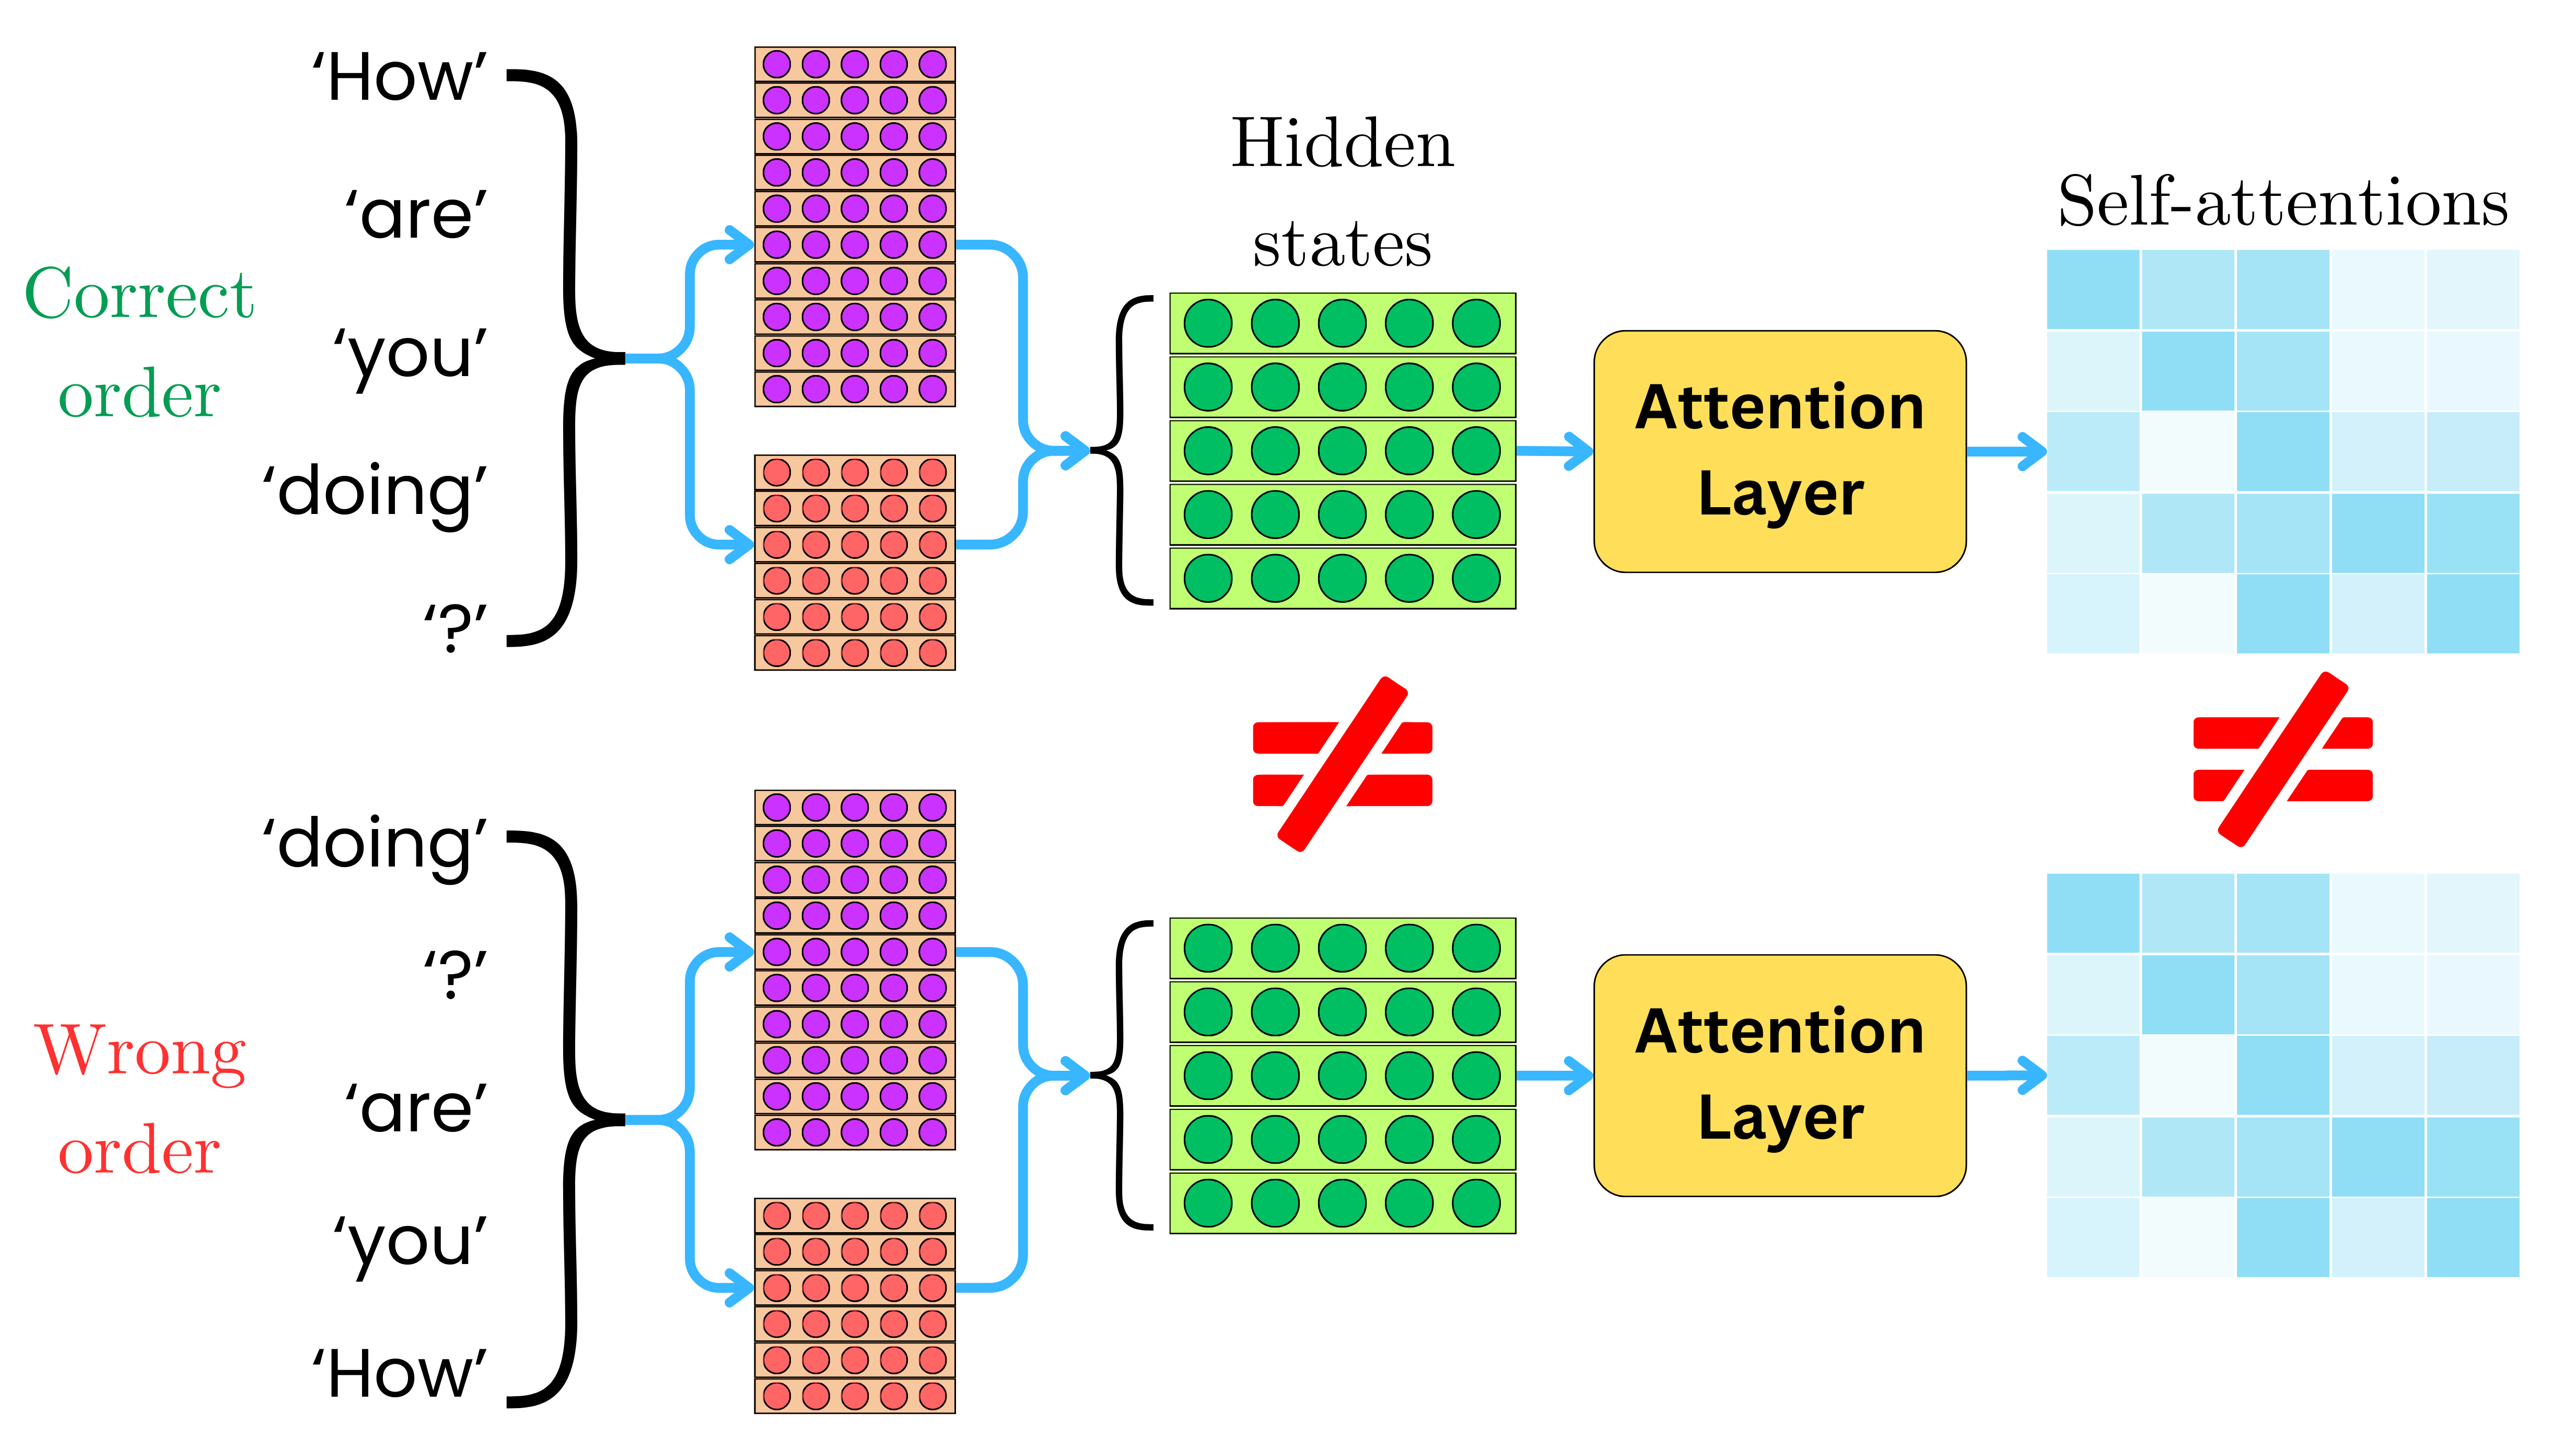
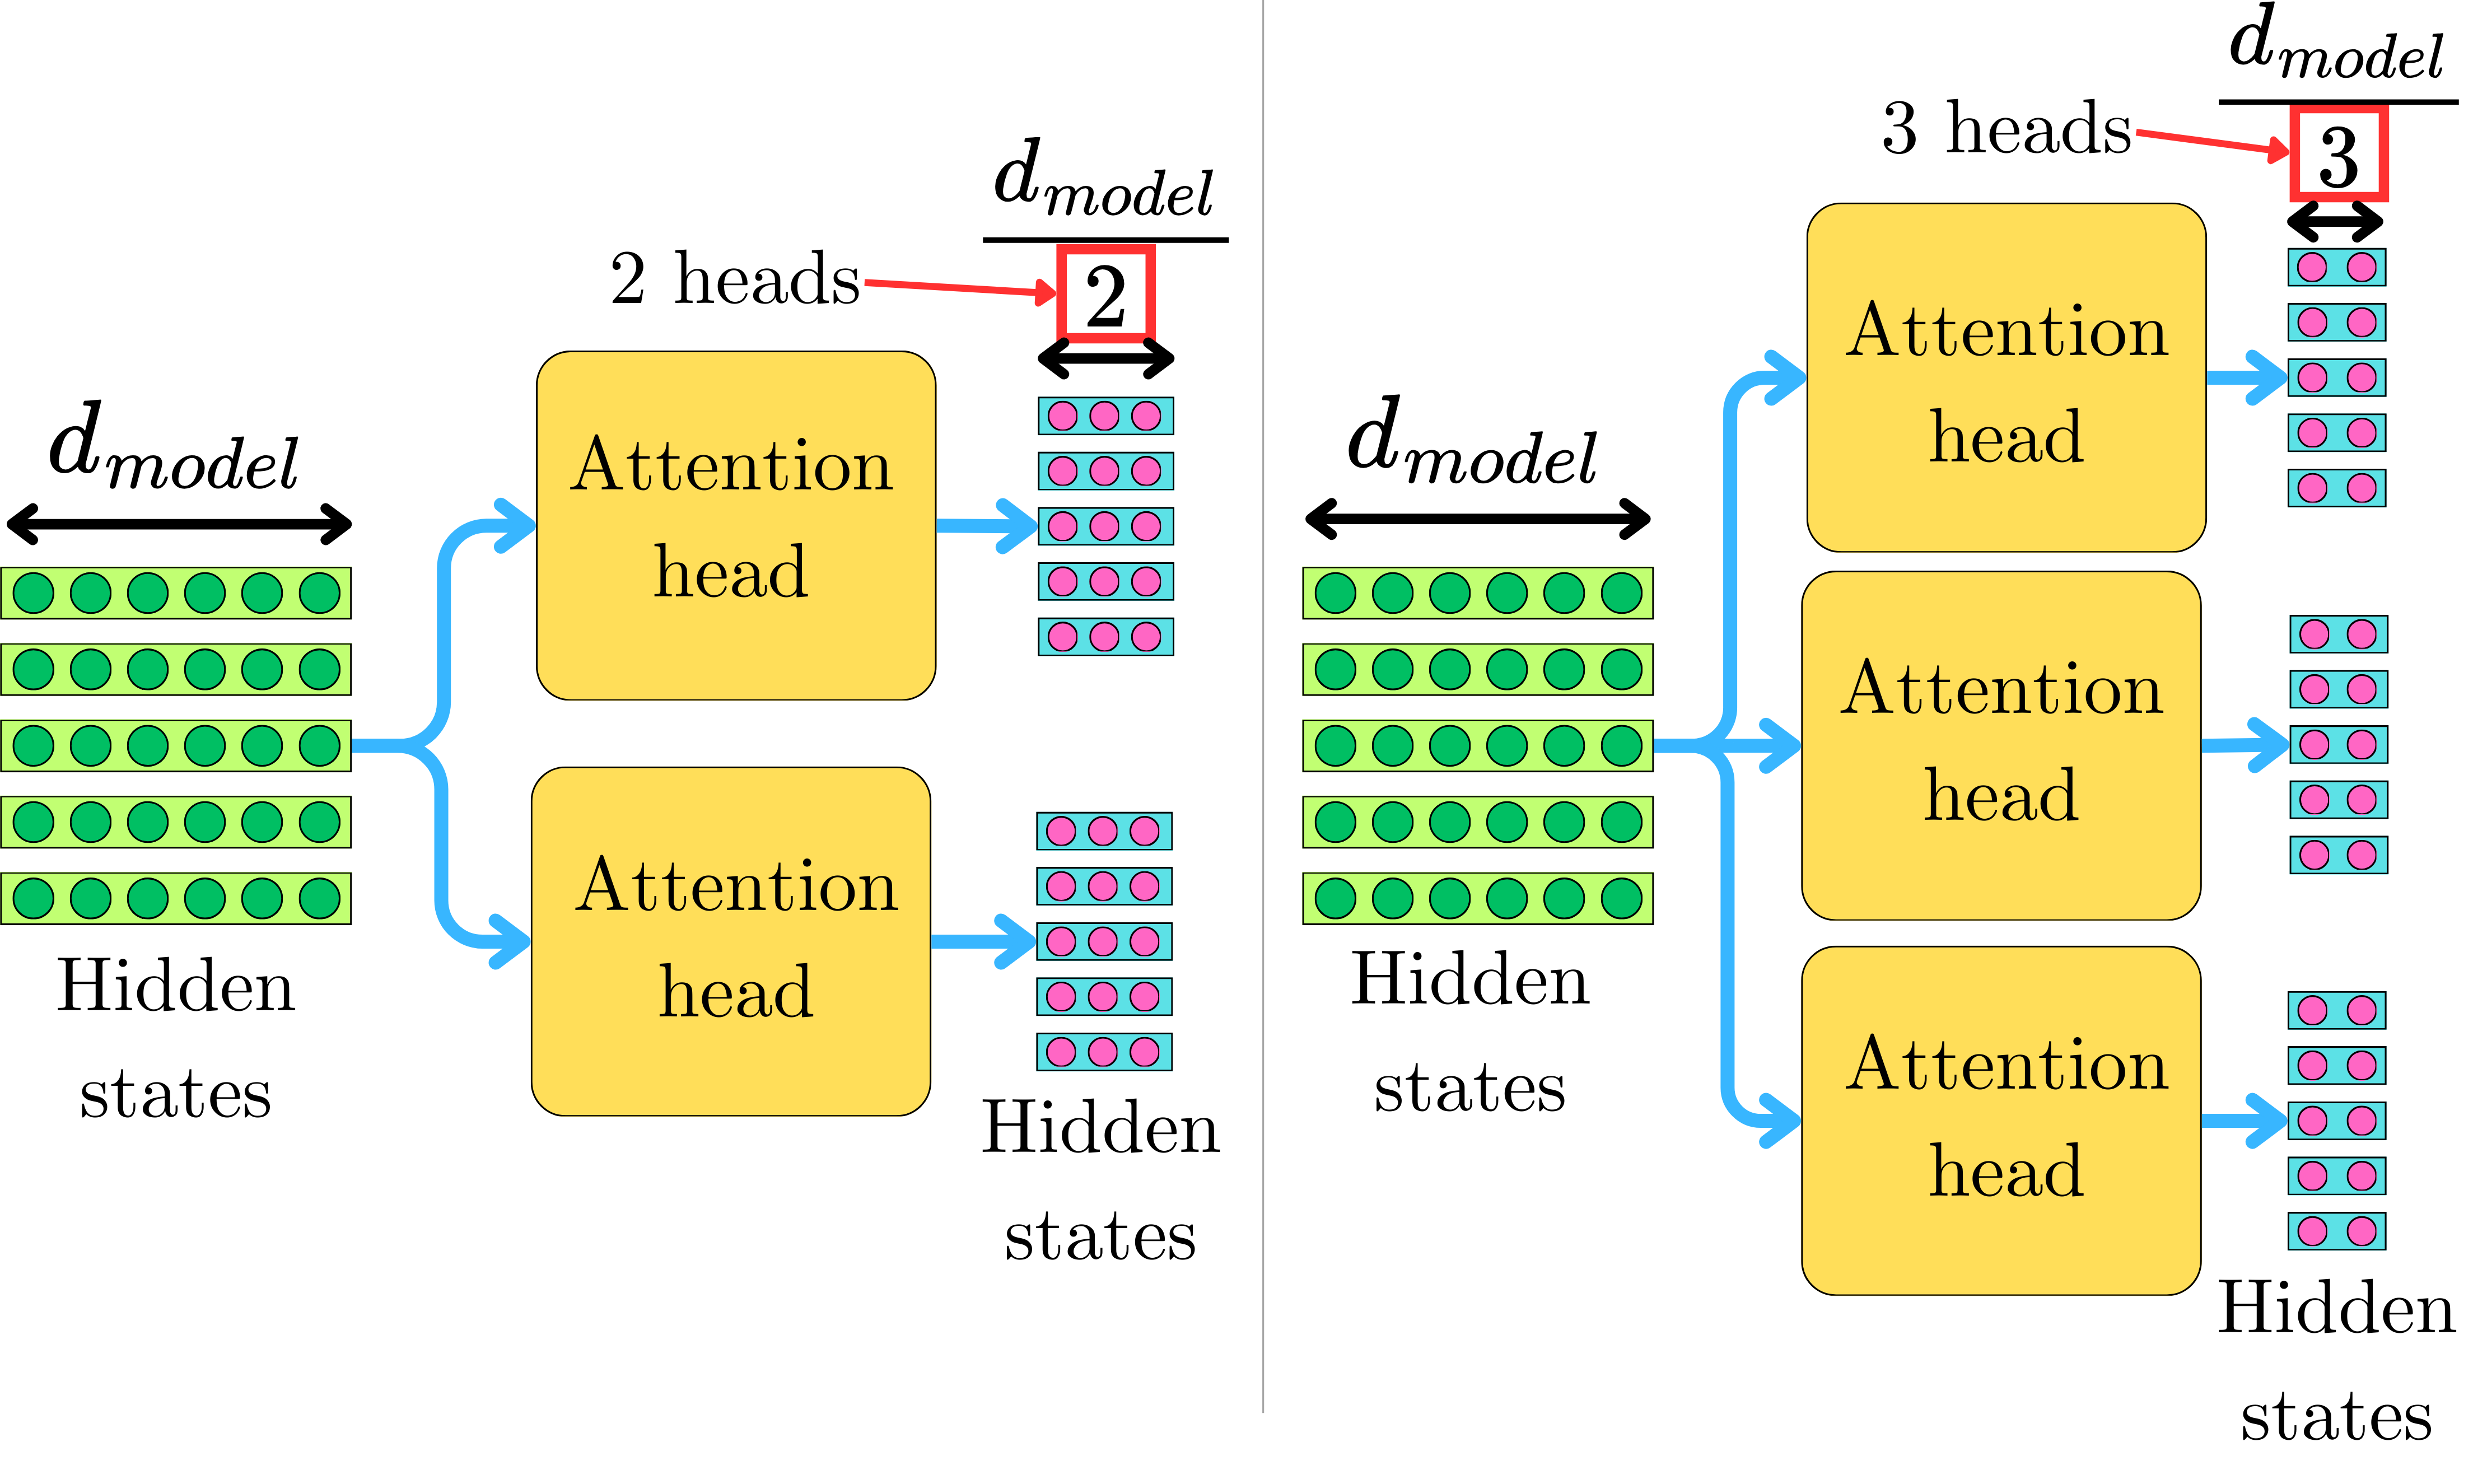
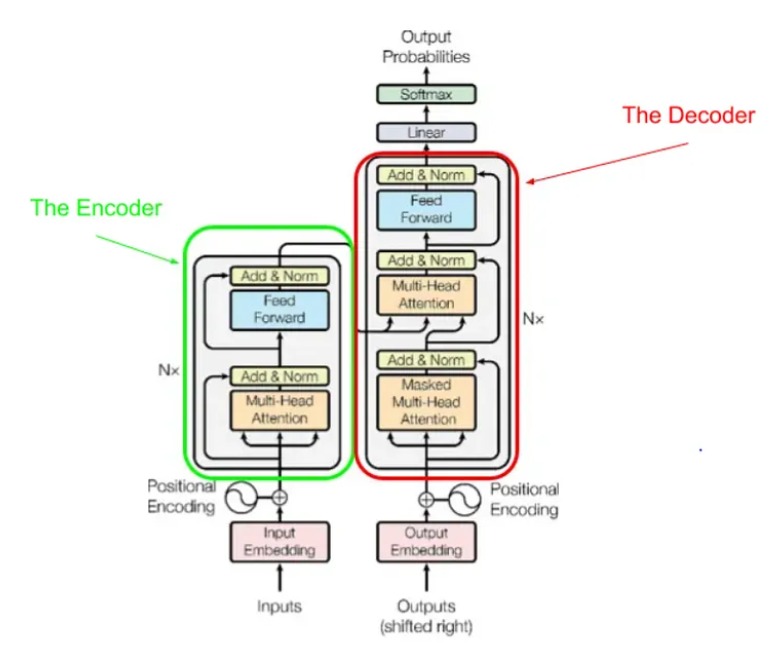
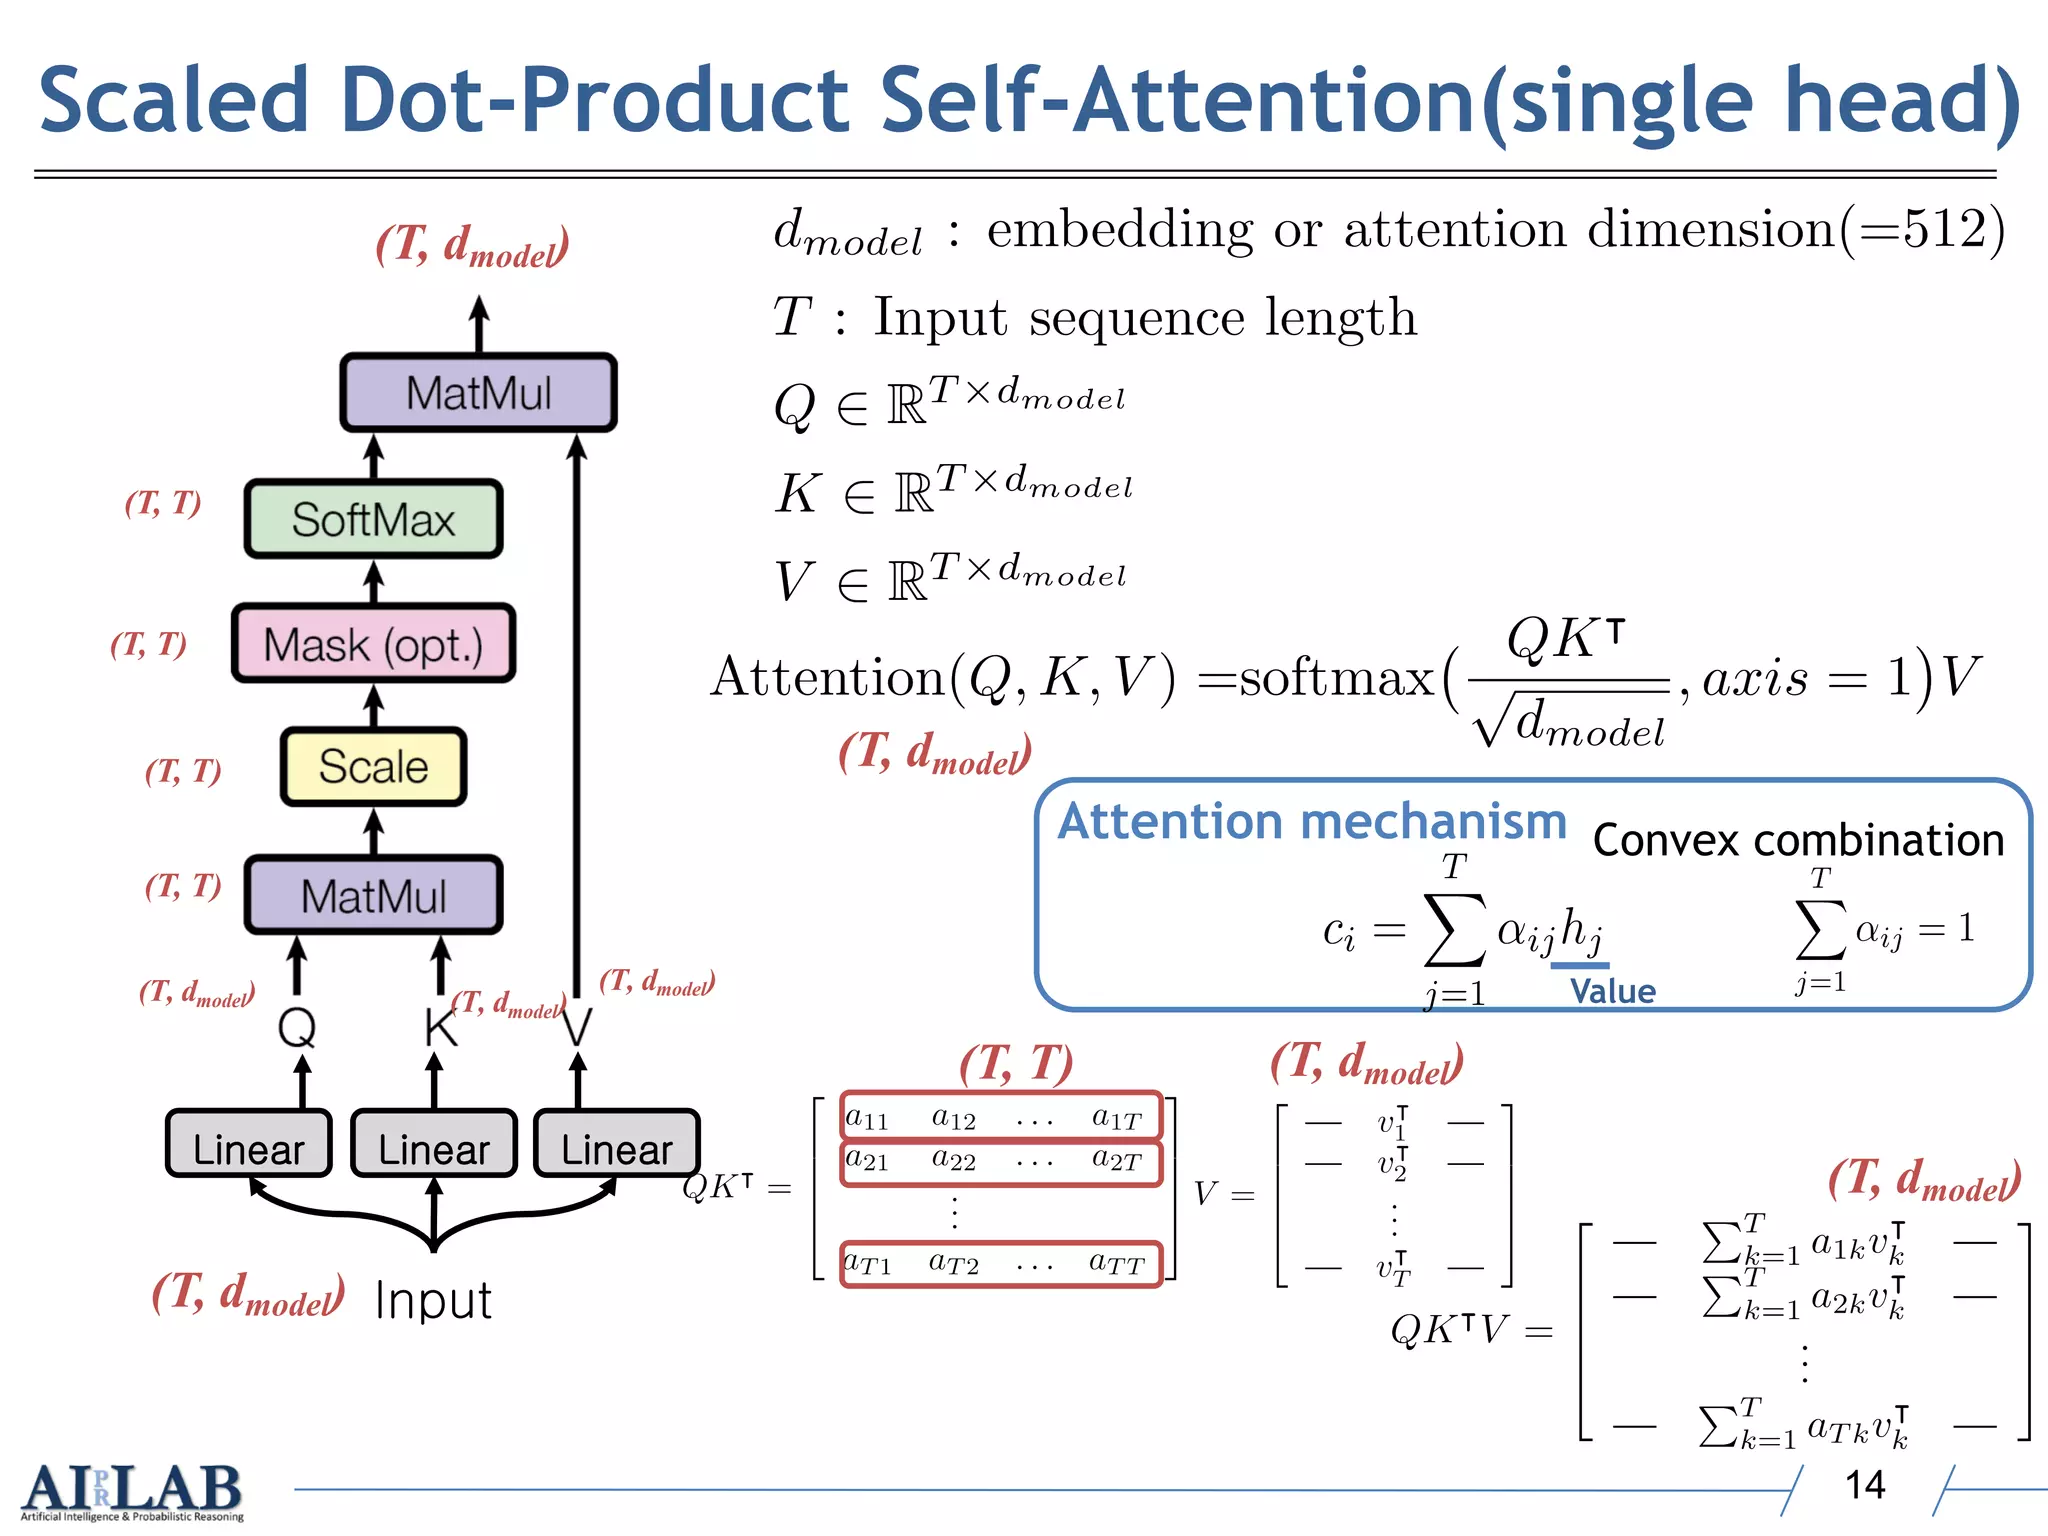
The core idea is straightforward once you strip away the math notation. Self-attention lets each position in a sequence directly attend to every other position, computing weighted representations based on relevance. Multi-head attention runs several of these attention operations in parallel with different learned linear projections, so the model can capture different types of relationships simultaneously. Positional encodings are added to the input embeddings because the architecture has no inherent notion of order — unlike RNNs, which process tokens sequentially. The encoder stack repeats six layers of multi-head self-attention and position-wise feed-forward networks, with residual connections and layer normalization after each sub-layer. The decoder stack adds a masked self-attention layer to prevent attending to future tokens during training, followed by an encoder-decoder attention layer that pulls information from the encoder output. I spent about three weeks trying to implement a minimal Transformer from scratch to understand the code, not just the paper. The hardest part was getting the masking right in the decoder's causal attention. A single off-by-one error in the upper triangular mask and your model will leak future information during training. The loss drops beautifully at first and then plateaus or gets worse because you are effectively cheating. I caught it by comparing my implementation against the TensorFlow tutorial implementation layer by layer and checking that the logits from both matched within numerical tolerance. That took me most of a weekend.
Common Misunderstandings and What People Miss
One thing that confuses people reading this paper is the difference between scaled dot-product attention and multi-head attention. The paper presents them as separate concepts, but multi-head attention is literally just multiple scaled dot-product attention heads running in parallel with different weight matrices, followed by a final linear projection. There is no new mechanism. Another misunderstanding is about the computational complexity. Self-attention has quadratic complexity with respect to sequence length because every token attends to every other token. For very long sequences — say, longer than 2048 tokens — this becomes a real problem. People who try to run vanilla Transformers on long documents hit memory walls fast. There are many variants designed to address this, like Linformer, Performer, and sparse attention methods, but the original paper works on sequences up to around 512 tokens comfortably on a standard GPU. A less obvious issue is that the positional encoding scheme used in the paper — sinusoidal functions — is somewhat arbitrary. Later work like RoPE (Rotary Position Embeddings) and ALiBi (Attention with Linear Biases) turned out to be more effective, especially for longer contexts. The original encoding works fine for the translation tasks the paper evaluated on, but if you are working with long-range dependencies beyond the training distribution, you should consider replacing it.
Get the Full Details
![Attention Is All You Need PDF] Attention Is All You Need | Semantic](https://i.ytimg.com/vi/n9sLZPLOxG8/maxresdefault.jpg)
Practical Advice if You Are Reading the Paper
Read the figures before the equations. Figure 1 gives you the overall architecture. Figure 2 breaks down the encoder and decoder blocks. The math in Section 3 is dense but not necessary to understand the high-level mechanics. The ablation studies in Section 5.3 and Table 3 are where the paper earns its credibility — they show that removing components like residual connections or layer normalization causes measurable degradation, and that the model scales well with more heads and larger feed-forward dimensions. If you are implementing this for research or production, start with an existing library like Hugging Face Transformers or the official Tensor2Tensor repository rather than building from scratch. The original implementation is in C++ and CUDA for the training speed, but for most purposes a PyTorch or JAX implementation is faster to iterate on. One thing I learned the hard way: the paper's training schedule uses a warmup phase for the learning rate. The first 4000 steps increase the learning rate linearly from zero to the peak value, then decay it inversely to the square root of the step number. Skipping warmup causes early training instability. I saw divergence within the first few hundred steps when I tried a constant learning rate on a custom implementation. Turning warmup back on fixed it immediately.
Where the Paper Falls Short
The Transformer architecture has known limitations. It struggles with tasks that require precise positional reasoning, like copying a long string or arithmetic operations, unless explicitly trained on them. The quadratic attention cost makes it impractical for very long sequences without modification. It also requires large amounts of data to train from scratch — the original model was trained on WMT English-to-German and English-to-French datasets with millions of parallel sentences. Fine-tuning on smaller datasets works, but pretraining a full Transformer on limited data usually produces poor results compared to starting from a pretrained checkpoint. For long document understanding or retrieval-augmented generation, you are better off using architectures that were explicitly designed to handle long contexts, like Longformer, BigBird, or models using rotary position embeddings with extended context windows. The original Transformer is a foundational piece, not a finished product for every use case.