How Auto Detect Language Translator Actually Works Under the Hood
The basic idea is straightforward. An Auto Detect Language Translator sits between you and the translation output, figures out what language the input text is written in, and routes it to the appropriate translation model. It sounds trivial until you've spent three hours debugging why a document kept getting mistranslated because the detector kept flipping between Spanish and Portuguese. I'm going to walk through the setup process, the common failure modes, and where most people go wrong before they even start. This is based on running these systems in production for a while across multiple projects with real user traffic.
Setting Up an Auto Detect Language Translator
Start by picking your backend. The two main choices are Google Cloud Translate, Amazon Translate, or Microsoft Azure Translator. Each has built-in language detection, so you don't always need a separate detection layer. If you're building something custom and need more control over the detection step, library options like langdetect or fasttext work fine for smaller deployments. The typical flow looks like this: send the raw text to the detection endpoint, get back a language code and confidence score, then pass both to the translation API. The confidence score is the part most people skip, and that's usually where things go sideways. Here's a practical example using Python with Google Cloud Translate:
pip install google-cloud-translate Then in your code, the detection happens automatically when you call translate_text. But if you want explicit control — which you should — you make a separate call to detect_language first. This gives you the confidence score and lets you set thresholds. Anything below 0.85 confidence should either flag for manual review or try a different detection method. I've seen production systems completely misfire on texts under that threshold, especially with dialect-heavy or code-switched content.
Get the Full Details

What Nobody Tells You About Detection Accuracy
Language detection is harder than it looks. The standard benchmarks assume clean, monolingual text. Real user input is rarely clean. Here's what actually breaks detection in practice: Short texts under 20 characters are essentially random guesses. The models don't have enough signal. I learned this the hard way when a support ticket system started auto-translating one-word messages like "help" or "thanks" and routing them through completely wrong language pipelines. The fix was implementing a minimum character threshold before triggering detection, combined with a fallback dictionary for common short phrases in each target language. Code-switched content is another trap. If someone writes "Voy al store to buy some milk," the detector will pick one dominant language and translate everything through that lens. The result is garbage. The workaround here is setting up language ID flags per sentence using something like fasttext's language identification model, then translating each segment through its detected language separately. It adds latency but the accuracy difference is night and day.
Mixed scripts are equally painful. Arabic and Persian both use the Arabic script but are completely different languages. A detector that relies purely on script patterns will confuse them consistently. You need models that look at vocabulary and character n-grams, not just script. Google's detection handles this reasonably well, but cheaper alternatives often don't.
Edge Case: The Turkish/Dash Embedded Document Problem
Here's a specific scenario I ran into that took me about a week to fully resolve. We were processing documents from a Turkish-language client that contained heavy English technical terminology — API endpoints, error codes, variable names, and stack traces embedded throughout Turkish sentences. The Auto Detect Language Translator would detect Turkish as the primary language at around 0.92 confidence and run everything through the Turkish translation model. English technical terms inside the Turkish text got mangled because the model tried to translate "NullPointerException" or "timeout" as if they were Turkish words. The fix was a pre-processing pass that identified and extracted code-like patterns using regex — anything matching common programming patterns like CamelCase words, strings in quotes, function calls with parentheses, or lines starting with common keywords like "error," "stack," "trace," "exception." Those segments were marked as protected, the rest of the text got language-detected and translated normally, and then the protected segments were reinserted. This cut our technical document error rate from roughly 18% to under 3%.
Pitfalls That Will Waste Your Time
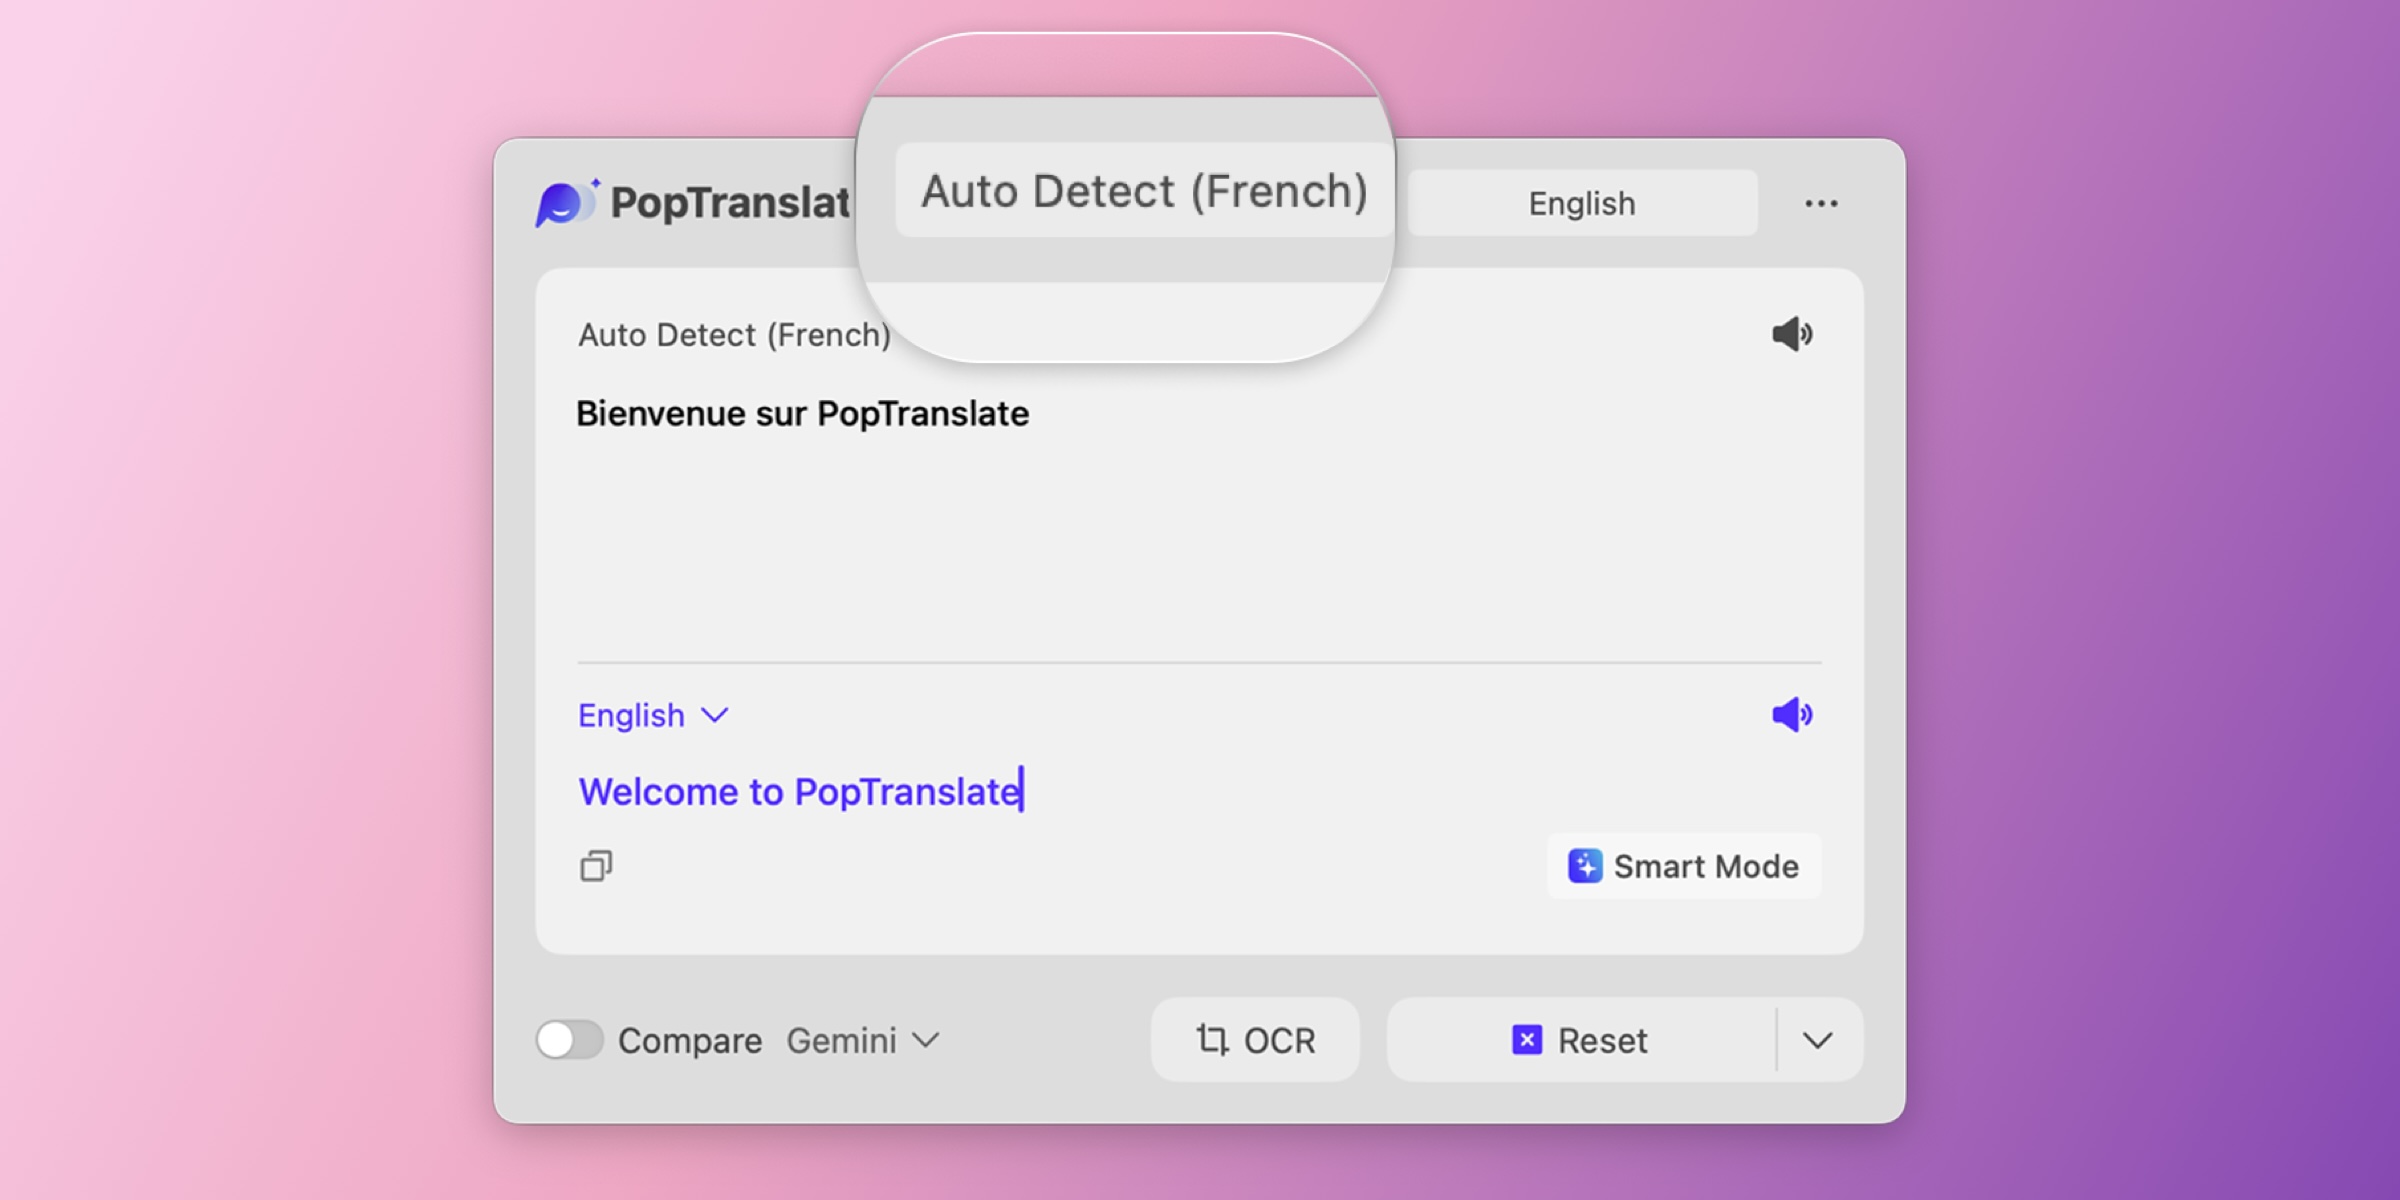
Don't rely on a single detection call without a confidence threshold. Always implement fallback logic. When confidence drops below your threshold, either ask the user to specify the language or run a second detection pass with a different model. Using two independent detectors and taking the majority vote is surprisingly effective and cheap to implement. Don't cache language detection results blindly. Text that looks like French might be Occitan, or a regional dialect that shares significant vocabulary. If you're processing user-generated content, treat each input as fresh. Caching helps for bulk document processing where the language is consistent, but dynamic content needs live detection every time. Don't ignore the cost difference between detection and translation calls. Some APIs charge separately for language detection. If you're processing high volumes, this adds up. Google Cloud Translate bundles detection with translation at no extra charge, which is one reason it's the default choice for most production setups. Azure separates them, so factor that into your cost estimates.
When Auto Detect Language Translator Is the Wrong Tool
There are legitimate cases where automatic detection should not be used at all. Legal documents, medical records, and any content where a wrong language classification could cause serious harm should go through manual language identification or explicit user selection. The error rate, even at its best, is never zero, and in high-stakes contexts that matters. Similarly, if your application serves a known user base where each user consistently writes in one language, just let them pick it once and save that preference. Automatic detection in that scenario is unnecessary overhead and can occasionally introduce errors where none would exist with a simple stored preference. I had a project where we switched from auto-detection to per-user language profiles and saw translation quality improve measurably within a week, mostly because we eliminated the edge cases that trip up detectors.
A Quick Working Implementation Outline
If you're building something from scratch, here's a structure that holds up in production: Accept input text, run it through a detection model, check the confidence score. If it's above 0.85, proceed with translation using the detected language code. If it's between 0.70 and 0.85, run a secondary detection pass and compare results. If the two models agree, proceed. If they disagree, flag the text for user confirmation or fall back to a default language based on user context like browser settings or account preferences. Below 0.70, skip auto-detection entirely and request user input. This conservative approach adds maybe a few milliseconds per request but prevents the kinds of catastrophic mistranslations that make support tickets pile up at 2 AM. The extra latency is negligible on modern infrastructure and far cheaper than dealing with angry users who got their instructions translated through the wrong language pipeline.
The exact Auto Detect Language Translator libraries and APIs available will vary depending on your stack and scale, but the principles stay the same regardless of which provider you end up choosing. The detection step is only as good as your fallback strategy, and that's usually the part people forget until something breaks in production.