What These Tools Actually Do
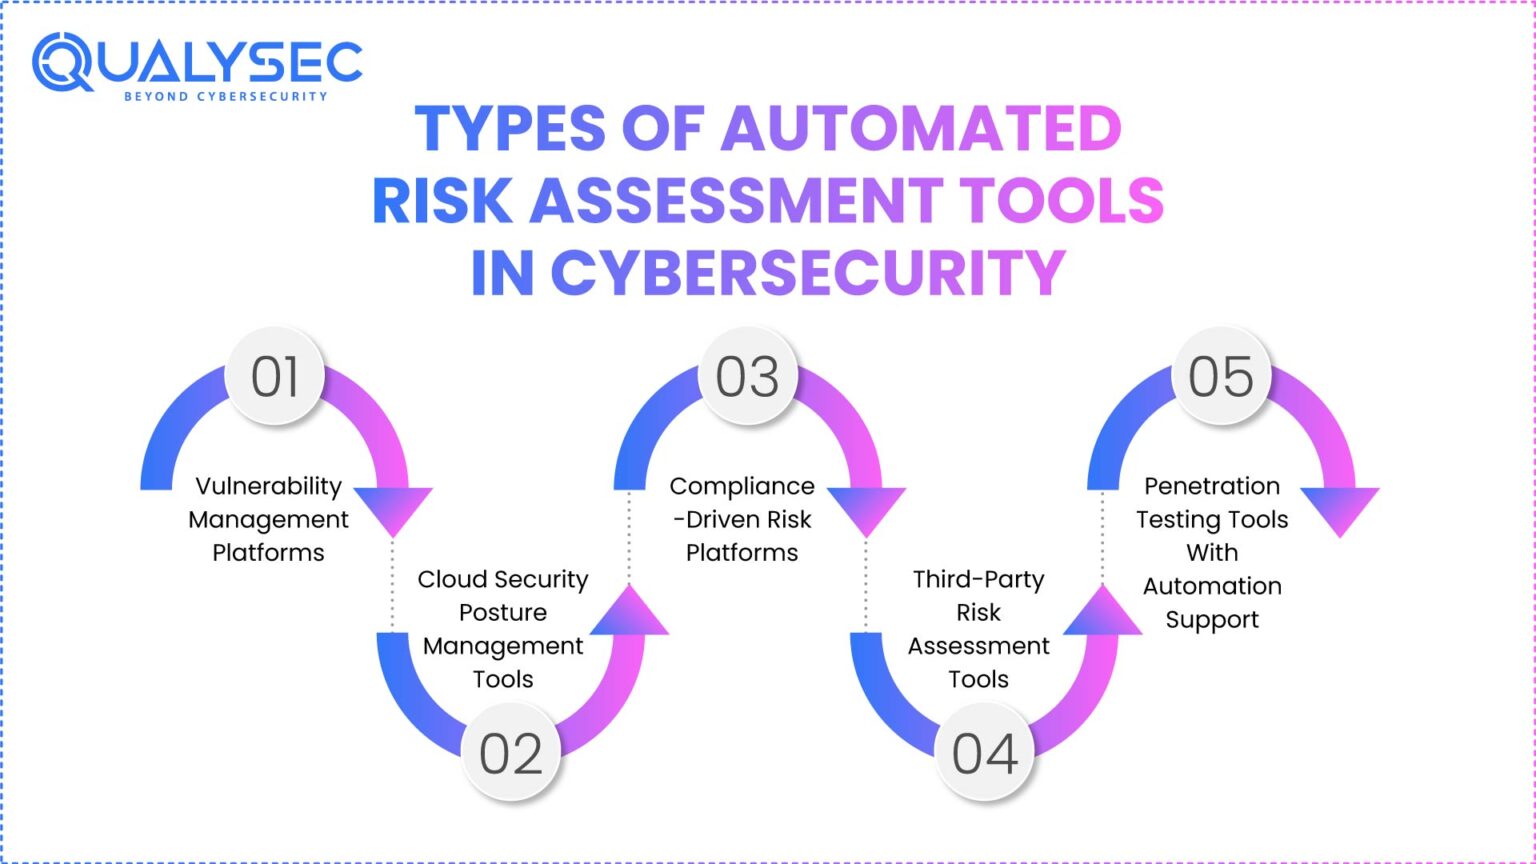
Automated Risk Assessment Tools are software systems that evaluate threats, vulnerabilities, and potential impact without requiring a human to manually walk through every step. They scan your environment, cross-reference findings against known databases, assign risk scores, and generate reports. That is the basic description. The reality is messier. Pick a tool that matches your infrastructure. If you are running mostly cloud workloads, something like Wiz, Orca Security, or Prisma Cloud will integrate faster than a traditional on-prem scanner. If you have a mixed environment, Tenable.io or Qualys are reasonable defaults. The important thing is not the vendor name. It is whether the tool can actually reach everything it needs to scan. I have seen teams buy licenses for tools that could not see half their assets because of network segmentation or IAM misconfigurations. Once you select something, connect it to your environment. This usually means installing agents or providing read-only access to cloud APIs. Agents give you better visibility into host-level issues. API connections are faster to deploy but often miss container runtime threats. Run a test scan before you hand it to anyone else. Check whether the results make sense. A scan that returns zero findings on a production environment with thousands of endpoints is either broken or scanning the wrong things. Both are common.
Configure your risk scoring model. Most tools default to NIST or CVSS-based scoring. That is fine as a starting point, but CVSS scores do not account for business context. A vulnerability on a public-facing web server and the same vulnerability on an internal development machine will have identical CVSS scores, even though one matters significantly more. Override the defaults. Create custom risk rules that weight exposure, asset criticality, and exploit availability. This takes time upfront but reduces alert fatigue later.
How It Works Under the Hood
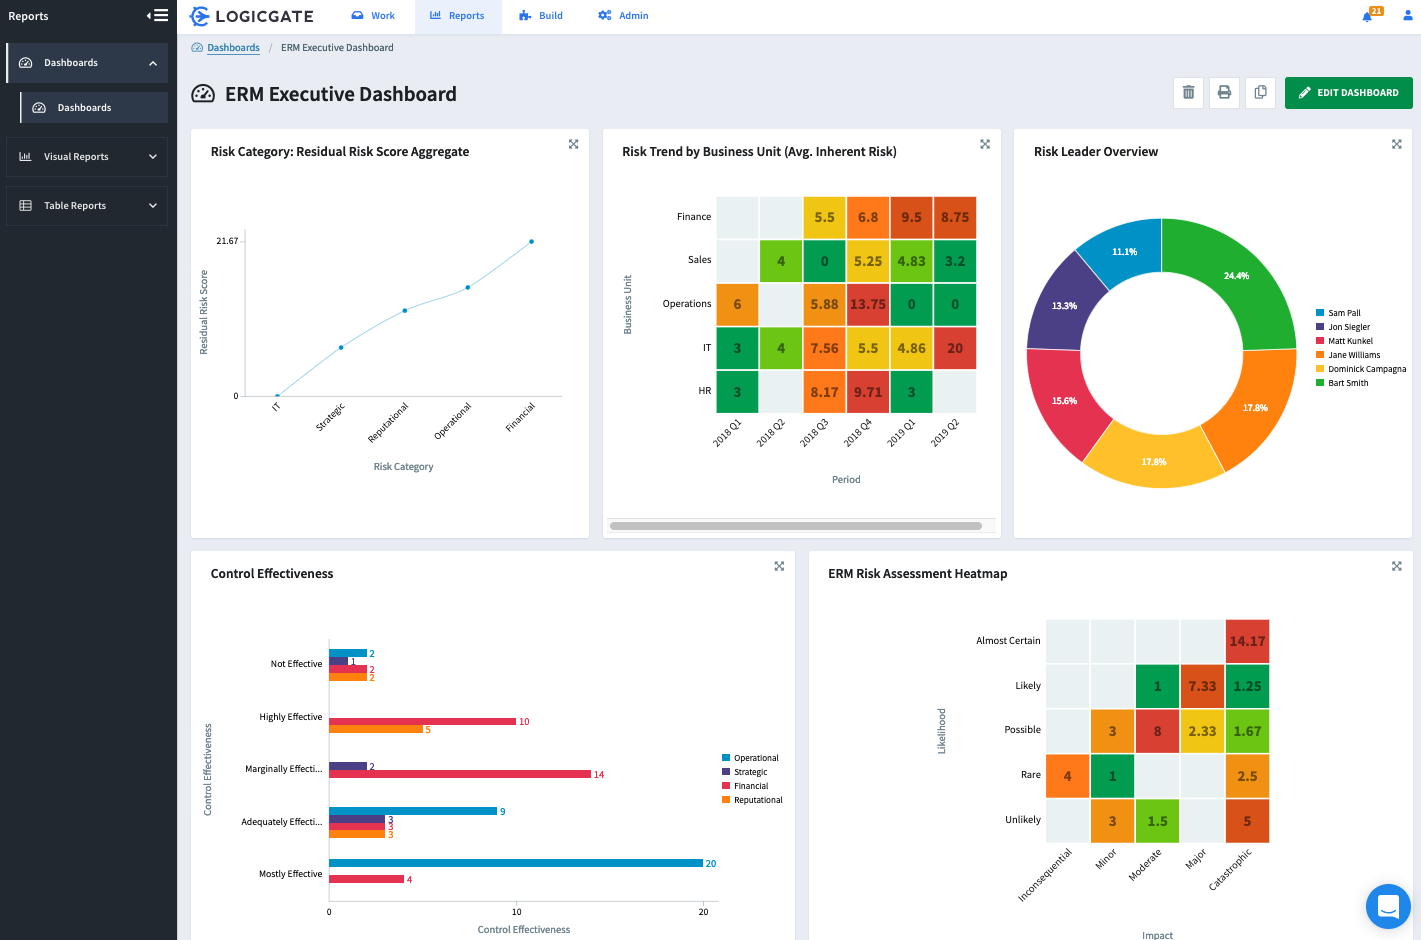
These tools operate in a loop. Discovery, scanning, analysis, reporting, and remediation tracking. Discovery identifies every asset on the network or in the cloud. Scanning checks those assets against vulnerability databases, misconfiguration checks, and compliance frameworks. Analysis applies your risk rules to score each finding. Reporting surfaces the findings in dashboards and exports. Remediation tracking follows up to confirm fixes have been applied. Some platforms now use machine learning to reduce noise by correlating related findings. The ML part is often just pattern matching dressed up in marketing language. It works decently for deduplication but does not replace actual risk analysis. Scanning frequency matters more than most people realize. A tool that runs once a month is basically a snapshot of history. Daily scans at minimum. Hourly for cloud environments where configuration drift happens constantly. I set up automated weekly exports of our top-risk findings to a Slack channel. Not for the team to act on immediately, but to create visibility. When compliance auditors ask what you are doing, having a trail of documented findings and remediation timelines is worth more than any dashboard.
Get the Full Details
Specific Problems I Have Seen
One issue that comes up constantly is credential-based authentication versus agentless scanning. Agentless scans are fast to deploy. You give the tool read-only credentials and it does its thing. But they miss a lot. Agents see what is actually running, what patches are applied, what processes are active. Without agents you are guessing based on port responses and banner grabbing. In my experience, the gap between agentless and agent-based findings can be forty to sixty percent on larger environments. You are not seeing the full picture with agentless alone. Another problem is false positive overload. The first month with any new tool, you will get hundreds or thousands of findings. Most of them will not matter to your organization. I have seen teams abandon a tool after two weeks because the noise was unmanageable. The workaround is strict tuning. Set up acceptance criteria. Low-severity findings on isolated systems that have no internet access and no sensitive data? Mark them as accepted risk. Outdated SSL certificates on internal testing servers? Suppress those. Document every suppression with a reason and a review date. When auditors check, they will ask about your exceptions, and you need answers ready. A specific edge case I ran into: a cloud environment where the scanning tool was reporting vulnerabilities on instances that no longer existed. The instances had been terminated, but the DNS records and load balancer configurations still referenced them. The tool was scanning the old IP ranges and flagging stale data. This went on for three weeks before anyone noticed. The fix was not in the tool itself. It was a cleanup of the cloud networking configuration and a re-sync of the asset inventory. The tool was technically correct. It was finding vulnerabilities on the network. The problem was that the network was mapping to ghosts.
What Beginners Miss
People treat risk scores as objective truth. They are not. A CVSS 9.8 on one system might be a paper tiger on another. Risk scoring is a prioritization tool, not a diagnostic one. The number tells you how severe a vulnerability is in isolation, not whether it matters for your specific setup. Factor in asset criticality, network exposure, current threat intelligence, and whether an exploit exists in the wild. My team uses a weighted formula: base CVSS score multiplied by exposure factor, multiplied by asset value, then adjusted for patch availability. It is not perfect, but it consistently surfaces the right problems over raw CVSS rankings. Another misconception is that these tools replace security teams. They do not. They augment them. A tool can tell you that a vulnerability exists. It cannot tell you whether it is being actively exploited against your specific stack, or whether patching it would break a critical dependency. That requires human judgment. The best organizations I have worked with treat the tool output as a starting point for discussion, not a finish line.
The Honest Downsides
Cost scales poorly with environment size. Enterprise licenses for tools like Qualys or Tenable can run six figures annually for large deployments. Smaller tools are cheaper but often lack the depth you need. There is also implementation drag. Getting a tool properly configured for your environment typically takes two to four weeks of focused work. After that, maintaining it is lower effort but not zero. You need someone to review false positives, update risk rules when the threat landscape shifts, and reconcile scanner findings with manual findings from penetration tests. Sometimes these tools fail entirely. I have seen them completely miss lateral movement paths in networks because the scanning was restricted to perimeter access. A network segmentation assessment requires different methodology. I have also seen cloud misconfiguration tools that flagged a bucket policy as risky when it was actually required for a legitimate application function. Context matters. If your organization relies heavily on a single vendor tool for all risk assessment, you are creating a single point of failure in your security process. Supplement with manual assessments at least quarterly. For smaller teams or startups that cannot justify enterprise tool costs, open-source options like OpenVAS or Trivy offer decent coverage at zero license cost. Trivy in particular is strong for container and Kubernetes environments. The trade-off is that you manage everything yourself. No vendor support, no polished dashboards, no automated reporting pipelines out of the box. It is a valid path if you have the engineering bandwidth to build what enterprise tools provide by default.
Practical Workflow
Here is what a realistic weekly cycle looks like on my end. Monday morning: pull the automated scan report and filter out anything already accepted or suppressed. Tuesday: triage the new findings. Critical and high priorities go into the ticketing system with SLA deadlines. Medium and low findings go into a batch review. Wednesday through Friday: field questions from the infrastructure team about specific findings and track remediation progress. End of week: export a summary of closed findings and outstanding risks for management review. This takes approximately four to six hours per week depending on environment size. Less than that and you are not doing the work properly. More than that and your tool is generating too much noise to ignore. The process is not glamorous. It is repetitive, occasionally frustrating, and constantly evolving. But it is better than the alternative, which is finding out you had a critical vulnerability six months ago because someone ran a scan and never checked the results.