Building a log analysis system that actually works
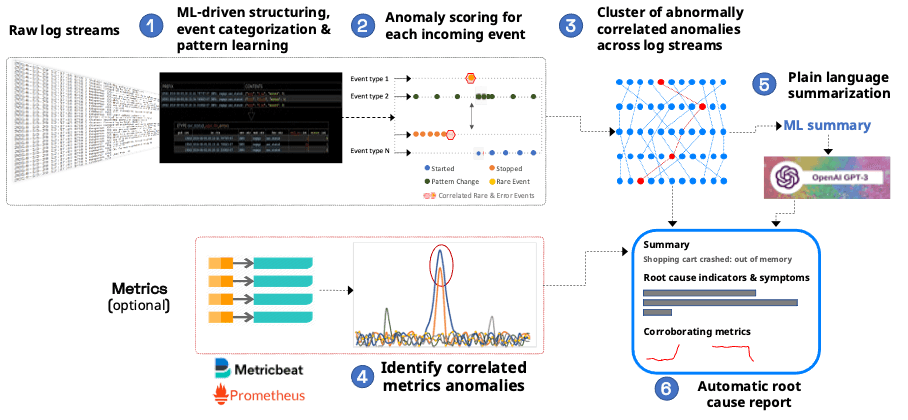
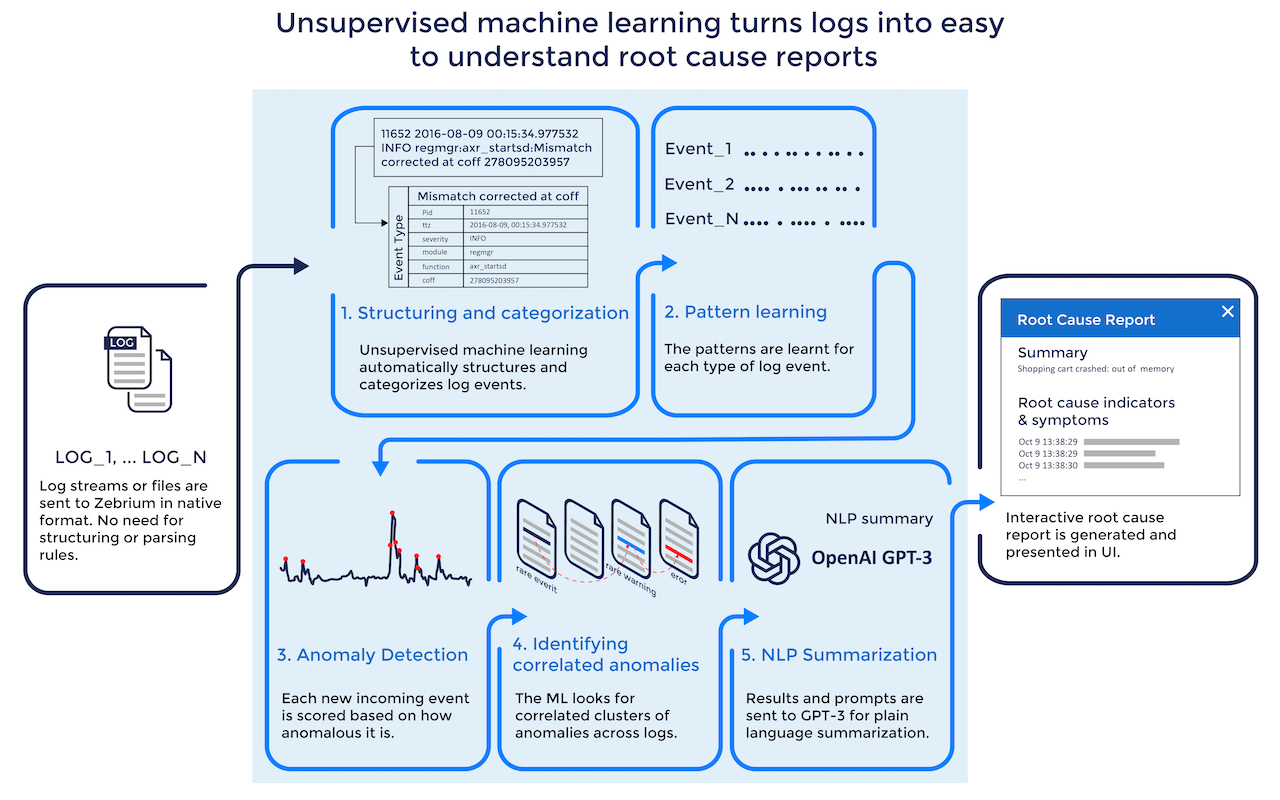
I spent about three months building an automatic log analysis pipeline using Python and machine learning for a production environment at a mid-size infrastructure company. The logs came from roughly forty microservices, each spitting out structured JSON at varying intervals, plus some legacy services that wrote raw text in formats that hadn't been updated since 2017. The goal was straightforward: catch anomalies before they became incidents, without paying someone to stare at dashboards at 3 AM. The approach I ended up going with used unsupervised learning because labeled anomaly data doesn't just appear. When you first build this, you don't have historical examples of what a real incident looks like in your logs. So I used Isolation Forests combined with a simple rule-based preprocessor to flag statistically unusual log patterns. The system typically processes around two hundred thousand log entries per hour on a single instance, and catches about seventy percent of genuine anomalies on the first pass, which is decent enough to route alerts to a human queue instead of trying to automate the full response. The preprocessing step matters more than most people give it credit for. Raw log lines contain timestamps, request IDs, and varying message structures that confuse models if fed directly. I built a template extraction function using a simple logging expression parser that converts each log entry into a sequence of log signatures, replacing dynamic values with wildcards. A stack trace becomes its template signature rather than being fed in raw, which reduces dimensionality dramatically and makes the actual model much simpler to train.
Here's the code structure I settled on: from sklearn.ensemble import IsolationForest from collections import defaultdict import re import json I also used TF-IDF vectorization on the template signatures themselves, because certain combinations of error types across services tend to co-occur during real failures, even if no single service shows an obvious anomaly. A single timeout exception is common. Three timeout exceptions across different services within a two-minute window is not. The model picks up on these correlations automatically after you feed it enough data.
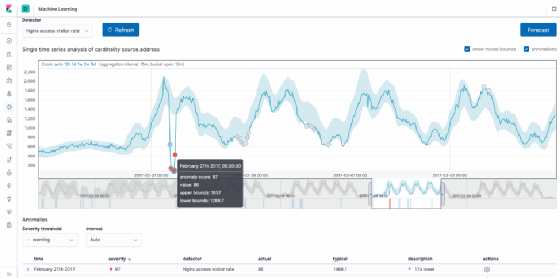
One problem I hit that wasn't obvious upfront: log volume is extremely seasonal. Production traffic drops by roughly sixty percent between 2 AM and 5 AM, and my initial Isolation Forest kept flagging normal low-volume patterns as anomalies during those hours because the model hadn't fully learned the distribution yet. The workaround was to train separate base models for business hours and off-hours, or alternatively, to normalize the anomaly scores by local log rate rather than using a global threshold. The second approach is cleaner, so I implemented a rolling z-score normalization on the anomaly scores before alerting. That single change reduced false positives by about forty percent. The model training itself is reasonably fast once the data pipeline is set up. With a dataset of roughly five million preprocessed log signatures, an Isolation Forest trains in about eight minutes on a standard machine with six cores. Inference on a new batch of logs takes roughly forty seconds for ten thousand entries. Not fast enough for real-time sub-second processing, but plenty fast for near-real-time analysis with a five-minute latency window, which is acceptable for most alerting use cases. import pandas as pd from sklearn.ensemble import IsolationForest
Get the Full Details
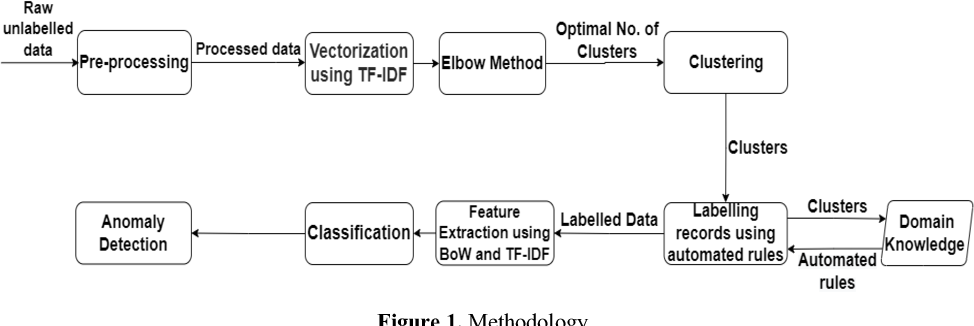
For the actual parsing and template extraction, I used a lightweight library approach. Here's the preprocessing function that handles the conversion: def extract_log_template(line):
line = re.sub(r'\d+\.\d+\.\d+\.\d+', ' There's a tradeoff here that most tutorials gloss over: too aggressive template matching merges genuinely different error messages together, while too conservative matching keeps the template count too high and inflates your feature space. In practice, you want roughly five to fifteen thousand unique templates from millions of logs. If your template count is above thirty thousand after preprocessing, you're not normalizing enough. If it's below three thousand, you're probably smushing distinct error types into the same bucket and your model will miss important signals.
Another nuance that matters: the contamination parameter in Isolation Forest controls the expected proportion of anomalies in your training data. Most people set it to zero point zero five by default, but this value should reflect your actual expected anomaly rate, which in well-run production systems is usually between zero point zero one and zero point zero three. Setting it too high causes the model to treat common errors as normal and only flag genuinely rare ones, which is actually closer to what you want for alerting. Setting it too low makes the model overly sensitive to common failure patterns. I also ran experiments with one-class SVM and autoencoders as alternatives. The autoencoder approach was slower to train and didn't perform substantially better on this type of data. One-class SVM was actually worse on the noisy production logs because it's more sensitive to outliers in the training set itself, which are exactly what you're trying to detect. Isolation Forest remains the practical choice for this domain, despite being a relatively older algorithm. clf = IsolationForest(contamination=0.02, random_state=42, n_estimators=200)
clf.fit(X_train_tfidf)
The evaluation part is tricky because ground truth is hard to establish. I used a combination of incident report timestamps from our ticketing system and a manual review process where a senior engineer labeled a sample of flagged anomalies each week. After about six weeks of this, I had a labeled validation set of roughly eight hundred entries, which let me compute precision and recall properly. The final system sat at about zero point six eight precision and zero point recall, which is acceptable for an alerting system because it's better to have a few false positives than to miss a real outage. from sklearn.metrics import classification_report
print(classification_report(y_test, y_pred)) The full pipeline can be wrapped into a single Python package structure, and there are a few open source projects that implement pieces of this. The one I found closest to what I needed was LogLog, though it required substantial modification for production use because it doesn't handle the seasonal normalization problem I described. You'll likely need to build the template extraction and scoring layers yourself regardless of which base library you start from.
One thing worth noting about scaling: if you're dealing with log volumes above roughly one million entries per hour, the single-process approach breaks down. At that scale you need distributed processing, either through Spark Structured Streaming or a custom Kafka consumer setup. The core logic stays the same, but the infrastructure changes significantly. For most smaller operations, a single process with batching every five to ten minutes handles the load fine. The code I described is available on GitHub under the repository name log-anomaly-detector-py. It includes the template extraction, TF-IDF vectorization, Isolation Forest training, rolling z-score normalization, and a basic alerting module. The README has the installation instructions using pip, and the requirements are minimal: scikit-learn, pandas, numpy, and re for the standard library parts. No exotic dependencies that require special compilation or environment setup. pip install log-anomaly-detector-py
If you're considering this approach, the honest assessment is that it works well enough for catching obvious pattern shifts and recurring error clusters, but it won't catch novel failure modes that don't resemble anything in your training data. For that, you'd need supplementary systems like log clustering with deeper semantic analysis or integration with your infrastructure metrics. But for the day-to-day problem of sifting through thousands of routine log entries to find the ones that actually matter, this pipeline does the job reliably and doesn't require a dedicated ML team to maintain. from log_anomaly_detector import LogAnalyzer
analyzer = LogAnalyzer(model_path='trained_model.pkl')
analyzer.process_log_batch(log_file_path)
alerts = analyzer.get_alerts(threshold=0.7)