Understanding Azure Data Solution Architect Exams and Real-World Architecture
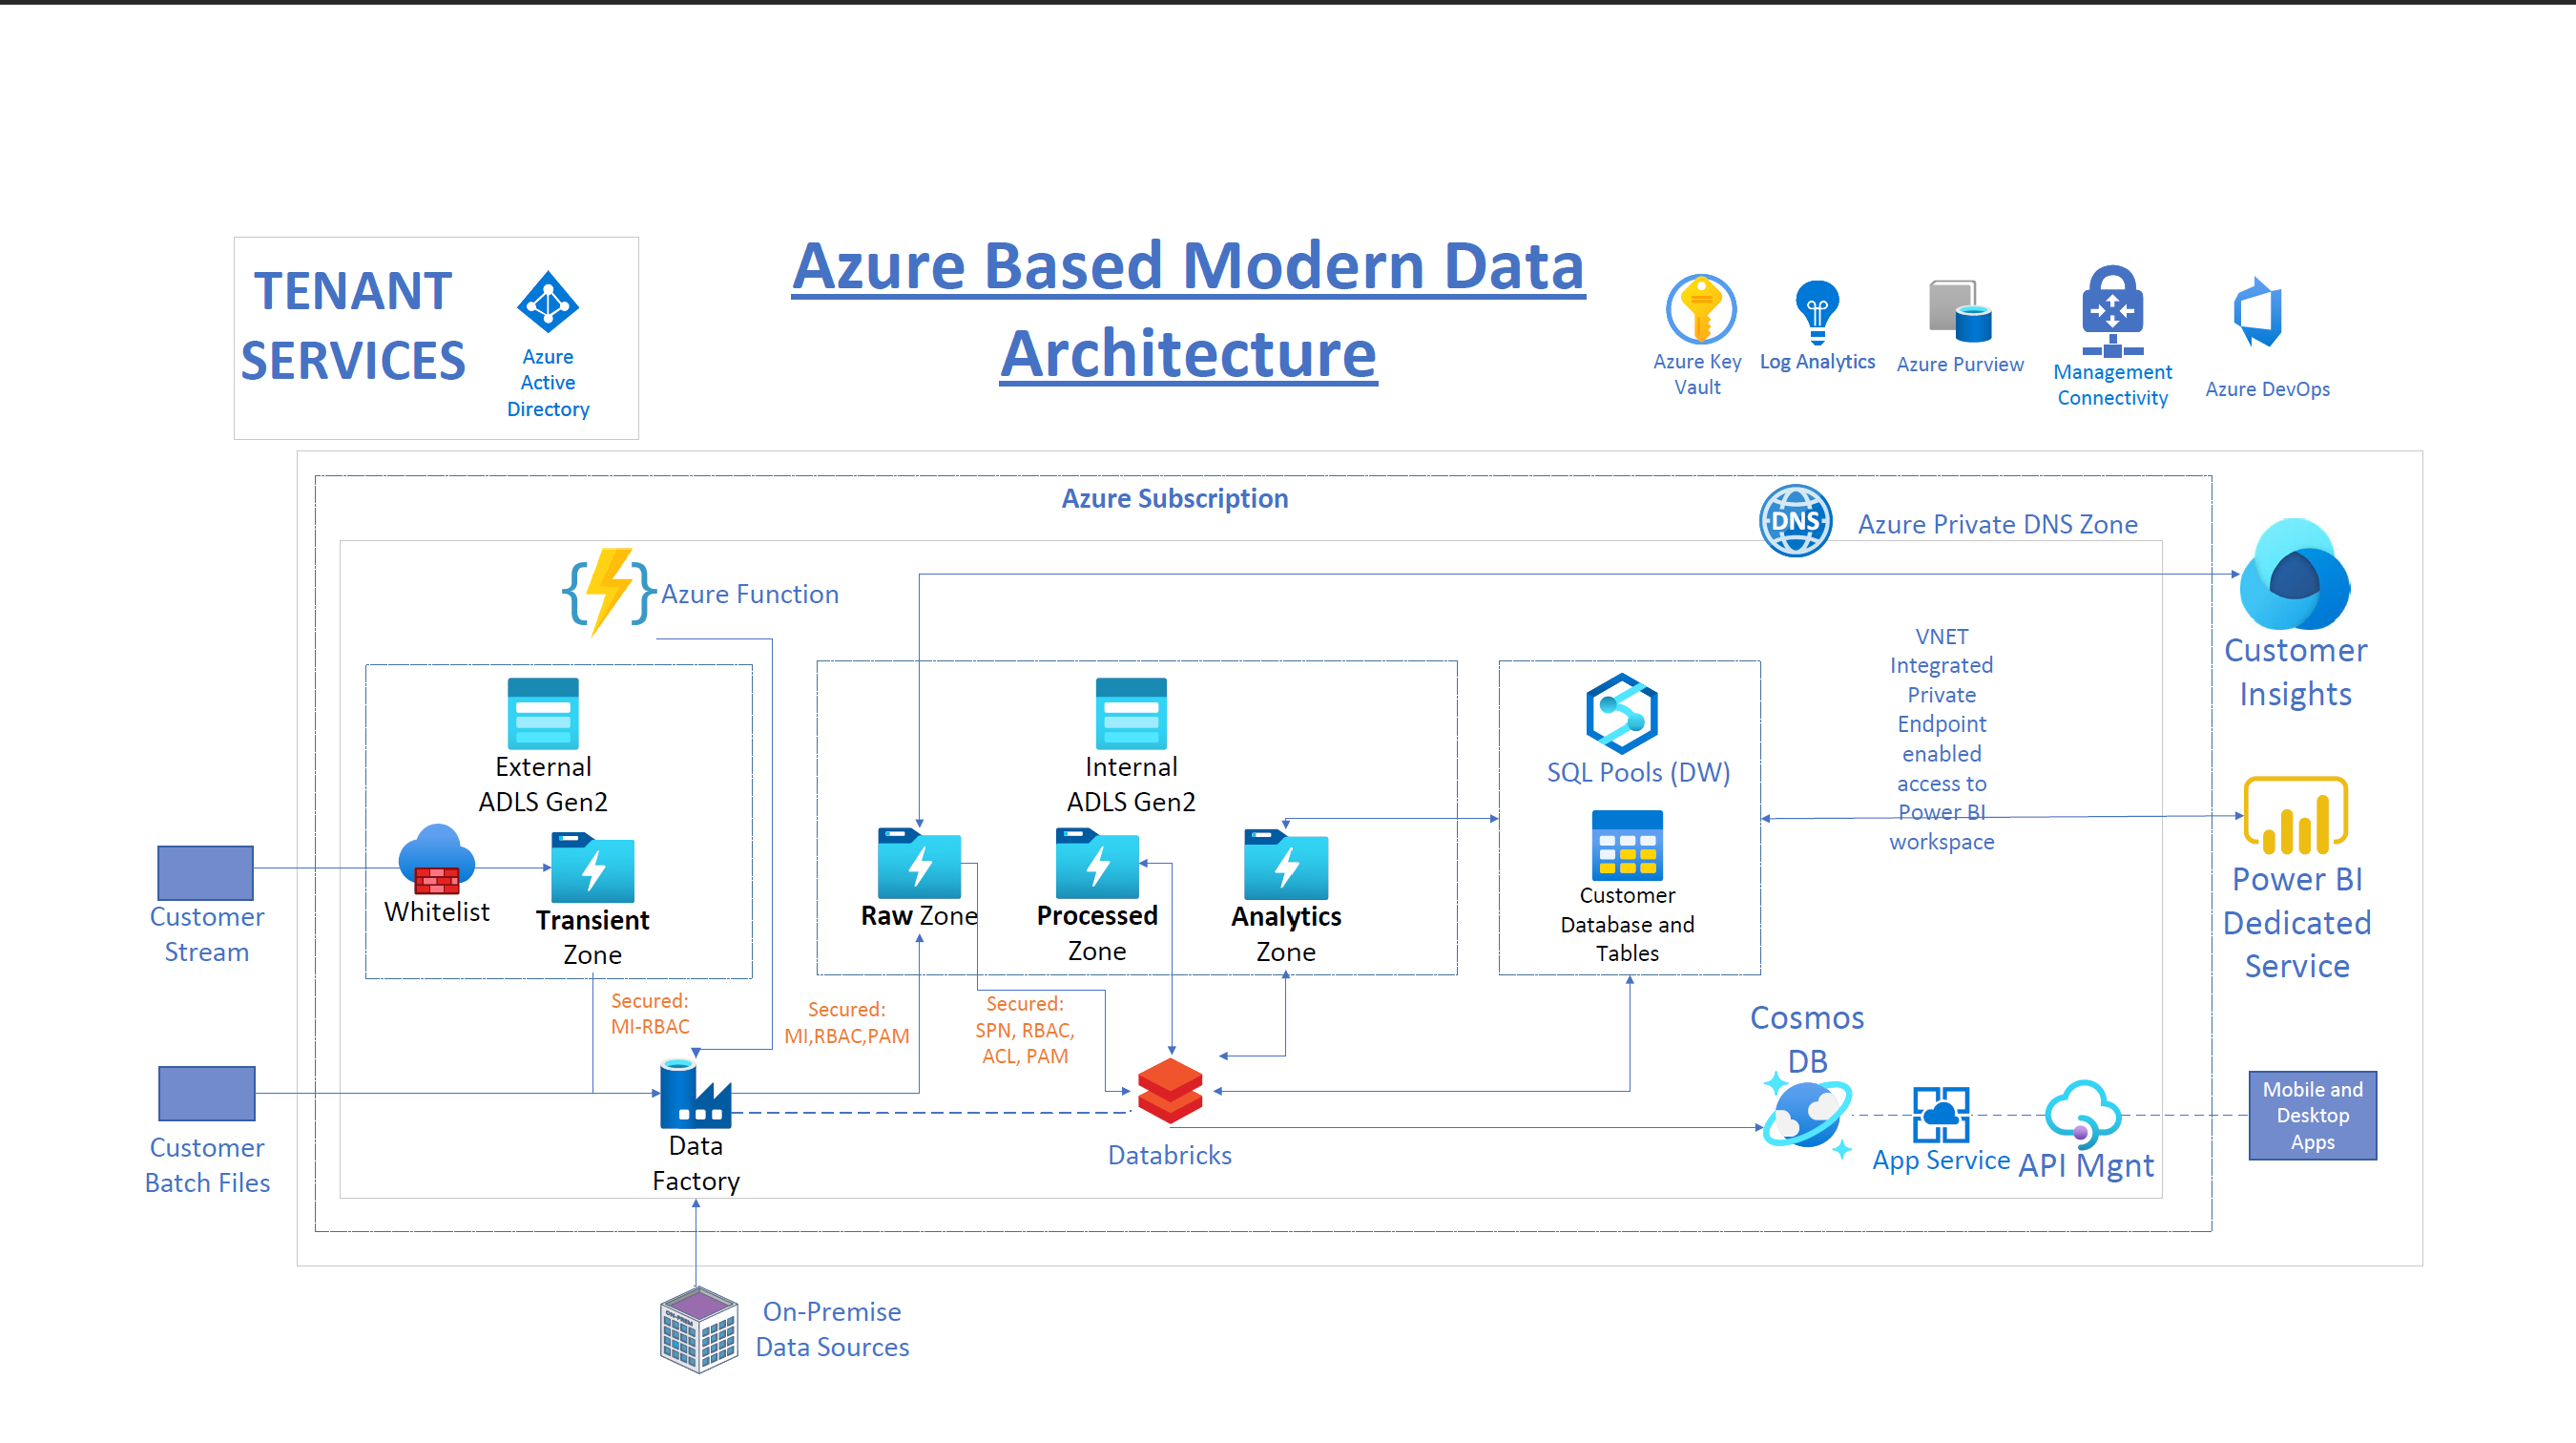
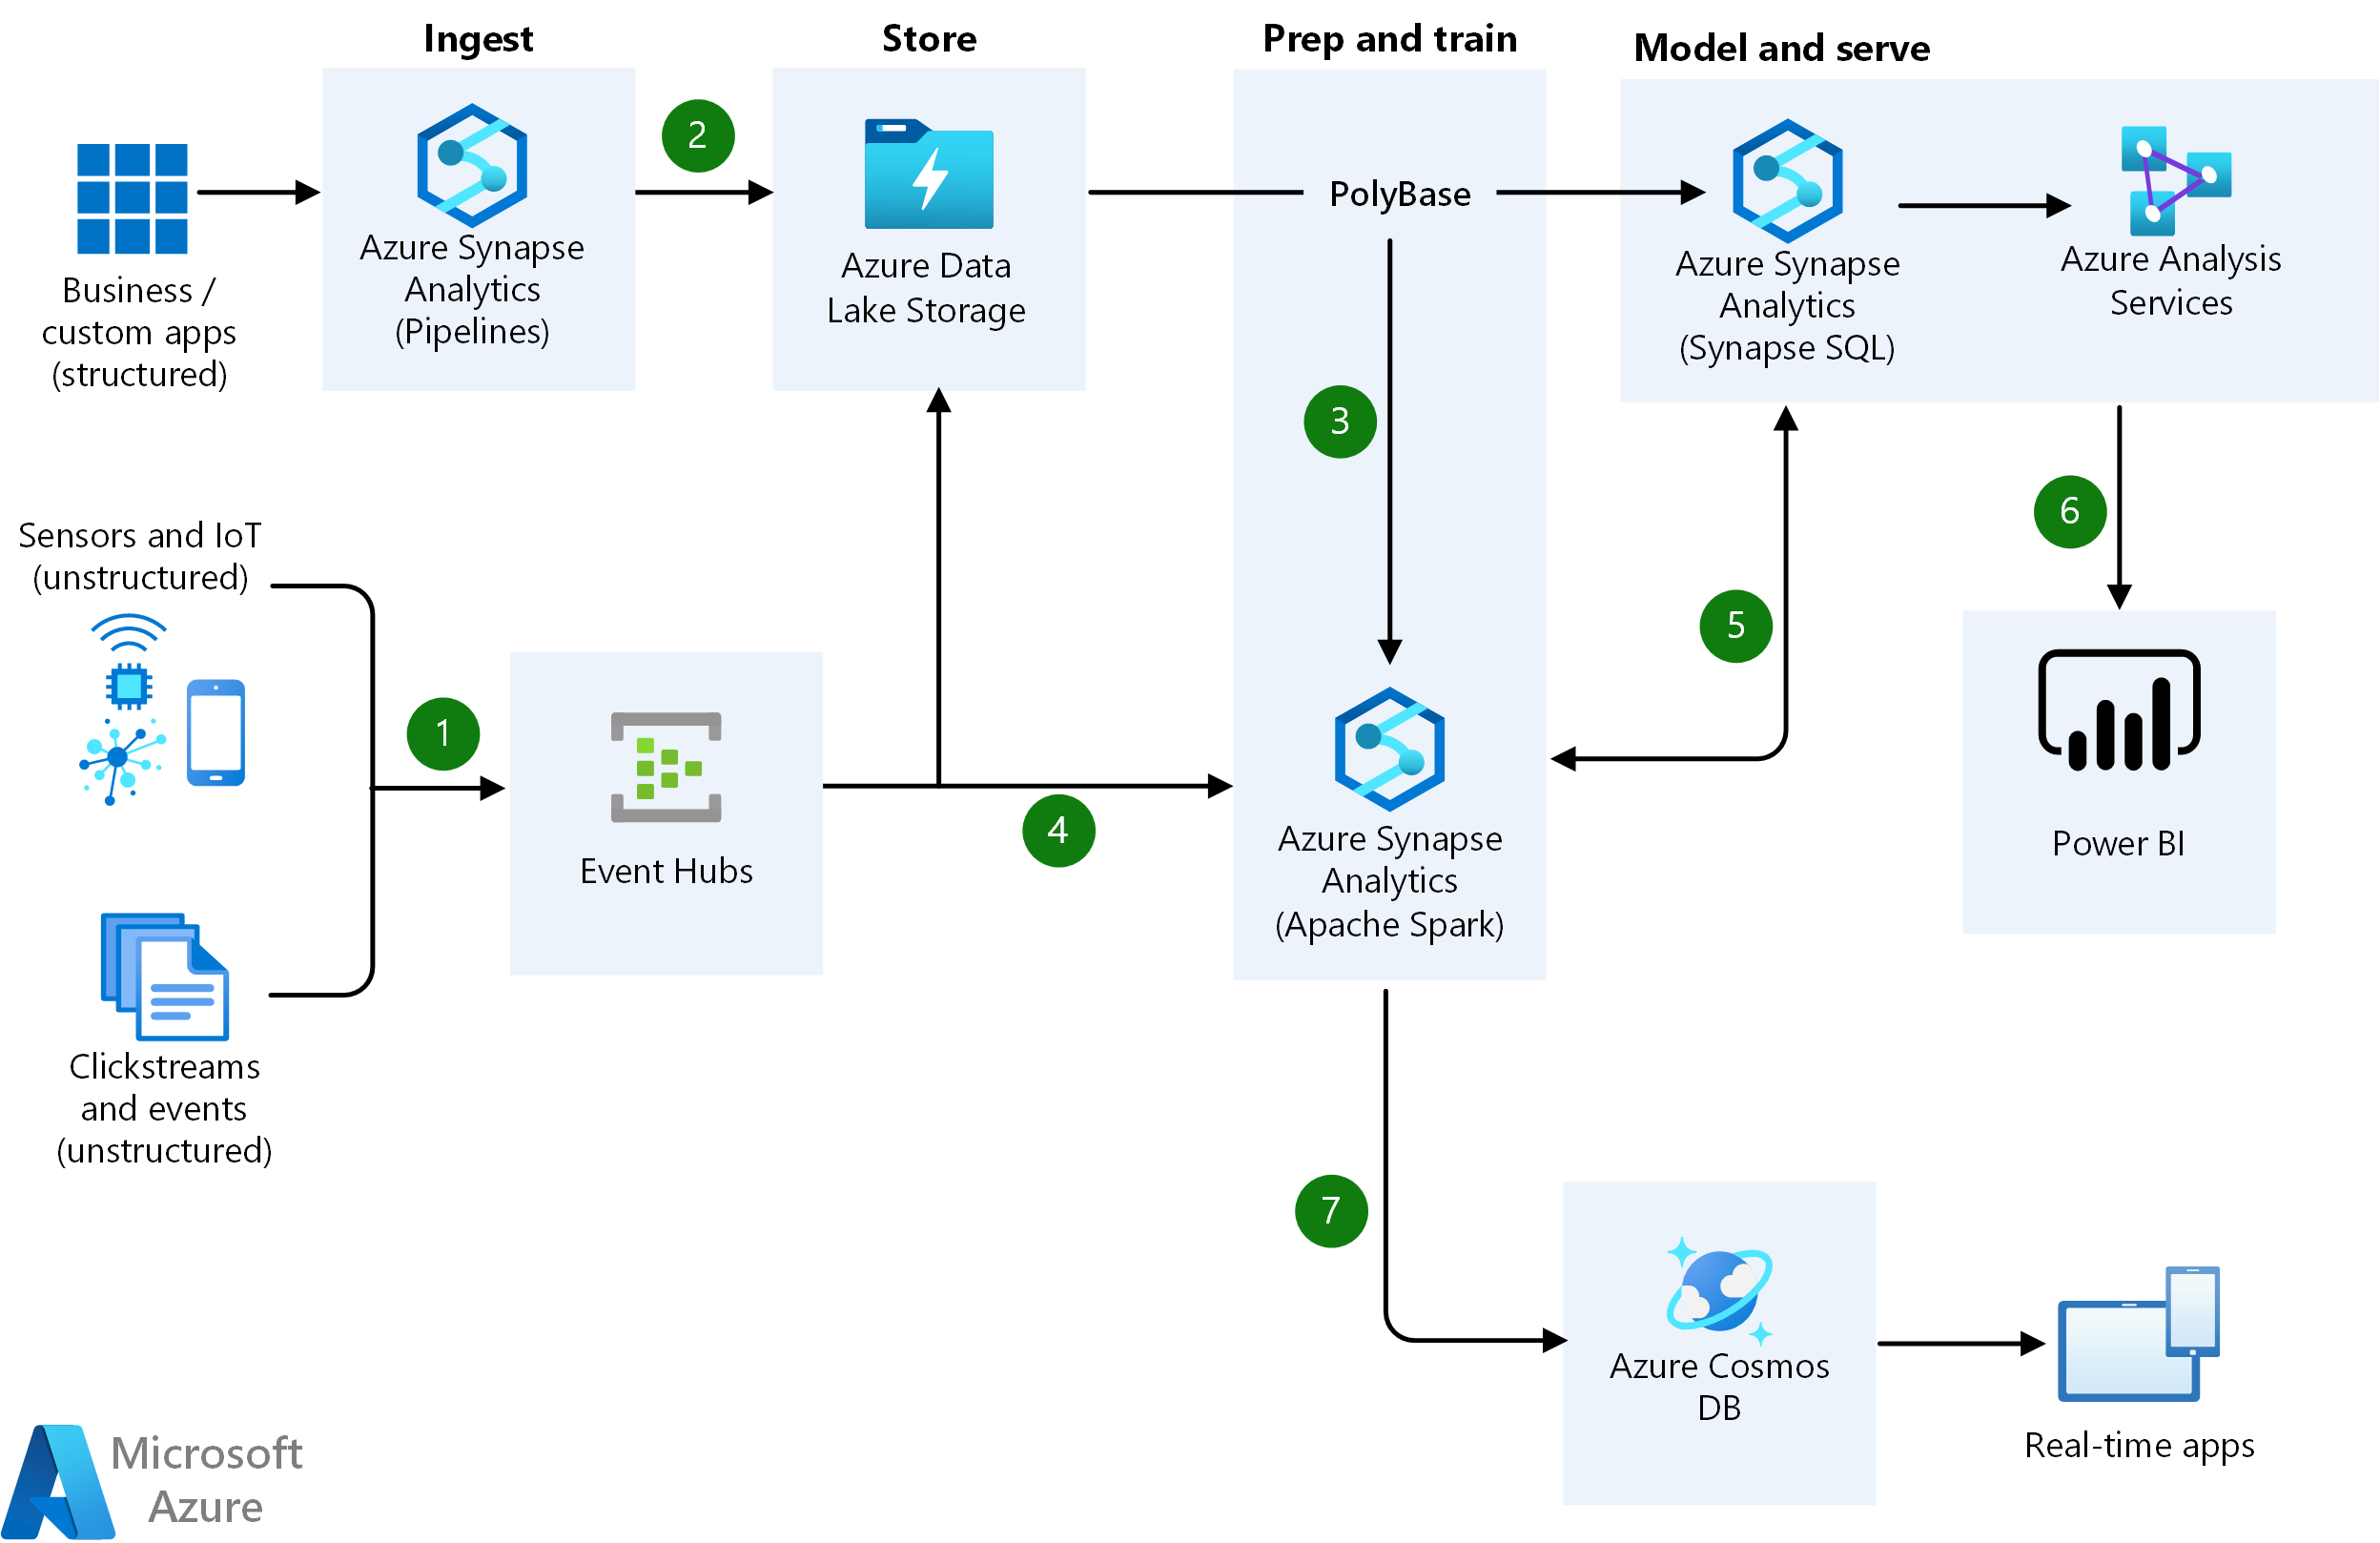
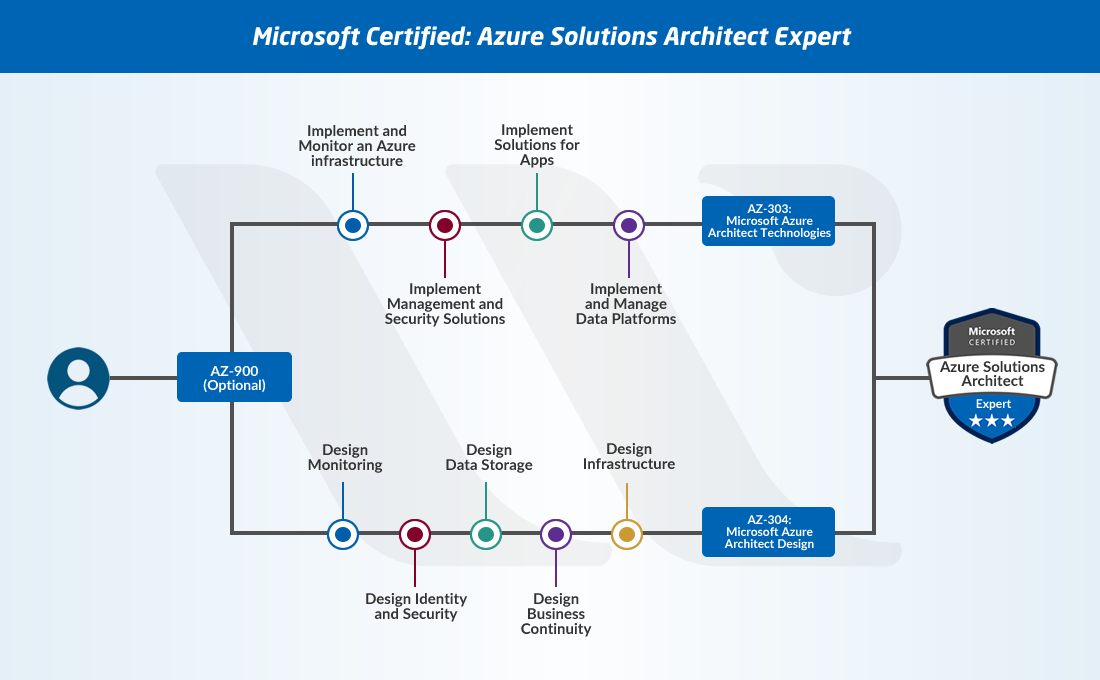
The AZ-305 Azure Solutions Architect Expert certification is the standard credential employers look for when hiring for Azure data architecture roles. The exam covers design for identity, governance, monitoring, storage, and compute. It also tests your ability to make decisions about data platform architectures. The Azure Data Solution Architect track sits within this broader certification but focuses specifically on data workloads. Most people confuse the two. They are related but different. This role is about designing data solutions on Azure. You pick storage tiers. You choose between Synapse, Databricks, and Data Factory. You decide where data lakes belong and how governance works. You figure out real-time versus batch processing. That is the core of it. The exam questions are scenario-based, which means you need practical understanding, not just memorization. I have worked through dozens of these architecture scenarios with clients. One thing that consistently trips people up is the difference between Azure Data Factory and Synapse pipelines. People treat them as the same thing. They are not. Synapse pipelines are built on ADF technology, but they have different capabilities and limitations. When you are building a data orchestration layer inside Synapse, you cannot reuse certain ADF connectors. You have to plan for that upfront.
Another common issue I ran into with a customer involved managing large-scale ETL workloads across multiple data centers. They tried to push everything through a single Synapse workspace and it became unmanageable. The workaround was to split the architecture into separate workspaces by domain and use ADF as the orchestrator on top. This gave them the isolation they needed without losing centralized monitoring through Log Analytics.
Core Topics You Need to Master
There are four main areas on the exam related to data architecture. The first is data storage strategies. This includes blob storage tiers, Data Lake Storage Gen2, managed disks, and file shares. You need to understand when each one makes sense. Most people know blob storage but underestimate the performance characteristics of ADLS Gen2 for analytics workloads. The second area is compute services. This covers Synapse SQL pools, Databricks, Spark, and serverless options. You need to know when to use dedicated SQL pools versus serverless SQL pools. Dedicated pools are better for consistent, predictable workloads. Serverless is cheaper for sporadic queries but has cold-start latency that can hurt interactive dashboards. Governance and security is the third area. Purview is the key service here. You need to understand data cataloging, classification, and lineage. Many people skip this part of their study plan because it feels dry. It is not optional on the exam. Questions about compliance, access control, and audit trails appear frequently.
Get the Full Details
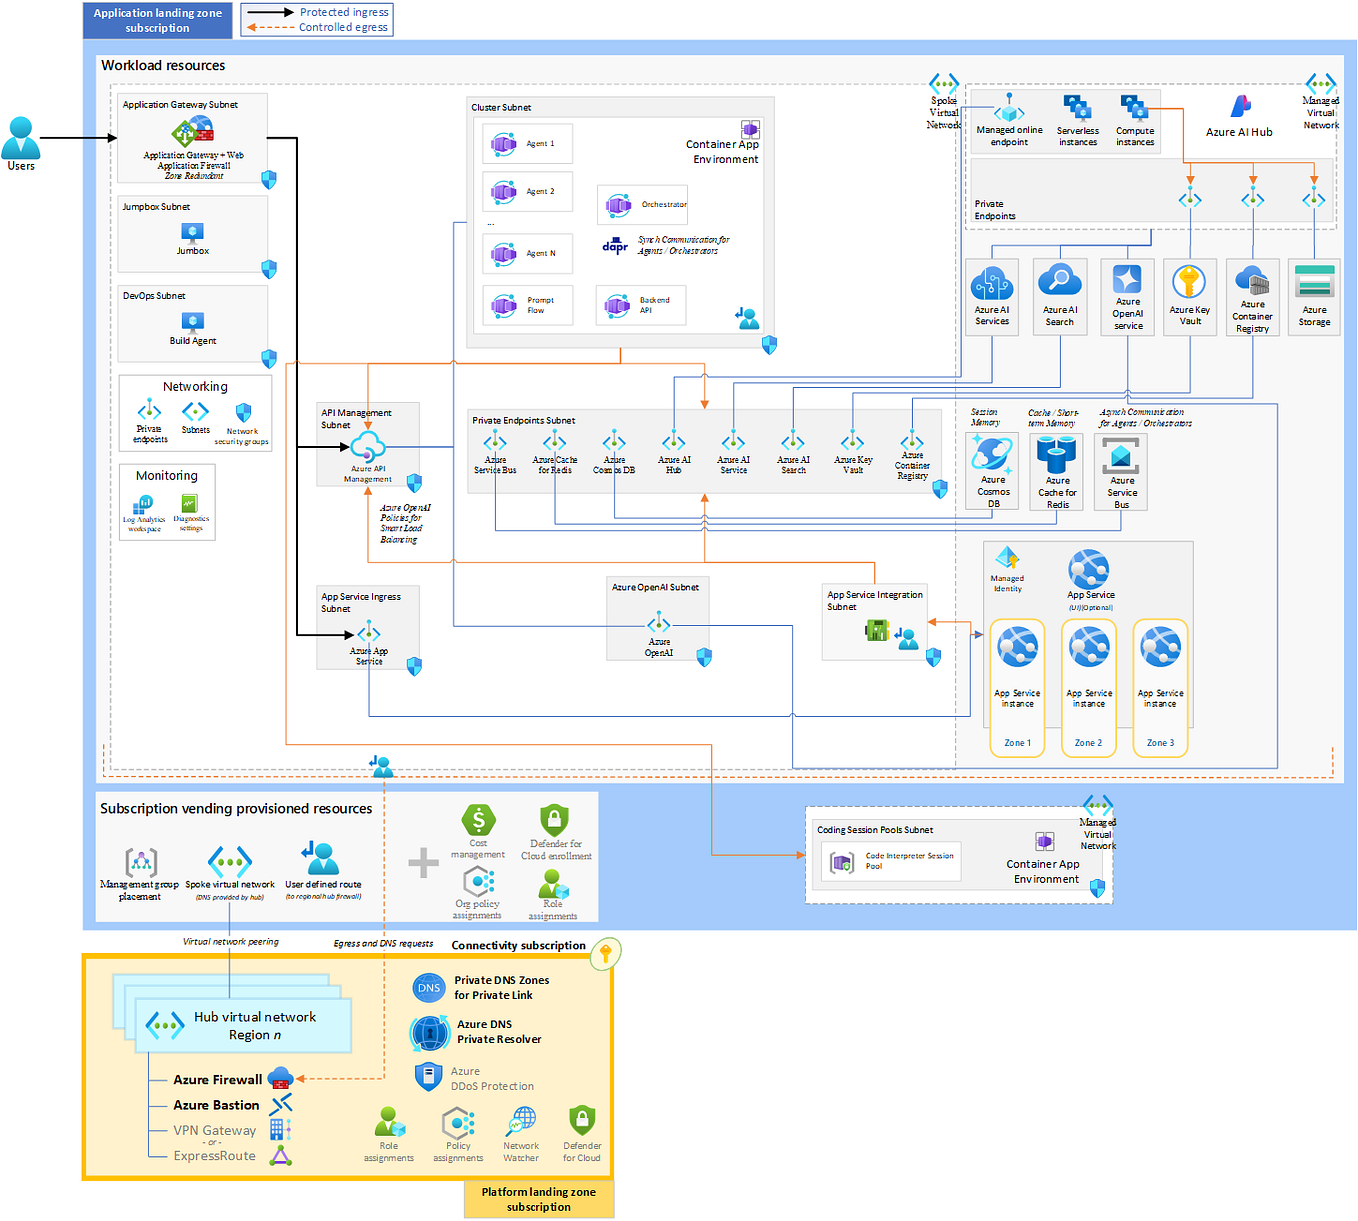
The fourth area is monitoring and optimization. This involves Application Insights, Log Analytics, and cost management tools. You should know how to set up alerts for pipeline failures and storage costs. You should also understand how to read query plans in Synapse to identify bottlenecks.
Practical Guidance for Building a Data Solution
Start with the workload. I know that sounds obvious, but I have seen too many projects where people pick tools first and figure out the workload later. If you are processing high-volume streaming data, Event Hubs and Stream Analytics might be your starting point. If you are doing batch ETL on structured data, Synapse SQL pools make more sense. One thing that catches people off guard is the cost model for Synapse dedicated SQL pools. It charges per DWU per hour, even when the pool is paused, for certain configurations. The official documentation mentions this in a footnote. A customer of mine had a budget spike because they did not realize their development pool was not pausing correctly. The fix was setting up proper auto-pause policies and using resource classes to manage concurrency. For data movement, ADF Copy activity is reliable, but it has limitations with schema drift. If your source data schema changes frequently, consider using Databricks notebooks for the transformation layer instead. They handle schema evolution much better. I built a pipeline using ADF for ingestion and Databricks for transformation, and it cut our rework time significantly compared to trying to force everything through ADF mapping data flows.
Common Pitfalls and What to Watch For
Overcomplicating the architecture is the biggest mistake. People love to use every tool available. They add Event Hubs when a timer trigger would work. They add Databricks when a simple SQL query does the job. The best architectures use the simplest tool that fits the requirement. This also matters for cost and maintainability. Another pitfall is ignoring data governance from the start. Purview can be added later, but it is much harder to retroactively catalog data and build lineage. I worked with a team that tried to bolt governance onto an existing pipeline. It took three weeks of manual work to map relationships that a well-placed Purview scan would have captured in hours. There is also the question of when NOT to use Azure data services. Sometimes an on-premises solution or a different cloud provider is simply better. Azure is excellent for many data workloads, but if your organization has deep investments in Snowflake or big data clusters elsewhere, forcing everything into Azure just for the sake of it is not a good architectural decision. Evaluate the actual fit.
How to Prepare Effectively
Hands-on practice matters more than reading documentation. Set up a free Azure account and build a simple pipeline. Move data from a CSV file in blob storage through ADF into Synapse. Add a Databricks notebook for transformation. Then connect Purview and watch the lineage appear. This practical exercise will teach you more than any study guide. The Microsoft Learn platform has free training modules for the AZ-305 exam. The official documentation is also thorough, though sometimes dense. I found the Microsoft documentation on Synapse serverless SQL queries to be particularly useful for understanding query performance characteristics. Read it with a test environment open. Practice exams can help, but do not rely on them exclusively. Some practice questions are outdated or focus on features that have changed. Use them as a general gauge of your readiness, not as a definitive predictor. The actual exam questions tend to be more scenario-heavy and nuanced than most practice tests.
If you want the official exam details and registration, go to the Microsoft Certification website. Search for AZ-305. There is no separate exam for the Azure Data Solution Architect specialization. It is covered within the Solutions Architect Expert exam. The data-focused questions typically make up roughly a third to a half of the total question count, depending on the version of the exam at the time you take it.
Azure Data Solution Architect Exam Preparation Notes
Focus your study on the scenario-based questions. These are the ones that test real understanding. Practice reasoning through trade-offs. For example, if asked to choose between dedicated and serverless SQL pools, consider query patterns, data volume, and cost constraints. There is rarely a single correct answer, but there are definitely wrong ones. Review the service limits and quotas for each data service. Knowing that Synapse dedicated SQL pools have a maximum of 120 DWUs per pool in some configurations can help you answer questions about scaling strategies. These details are often the difference between two close answer choices on the exam. Finally, do not underestimate the governance section. Data security, compliance frameworks like GDPR and HIPAA in an Azure context, and Purview configuration are all fair game. Build a small Purview setup in your lab environment and go through the process of scanning a data lake, creating classifications, and viewing lineage. It takes about an hour and will pay off on exam day.