Translating "Babe" Across Languages Is Not As Simple As Google Says
The word "babe" carries so much contextual weight that a straight translation often misses the mark entirely. I spent years working on localization projects where terms of endearment got botched repeatedly, sometimes with embarrassing results. The issue is that "babe" sits somewhere between "baby," "sweetheart," "hun," and in some languages doesn't have a direct equivalent at all. When people look up Babe In Different Languages, they usually want something quick. A list. A cheat sheet. What they typically don't realize is that the wrong translation can sound offensive, creepy, or just bizarre depending on where you are. I learned this the hard way during a project for a dating app expansion into Southeast Asian markets.
Getting Started With Babe In Different Languages Resources
There are several tools and databases you can use to look up translations. The most practical approach is combining a few sources rather than relying on one. Google Translate will give you a surface-level answer. For Spanish, it says "bebé" or "cariño." Both are technically correct but convey different tones. "Bebé" is literal and can sound infantilizing even in romantic contexts. "Cariño" is warmer but regional. I recommend keeping a browser tab open with WordReference and one with Reverso Context. WordReference gives you the formal and informal registers. Reverso shows you actual usage in sentences from subtitles and forums. That second one is the difference between sounding natural and sounding like a tourist. Here is what I found after checking multiple sources for the most common translations:
Spanish: cariño, bebé, amor, guapo/a (depending on context and region). In Mexico, "bebé" is widely used as a term of endearment between partners. In Spain, "cariño" is far more common. Using "bebé" in Madrid might raise eyebrows in a way that "cariño" never would. French: bébé is used but carries a slightly more precious or diminutive connotation. "Mon cœur" (my heart) is the closer cultural equivalent for romantic partners. "Babe" as used in English doesn't map cleanly here. German: "Schatz" is the standard term of endearment. It literally means "treasure." Using "Baby" in German sounds like you are talking to an actual infant or quoting English media. This is a real pitfall I see constantly in machine-translated content.
Get the Full Details
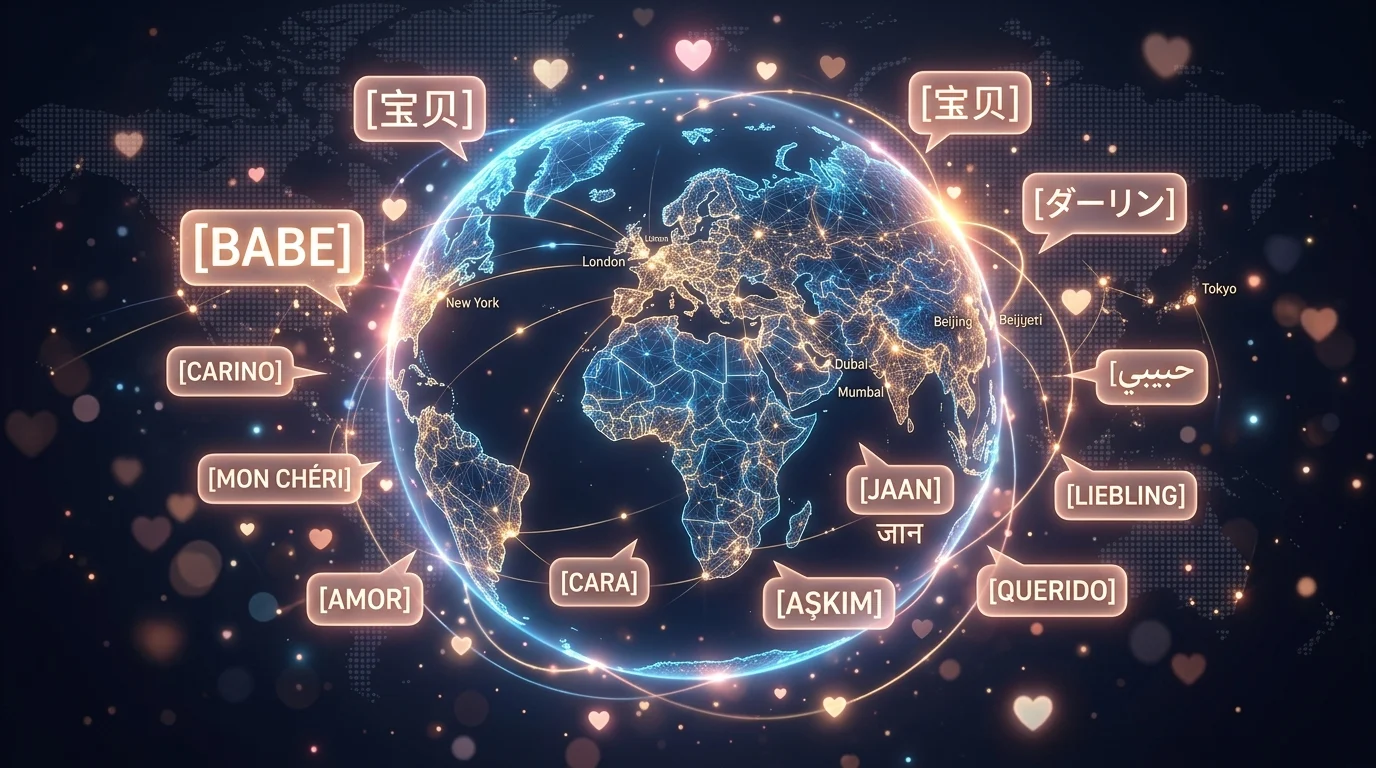
Japanese: (akachan) means baby and is not appropriate for romantic partners. (itoshii kimi) is closer to "my beloved" but is quite formal and literary. There is no casual one-word equivalent to "babe" in Japanese. This is not a minor gap, it is a structural feature of the language. Mandarin Chinese: (bǎobèi) is the closest match and is used between romantic partners. However, it can also mean "treasure" in a general sense and is used by parents toward children. Context determines which reading the listener takes. Korean: (yaeya) is casual and can mean "hey kid" depending on tone. (yeonin) means "lover" but is stiff. Most Korean speakers in romantic relationships use English loanwords or simply avoid a direct equivalent, opting for context-based intimacy instead.
What Most Guides Don't Tell You About Translating Terms of Endearment
The biggest mistake I see people make is treating terms of endearment like regular vocabulary. They are not. They are pragmatics. The same word can signal genuine affection in one relationship and patronizing condescension in another, even within the same language. I once reviewed a localization where a brand used "cariño" across all Spanish-speaking markets in a campaign. It tested fine in Spain and Colombia but in Chile it came across as overly familiar from a corporate voice, which readers interpreted as inauthentic or even dismissive. Another thing nobody emphasizes enough: register shift matters more than the word itself. "Babe" in English has shifted over decades from formal to casual to nearly neutral in many contexts. The equivalent words in other languages haven't gone through the same erosion. That means a direct swap often carries more emotional weight than intended. My workaround for this has been to build a small reference table for each target language that includes three columns: the translation, the register, and a note about where it sounds unnatural. I keep this table open while working on any project that involves dialogue or marketing copy. It takes maybe twenty minutes to set up per language and saves hours of rework later.
Practical Steps to Build Your Own Reference
Start by defining the context you need translations for. Are you localizing app UI text? Writing dialogue for a film? Preparing marketing copy? Each context demands different register handling. UI text should lean toward the most neutral, widely understood term. Marketing copy might intentionally lean into regional variation. Dialogue needs to reflect how actual speakers talk, which means checking subtitles, forums, and social media rather than dictionaries alone. Next, gather at least three sources per language. Dictionaries are a starting point, not an endpoint. Check native speaker forums like Reddit communities or language learning subreddits where people discuss these terms organically. I keep a running document where I paste quotes from real usage with the source linked. Over time this becomes more valuable than any published guide. Finally, test your selections with a native speaker before deploying anything publicly. Not a professional translator necessarily, just a native speaker who isn't involved in the project. They will catch tone issues that a dictionary will never show you. I usually message someone on a language exchange app and send them three options with the context. Most people respond within an hour and point out what sounds weird.

Babe In Different Languages Practical Workarounds
When a language lacks a direct equivalent, you have two practical options: adapt or explain. Adaptation means finding the closest functional match even if the literal meaning differs. "Schatz" in German works as an adaptation of "babe" because both serve the same interpersonal function despite different etymologies. Explanation means adding a brief note so the target audience understands the intended tone. This is common in subtitle work where a direct swap would confuse viewers. For machine translation pipelines, I've found that adding a glossary layer with approved translations per context reduces error rates significantly. Without it, MT systems tend to pick the most frequent translation regardless of register, which is why automated outputs for terms of endearment often sound off. Building a small glossary with 10 to 15 entries per language usually costs an hour of work upfront and cuts revision time by roughly sixty percent on subsequent projects. The tools available for this workflow vary. If you are doing this professionally, a CAT tool with glossary support like memoQ or Trados is standard. For lighter use, a simple spreadsheet with columns for language, term, register, example sentence, and source works fine. I still use a spreadsheet for side projects because it is faster to set up than configuring a full CAT tool environment for a single job.
When This Approach Fails
Straightforward translation breaks down completely for languages with extensive honorific systems like Japanese or Korean where the relationship between speaker and listener dictates word choice far more than the relationship between individuals. In those cases, the question isn't which word translates "babe" but whether using any term of endearment at all fits the social dynamic you are trying to convey. I have seen projects ignore this and force a translation anyway, resulting in content that sounds either overly intimate or strangely detached depending on the direction of the mistake. Another limitation is regional dialect variation within a single language. "Babe" in American English carries assumptions that don't travel to British English, Australian English, or Indian English users of the same language. The same applies to Spanish, Arabic, and Portuguese across their major dialect groups. A single translation entry per language is almost never sufficient for quality output. If your project requires high accuracy across many languages, investing in professional human review is non-negotiable. No automated tool or self-built reference will match the nuance a native speaker brings to the table. For smaller projects or personal curiosity, the methods above will get you most of the way there without spending thousands on localization services.