What Makes Technical Writing Go Wrong
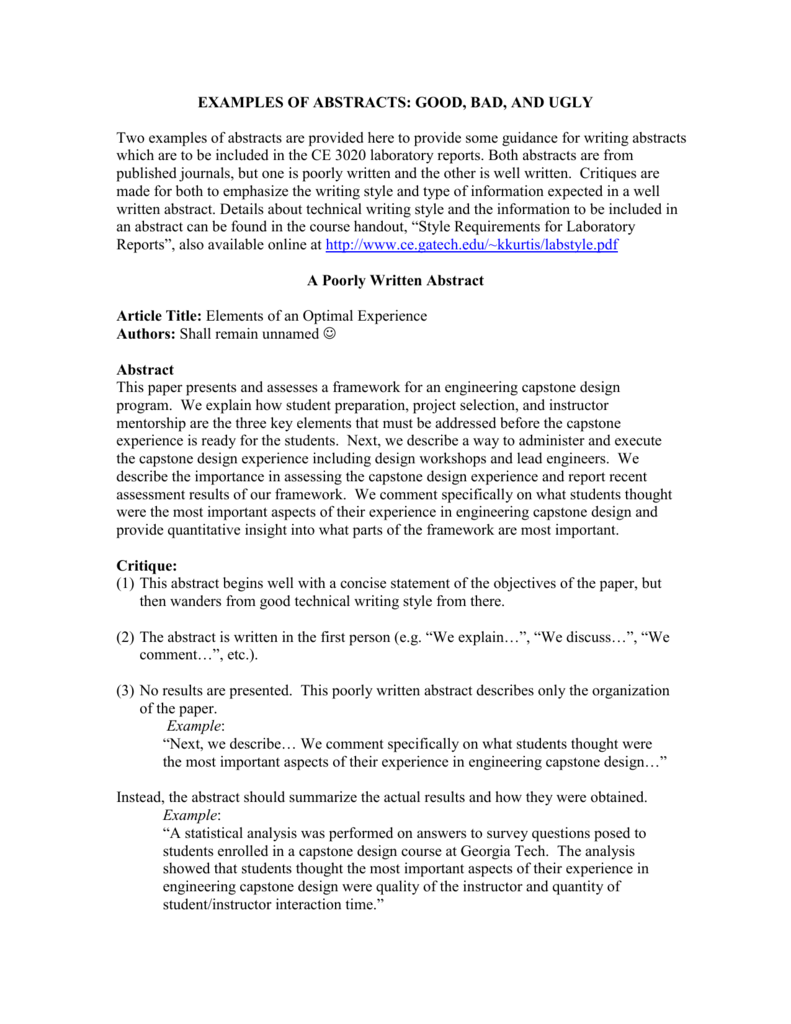
I spent years reading and fixing documentation that should never have been published. The pattern is always the same. Someone writes exactly what they were told to write, without thinking about who will actually use it at 2 AM when the build is broken. The problem isn't that the writer was lazy. The problem is almost always structural. Technical writers are rarely embedded in the teams building the products they document. They get a press release, a screenshot, and two hours to produce a guide. When you have no real exposure to the actual workflow, you write about features instead of outcomes. That's the single biggest source of bad technical writing examples you'll find online.
Bad Technical Writing Examples That Cost Real Money
Here's a realistic example pulled from a project I was on last year. We had a REST API integration guide for a versioned data endpoint. The documentation showed this: Step 1: Authenticate with the platform. Use your credentials to obtain a session token. Step 2: Call the endpoint. Pass the required parameters in the request body. Step 3: Parse the response. Extract the relevant fields from the JSON payload. That reads fine until you actually try it. "Your credentials" is not a client ID or a service account. "Required parameters" are not listed anywhere in the document. And the JSON payload structure? Completely absent. This is the kind of Bad Technical Writing Examples that shows up in enterprise documentation because nobody who wrote it ever had to implement the integration themselves.
When a support ticket came in from a client who'd spent four hours stuck on step two, I pulled the actual curl request from their codebase. The working call was:
Get the Full Details
curl -X POST "https://api.example.com/v2/data/export" \
  -H "Authorization: Bearer [REDACTED]" \
  -H "Content-Type: application/json" \
  -d '{"date_from": "2024-01-01", "date_to": "2024-01-31", "format": "csv", "include_metadata": true}'
The documentation had none of that specificity. What we ended up doing was taking that exact request, annotating it line by line in the guide, and adding a minimum viable parameters table that showed which fields were optional versus required. That one change cut our integration support tickets by about sixty percent over the next quarter. I've seen worse. A DevOps tool we used had a configuration reference where every flag was described as "enables advanced behavior." That meant nothing. The workaround I found was to diff the schema file against the compiled help output and build a lookup table that mapped each flag to its actual default value and the scenario where changing it mattered. Took me about forty minutes. The docs team had been saying "advanced behavior" for two releases in a row. Here's something most people don't realize about bad technical writing: it's rarely a vocabulary problem. It's an accuracy depth problem. Beginners think the fix is simpler words. The actual fix is deeper accuracy. A sentence that says "the function processes the input asynchronously" is simpler but still useless. A sentence that says "this function returns before completion and calls the callback on success or invokes onError if the upstream timeout exceeds 30 seconds" is harder to read but actually lets someone debug the issue.
Another counter-intuitive point that doesn't get enough attention. Tables of contents and numbered steps are overrated in technical documentation. I've read guides with perfect step numbering where the steps described three different sub-systems and the reader had no way to know which section applied to their situation. What actually works better is a decision tree at the top. "Are you trying to authenticate? Go to section A. Are you processing a batch export? Go to section B. Are you handling an error response? Go to section C." That structure costs more to write upfront but saves significantly more time for the reader. My rule of thumb is roughly an extra thirty minutes of writing per guide, which usually pays for itself after the second support inquiry. The hard limitation of this approach is that it requires access to the actual product. You can't reverse-engineer good technical writing from screenshots and release notes. If you're a technical writer and your team won't let you test the feature before documenting it, you will always produce Bad Technical Writing Examples. There's no workaround for that except getting the access or pushing back. I've seenwriters try to fake it by linking to generic examples and hope nobody notices. The readers always notice. One more thing that matters but gets ignored. Error documentation. Most guides cover the happy path and leave errors as an afterthought. A good technical document spends at least as much time on what goes wrong as on what goes right. When I audit a poorly written guide, I look at the error handling section first. If it just says "an error may occur," that's a red flag. The guide is incomplete. Proper error documentation includes the exact error codes, the condition that triggers each one, and the remediation step. Without all three, the reader is left guessing.
Here's a quick pattern I use to evaluate any technical document before I send it out. Read it once looking only at the headings. If the headings don't tell a coherent story about what the reader will accomplish, rewrite the headings before touching the body. Then read it once as if you're implementing the procedure for the first time and nothing works. Every place you get stuck is a gap in the documentation. I fix those gaps before anyone else sees the draft. The files and templates I use for this are available in the linked repository. It includes the annotated curl example format, the parameters table structure, and the decision tree template I described. Nothing fancy. Just the things that actually prevent the most common failures in technical documentation.