What Based Discourse Analysis Actually Is
Based Discourse Analysis is a method of examining how language constructs meaning in real social contexts. It doesn't rely on abstract theory alone. The approach grounds its claims in observable textual data and contextual evidence rather than speculation. You collect real texts, you trace how specific discursive moves operate, and you build your argument from what the data actually shows you. I've used this method for about six years now, mostly in organizational communication research. The early versions of my codebooks were messy because I was trying to force every utterance into pre-existing categories. That doesn't work well. The whole point of the "based" part is that your categories should emerge from the material, not the other way around.
The Core Workflow of Based Discourse Analysis
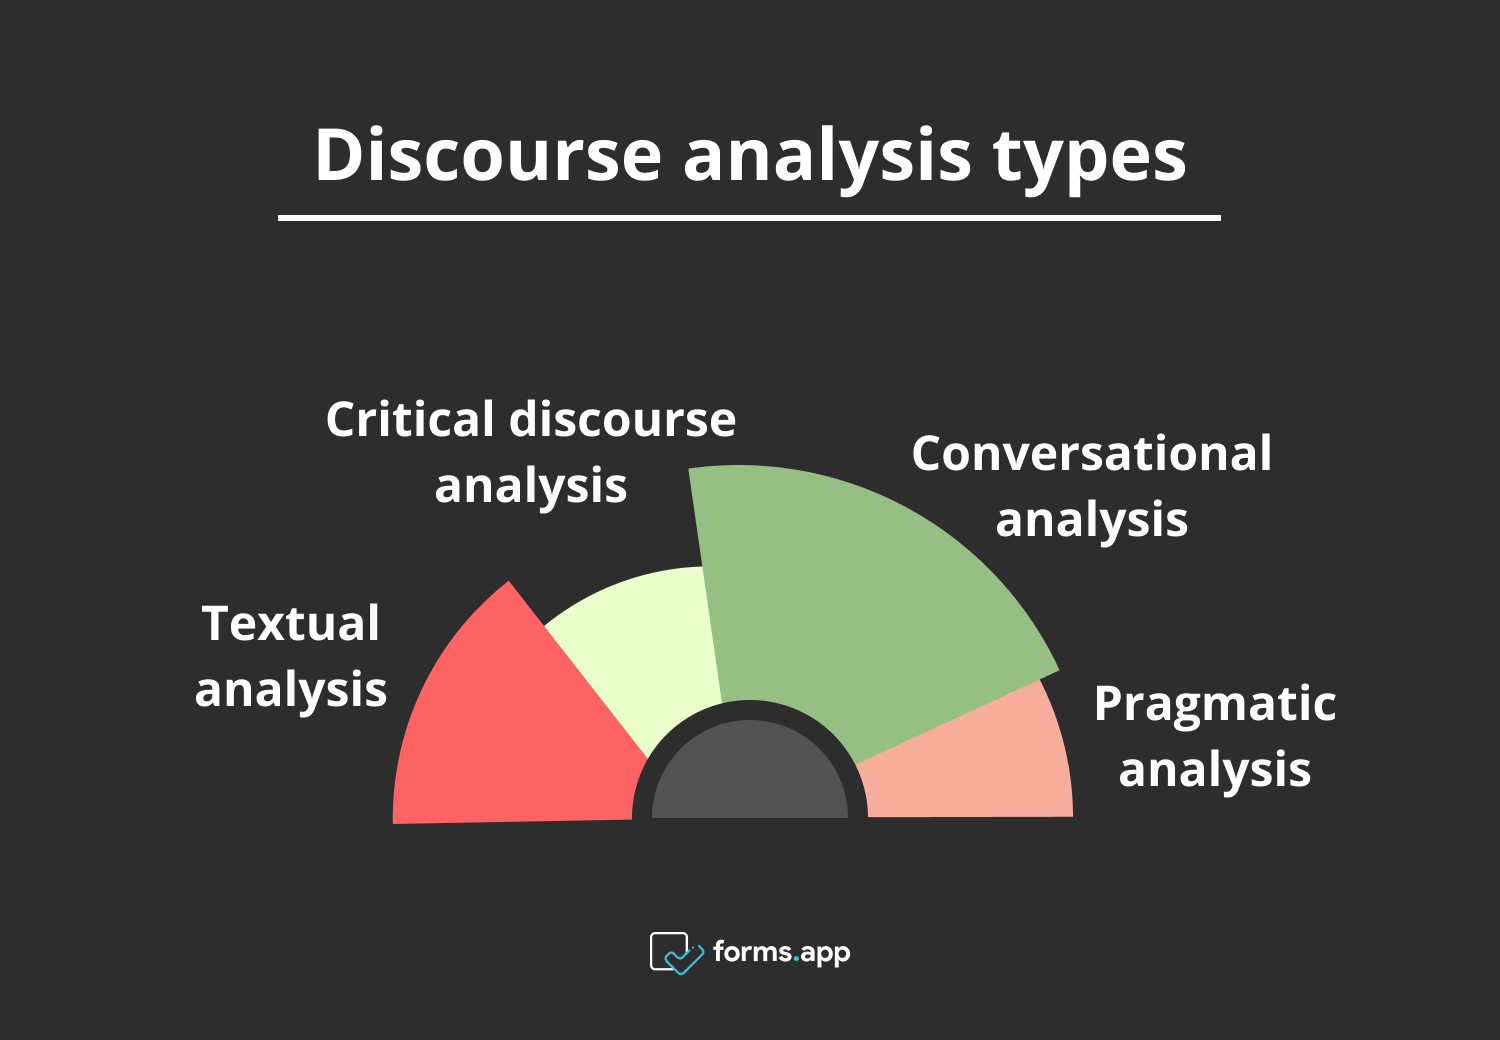
Here's what the process looks like in practice. First, you gather your corpus. This could be interview transcripts, social media threads, policy documents, meeting recordings, or any text where discourse is produced and consumed. The key is that the data has to be substantial enough to reveal patterns but focused enough that you can actually read it thoroughly. Second, you do initial coding without predefined categories. Read through the material and mark anything that seems discursively significant. This is where people tend to rush, and rushing here will cost you time later. I usually spend about a week on a 200-page corpus just doing this first pass. It feels slow. It's not slow. Third, you develop your analytical framework based on the patterns you found. This is different from traditional discourse analysis where you bring a theoretical lens like Foucauldian analysis or critical discourse analysis into the room from the start. Here, the lens forms after you've looked at the data. Your framework should account for the actual moves speakers and writers are making.
Fourth, you apply that framework back through the corpus and refine it iteratively. The framework changes as you encounter new data. This is normal. If your framework stays exactly the same after the third pass, you're probably not looking closely enough.
Get the Full Details
Common Mistakes People Make
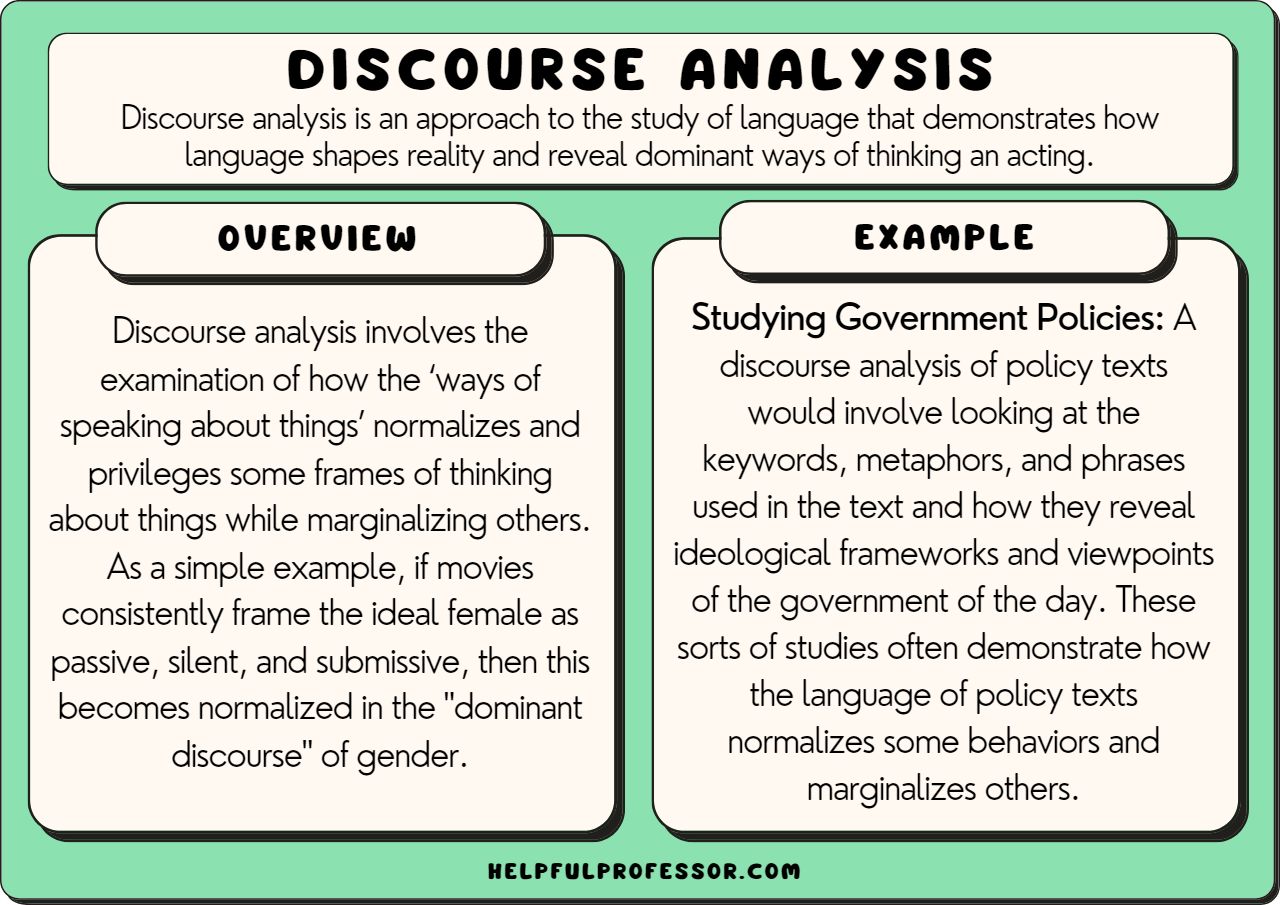
The biggest mistake I see is treating Based Discourse Analysis as if it means you don't need theory. You absolutely still need theory. What you're avoiding is theoretical priors that blind you to what the data is actually showing. You need enough theoretical grounding to recognize patterns when you see them, but not so much that you can't see patterns that don't fit your favorite theory. Another mistake is underestimating the importance of context. Discourse doesn't exist in a vacuum. A phrase like "we need to talk about this" means something completely different in a boardroom versus a family group chat versus a Twitter thread. I once spent two weeks trying to analyze a set of internal company Slack messages without understanding that the company had just gone through a merger. The discourse patterns I was seeing made no sense until someone explained the restructuring timeline. Context is not optional in this method. There's also a tendency to over-generalize from small corpora. If you analyze 15 tweets and conclude that a whole demographic holds a certain view, you haven't done Based Discourse Analysis. You've done opinion reporting. The method requires you to be honest about the scope of your claims relative to the scope of your data.
When Based Discourse Analysis Fails You
This method has real limitations. It works best when you have access to a reasonable volume of naturalistic text data. If you're studying something like parliamentary debate where the recorded discourse is heavily scripted and performative, the method can still work but you need to account for the performative nature of the data. If you have almost no textual data to work with, this approach will leave you with nothing to analyze. The iterative nature of the method also means it's not particularly time-efficient if you're working under tight deadlines. A thorough based discourse analysis of a moderate corpus typically takes between three and eight weeks depending on team size and data complexity. If you need results in a week, you're better off with a quick thematic analysis or content analysis. Those methods are faster and good enough for many purposes. There's also the problem of researcher subjectivity. Two researchers working from the same corpus will often develop different frameworks. This isn't necessarily a bug, but it can be frustrating if you need replicable results or if you're working in a field that prioritizes inter-coder reliability. I've seen projects derail because two analysts couldn't agree on whether a particular discursive move was an instance of framing, hedging, or strategic ambiguity. In those cases, bringing in a third analyst or using an established coding scheme as an anchor tends to help.
A Practical Tip from Experience
One thing that helped me significantly was keeping a detailed memos document throughout the process. Not just code definitions, but notes on why I was making certain analytical decisions, what bothered me about certain passages, and connections I noticed between seemingly unrelated texts. When I started doing this, my analysis became substantially more coherent because I could trace how my thinking evolved rather than pretending I arrived at conclusions fully formed. Another practical tip: use software but don't let software do your thinking for you. Tools like NVivo, Atlas.ti, or even simpler options like Dedoose can handle large corpora efficiently. I use them for organization and retrieval. I never let them generate codes or themes automatically. Automated coding in discourse analysis usually produces garbage because the algorithms don't understand pragmatic meaning, irony, or context. They count words. Discourse analysis is about meaning, not word frequency. The method continues to evolve as new types of digital discourse become relevant. Analyzing Discord servers or TikTok comment threads requires different sensitivities than analyzing newspaper editorials, but the core principle remains the same: ground your claims in the data and let the data shape your framework rather than forcing data into a framework you brought with you.