What Actually Happens When You Stop Counting Boxes by Hand
I spent three years running a small distribution warehouse before we replaced the spreadsheet system that was keeping us alive. Our original setup involved a printed manifest, a clipboard, and about twelve people calling each other on cell phones to confirm stock levels. We lost roughly fourteen percent of our annual inventory to untracked discrepancies. That number came from an external audit, not a guess. The transition wasn't clean. It rarely is with any operational change that large. But the long-term benefits became visible within the first ninety days. Revenue accuracy improved because we stopped selling things we didn't have. Labor costs for cycle counting dropped by about sixty percent. The main reason is that automated systems handle the data entry that humans would otherwise do poorly under time pressure.
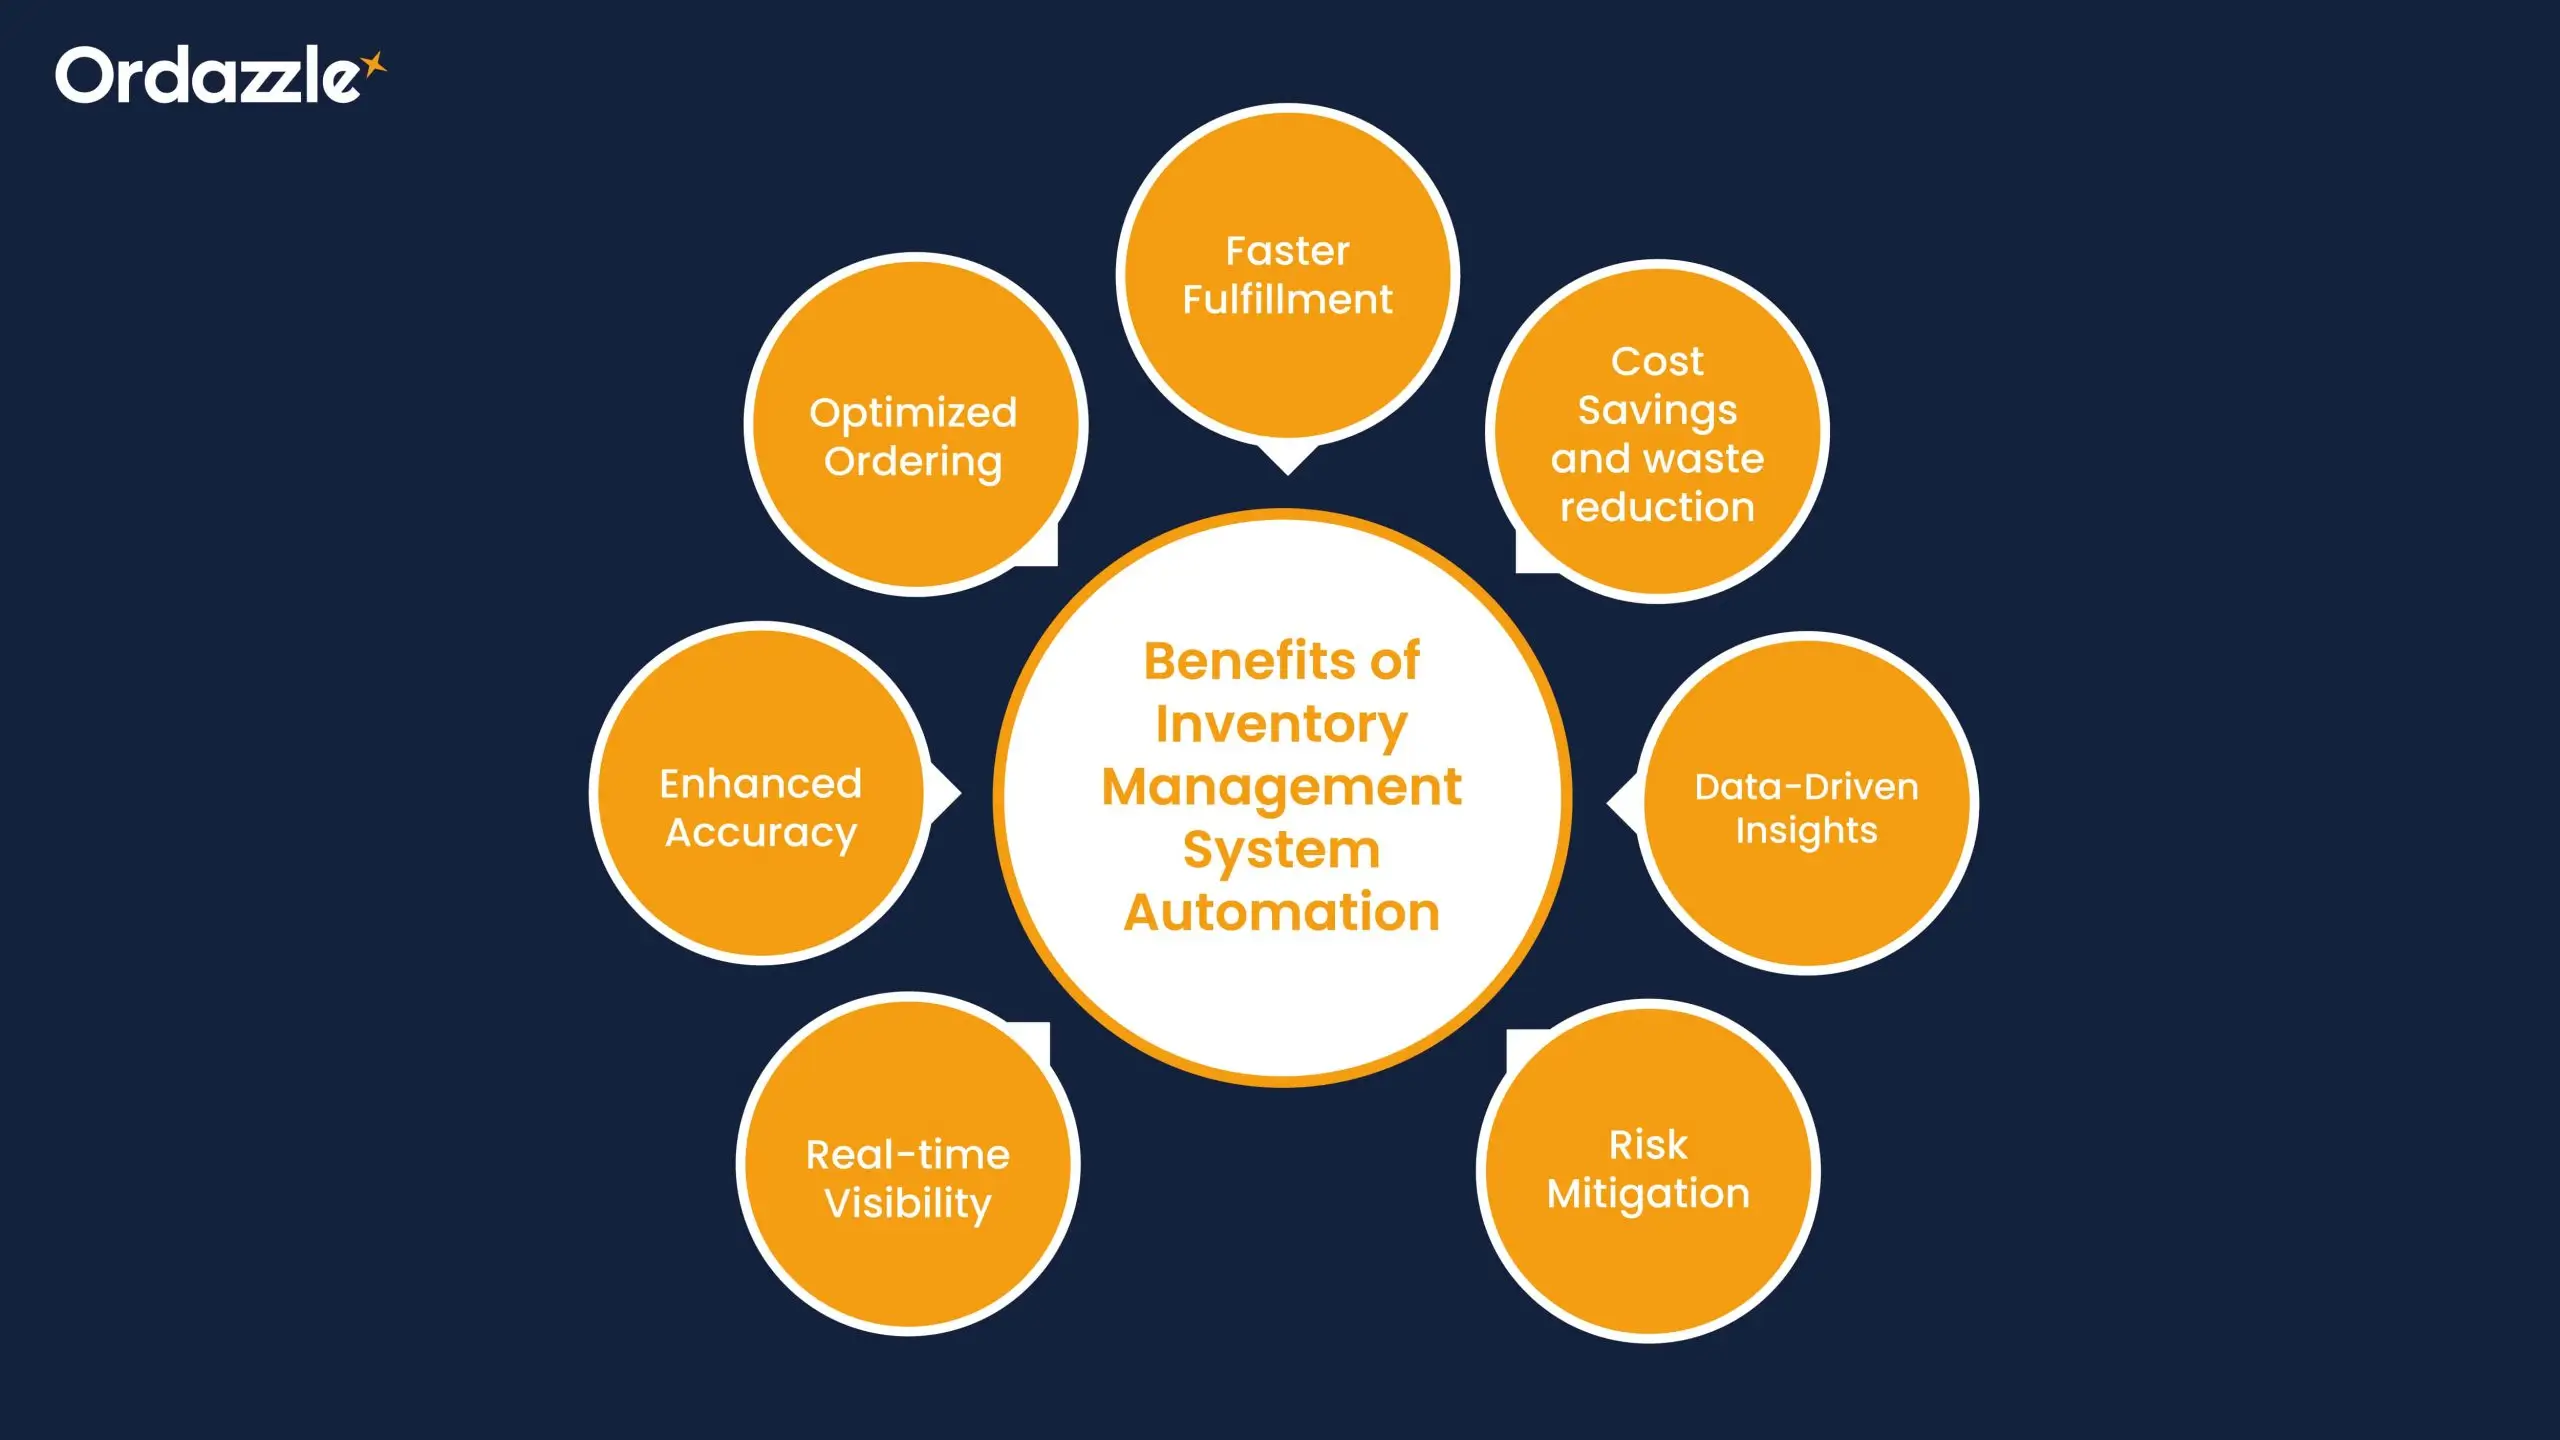
Understanding the Benefits Of Automated Inventory Management System
An automated inventory management system connects your point-of-sale terminals, purchasing workflows, and warehouse tracking through a central database. When a sale happens, the system reduces the tracked quantity. When a purchase order is received, it increases the quantity. The difference between manual and automated is mostly about latency and error rate. Manual entry introduces delays and transcription mistakes. Automation removes both variables, though it introduces a different set of configuration requirements. Here is something most guides don't mention: automated systems create more data than they solve problems with. A warehouse I consulted for in 2022 had automated their receiving process using barcode scanners and RFID tags. They immediately started generating over four thousand inventory event records per day. Their team had no protocol for analyzing that data, so the insights were sitting there unused. The system was doing its job correctly. The organization around it wasn't equipped to act on what the system produced.
How These Systems Actually Work Under Normal Conditions
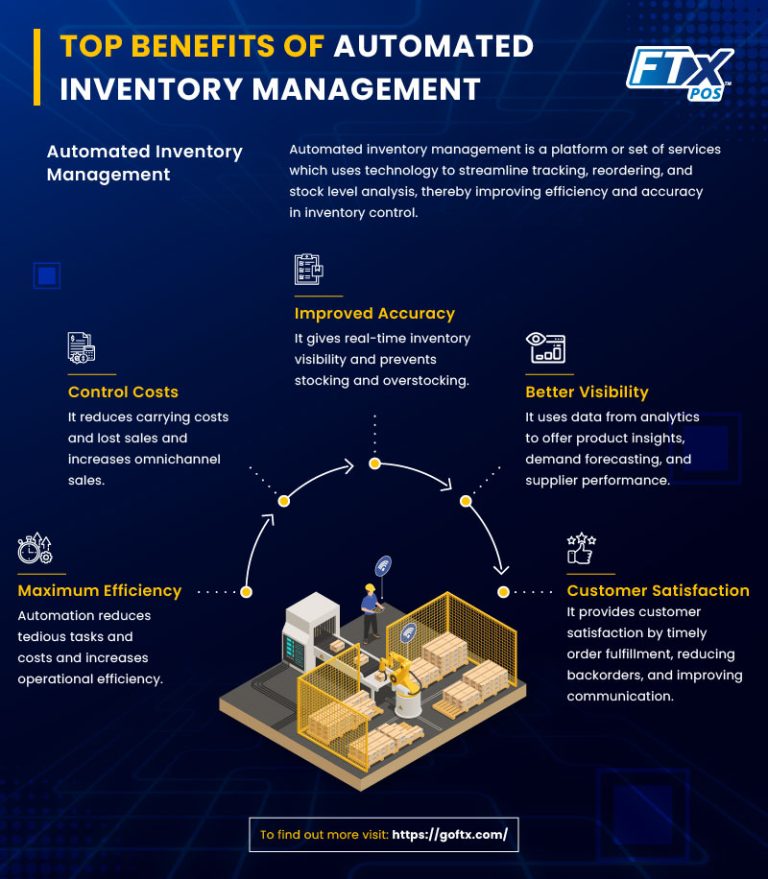
The basic architecture involves a central database, barcode or RFID scanning equipment, and integration layers that connect to your existing accounting or e-commerce platform. When an item arrives at your receiving dock, a worker scans the barcode on the incoming shipment. The system matches the scan against the open purchase order, updates stock levels, and flags any quantity variances for review. That part is straightforward. The less obvious part is how the system handles demand forecasting. Modern platforms analyze historical sales velocity, seasonal patterns, and supplier lead times to recommend reorder points. The algorithm isn't perfect, but it consistently outperforms human guesswork for SKUs with enough transaction history to build a reliable model. For new products with zero sales data, the system falls back to manufacturer lead time estimates and safety stock formulas. The recommendation is rough until you accumulate real data. I ran into a specific edge case with a client who sold products across multiple warehouses with different regional demand patterns. The automated system was set to replenish from the central warehouse based on aggregated demand data. This caused chronic stockouts in the coastal locations and overstock in the inland facility. The workaround was to disable cross-warehouse transfers for that category and configure each location as a separate demand node with its own reorder parameters. The system wasn't broken. The configuration was just too generalized for their actual business structure. It took two weeks to reconfigure properly, and inventory carrying costs dropped about eighteen percent after the adjustment.
Get the Full Details
Counter-Intuitive Things About Implementation That Nobody Warns You About
People expect the hard part of automation to be the technology. It almost never is. The hard part is getting your product data to exist in a consistent format before you feed it into the system. I've seen implementations stall for months because someone tried to digitize inventory that hadn't been cleaned up in years. Duplicate SKUs, mismatched units of measure, items listed under three different product names. The software can't reconcile that without manual intervention, and the volume of manual intervention required often exceeds what the automation would save. Another thing that catches teams off guard: automated systems expose process gaps that manual processes were quietly masking. When you were counting by hand, you could overlook a misplaced pallet or a receiving error and it never registered. Automation makes every discrepancy visible immediately. Some operations aren't ready for that level of visibility. Management needs to decide whether they want the truth more than they want the comfort of not knowing exactly how messy things actually are. There's also a hidden cost in system maintenance that most vendors downplay. Barcodes deteriorate. Warehouse lighting fails. RFID readers get knocked off alignment. A team that goes fully automated without budgeting for ongoing equipment maintenance and software updates will find their system degrading within six to twelve months. The decline is gradual enough that it looks like normal variation rather than a maintenance problem. By the time the errors become impossible to ignore, the data quality has been compromised for a long period.
What This Type of System Cannot Do
Automated inventory management doesn't fix broken supplier relationships. If your primary vendor consistently ships late or sends incorrect quantities, the system will accurately record those failures but it won't prevent them. You still need procurement discipline separate from the technology. It also doesn't eliminate the need for physical cycle counting. Most platforms recommend a regular cycle count schedule to reconcile the system records with actual physical inventory. Items get misplaced, damaged, stolen, or miscounted during receiving. The automation tracks transactions. It doesn't track reality when reality diverges from the documented flow. A well-implemented system with weekly cycle counts typically achieves discrepancy rates below two percent. A system without regular physical verification often drifts to five or six percent within the first year, which is worse than what you'd get from careful manual processes. For very small operations with fewer than two hundred active SKUs and simple buying patterns, the math may not favor automation. The monthly subscription cost, the implementation hours, and the ongoing maintenance often exceed the value gained. A well-maintained spreadsheet or a basic free-tier tool like inFlow Inventory or Zoho Inventory can handle low-volume operations adequately without the overhead of a full warehouse management system.
Practical Steps to Get This Running Without Breaking Your Operation
Start by cleaning your product data before you touch any software. Consolidate duplicate SKUs, standardize your units of measure, and create a single source of truth for product descriptions. This step alone takes longer than the implementation of most systems, but skipping it guarantees that the automated system will produce garbage data at high speed. Choose a system that integrates with your existing tools rather than replacing them entirely. An inventory platform that connects to your current accounting software, e-commerce storefront, and shipping carrier saves considerable integration work. Forcing your team to use a disconnected system creates duplicate data entry, which defeats the purpose of automation in the first place. Configure reorder points based on actual supplier lead times, not estimated ones. I've seen operators set minimum stock levels based on ideal conditions. When suppliers inevitably run late, the system triggers emergency purchases at premium pricing because the safety stock was calculated from best-case scenarios. Use the worst thirty percent of your historical lead times as your baseline for reorder calculations. That buffer prevents the panic purchasing that erodes margins.
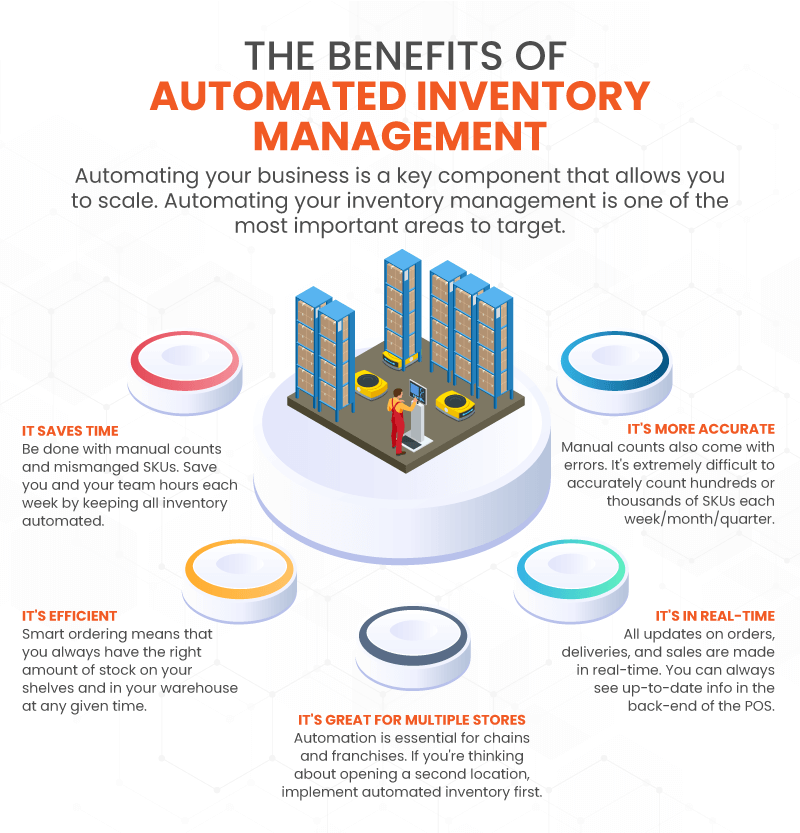
Train your receiving team on scanning discipline from day one. The single most common source of data corruption in automated systems is a receiver who scans the wrong item because two similar products look alike on the shelf. Standardize where incoming items are placed, require scanners to verify SKU numbers before accepting quantities, and run weekly audits comparing system records against physical counts for the highest-value items. The Benefits Of Automated Inventory Management System become clear when the underlying processes support it. The technology amplifies whatever you feed into it. Clean data and disciplined procedures produce accurate forecasts and tight stock control. Messy operations just produce faster mistakes.