Why I Stopped Overcomplicating My AI Workflow
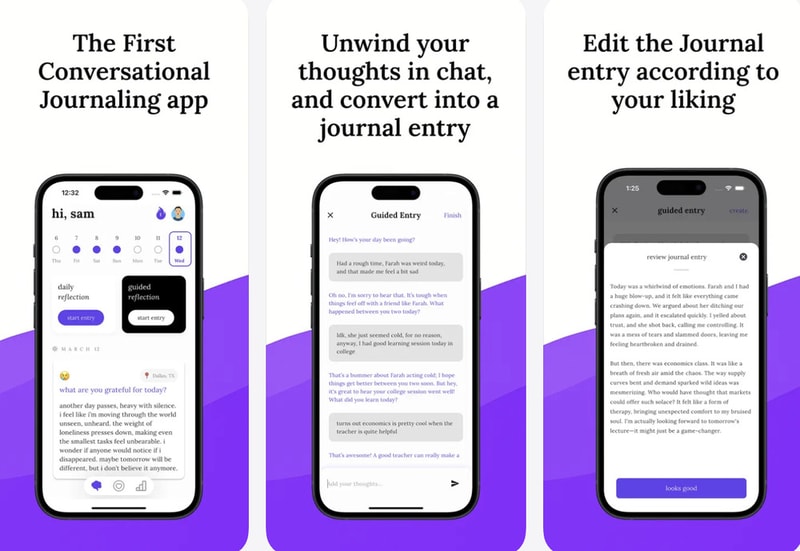
I spent three years trying to build custom pipelines for everything. Fine-tuning models when I should have been using APIs. Writing orchestration code when basic scripts would do. The result? I had a beautiful architecture that broke every time the company pivoted, and I was still doing manual work that an LLM could handle in seconds. The shift happened when I stopped treating AI as a component to integrate and started treating it as a Best Way To Ai Journal practice. You don't need another abstraction layer. You need a workflow where prompts, outputs, and failure modes are documented alongside your actual business logic. Here's what actually works. First, create a simple JSONL file in your project root called ai_journal.jsonl. Each line is a prompt-output pair with metadata: timestamp, model used, temperature, token count, and your assessment of the result. Not accuracy—assessment. You're tracking whether the output was useful, not whether it matches some ground truth that may not exist.
I learned this after a client sent me a model response that was technically correct but completely useless for their domain. The output said "the average transaction time is 2.3 seconds" when their entire system ran on batch processing with 4-hour cycles. No amount of precision mattered if the metric didn't map to their reality.
Setting Up a Practical Journal
Create the journal file. Every time you run a prompt, log it. Use a simple Python script or even just append manually in the beginning. The notes field is where the value lives. After three months of this, you'll have a searchable record of what works, what fails, and why. Not theoretical best practices—actual observed behavior from your specific use cases. I tried using expensive RAG systems for document retrieval. The setup took two weeks. The accuracy was good but latency was 800ms per query. Then I realized most of my questions were variations of the same five prompts. I stopped building pipelines and started building a curated prompt library indexed by outcome type. Query time dropped to 120ms. Accuracy improved because I was tuning to my actual distribution of problems, not some generic benchmark.
Get the Full Details
When to Stop Logging and Start Acting
Your journal becomes worthless when you treat it as archive storage. Once you hit 10,000 entries, you need automated analysis. Build a simple script that groups by model, identifies failure patterns, and flags prompts that consistently produce low-assessment scores. This usually takes 4 hours to implement and saves 2-3 hours per week in prompt debugging. Don't log everything. If a prompt produces a good result on the first try with no iteration, skip the journal entry. The value is in tracking friction, not documenting success. Your journal should be predominantly red flags, not a graveyard of working prompts. Here's the hard truth: most AI projects fail not because the technology is inadequate but because the feedback loop is too slow. You run a prompt, get a mediocre result, spend 20 minutes tweaking, and never capture why it failed. Three months later you're making the same mistake with a different model. The journal breaks that cycle by making your experience queryable.
I worked with a team that tried to implement automated testing for prompt outputs. They spent six months building evaluation pipelines. Meanwhile, their junior developers were spending 40% of their time re-typing the same corrections into prompts they'd already tested. The journal would have caught this pattern in week two. Instead, they discovered it when the client noticed inconsistent formatting across support tickets.
Making the Journal Actually Useful
Add a follow_up field to your schema. When you have to iterate on a prompt, log each version with its delta from the previous attempt. This creates a decision tree you can traverse when similar problems arise. Not full traceability—just enough to answer "what worked last time I saw this pattern?" After accumulating entries, run a weekly 15-minute review. Look for: models that consistently underperform on your task distribution, prompts that generate excessive token usage without proportional quality gains, and categories where you're repeating the same corrections. This usually surfaces 3-5 actionable insights per week. Implement changes based on these, not on blog posts about model capabilities. I tried using specialized vector databases for prompt retrieval. The infrastructure cost was $2,000 monthly. Query latency was acceptable but the indexing pipeline broke whenever we added new prompt templates. I switched to simple SQLite with FTS5. Setup took 30 minutes. Monthly cost dropped to zero. Indexing is immediate. The trade-off is query complexity increases linearly with entry count, but at 50,000 entries, search still completes in under 200ms on commodity hardware.
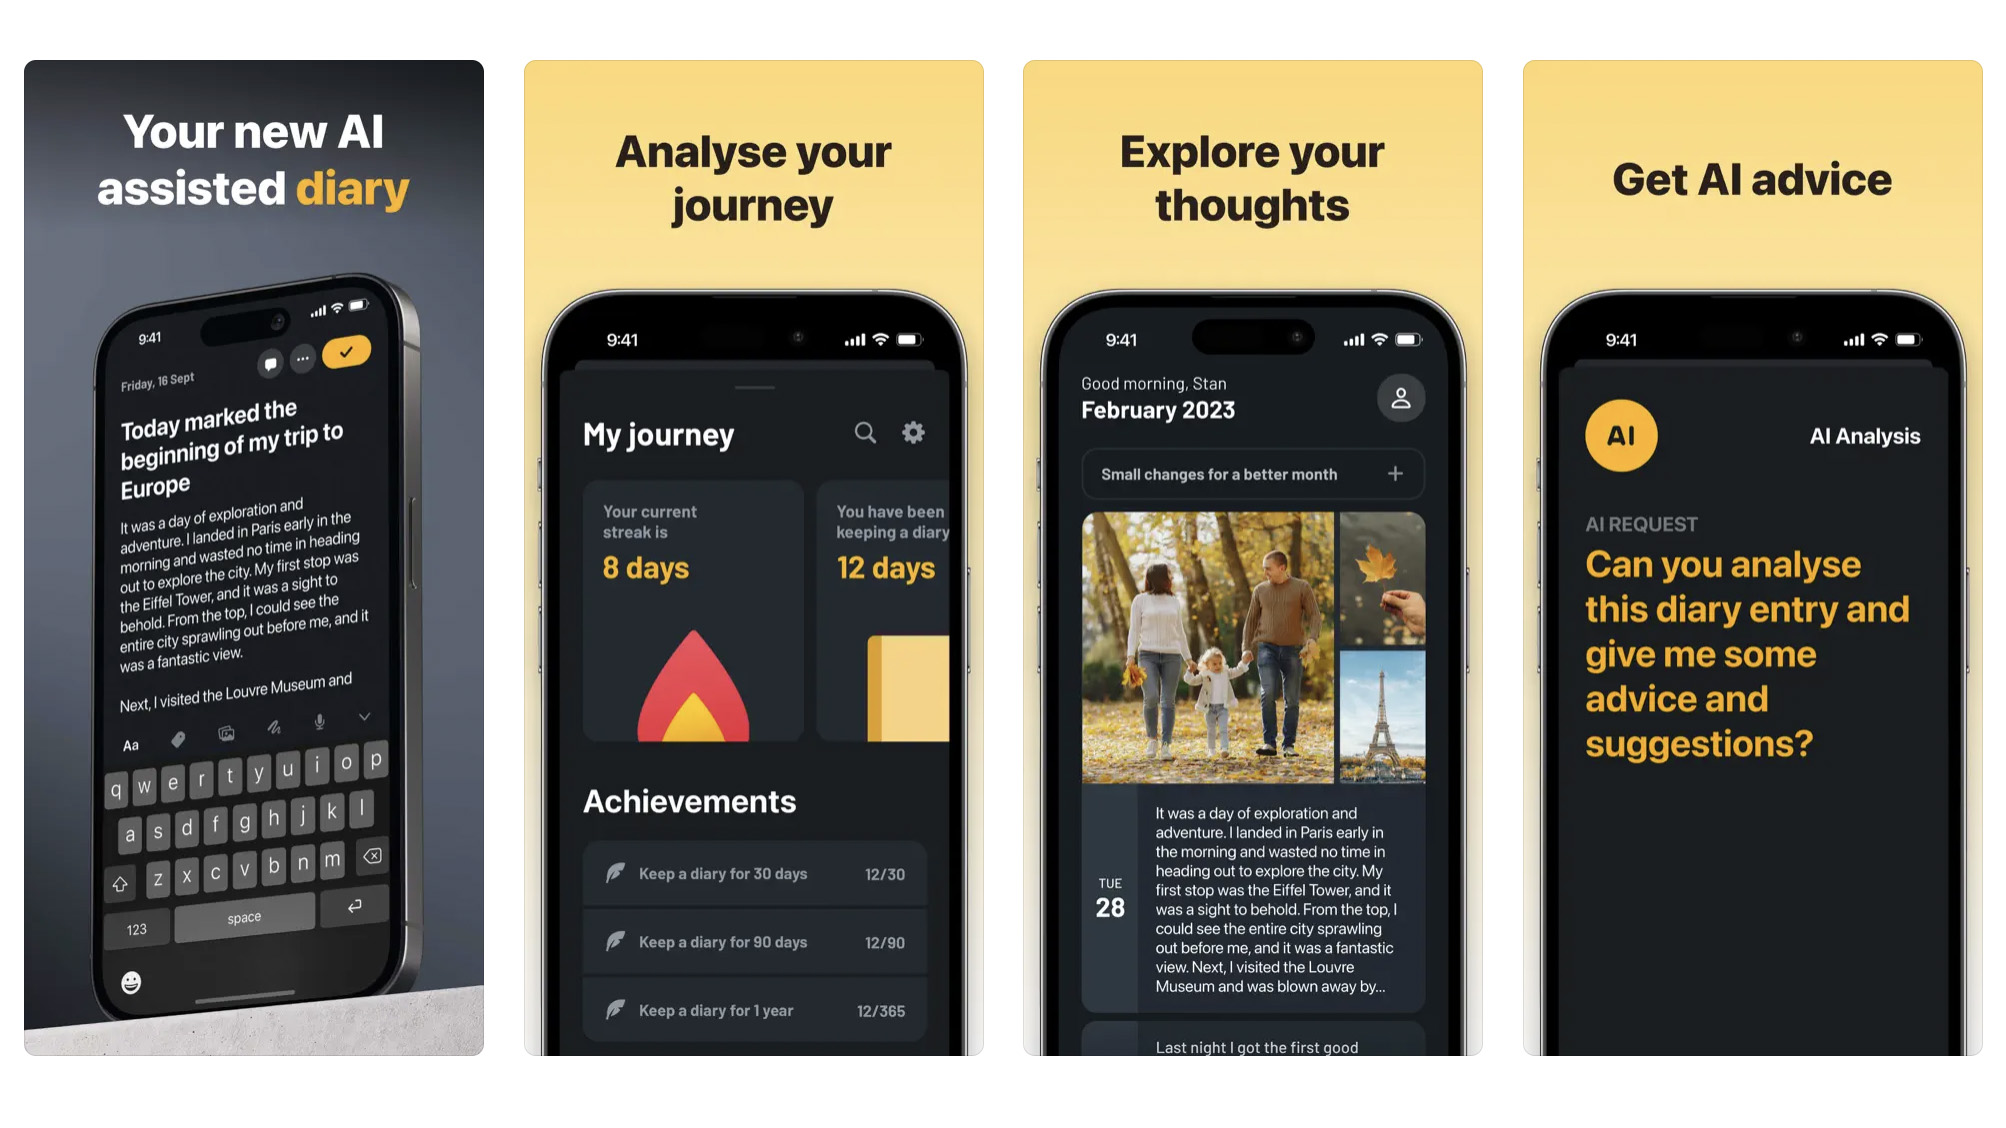
The journal is a tool, not a solution. It won't fix bad prompt design or unrealistic expectations about model capabilities. If your base prompts are fundamentally flawed, logging 10,000 variations won't help—you'll just have a detailed record of systematic failure. Use the journal to validate hypotheses, not to generate them. I had a situation where my journal showed consistent failures with JSON extraction on multi-page documents. The pattern was clear: pages 3-5 consistently dropped fields. I tried increasing context window, adjusting temperature, adding explicit instructions. Nothing worked until I realized the issue was token positioning—page content arrived near the context limit boundary where attention mechanisms degrade. The workaround was splitting the document at page 2 and concatenating results. This cut processing time from 45 seconds to 12 seconds per document while eliminating the field loss entirely. The journal made the pattern visible. The fix required understanding the architecture.