What Actually Goes Into Breaking Down Betting Markets
I spent three years working with sportsbooks and data vendors, mostly cleaning raw feeds and building models that tried to predict outcomes better than the closing line. The work is less glamorous than people think. It is mostly dealing with incomplete JSON, timezone mismatches, and the occasional vendor who pushes stale odds without any update flag. You can find a few open source tools on GitHub that handle parsing, but most of what matters isn't the script you download. It is the pipeline around it. I typically start by pulling a CSV or JSON feed from a provider like The Odds API, SportRadar, or OddsPortal, then run it through a quick normalization step that aligns timestamps to UTC and maps bookmaker names to a consistent registry. The actual analysis comes after you have clean data. You are looking for lines that moved, vig differences across books, and markets where the implied probability doesn't match your own model output. I built a simple Excel workbook once that took opening and closing lines for NFL spreads and calculated the average line movement per week. It took about twenty minutes to set up and saved me hours of manual cross-referencing against public odds archives.
Practical Steps That Actually Work
Most beginners jump straight into machine learning. That is a mistake unless your dataset is already clean and your target variable is well-defined. I usually start with descriptive statistics. Calculate the mean, median, and standard deviation of line movements for a specific market over a season. Then look at the distribution of closing lines versus opening lines. If your closing line beat the opening line more than 52.4 percent of the time after accounting for vig, you have a viable edge. If not, your model isn't adding value yet. Here is a specific problem I ran into that almost cost me a month of work. A vendor was returning odds with timestamps in local time zones instead of UTC. The fix was straightforward, but I didn't catch it until I cross-referenced the same game across three different books and noticed the line movement timeline was completely scrambled. The workaround was to add a timezone conversion layer that maps the returned timestamp to UTC using the venue location stored in the fixture metadata. That took about ten minutes to implement once I understood the pattern.
Common Pitfalls and How to Avoid Them
Survivorship bias is the biggest trap. Most public datasets only include games where at least one sharp book made a line. If you are filtering for high-volume markets, you are implicitly selecting for games where something happened. The empty games, the ones that stayed flat, are invisible. This skews your model toward overestimating line movement frequency. Vig is not constant. Many beginners assume a standard -110 juice across all markets. It isn't. Prop bets, player props, and alternate lines often carry 15 to 25 percent vig. If you are comparing implied probabilities across different market types without adjusting for vig, your edge calculations will be wrong. The fix is to convert odds to true probabilities by removing the bookmaker margin before comparing against your model. Timestamp alignment errors. I see this constantly. A provider returns an odds update at 2024-03-15T14:30:00Z, but your local system reads it as 2024-03-15T09:30:00 EST and thinks the line moved before the game even started. Always store timestamps in UTC and convert for display only.
Get the Full Details
Tools I Actually Use
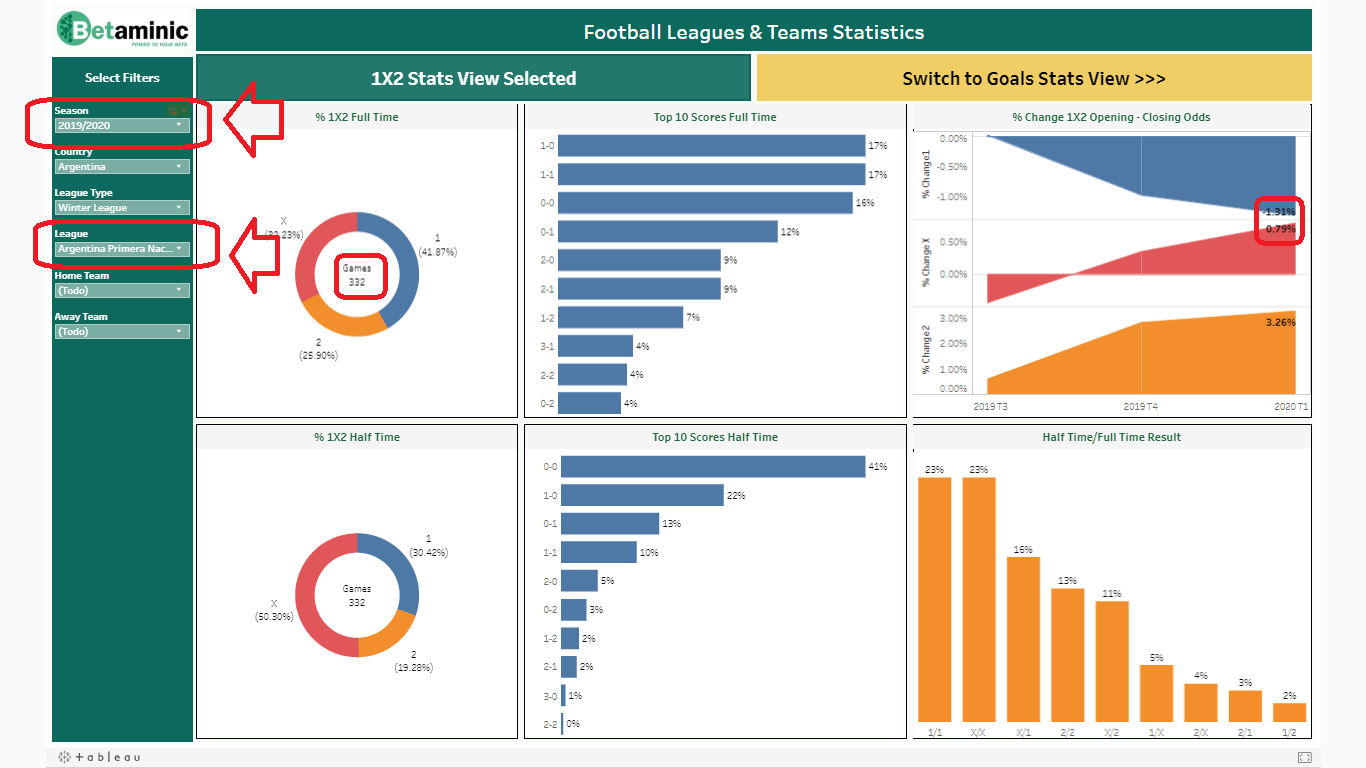
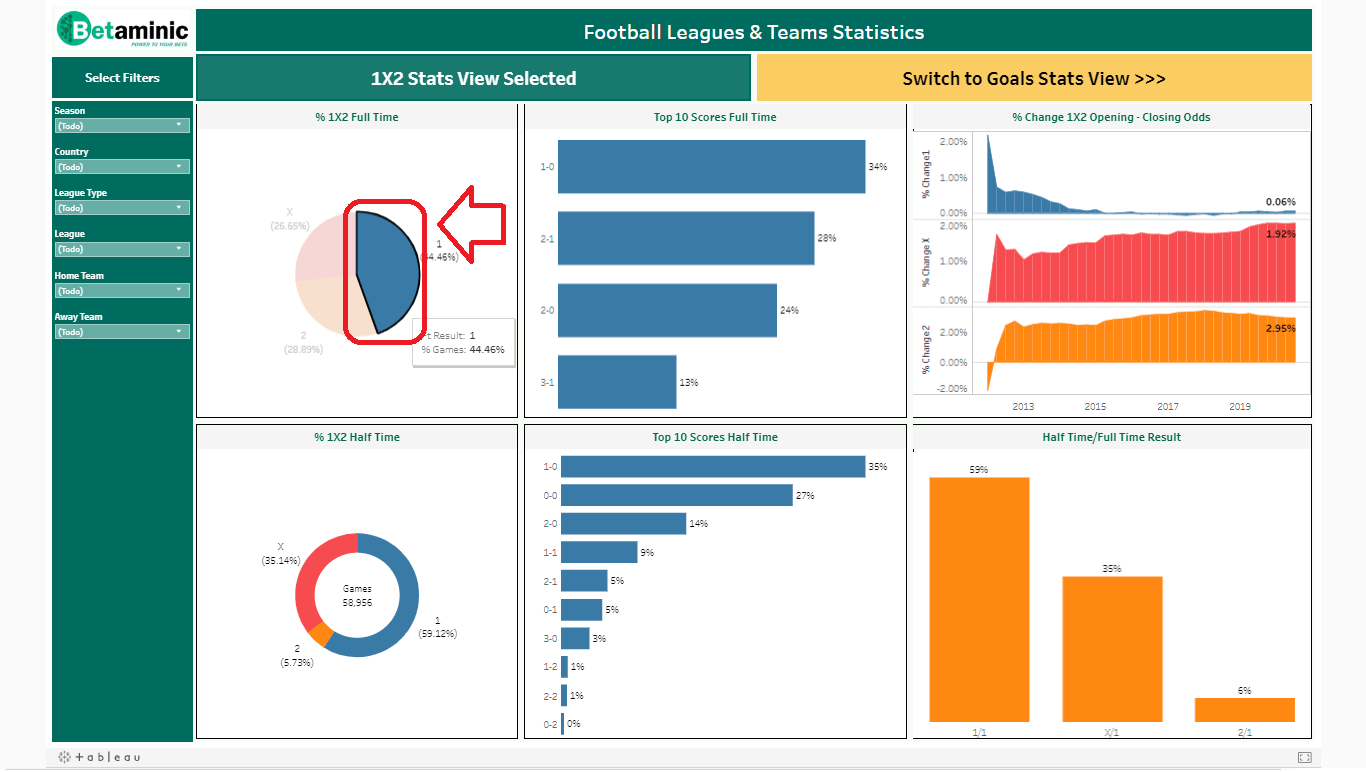
For data ingestion, I rely on Python with pandas for the heavy lifting. The `betfairlightweight` library is useful if you are working with exchange data. For visualization, I use Tableau Public because it handles time-series line movement plots better than Matplotlib without requiring custom code. For storage, I keep everything in SQLite. It is fast enough for single-user analysis and doesn't require a server. If you want to download something to get started, this open source toolkit on GitHub has a basic pipeline for parsing odds feeds, normalizing timestamps, and calculating line movement statistics. It isn't production-ready, but it is a solid starting point. The README includes examples for NFL and NBA markets.
When Betting Data Analysis Doesn't Work
It fails completely in markets with low liquidity. If a bookmaker is the only one offering a prop bet, there is no independent price discovery. The line moves based on action, not information. In those cases, no amount of analysis will give you an edge because there is no market signal to extract. It also fails when you are comparing against recreational books. Sharp books like Pinnacle or Betfair Exchange move lines based on money flow from professional bettors. Recreational books adjust their lines based on public betting patterns, which are often lagging indicators. Mixing the two in the same model creates noise, not signal. The honest truth is that most people who try this never make money. The market is efficient enough that edges are small, short-lived, and require significant infrastructure to capture. If you are doing this for fun, treat it as a learning exercise. If you are doing it professionally, expect to spend at least six months cleaning data before you see a single reliable signal.