Operant Conditioning Actually Works, But Most People Mess Up the Variable Schedules
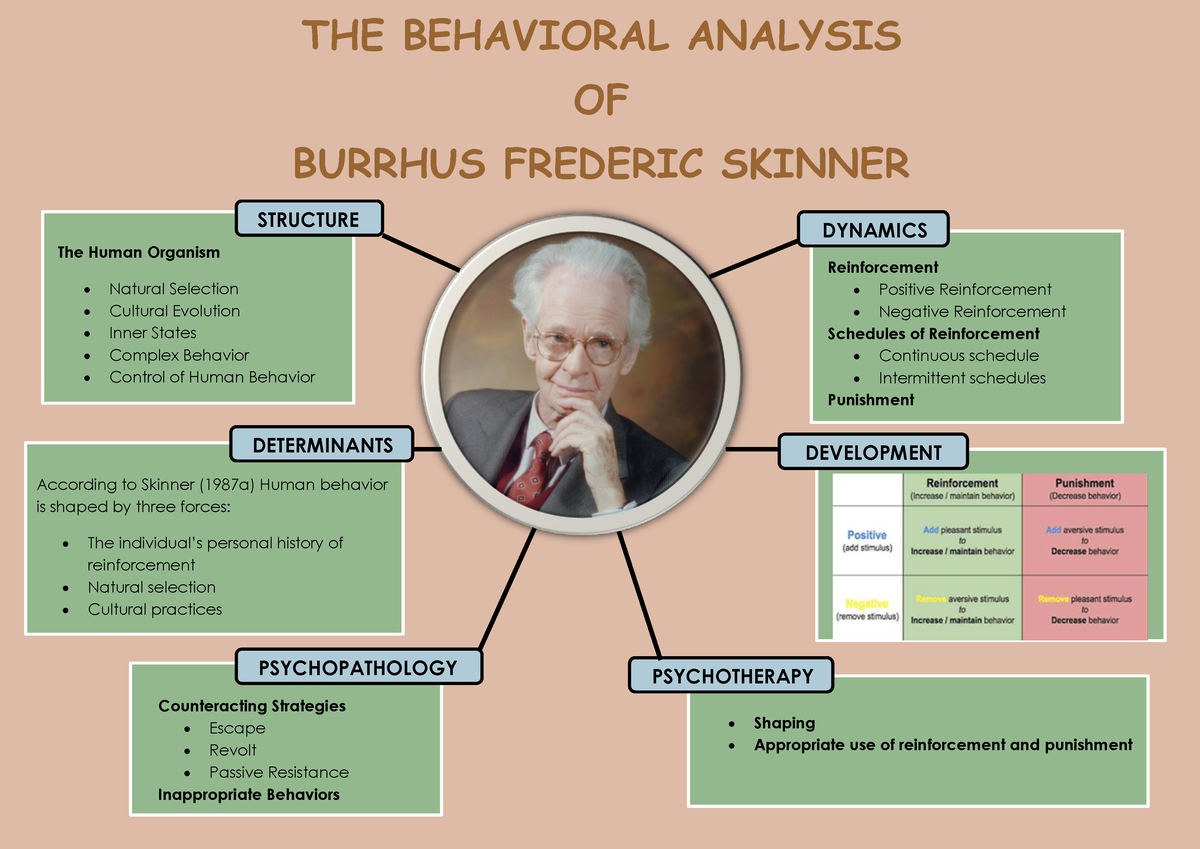
I spent three years running contingencies on a custom-built rig before I really understood what Skinner was actually describing. The textbook version makes it sound simple: behavior followed by reinforcement gets stronger, behavior followed by punishment gets weaker. That's not wrong. It's just the tip of a very large iceberg. At its core, Skinner's approach is about identifying the environmental variables that control observable behavior. Not thoughts. Not feelings. The actual stimuli that precede a response and the consequences that follow it. He called this the three-term contingency: antecedent, behavior, consequence. A stimulus sets the occasion for a response, and the response produces a consequence that either increases or decreases the likelihood of that response recurring. Most people conflate this with Pavlovian conditioning. They're wrong. Pavlov was studying reflexive, involuntary responses. Skinner was studying operant behavior — actions the organism emits voluntarily because of what those actions have produced in the past. A rat pressing a lever isn't being conditioned to salivate. It's learning that pressing the lever produces food. That distinction matters more than you'd think.
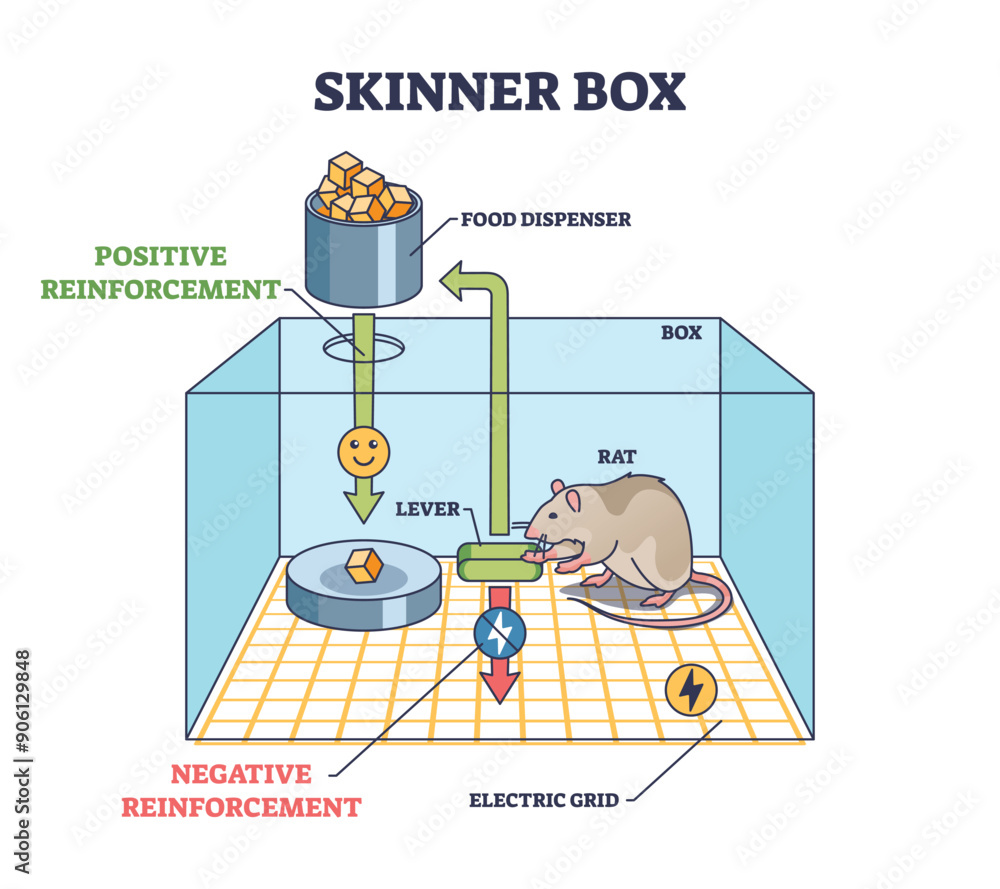
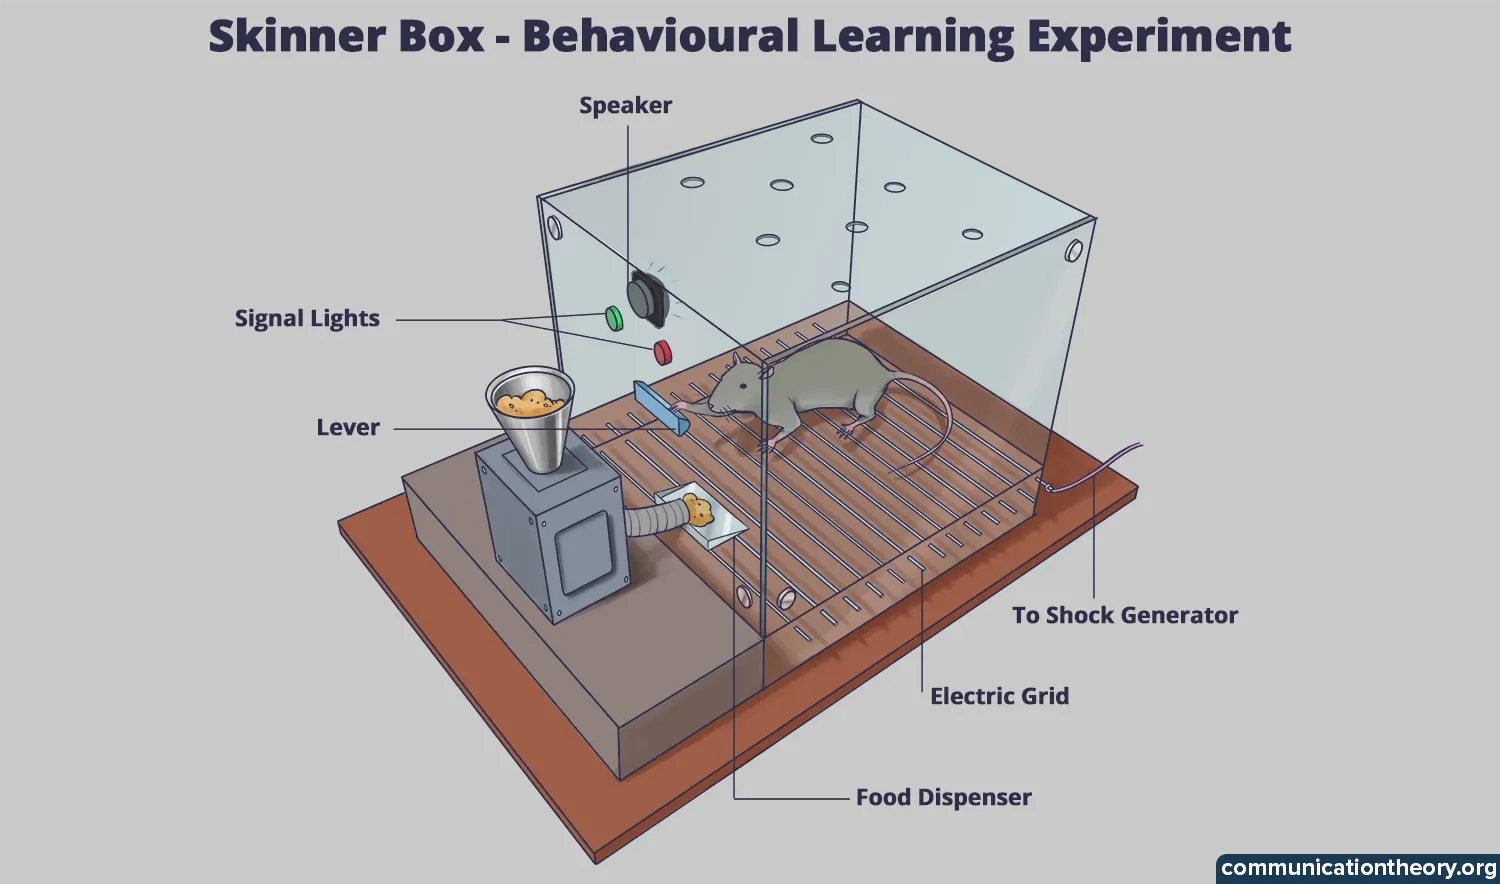
The Skinner box itself was brutally simple. A lever, a food dispenser, a light, a speaker, a grid floor for shock delivery. That's it. Nothing fancy. The elegance wasn't in the apparatus. It was in the logic of how you extracted data from it.
The Schedule of Reinforcement Is Where Everything Falls Apart
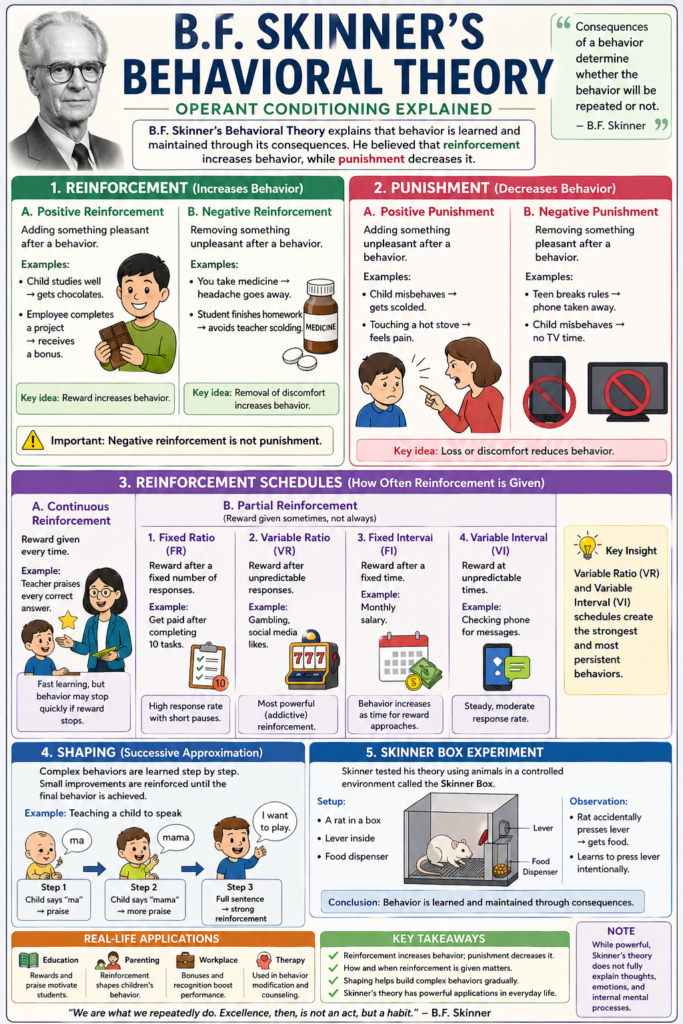
This is the part that beginners consistently overlook. The type of reinforcement — positive or negative — gets all the attention. But the schedule is what actually determines whether a behavior persists, how resistant it is to extinction, and how predictable the response rate will be. Fixed ratio schedules produce high response rates with a brief pause after each reinforcement. A rat on FR-5 will press rapidly, then take a micro-pause after the food pellet drops, then start again. Variable ratio schedules — the lottery effect — produce the highest and most steady response rates with virtually no post-reinforcement pause. This is why slot machines work. This is why social media likes work. Variable ratio isn't a bug. It's the feature. Fixed interval creates a scalloped response pattern. Minimal responding right after reinforcement, then accelerating as the interval elapses. A pigeon pecking at a key that delivers food every 60 seconds will barely peck for the first 40 seconds, then ramp up hard as the clock ticks down. Variable interval produces moderate, steady responding. You check your email at roughly even intervals not because there's a fixed schedule, but because the reinforcement (new messages) arrives unpredictably over time.
Get the Full Details
Punishment schedules are a trap. Most people reach for punishment when reinforcement isn't working fast enough. It doesn't suppress behavior reliably. It creates avoidance, aggression, and emotional side effects that often outweigh whatever temporary suppression you get. And the behavior comes back as soon as the threat of punishment is removed. Reinforcement always wins in the long run.
A Real Problem I Encountered
I was running an extinction protocol on a subject that had been on a variable ratio schedule for eight months. The baseline response rate was incredibly high and stable. Once I cut off reinforcement, the behavior didn't just decline gradually. It exploded first. This is the extinction burst — a well-documented phenomenon where the organism ramps up responding aggressively right before it starts to fade. I'd read about it. Seeing it happen in real time is different. The burst lasted approximately 47 minutes. Response rate spiked to 340% above baseline before starting a slow decline. If you're not expecting it, you'll make a mistake. You'll interpret the spike as the protocol failing and either reinforce accidentally or terminate the session early. Both outcomes sabotage the data. I learned to set a minimum observation window before drawing any conclusions about extinction. Forty-five minutes minimum. Anything less and you're measuring the burst, not the decline. Another edge case: partial reinforcement extinction effect. Behaviors maintained on variable schedules are dramatically more resistant to extinction than those on continuous schedules. A rat on CRF might extinguish in 20 trials. The same rat on VR-10 could keep responding for 200 plus trials. This isn't a minor difference. It's an order of magnitude. When you're designing a study, the schedule you choose before training begins will determine whether your experiment takes two days or two weeks.
Counter-Intuitive Things Nobody Tells You
Shaping — reinforcing successive approximations toward a target behavior — sounds straightforward until you try it. The step size is everything. Too large a jump between criteria and the subject stops responding entirely. Too small and you waste sessions stacking insignificant increments. I once shaped a complex multi-component sequence and spent three days reinforcing what amounted to the subject accidentally doing the first step correctly twice. The fix was cutting the criterion step size in half and adding a discriminative stimulus that signaled exactly when the next approximation was required. Second counter-intuitive point: punishment doesn't create new behavior. It suppresses existing behavior. If you need an organism to do something specific, punishing the wrong thing leaves a vacuum. The subject will just emit whatever behavior happens to be available in that moment. That's why reinforcement of an alternative behavior — DRA, differential reinforcement of alternative behavior — is the standard approach. You don't just suppress the problem. You build something else to take its place. A third one that trips people up: the difference between negative reinforcement and punishment. Negative reinforcement strengthens behavior by removing an aversive stimulus. Punishment weakens behavior by presenting an aversive stimulus or removing a positive one. They are not opposites. They are completely different operations. A student studies harder to avoid failing (negative reinforcement). A student studies harder to avoid their parent's anger (also negative reinforcement, but now the aversive stimulus is social rather than academic). The mechanism is identical. The context changes everything.

When This Approach Fails Completely
Radical behaviorism deliberately brackets internal mental events. It treats thoughts and feelings as private behaviors subject to the same contingencies as public behavior. That's philosophically coherent. Practically, it's a severe limitation when you're working with complex verbal organisms — humans — who have elaborate rule-governed repertoires. A rat will navigate a maze based on stimulus-response associations. A human will navigate the same maze by reading a sign, remembering a conversation, or imagining a future outcome. The behavior looks identical on the outside. The controlling variables are fundamentally different. Skinner himself acknowledged this with his distinction between selection by consequences (evolutionary, trial-and-error) and selection by culture (verbal mediation, instruction). But most applied work in behavior analysis glosses over that gap. If you're working with language-dependent humans, pure S-R models will underpredict and overgeneralize. You need to incorporate verbal behavior as its own category, not just treated as "behavior that happens to involve words." Another hard limitation: biological constraints. You cannot shape a behavior that contradicts an organism's species-specific predispositions indefinitely. You can condition a pigeon to peck a key for food. You cannot easily condition that same pigeon to peck only when a specific color is present if that color has no natural relevance to its foraging behavior. Preparedness matters. Some associations form in one trial. Others require hundreds and still don't stick. The animal learns what its biology says it should learn, not what the experimenter wants it to learn.
Practical Takeaways
If you're setting up your own contingency experiment, start with continuous reinforcement to establish the baseline behavior. Don't jump to variable schedules until the response is stable — usually 10 to 15 trials at CRF with a clear asymptote. Then switch schedules based on what you're trying to measure. If you're studying resistance to extinction, go variable immediately. If you're studying acquisition speed, stay on fixed ratios longer. Record inter-response times, not just response counts. Two subjects can emit the same number of responses in a session and have completely different behavioral topographies. One might be bursting through responses with no pauses. The other might be spacing them evenly. The IRD distribution tells you which. It also catches subtle effects that total counts obscure. Watch for accidental reinforcement. It happens constantly. A subject emits a novel behavior, you blink, it happens again, you reinforce it, and now you've shaped something you never intended. Keep a running log of every reinforcer delivery with a timestamp and a description of what the subject was doing. Three weeks into a protocol, you'll look back and realize you reinforced a completely unrelated behavior on day four and haven't noticed because the subject kept doing it alongside the target behavior.
Extension bursts during extinction are normal. Partial reinforcement makes extinction take exponentially longer. Punishment creates more problems than it solves. Biological preparedness constrains what you can shape. Internal mental events matter more than radical behaviorism wants to admit. These aren't caveats. They're the actual operating parameters of the method.