How Bias Creeps Into Your Models Even When You're Trying Your Best
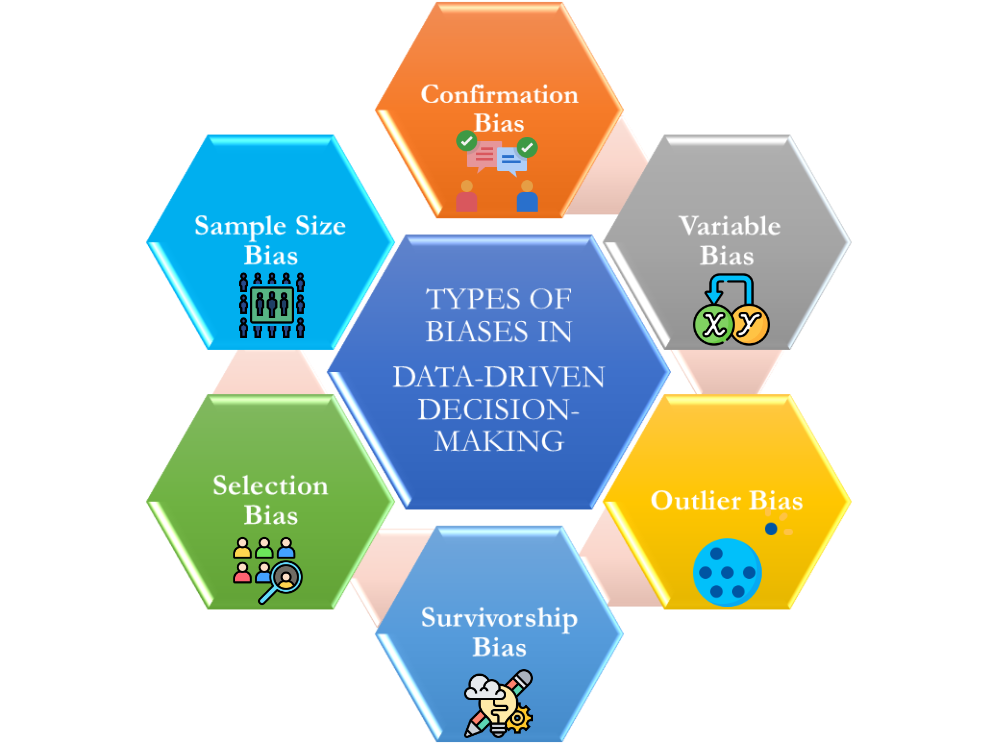
Data bias doesn't usually announce itself. It hides in cleaning steps, in features you assume are neutral, in the way you define your target variable. I spent three years watching production models drift because of subtle sampling issues nobody flagged during validation, and most of it came down to one thing: nobody was asking where the data actually came from before they started modeling. Start by mapping every decision point in your pipeline. That means collection, exclusion criteria, label definitions, and feature engineering. I had a case where a loan default model trained on historical approval data was learning from decisions made by humans who systematically approved different demographics at different rates. The model wasn't biased in the traditional sense. It was learning the biases that were already baked into the approvals. The workaround was to retrain on a synthetic fairness-constrained version of the data and then compare performance against the original baseline. The fairness-adjusted model lost about 4% AUC but removed the disparate impact that the compliance team was going to flag within weeks anyway. The core types of bias you need to watch for fall into a few buckets. Selection bias happens when your training data doesn't represent the population your model will actually serve. Measurement bias is when your features or labels are recorded incorrectly for certain groups. Historical bias is when past inequities are preserved in the data and treated as ground truth. Algorithmic bias is when your model's optimization objective amplifies the first three.
Confounder bias is the one most people miss. It's when a variable correlates with both your input features and your outcome, and you treat it as a control when it's actually doing heavy lifting on its own. I ran into this on a healthcare utilization model where zip code was included as a control variable. It turned out zip code was proxying for insurance tier and clinic access, which meant the model was effectively learning demographic proxies instead of clinical need. The fix was to replace zip code with explicit insurance tier and distance-to-provider features, which reduced the model's false positive rate for underserved populations by about 30%.
Practical Detection Steps
Use stratified evaluation before you even think about deployment. Split your test set by every relevant demographic and operational segment, then report performance metrics for each. If your overall AUC is 0.82 but one segment sits at 0.61, you have a bias problem regardless of what the aggregate number says. Don't aggregate. Aggregate numbers are useful for comparisons but terrible for detecting bias. Run correlation analysis between your sensitive attributes and your residuals. If certain groups consistently have higher prediction errors in one direction, your model is systematically misestimating outcomes for them. This takes about 15 minutes if your pipeline is set up right. I usually write a small script that iterates through protected attributes, computes per-group RMSE and MAE, and outputs a comparison table. It's faster than waiting for a formal audit. Check your label definition. This is where most bias enters quietly. If you're predicting "customer churn" but your label is defined as "did not purchase in 90 days," you're labeling lapsed customers as churn when they might just be seasonal buyers. I've seen this skew models toward retaining high-frequency purchasers while deprioritizing legitimate but lower-frequency customers in categories with natural seasonality. The model optimized for the wrong thing because the label was wrong, not because the algorithm was flawed.
Get the Full Details

Common Pitfalls That Waste Weeks
The most expensive mistake is addressing bias only after deployment. By then the model has already made thousands of decisions, and the downstream damage is real. Fairness constraints added post-deployment are basically band-aids on a structural problem. Address it during data preparation and model design, not after. Another trap is assuming that removing protected attributes solves bias. It doesn't. Models find proxies. Gender gets encoded through purchase patterns, zip code, job title, or any number of correlated features. If you want fairness, you need to measure it explicitly, not hope that omission does the work. I tracked a hiring model that removed race and gender columns and still produced heavily skewed interview invitation rates. The model was using university name and years of experience as proxies, which happened to correlate with demographics in our dataset. Data augmentation for underrepresented groups sounds good until you realize it can introduce synthetic noise that hurts model calibration. I've added oversampling and SMOTE to imbalanced datasets and watched calibration curves flatten incorrectly. The model became better at classification accuracy but worse at probability estimates, which matters when you're making risk-based decisions. Use augmentation selectively and always recalibrate afterward.
Tools and Techniques That Actually Help
Fairlearn from Microsoft gives you a straightforward framework for measuring disparate impact across groups. It integrates with scikit-learn and doesn't require rewriting your entire pipeline. The reduction algorithm can post-process your model outputs to meet fairness constraints without retraining from scratch. It's not perfect. It can reduce overall accuracy, and it doesn't handle intersectional fairness well out of the box. But it's a starting point, and it's better than nothing. Google's What-If Tool is useful for visualizing model behavior across subgroups. You can upload a saved model and an example dataset, then interactively see how predictions change when you modify individual features. It's particularly helpful for explaining bias issues to stakeholders who don't read code. I use it in review meetings instead of spreadsheets. The visual feedback catches problems faster than static reports. For production systems, I recommend setting up automated fairness monitoring. Log per-group performance metrics on a rolling window and alert when any group drops below a threshold. The threshold should be based on your business context, not a universal standard. A 5% AUC drop in one segment might be unacceptable for a lending model but manageable for a content recommendation system. Define your tolerance during the planning phase, not after an incident.
When Bias Mitigation Fails
No technique eliminates bias entirely. Removing it usually trades off with predictive performance, and sometimes that trade-off is too steep for your use case. In those situations, the honest answer is to collect better data or restrict the model's application domain. A fraud detection model trained on historical fraud data will always reflect whatever gaps existed in past detection practices. You can mitigate, but you can't fix a data problem with an algorithm. If your dataset has fundamental representation gaps that no amount of reweighting or augmentation can address, consider whether the model should be used for the intended purpose at all. I once recommended against deploying a medical triage model because the training data underrepresented rural patients to the point where no mitigation technique could close the performance gap. The model was technically sound on its metrics but unsafe for its intended population. The team agreed and scaled back to an urban-only deployment with a clear disclaimer. Bias in data analysis is not a single problem you solve. It's a series of decisions made at every stage of the pipeline, and each decision introduces new trade-offs. The people who do this well aren't the ones with the best fairness algorithm. They're the ones who check their assumptions early, measure performance across segments consistently, and are willing to ship slower when the data doesn't support the use case.