Setting Up a Practical Big Data Stack
I spent roughly three years working with data pipelines for mid-market companies before I stopped pretending that every tool listed on Wikipedia would fit their actual workflows. Most of the time it doesn't. The tools are powerful but they have opinions, and those opinions cost money in engineering time. The most common mistake I see is organizations buying into a full Apache Hadoop ecosystem when a simple PostgreSQL database with a proper ETL script would do the same job at a fraction of the infrastructure cost. Hadoop was built for internet-scale problems. Most businesses are solving warehouse-scale problems.
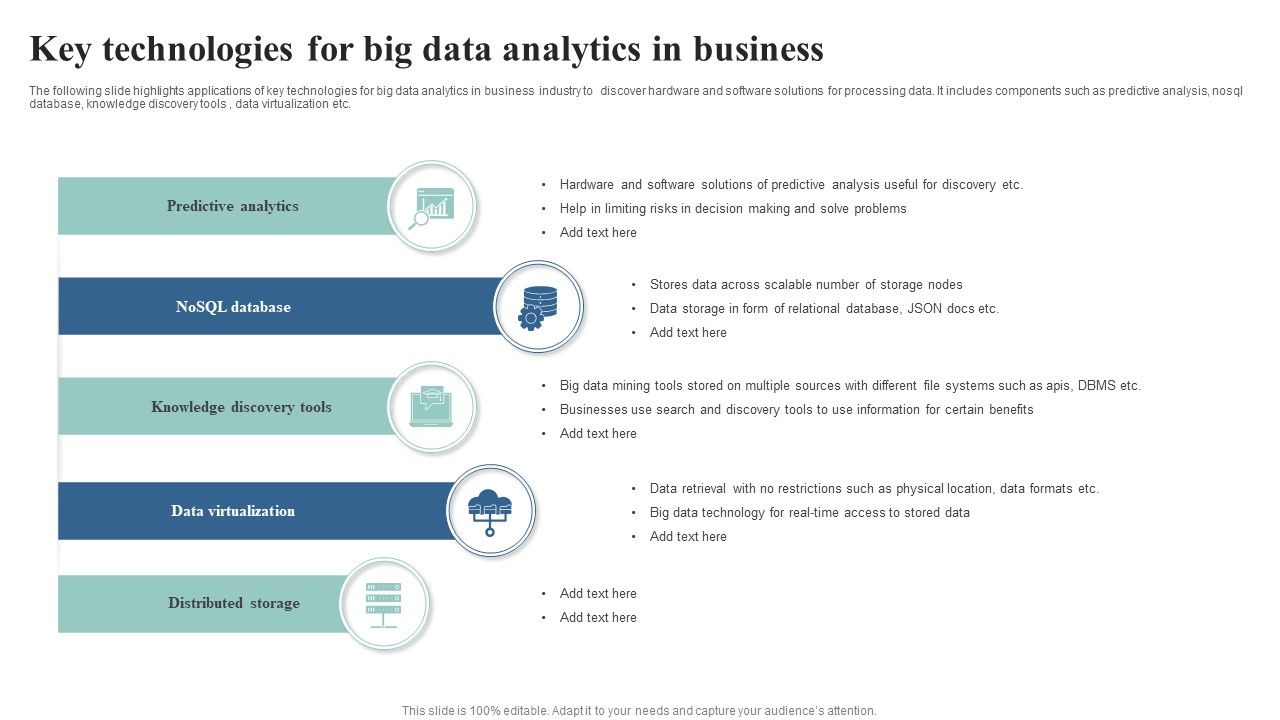
Big Data Technologies For Business
This is the practical breakdown of what actually moves data in production environments and what tends to fall apart in practice. Apache Spark is the engine most people reach for. It handles in-memory processing, which means jobs that used to take hours on map-reduce run in minutes. I had a client who migrated a nightly batch job from Hadoop streaming to Spark and cut processing time from 47 minutes down to six. The tradeoff is memory consumption. Spark runs hot. You need adequate heap allocation or the garbage collector will chew through your cluster. Apache Kafka handles streaming data ingestion. It's not a database, it's a distributed commit log. People misunderstand this constantly. Kafka keeps data for a configurable retention period, and consumers read from it at their own pace. If your consumer falls behind, Kafka doesn't pause. It just overwrites old messages once the retention window expires. I learned this the hard way with a sensor monitoring pipeline where the consumer service crashed for eight hours and we lost fourteen days of telemetry data because the retention was set to seven days by default.
The workaround was straightforward but expensive. We reconfigured retention to 30 days, added a second Kafka topic as a dead letter queue, and built a replay script that fed missed partitions back into the consumer. That cost about two weeks of engineering time and taught me to never trust default configurations in production. Apache Flink is worth mentioning alongside Spark because it handles stateful stream processing better than Spark Structured Streaming does. If you're doing real-time fraud detection or anomaly scoring where you need to track state across events, Flink's checkpointing mechanism is more reliable. Spark can do it. Flink was built for it from the ground up. Airflow orchestrates everything. Without it, your pipeline is a collection of scripts held together by cron and prayer. Airflow gives you directed acyclic graphs, retry logic, alerting, and a web interface that lets you see which task failed and why at 3 AM instead of discovering it through a PagerDuty notification. The learning curve is moderate. DAGs are written in Python, which is good if you know Python and less good if you don't.
Get the Full Details

For storage, Apache Parquet is the file format to use. It's columnar, compressed, and split-aware. Reading a Parquet file lets you pull only the columns you need instead of scanning entire rows. I compared CSV and Parquet on a 40-gigabyte dataset with roughly sixty columns and twelve of them being selected for analysis. The Parquet query took four seconds. The CSV query took forty-one. That difference compounds when you're running the same query every hour. Presto/Trino handles interactive queries across distributed datasets. It's not a database. It's a query engine that talks to existing data sources. If you've got data spread across S3, a Postgres instance, and a Kafka topic, Trino can query all three in a single SQL statement without copying anything. This sounds magical until you try it on unpartitioned data. A join across two unpartitioned datasets in Trino will scan everything and run for hours. Partition your data first. Always partition your data first. The cloud alternatives exist and they're not free. Managed services like AWS Glue, EMR, and Redshift Spectrum remove operational overhead but introduce vendor lock-in and unpredictable pricing. I worked with a company that switched from their own EC2-based Spark cluster to EMR and saw their monthly data costs jump from roughly eight thousand dollars to twenty-two thousand. The team was happier because they weren't managing clusters anymore. The CFO was not.
dbt has become essential for the transformation layer. It turns SQL into version-controlled, tested, documented analytics code. If your team writes SQL in spreadsheets and emails them to each other, you're behind. dbt compiles your models, runs tests, and builds a lineage graph showing where each column comes from. The downside is that it adds a compilation step to your pipeline and requires discipline around naming conventions and modular design. Sloppy dbt projects are worse than sloppy SQL projects because the sprawl is hidden behind a nice interface. When building a pipeline, start with the query you need to answer, not the tools you want to use. I've seen teams provision entire Kubernetes clusters and deploy ZooKeeper before they knew whether they needed batch or streaming. Pick the smallest tool that handles your current volume, add complexity only when you hit a ceiling, and document why you made each decision. Future you will be grateful, or at least less angry. Data quality should be treated as a first-class concern, not an afterthought. Great Expectations and Soda Core are two frameworks I use regularly. They run assertions against your data as part of the pipeline. If a schema drifts or a column drops below a threshold, the pipeline fails and alerts fire. This prevents bad data from propagating downstream into dashboards and reports that executives make decisions on. I've seen revenue figures reported incorrectly for a quarter because someone changed a column type in the source system and nobody noticed until the CFO asked why the numbers didn't match the ledger.
Monitoring and observability matter more than the tools themselves. Metrics, logs, and traces should be collected from day one. Prometheus with Grafana is a standard stack for this. Track job duration, failure rates, data volume per run, and lag between source and destination. When something breaks at 2 AM, you should know within thirty seconds what broke and where, not spend an hour digging through logs. There is no perfect architecture. Every stack has tradeoffs between consistency, availability, and partition tolerance. Pick your constraints, build accordingly, and accept that your data will never be completely clean or perfectly fresh. The goal is useful data delivered fast enough to act on it.


