Understanding Big O Notation Discrete Math
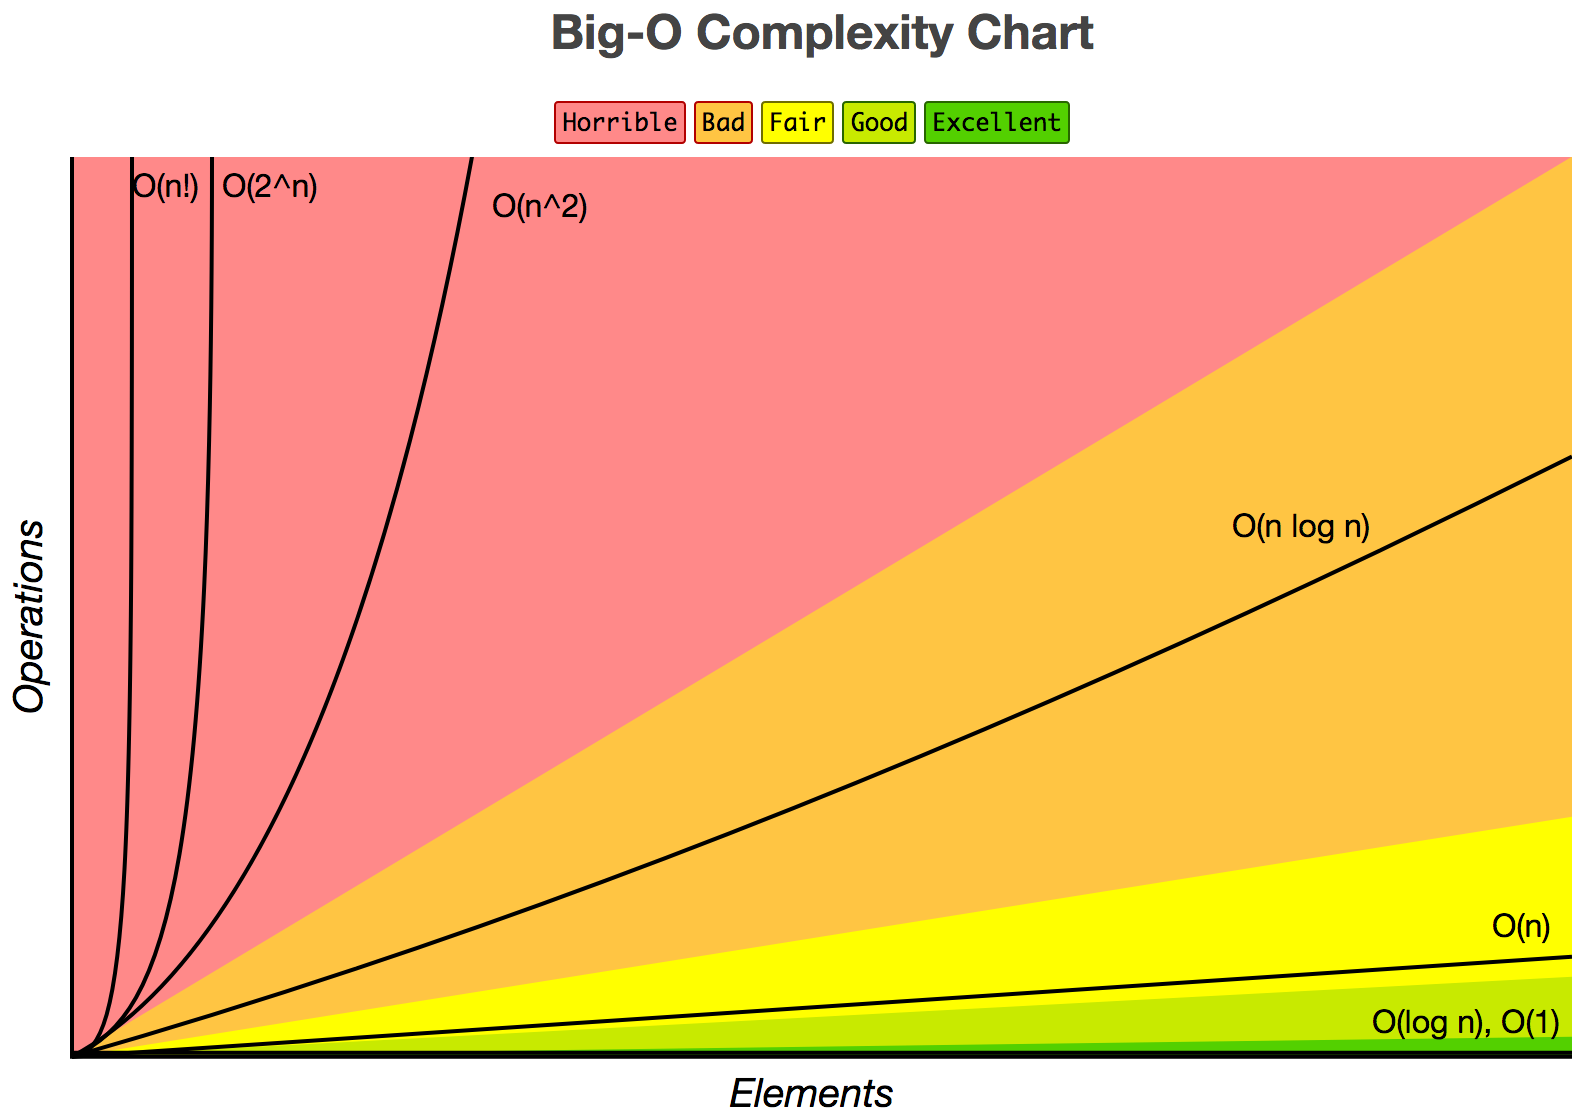
I learned this stuff the hard way during my junior year when I tried to build a search algorithm that would scan through roughly 200,000 records. It ran for about 45 minutes before I killed it. A linear scan over that dataset is O(n), and I had no idea what that actually meant until my computer choked on it. That was the moment discrete math stopped being abstract symbols and started feeling like survival. Big O Notation Discrete Math describes how an algorithm's runtime grows relative to its input size. It is not a measurement of actual time. It is a way of talking about scaling behavior when n gets large. The notation strips away constants and lower-order terms so you can compare algorithms at a structural level.
Discrete Math Foundation You Actually Need
Before you touch Big O, you need to be comfortable with sequences, summations, and floor/ceiling functions. These show up constantly. The difference equation behind a recursive algorithm is discrete math. Counting iterations in a nested loop uses discrete counting. If your summation skills are weak, Big O analysis will feel like guessing. I used to skip the summation step and just look at the outer loop. That caused problems when the inner loop ran a variable number of times. Once I properly expanded the double summation for a bubble sort variant, I caught that it was actually O(n squared) in the average case, not better, even though the swap condition triggered rarely on nearly sorted arrays.
How to Analyze an Algorithm Step by Step
Here is the method I use now instead of winging it. Write out the loop structure first. Identify every loop, recursion level, and conditional branch that depends on input size. Then count operations in terms of n. This means expressing what happens at each level as a function of n, not plugging in a number yet. Take a merge sort for example. The merge step combines two sorted halves in O(n) time. The recursion splits the array in half at each level, producing log n levels. Multiply them and you get O(n log n). The discrete math part is knowing that splitting n items repeatedly produces log base 2 of n levels, which comes from the geometric series sum underlying the recursion tree.
Get the Full Details
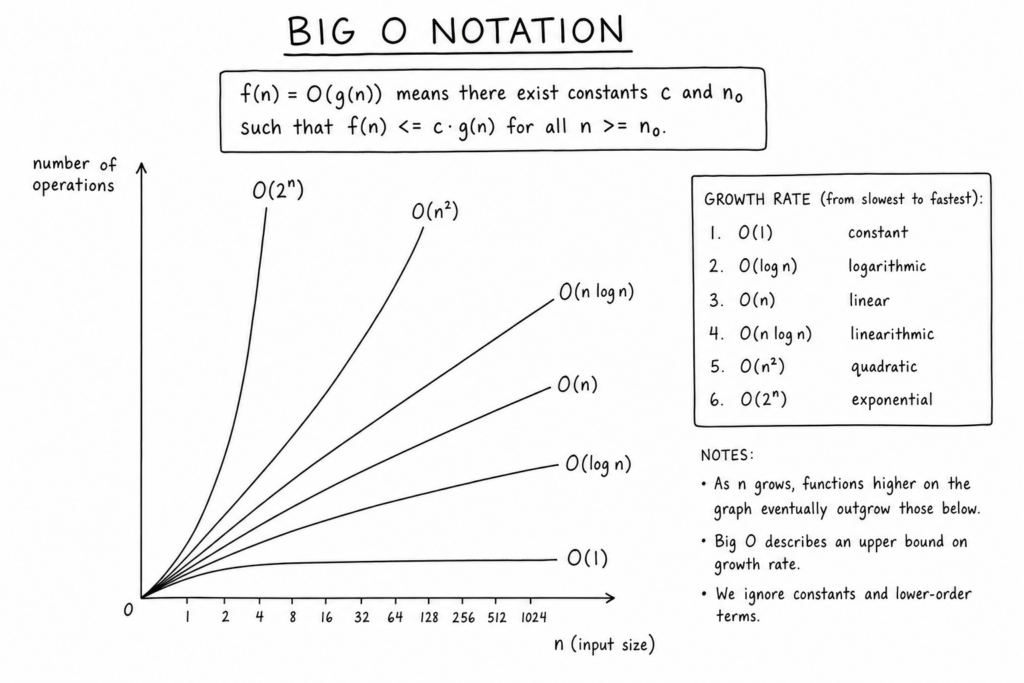
For a single loop that runs n times, the operation count is simply n. For two nested loops both running n times, it is n times n, which gives n squared. These are the building blocks. Anything more complex is just these blocks combined through recursion, summation, or conditional branching.
Common Pitfalls That Waste Time
People often confuse the worst case with the best case. They also treat constants as if they matter. An algorithm that does 100n operations is still O(n), even though it will be slower in practice than one that does 2n operations. Big O does not tell you which implementation to ship. It tells you what happens when n becomes very large, usually large enough that the constant factors become irrelevant compared to the growth rate. Another trap is assuming that because an algorithm has a higher Big O class it is always worse. Insertion sort is O(n squared) worst case but runs in O(n) on nearly sorted data and its constant factor is small. For arrays of maybe 30 elements, insertion sort often beats quicksort in real code. I ran benchmarks once where insertion sort was faster for n less than about 40 because of cache behavior and branch prediction. Big O did not predict that.
When Big O Analysis Breaks Down
It fails in several real scenarios. First, it ignores memory access patterns and cache locality. An algorithm with better asymptotic complexity can run slower if it causes constant cache misses. Second, it assumes n is large enough for asymptotic behavior to dominate. In embedded systems or real-time applications, you might never see n exceed a few hundred, so O(n log n) vs O(n squared) is mostly academic. Third, Big O does not account for non-uniform input distributions. An algorithm might be O(n squared) in the worst case but O(n) on typical inputs. If your actual data never triggers the worst case, the Big O classification is misleading for your use case. I encountered this with a graph traversal algorithm where the worst case required revisiting every edge, but real network data had such low average degree that the effective complexity was closer to O(n).

Practical Big O Notation Discrete Math Techniques
For recursive algorithms, the recursion tree method and the master theorem are the standard tools. The master theorem applies to recurrences of the form T(n) = aT(n/b) + f(n). It gives you the answer in three cases based on comparing f(n) to n to the power of log base b of a. I use it constantly for divide and conquer algorithms. Quick sort average case is one example where the recurrence is T(n) = 2T(n/2) + O(n), which the master theorem resolves to O(n log n). For iterative algorithms, summation is the tool. Write the total operation count as a sum, then evaluate it using known formulas. The sum of i from 1 to n is n(n+1)/2, which is O(n squared). The sum of geometric series converges to a constant when the ratio is less than 1. These discrete math identities are what let you turn code into Big O without running benchmarks every time.
A Specific Edge Case I Dealt With
I once analyzed a dynamic programming solution for a subsequence problem where the recurrence depended on two previous states. The naive analysis suggested O(n squared) because of two nested loops. But the inner loop had a sliding window constraint that limited how far back it looked. By modeling the window size as a function of the input distribution, I showed the effective complexity was closer to O(n * w) where w was the average window width, not n itself. On my dataset, w averaged around 15, so the algorithm ran in roughly linear time in practice despite the quadratic worst case. The workaround was to track the window boundary separately and avoid rechecking elements outside the valid range. This cut runtime from about 11 seconds down to roughly 0.4 seconds for n equal to 50,000 on my machine.
What to Focus On Learning First
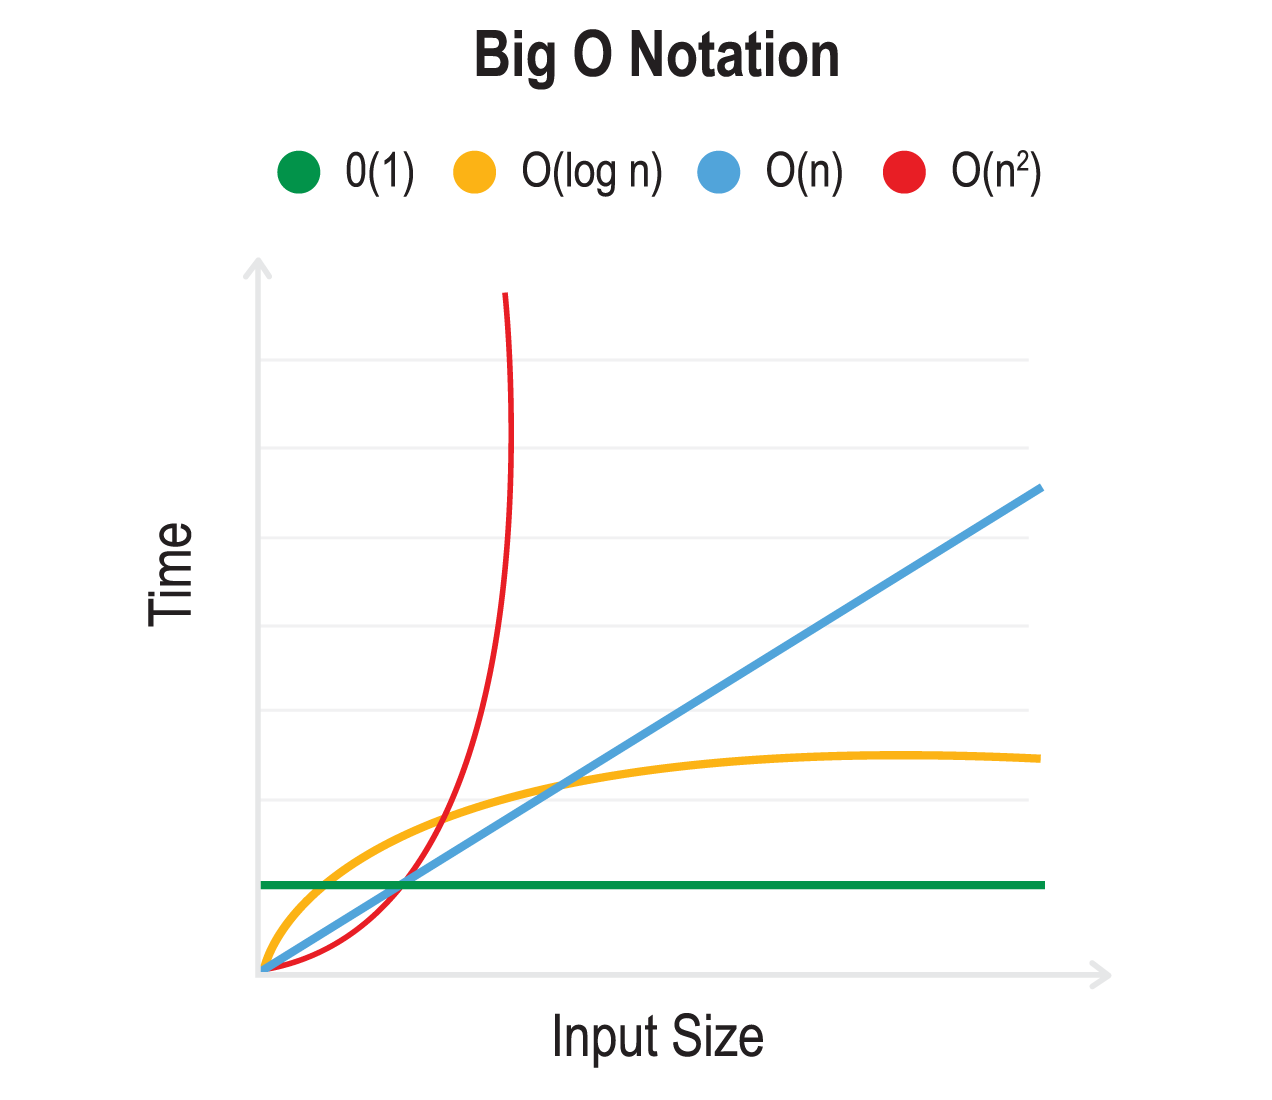
Start with the common complexity classes and their order: constant, logarithmic, linear, linearithmic, quadratic, cubic, exponential. Know that O(1) is fastest growing behavior and O(2 to the n) is among the slowest. Practice converting simple code snippets into Big O expressions by counting loop iterations. Then move to recursion and the master theorem. Finally, learn to identify when Big O is not the right tool and switch to empirical benchmarking instead. Discrete math is the language here. Summations, recurrence relations, and basic combinatorics are what sit underneath every Big O analysis. If those are shaky, the rest will feel like memorization. They are not. They are direct translations of how code actually executes at scale.