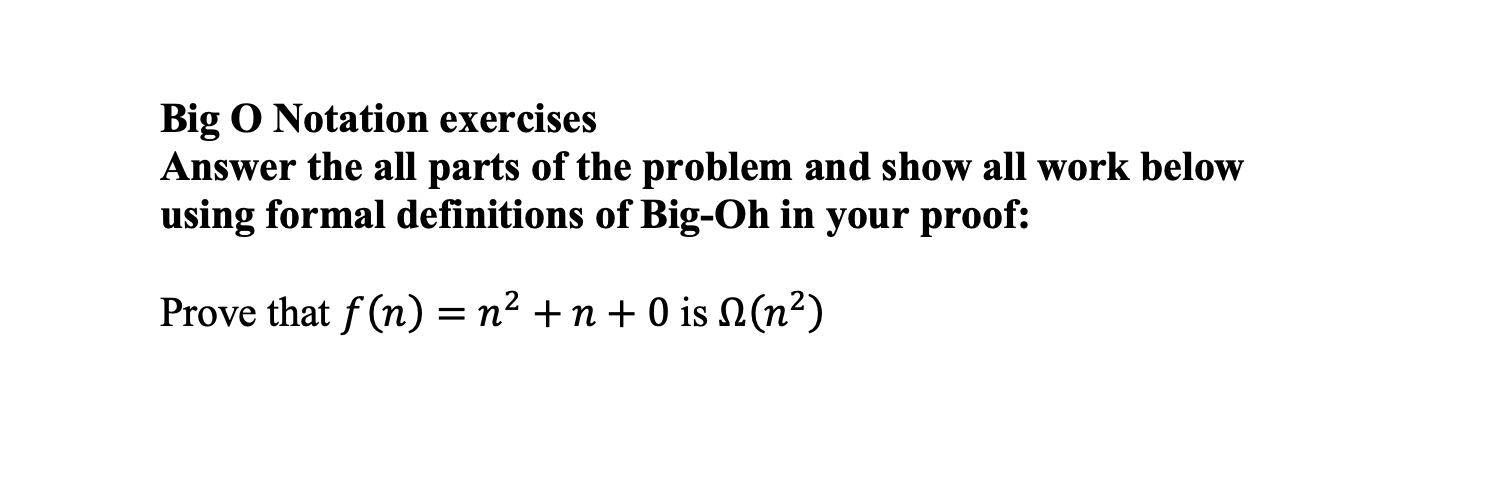
Working Through Big O Complexity by Hand
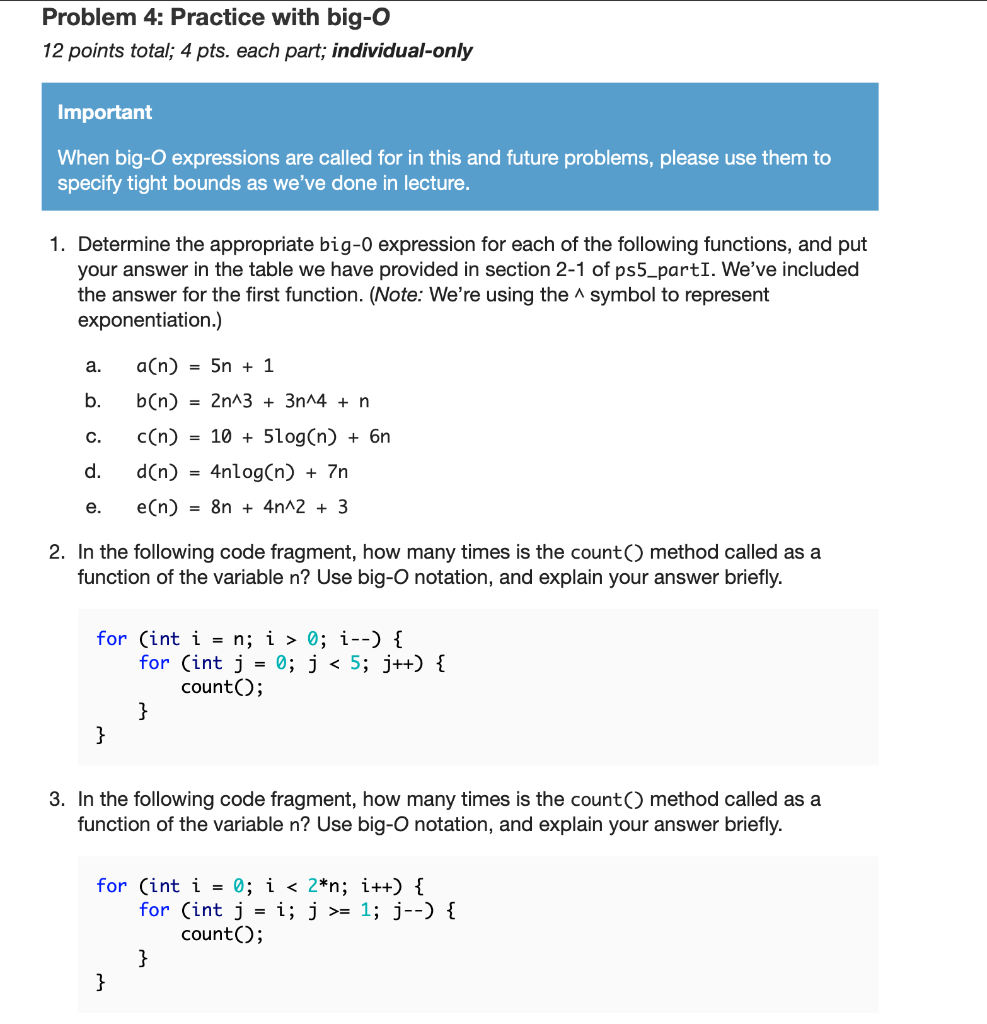
Most people learning algorithm analysis get stuck because they treat it like a memorization exercise. It isn't. The real skill is pattern recognition across loop structures and recursive calls. I found this out the hard way during a code review when someone submitted a solution they claimed was O(n) but was actually O(n² log n) because of a nested loop hiding inside what looked like a single pass. They had written a flattening operation that iterated over a list and then ran a sorted search on the same data in the same traversal. The Big O notation practice problems with answers I'd found online all had clean textbook inputs. Real code doesn't work that way. Start by identifying every operation that scales with input size. Don't look at the code and guess. Actually trace through it. Walk through a concrete example where n equals 100 and count the rough number of steps each block takes. This is faster than most people expect and catches errors that abstract reasoning misses. Here's a practical method I use and recommend to junior engineers on my team. Step one: Locate the outermost control flow. Is there a single loop running n times? A recursive call splitting the problem in half? A nested loop where the inner loop depends on the outer variable?
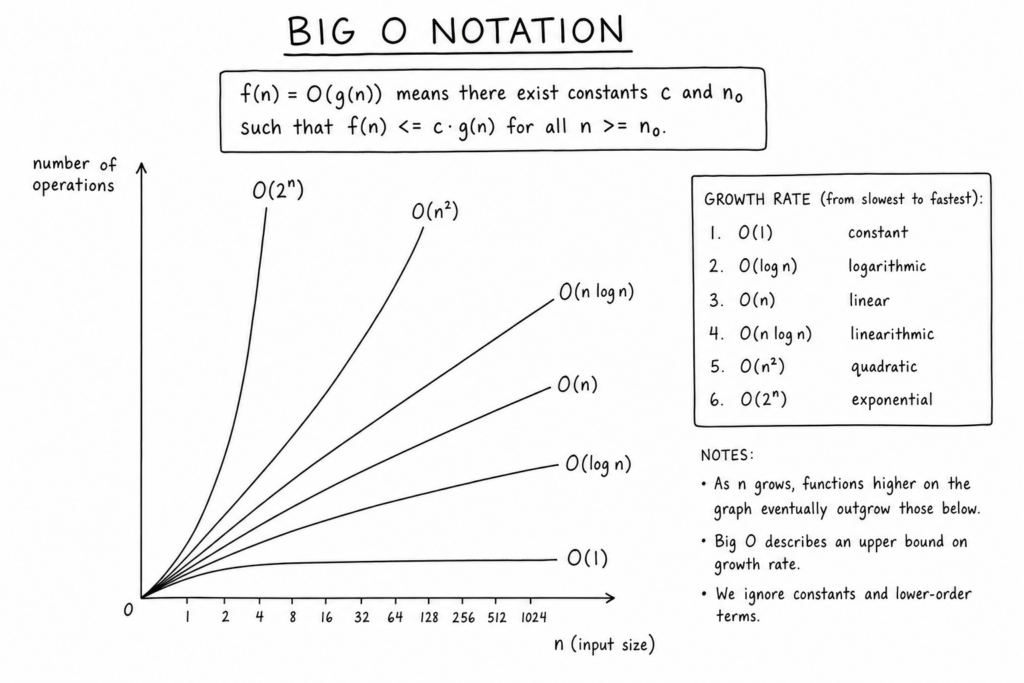
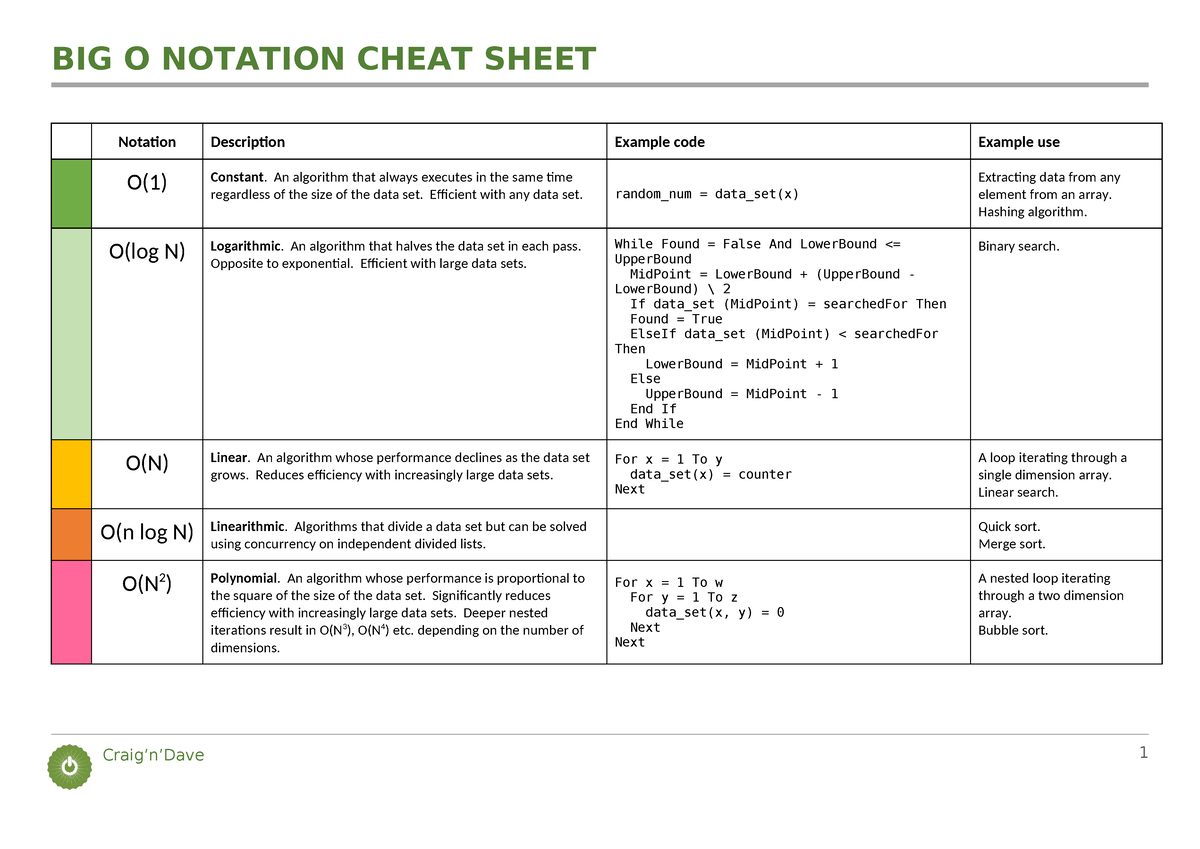
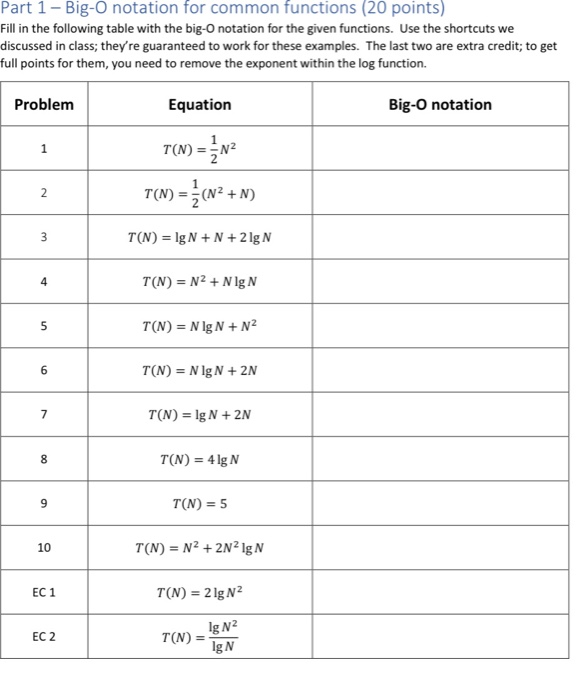
Step two: For each loop or recursive call, determine what portion of the input it processes and how many iterations occur. A loop from 0 to n is O(n). A loop that halves the remaining range each time, like binary search, is O(log n). Two independent loops running n times each combine to O(2n), which simplifies to O(n). Nested loops where the inner one runs n times for each iteration of the outer are O(n²). Step three: Strip constants and lower-order terms. O(n² + 5n + 3) becomes O(n²). The dominant term is what matters at scale. If your algorithm has a pre-processing step that takes O(n log n) and then a dominant O(n²) section, the overall complexity is O(n²). Step four: Check for hidden complexity. This is where people fail. A function call inside a loop might look cheap but could itself be O(n). Sorting inside a loop is a common trap. String concatenation in a loop in certain languages creates O(n²) behavior due to memory reallocation. HashMap lookups are O(1) average but degrade to O(n) worst case with poor hash distributions.
Common Practice Problems and How to Solve Them
Here are the problem types that show up most frequently in technical screening rounds and how to approach each one methodically. Problem type one: two-sum variant. Given an array of integers and a target value, find two elements that sum to the target. Return their indices. The naive approach checks every pair, giving O(n²) time and O(1) space. The better approach uses a HashSet to store complements as you iterate, achieving O(n) time and O(n) space. The tradeoff is memory for speed. In an actual production system I worked on, we used the HashSet approach for arrays under a million elements and switched to sorting plus a two-pointer scan for larger datasets because the memory allocation was causing GC pauses. Problem type two: finding the middle of a linked list. Use the fast and slow pointer technique. Fast moves two nodes per iteration, slow moves one. When fast reaches the end, slow is at the middle. This runs in O(n) time with O(1) space. Simple pattern, worth memorizing because it appears in many forms.
Get the Full Details
Problem type three: merging two sorted arrays. Use two pointers starting at the beginning of each array. Compare the current elements and advance the pointer pointing to the smaller value. Append to a result array. This is O(m + n) time and O(m + n) space for the output. If you sort both first and then merge, you add an unnecessary O(m log m + n log n) preprocessing step. Don't do that unless the arrays aren't already sorted, in which case you need the sort. Problem type four: checking if a string contains all unique characters. Without extra space, sort the string first, which costs O(n log n), then scan once for duplicates, giving O(n log n) total. With a boolean array or HashSet, check each character against the set in O(n) time and O(1) or O(n) space depending on character set size. The space-constrained version is the interview trap. They say no extra data structures, which forces the sort approach. Problem type five: Fibonacci using dynamic programming. The naive recursive solution is O(2) because it recomputes the same values repeatedly. Caching results in a table drops it to O(n) time and O(n) space. Tracking only the two previous values reduces space to O(1). This is the classic example of why memoization matters and what memoization actually does to the complexity profile of an algorithm.
Big O Notation Practice Problems With Answers That Test Edge Cases
The problems above cover standard cases. The harder questions test whether you understand what happens at the boundaries. Consider a binary search on a rotated sorted array where the array contains duplicate values. The standard O(log n) binary search fails because you can't determine which half to discard when the middle element equals the boundary element. You handle this by decrementing or incrementing the pointer one step at a time when arr[mid] equals arr[high] or arr[low], which in the worst case degrades to O(n). I've seen candidates miss this entirely and insist the answer stays O(log n) regardless of duplicates. It doesn't. Another edge case that trips people up is the analysis of divide and conquer algorithms where the subproblems aren't equal. The Master Theorem assumes a and b are constants and the subproblems are identical in size. If your algorithm splits a problem into sizes n/3 and 2n/3 instead of n/2 and n/2, the recursion tree is unbalanced and the Master Theorem doesn't apply directly. You need to use the recursion tree method or substitution method instead. The depth becomes O(log n) still, but the work per level isn't uniform, so the total complexity differs from what Master Theorem would give you.
Where Big O Analysis Breaks Down
I need to be blunt about this because nobody talks about it enough. Big O notation describes asymptotic upper bounds. It tells you what happens as input approaches infinity. In practice, your input never approaches infinity. For small datasets, an O(n²) algorithm with a tiny constant factor will routinely outperform an O(n log n) algorithm with heavy overhead. Quick sort is technically O(n²) in the worst case but almost always beats merge sort on real-world data because its constant factors are lower and it has excellent cache locality. Same with insertion sort on nearly sorted arrays, which runs in O(n) time despite being classified as O(n²) generally. Big O also ignores memory access patterns. An algorithm that runs in O(n) but causes cache misses on every iteration can be slower than an O(n log n) algorithm that accesses data sequentially. Cache-aware complexity analysis is a real field and matters when you're building systems that process millions of records. If you only optimize for Big O and ignore memory behavior, you'll ship code that performs worse than the simpler alternative. Space complexity is equally important but routinely skipped. An O(n) time solution that allocates a separate array for every element uses O(n) space and may trigger memory constraints or garbage collection overhead. In-memory systems and embedded environments where heap space is limited require you to think about space tradeoffs as seriously as time tradeoffs.
A Real Problem I Had to Fix
Last year I inherited a service that was supposed to deduplicate user transactions by matching records within a time window. The original developer wrote a nested loop comparing every transaction against every other transaction. For 10,000 records this took about four seconds. For 100,000 records it took roughly five minutes. The complexity was clearly O(n²). My first fix was to sort the records by timestamp and then use a sliding window, reducing the comparison space dramatically. This brought the runtime down to roughly 0.3 seconds for 100,000 records. The complexity shifted to approximately O(n log n) due to the sort step, with the window scan being O(n) after sorting. The second fix was deeper. The sliding window approach still compared records that were close in time but far apart in user ID. I added a HashMap keyed by user ID, so each user's transactions were grouped first. Then the sliding window only ran within each user's group. For a dataset with thousands of users, this reduced the average group size significantly and cut the runtime to under 50 milliseconds for 100,000 records. The key insight was that the quadratic behavior came from comparing across groups that would never match. Once you constrain comparisons to relevant pairs, the effective complexity drops far below what the naive analysis suggests.
How to Practice This Skill Effectively
Don't just read solutions. Write the algorithm first, even if it's wrong. Trace through it with a small input on paper. Count the operations yourself. Then compare your analysis to the expected answer. The gap between your count and the correct complexity is where the learning happens. Most practice resources skip this step and just give you the answer, which is why people study for months and still can't analyze an unfamiliar algorithm under time pressure. Use platforms that let you submit code and see runtime metrics alongside your complexity claim. If you say your solution is O(n) but the runtime graph shows a quadratic curve as input grows, your analysis is wrong. This feedback loop is more valuable than any written answer key. When practicing, focus on recognizing structural patterns rather than memorizing individual problems. The two-pointer pattern, the sliding window pattern, the divide and conquer pattern, and the memoization pattern each correspond to specific complexity classes. Learn to map structure to class, and the problems become variations you can solve on the spot. The hardest part of Big O analysis isn't the math. It's the discipline of actually counting operations instead of guessing. When you slow down and trace through the code line by line with concrete numbers, the complexity becomes obvious. The people who struggle are the ones who look at a block of nested loops and immediately assume O(n²) without checking whether the inner loop actually runs n times in every case. Sometimes it runs log n times. Sometimes it runs a constant number of times. Sometimes it runs n/2 times. All of those change the final answer.