The 2003 Northeast Blackout: What Actually Happened
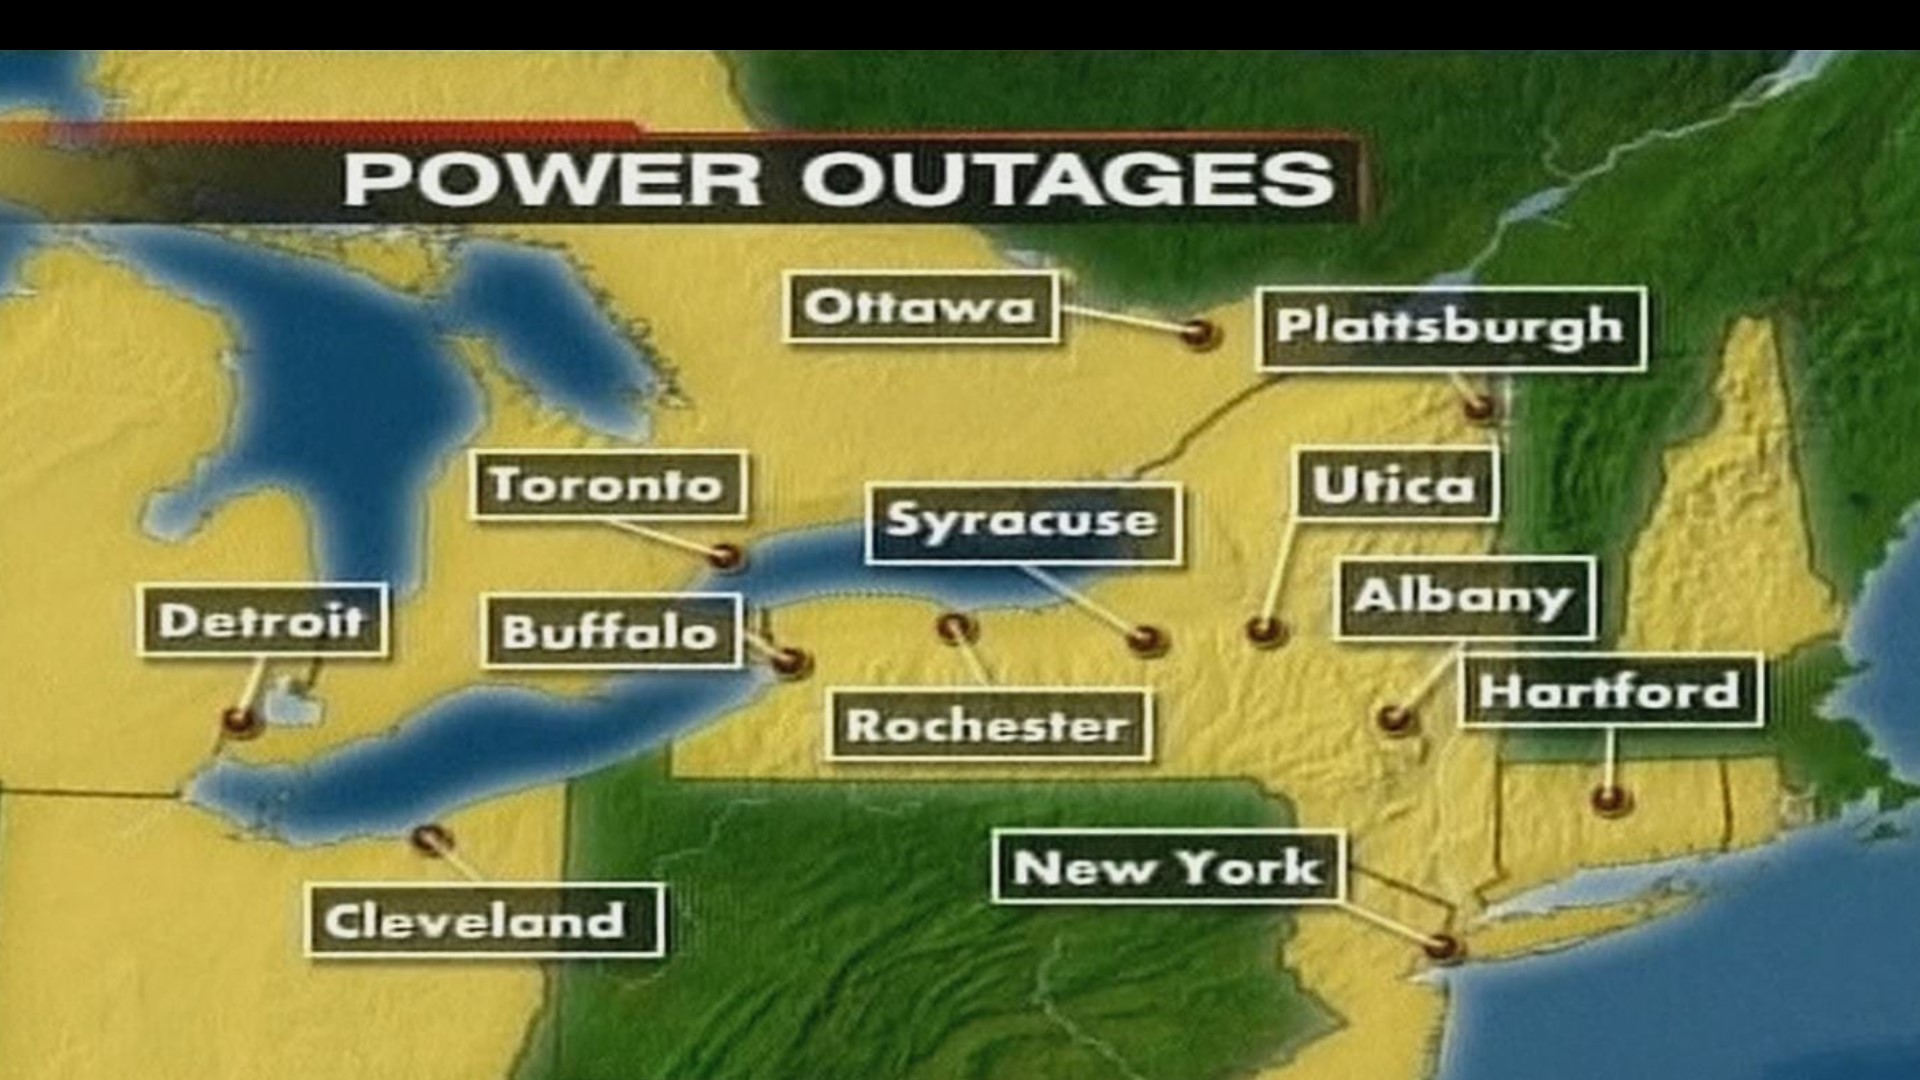
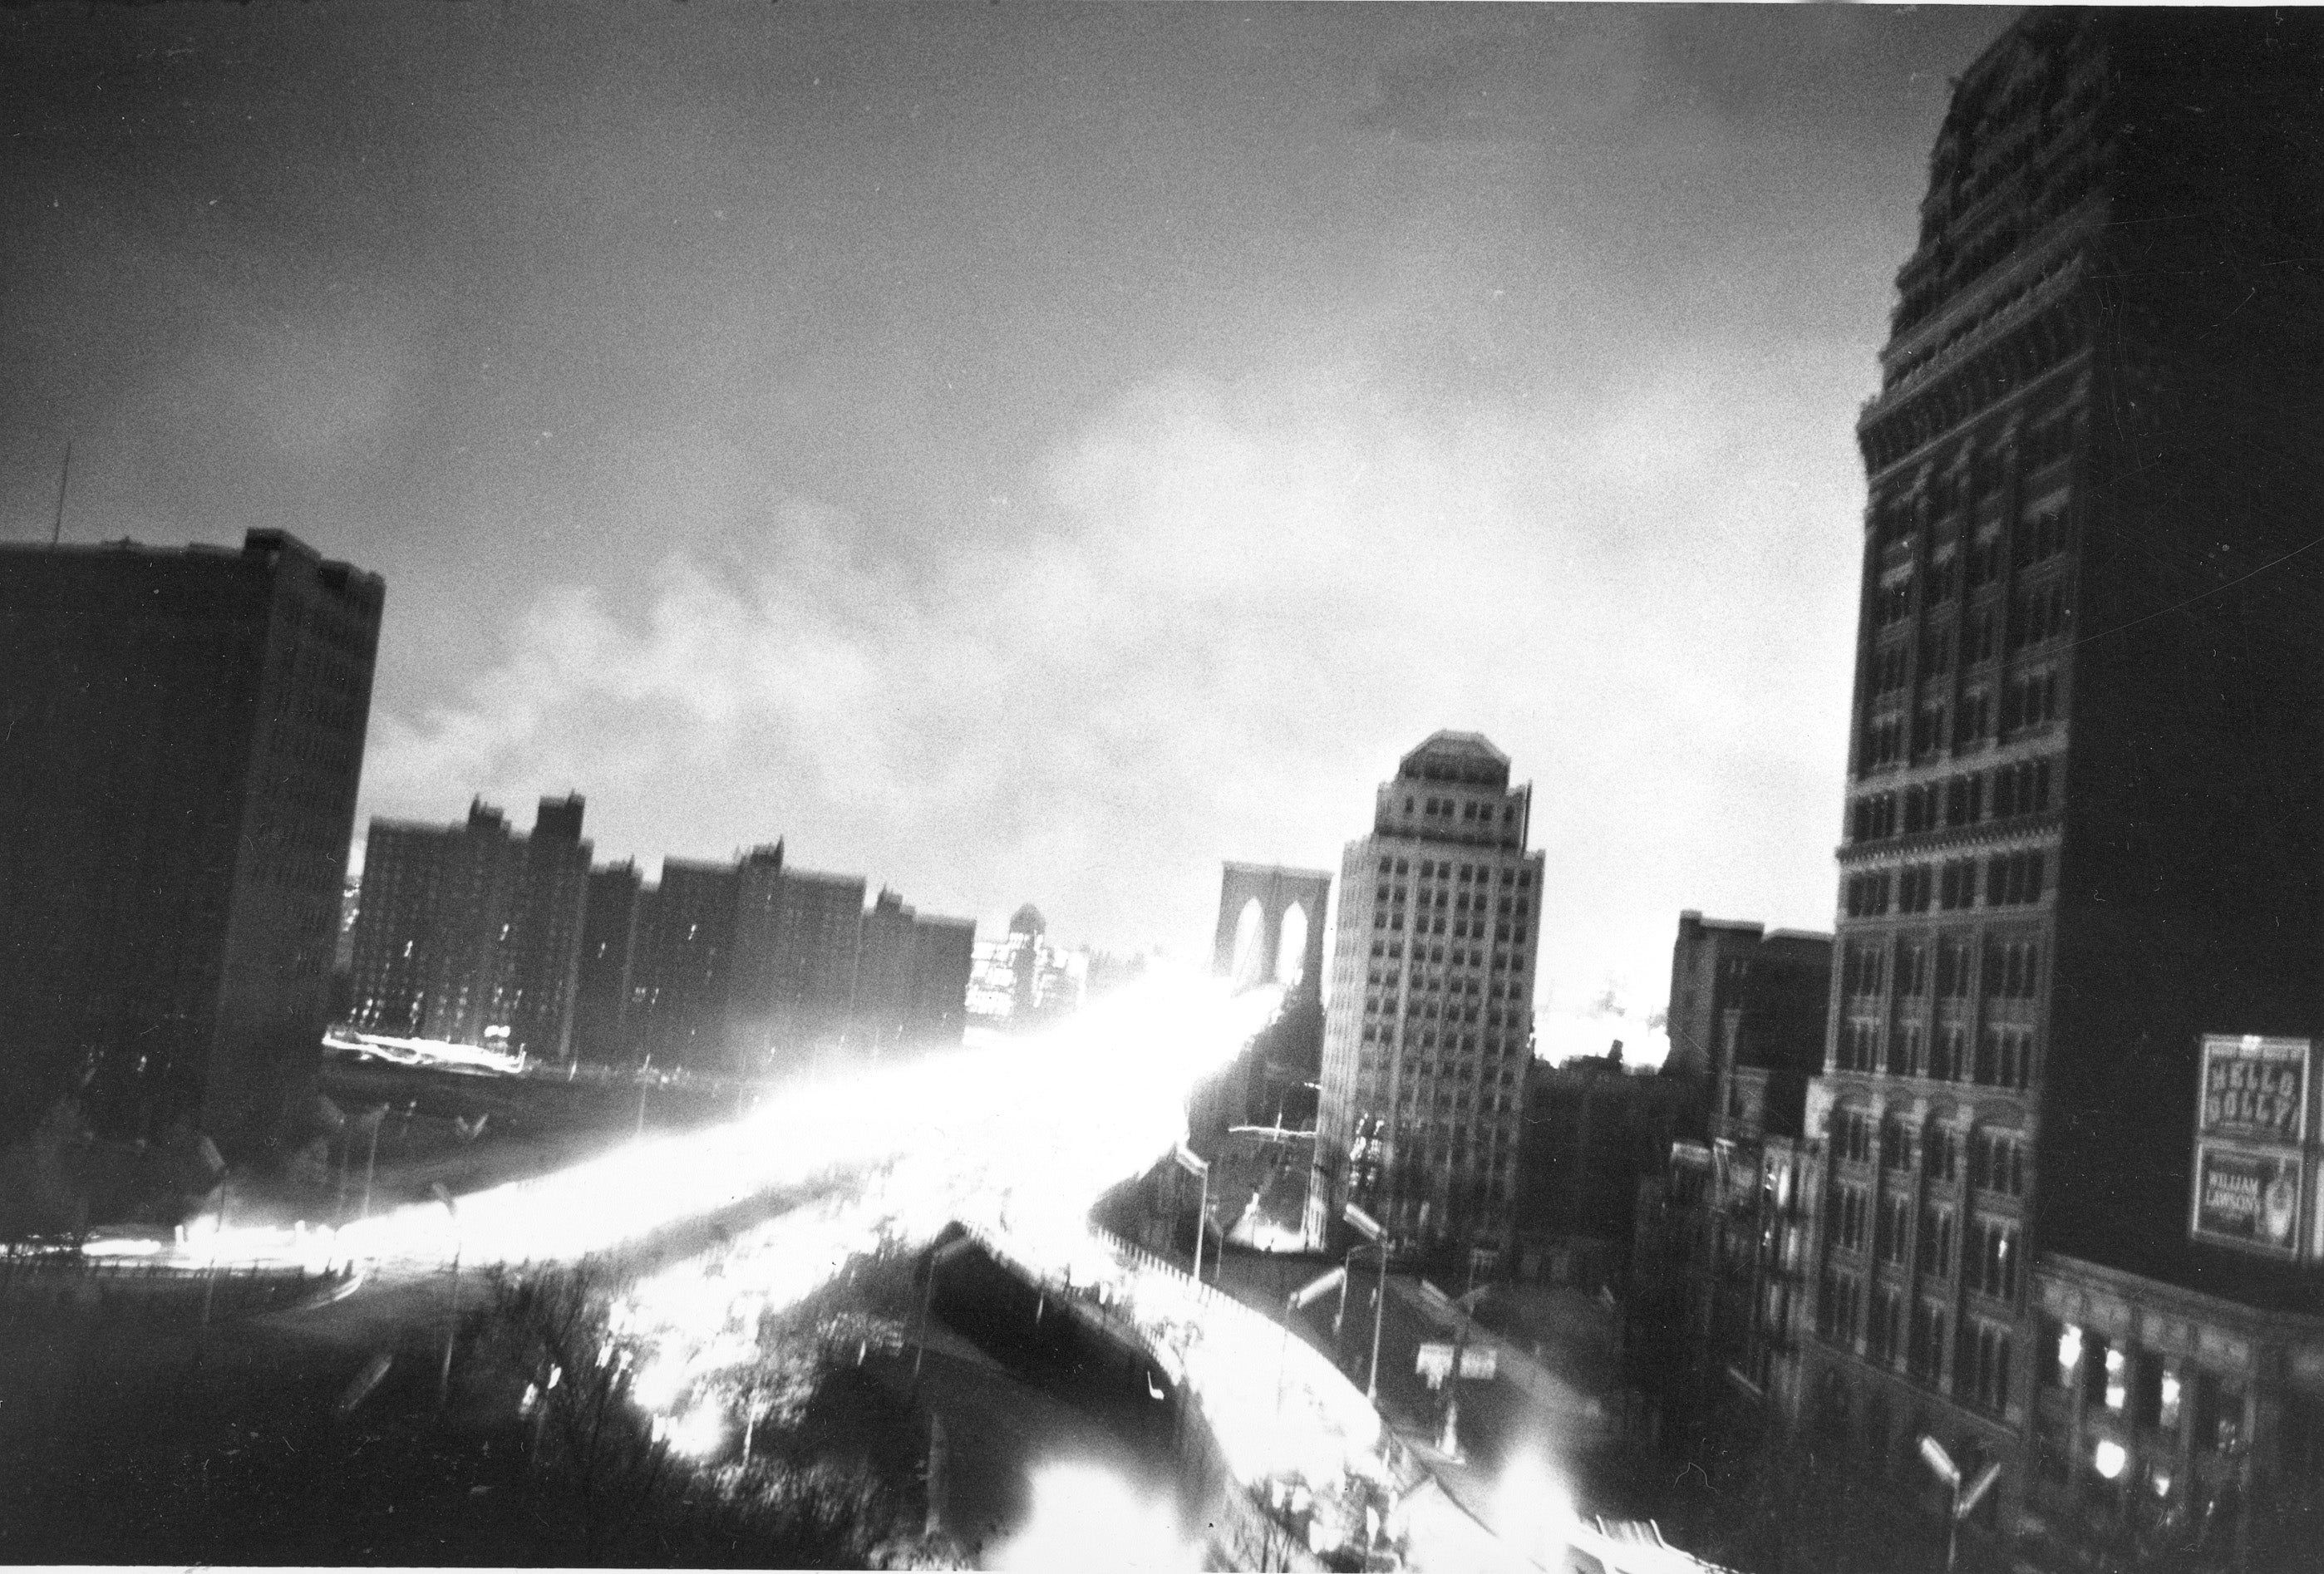
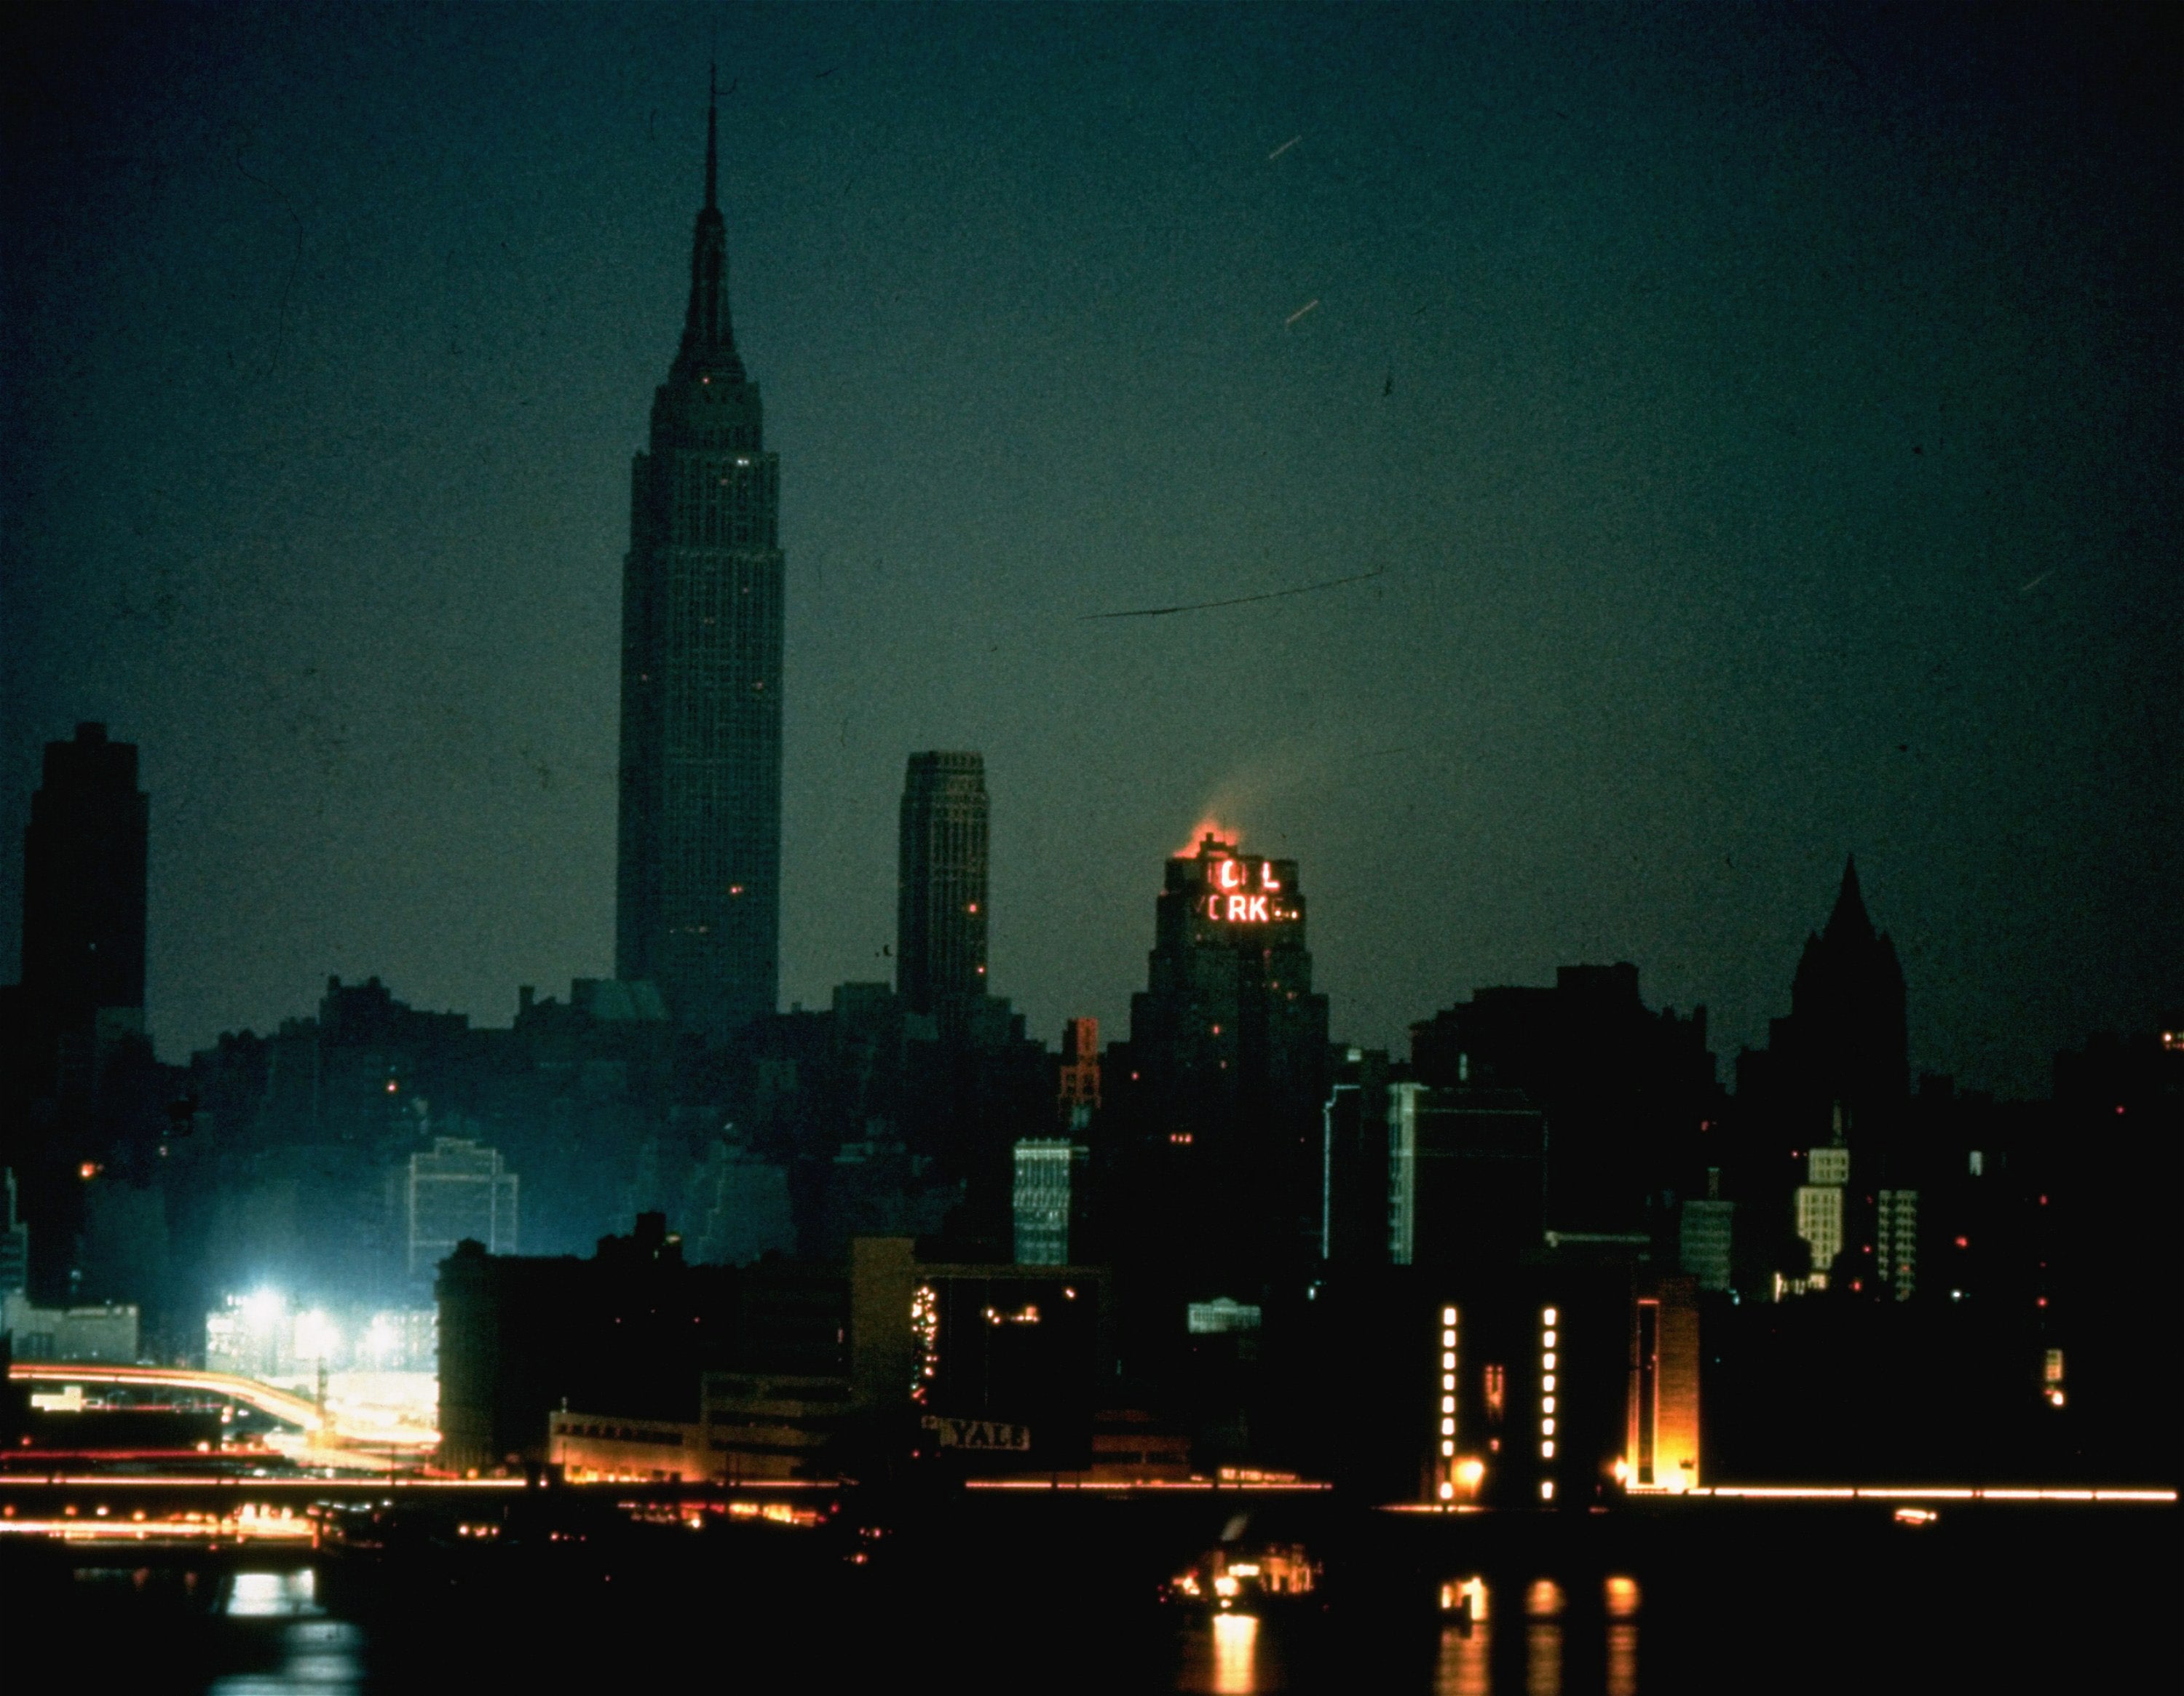
The largest blackout in North American history hit on August 14, 2003. It started around 4:10 PM Eastern Daylight Time and cascaded across five northeastern US states and parts of Ontario, Canada. About 55 million people lost power. The outage lasted up to four days in some areas, though most restoration happened within 24 to 48 hours. Peak affected load was roughly 61,000 megawatts, which was about 25% of the combined utility demand in the region at the time. The failure wasn't a single event. It was a chain. First, a tree contact on a high-voltage transmission line in Ohio tripped offline at 2:05 PM. The control room at FirstEnergy's Eastland Generating Station never saw the alarm go off because their alarm system was being updated that day. That's not a small detail. Missing a single tree contact notification is the kind of operational gap that compounds fast. The line was out, but the remaining lines picked up the load. Without proper re-dispatch or reactive power support, voltages began to sag. The software running on their line-monitoring system was set to an older version that didn't alert operators about impending line failures. Trees kept growing. Lines kept drooping. At 3:37 PM, a third line in the same corridor tripped due to vegetation contact.
At this point, the system was barely holding together. By 4:10 PM, the entire control zone collapsed. The protective relays shed generator output faster than demand could be balanced, and the regional grid split into multiple islanded sections. Some sections had excess generation; others had severe deficits. The cascade rippled across three control areas within minutes.
Why This Wasn't Just Bad Luck
People assume massive blackouts happen because of equipment failure or storms. That's rarely the full picture. The real problem here was the absence of situational awareness. Operators didn't know the grid was in distress until it was too late. That's the counter-intuitive part nobody talks about enough: under extreme conditions, what you don't see matters more than what breaks. The NERC report that followed identified at least nine violations of reliability standards. Most of them weren't catastrophic in isolation. They were systemic drift. Software not updated. Alarms unacknowledged. Vegetation management falling behind. Real-time monitoring tools not properly configured. When those gaps align, the grid doesn't fail from a single point. It fails because everyone assumed someone else was watching.
Get the Full Details
What Changed Afterward
FERC established mandatory reliability standards through NERC, which used to be purely voluntary. Enforcement capacity increased. Real-time grid monitoring improved significantly. State and regional reliability councils got better data access and clearer protocols for cascading failure scenarios. The 2011 Eastern Interconnection outage and the 2015 Southern California event both showed faster detection and more effective mitigation than 2003 would have allowed. That said, the grid still struggles with coordinated response during large-scale failures. I worked a restoration assessment project in 2019 where we found that several regional control centers still couldn't reliably share situational data within the three-minute window required during a fast-moving cascade. The standards exist on paper. Implementation is patchy. If a blackstart sequence gets interrupted mid-process because two regions aren't communicating on timing, you can lose hours of recovery time. We handled one such case by manually cross-referencing SCADA timestamps between adjacent control areas to reconstruct the actual sequence. It took about six hours of tedious work but confirmed exactly where the handoff had failed.
Practical Lessons for Grid Operators
If you're dealing with grid operations or emergency planning, here's what actually matters based on post-2003 improvements: Alarm management is not optional. A silenced or suppressed alarm during peak loading is the most common precursor to cascading failure. Test your alarm suppression rules quarterly, not annually. During one of my audits, I found a control center that had alarm suppression active for over 11 days after a routine software patch. The patch hadn't been rolled back. Operators had simply stopped noticing the silence. Vegetation management needs to anticipate growth, not react to contacts. The standard trimming cycle in the Northeast at the time was seven years. Tree species in those corridors can grow two to three feet per year under optimal conditions. That means the distance between a trimmed line and a fault can close in two or three growing seasons, not seven. Shorten your assessment windows and model growth rates for the specific species on each corridor.
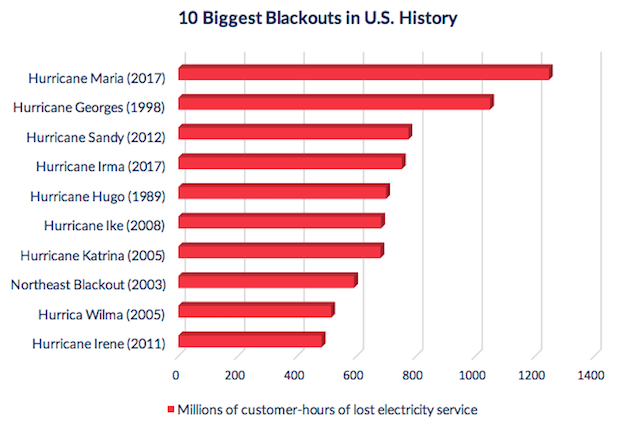
Blackstart sequencing should account for asymmetric islanding. Most plans assume the grid splits into balanced islands. It rarely does. In the 2003 event, the Cleveland area ended up with excess generation while surrounding regions went dark. Recovery required careful coordination of frequency restoration before reconnection. If you haven't modeled asymmetric island scenarios in your restoration plan, you haven't tested it thoroughly enough. The bottom line is that the Biggest Blackout In History wasn't caused by anything dramatic. It was caused by ordinary systems operating under normal degradation. That's what makes it dangerous. If you're reviewing your own procedures, start by checking whether your alarms are working, whether your software matches your current configuration, and whether your team knows what happens when the monitoring tools stop telling them things they need to hear.