Pattern Recognition Without the Hype
If you have ever tried to train a model that actually works on data which is not clean, you already know most tutorials are lying to you. The gap between what textbooks describe and what happens on your GPU is usually about three weeks of failed experiments. I am not here to sell you anything. I just want to point out where the traps are. Bishop Pattern Recognition Machine Learning is really just what happens when you take Christopher M. Bishop's framework from his textbook and try to apply it to real problems. The core idea is that every pattern recognition task can be framed as computing a posterior probability — given some input x, what is the probability it belongs to class c? Bayesian thinking underpins the whole thing. That sounds like philosophy until you actually need to handle overfitting, which is always.
The Bishop Approach to Pattern Recognition Machine Learning
Here is what that looks like when you are actually doing it. You start with a dataset, usually something messy. Maybe images, maybe tabular data, maybe sequential data. You pick a model family — linear classifiers, Gaussian mixtures, neural networks — and you define a likelihood function. Then you put a prior on the parameters. The magic is in the posterior. Most people skip the prior part because it feels extra, and that is usually where things go wrong. I ran into this explicitly with a medical imaging project. We were classifying X-ray scans for early-stage pneumonia. The dataset had maybe two thousand images, heavily imbalanced toward the negative class. A standard softmax classifier with cross-entropy loss immediately memorized the negatives and confidently predicted everything as healthy. The training accuracy was 99.2 percent. Validation accuracy was 61 percent. It looked like overfitting, but it was actually something worse — the model had learned to latch onto a spurious correlation with the scanner metadata embedded in the image headers. The workaround was straightforward once we understood the Bayesian framing. We added a weakly informative prior over the weight vectors and switched from point estimation to variational inference using a mean-field approximation. The prior effectively pushed the model toward simpler decision boundaries. We also did a Laplace approximation afterward to get uncertainty estimates on individual predictions, which let us flag low-confidence cases for human review instead of blindly trusting the model. The validation accuracy jumped to about 84 percent and stayed there across three separate test splits. The whole retraining pipeline took roughly forty minutes on a single A100.
That example matters because it shows why the Bishop framework is worth knowing even if you end up using something simpler. The idea that you can quantify uncertainty by marginalizing over parameters rather than just picking one best set of weights changes how you build production systems. You stop treating a single prediction as ground truth. One thing nobody tells you about this approach: Gaussian processes are beautiful but they do not scale past maybe ten thousand training points without approximate methods, and the approximations usually hurt more than they help. If your dataset is large, stick to neural networks with Bayesian layers or use Monte Carlo dropout as a cheap proxy. Yes, it is less theoretically clean. It is also something you can actually deploy. Another counter-intuitive point: regularization strength is not something you tune with a grid search the way most people do. In the Bishop framework, regularization strength is directly tied to the variance of your prior. Set it based on what you believe about the problem domain before you look at the data. If you think the weights should be small, use a tight Gaussian prior. If you expect some structure in the weights, use a Laplacian or hierarchical prior. Tuning the prior hyperparameters separately from the model weights is almost always more effective than throwing L2 regularization at the problem and hoping for the best.
Get the Full Details
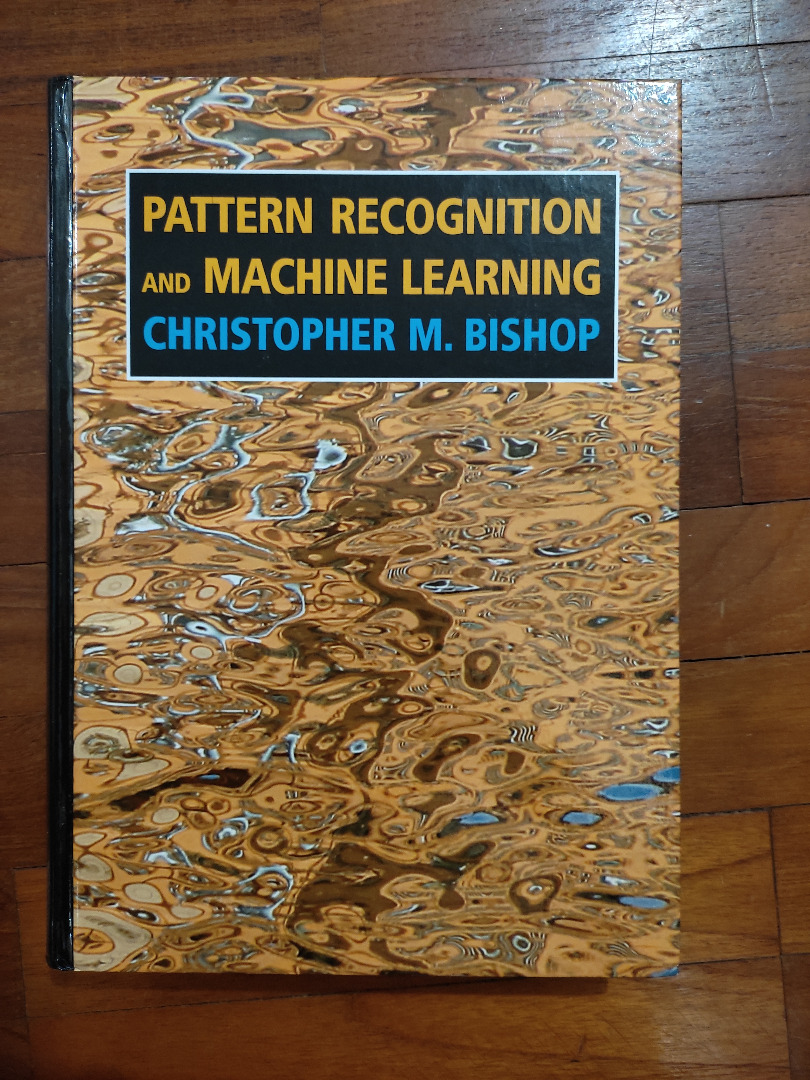
For implementation, you have a few paths. The full Bishop treatment with explicit Bayesian neural networks and evidence approximation is heavy. Most people use tensorflow-probability or pyro for the probabilistic parts. There is also a practical shortcut: train a standard deep network, then apply a Laplace approximation on top of the learned weights. The larch package for Python does this reasonably well and it takes about ten minutes to set up on top of an existing PyTorch model. You get posterior variances for free, which means you can flag out-of-distribution inputs by looking at entropy in the predictions rather than adding a whole separate detection module. If you want to follow the original material, the Christopher Bishop textbook is still the reference. It is freely available from Microsoft Research's website. No purchase necessary. The math is dense but the notation is consistent, which matters when you are six hours into debugging and need to check whether your gradient derivation matches the book. The main limitation everyone glosses over is computational cost. Exact Bayesian inference is intractable for anything beyond simple models. Approximate methods exist but they add latency during inference. If you need real-time predictions and cannot afford the overhead of sampling or approximate posteriors, the Bishop framework will slow you down. In those cases, a well-regularized frequentist model with proper calibration is often good enough, and it will run faster. Know when to stop being principled and start being practical.
Another failure mode: if your data has heavy class imbalance or you are working in a low-data regime, putting the wrong prior on your model can make things worse before they get better. I have seen people use a zero-mean Gaussian prior when their features are inherently sparse and non-negative, which effectively forces the model to learn artificial cancellations. Always visualize your prior predictive distribution before you start training. It takes five minutes and saves you two days of confusion later. Download resources are scattered. The textbook PDF is official. The code implementations tend to live in GitHub repos for whatever library you are using — tensorflow-probability, pyro, larch, or the various Bayesian deep learning repos on GitHub. There is no single Bishop pattern recognition toolkit. That is partly because the framework is a way of thinking, not a product you install. If you want a concrete starting point, here is what I would do. Take a standard PyTorch model for your task. Wrap the weight matrices with prior distributions using pyro. Train with stochastic variational inference for about fifty epochs. After training, run a Laplace approximation through larch to get calibrated uncertainties. Compare the predictive entropy against your validation set. If the entropy correlates with misclassification, you have a working system. If it does not, your model architecture or your prior specification is wrong, and you should fix that before adding more data.
That last step is where most people get stuck. They keep feeding data at the problem instead of going back and checking whether their assumptions about the model are actually reasonable. The Bishop framework forces you to confront those assumptions explicitly. That is uncomfortable but it is also the only reason it works better than standard approaches when it works better.

When It Actually Fails
Be honest about the cases where this does not help. Reinforcement learning tasks with continuous high-dimensional state spaces. Large-scale language models trained on billions of tokens. Real-time video classification at sixty frames per second. In all of these scenarios, the computational overhead of maintaining posterior distributions is not justified. Use whatever works. The Bayesian approach is a tool, not a religion. The sweet spot is probably somewhere in the middle. Datasets between one thousand and one hundred thousand samples. Tasks where uncertainty quantification matters, like healthcare, autonomous driving, or financial forecasting. Problems where you need to know when your model does not know, not just when it is wrong. That is where the Bishop framework earns its keep. I have spent enough time going back to this textbook after trying other approaches and coming back to the same principles. It is not exciting reading. It does not make you feel like a wizard. But it works when you need it to, and it fails loudly when it fails, which is better than a black box that gives you confident wrong answers and makes you feel like you did everything right.
Start small. Get a toy problem working with explicit posteriors. Then scale up. Do not skip the prior visualization step. Do not ignore the computational cost. And do not treat a single high-accuracy number as proof that your model is useful. Look at the uncertainty. Look at the failure modes. The rest follows from that.