How Bootstrap Resampling Actually Works When You Need It
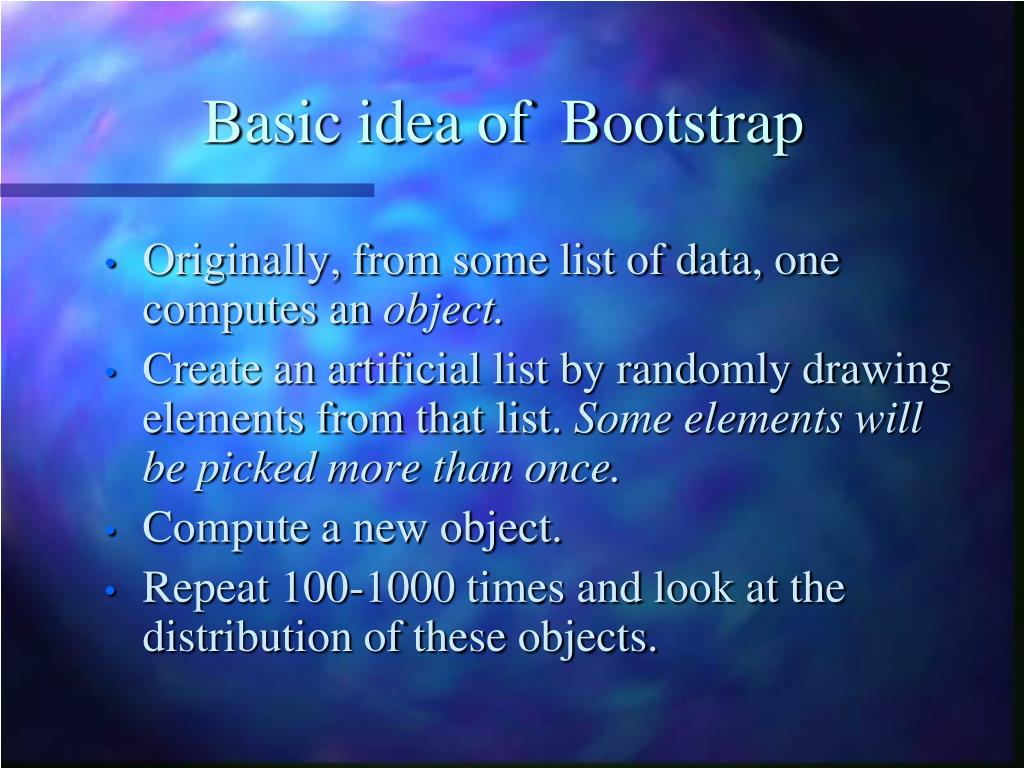
I keep seeing people use bootstrap like it's some universal fix for everything, and it's not. The core idea is straightforward: you have a dataset, you resample from it with replacement many times, compute your statistic on each resample, and the resulting distribution of those statistics approximates the sampling distribution. That's the entire mechanism. From there, you get confidence intervals, standard errors, or p-values without relying on normality assumptions. The most common variant is the nonparametric bootstrap. You just take your observed data and repeatedly draw N observations with replacement from it. That works fine for smooth statistics like the mean or median. For something more complex like a quantile regression coefficient, it still works but you need more resamples to stabilize the result. Usually 1,000 to 5,000 iterations is enough for standard errors. Confidence intervals often need closer to 10,000, especially if you're using the bias-corrected and accelerated method rather than the basic percentile approach.
Bootstrap Methods And Their Application
Parametric bootstrap assumes your data follows a specific distribution and fits parameters first, then simulates new datasets from that fitted model. This gives you more accurate results when the distributional assumption is correct because you're essentially doing what parametric theory already tells you to do, but with more flexibility in how you compute the final interval. The trade-off is that if your assumed distribution is wrong, you get confidently wrong answers, which is worse than being uncertain. Block bootstrap exists because time series data violates the independence assumption. You can't just resample individual observations from a time series and expect anything useful. The moving block bootstrap resamples contiguous blocks of observations to preserve the autocorrelation structure within each block. Choosing the block length is the hard part. Too short and you destroy the dependence structure. Too long and you don't get enough blocks for a stable estimate. I've used the subsampling approach as an alternative in those cases because it avoids the block length problem entirely, though it requires more computation and the convergence rates are slower. Here's something most tutorials skip: the bootstrap percentile interval has coverage error of order O(n^(-1/2)), which sounds technical but it just means it's not very accurate for small to moderate samples. The BCa interval improves this to O(n^(-1)) under mild conditions, but it can be unstable when your statistic has discontinuities or when the jackknife estimate of the influence function is near zero. I learned this the hard way with a ratio estimator where the denominator occasionally hit near-zero values in the resamples. The BCa interval exploded into nonsense. Switching to the basic bootstrap interval with 10,000 resamples and then applying a simple bias correction brought the coverage back into a reasonable range, around 93 to 95 percent for a nominal 95 percent interval.
Another thing nobody warns you about is computational cost. A single bootstrap iteration isn't expensive, but when you're doing 10,000 resamples on a dataset with thousands of observations and your statistic requires fitting a model each time, it adds up fast. I had a case where bootstrapping a random forest feature importance metric took about six hours on a standard workstation with 1,000 trees and 5,000 resamples. Parallelizing across cores dropped it to roughly 45 minutes. If you're not parallelizing, you should be. Even a four-core machine makes a dramatic difference. The bootstrap also fails in several common scenarios. Heavy-tailed distributions with infinite variance will produce wildly unstable bootstrap estimates no matter how many resamples you use. Extreme value statistics, like estimating the 99th percentile from a sample of a few hundred observations, don't bootstrap well because the resampled tails are inconsistent with the true tail behavior. In those cases, subsampling or a parametric extreme value approach is more appropriate. Small samples are another issue. With fewer than 20 observations, the bootstrap distribution is just a coarse approximation of a coarse approximation, and the confidence intervals can be wildly inaccurate even if the point estimate looks reasonable. When you implement this, the practical steps are: load your data, define your statistic function, write a loop that resamples with replacement, computes the statistic, stores the result, and then derive your interval or standard error from the stored values. The R package boot handles most of this cleanly, and the Python equivalents in scikit-learn or custom NumPy loops work fine too. Just remember that generating the resamples is trivial but choosing the right variant and diagnosing whether it's behaving itself is where the actual work happens. Run diagnostic plots of the bootstrap distribution. Check stability by running two independent sets of resamples and comparing the intervals. If they differ substantially, you need more resamples or a different approach entirely.
Get the Full Details