Reading a boxplot is mostly about not misreading it
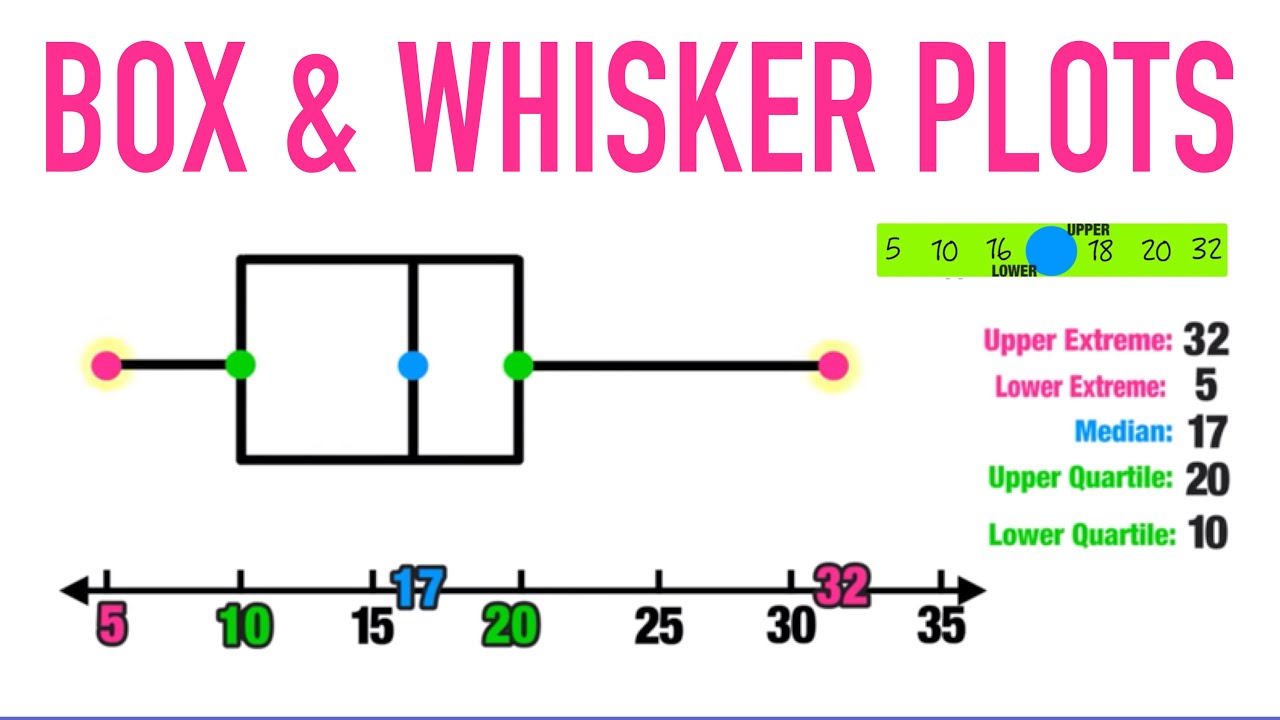
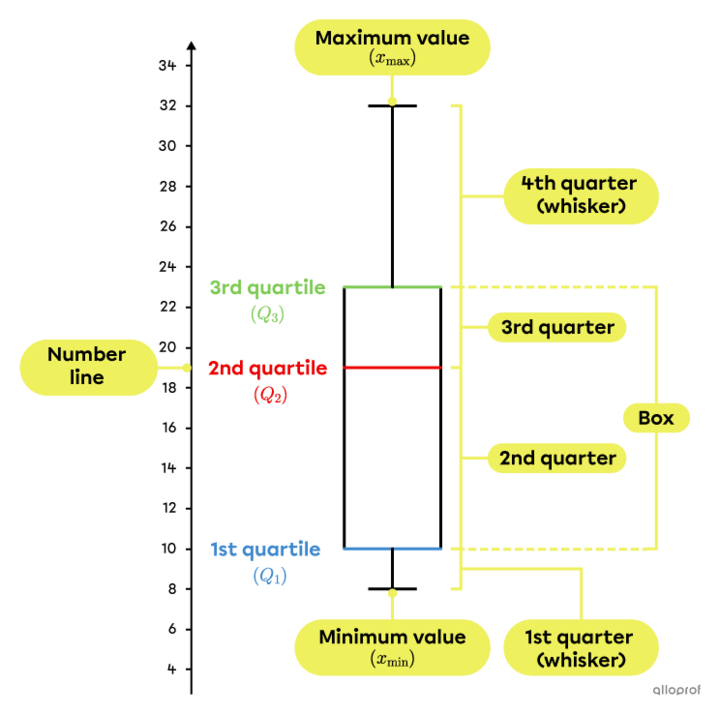
Most people look at a box and whisker graph and think they understand it immediately because the shape is simple. The shape is simple. The interpretation is where things get messy. I still see people in meetings confidently claim their data has no outliers because the plot looks "clean," not realizing that a compact box with no whiskers beyond the fence line just means the spread happens inside the observed range. That is a completely different thing from a tight, normal distribution. A boxplot shows five summary numbers. The minimum, the first quartile, the median, the third quartile, and the maximum. Outliers sit outside the whiskers as individual points. That is the textbook version. In practice, the way those numbers are calculated varies by software, and that variation matters more than most people admit.
How to build a Box And Whisker Graph in Python or Excel
In Python you use seaborn or matplotlib. The seaborn function boxplot takes a dataset and returns the plot. That part is trivial. The part that is not trivial is making sure your data is actually numerical, properly filtered, and that you understand which quartile method the underlying library is using. Matplotlib uses the inclusive method by default for its quartile calculations, which means the median gets included in both the lower and upper halves when you have an odd number of data points. That shifts Q1 and Q3 slightly compared to the exclusive method. In Excel, you have the older error bars approach or you can use the Analysis ToolPak add-in. The Analysis ToolPak boxplot option is surprisingly decent but it defaults to certain quartile interpolation that does not match Python or R. I once had a client compare a Python-generated boxplot against an Excel one for the same dataset and the outlier lists were completely different. The difference came down to how each program interpolates between data points when the quartile position falls between two values. They used different algorithms. Not all of them are documented clearly in the help files. For a quick tutorial approach, here is the manual method if you want to verify what your software is actually doing. Sort your data from smallest to largest. Find the median. Split the data into a lower half and an upper half. The median of the lower half is Q1. The median of the upper half is Q3. The interquartile range is Q3 minus Q1. Multiply that range by 1.5. Any value below Q1 minus 1.5 times the IQR or above Q3 plus 1.5 times the IQR is flagged as an outlier. The whiskers extend to the most extreme data point within those fences. Values outside become the dots.
I should say that last sentence again because it trips people up constantly. The whiskers do not necessarily reach the minimum and maximum of the dataset. They reach the most extreme point that is not considered an outlier. If your data has extreme values, the whiskers will be shorter than your actual range. That is by design, not a bug.
Get the Full Details

Edge cases that actually come up in production
Here is a specific problem I ran into recently. A manufacturing team was tracking the cycle time of a packaging line. The dataset had about 3,000 observations over eight weeks. The boxplot looked completely normal until I zoomed in and noticed there were no individual outlier points plotted, which normally suggests a clean dataset. But the lower whisker was extremely short, almost touching the bottom of the box. The process had been throttled by a bottleneck upstream that created a hard floor on cycle times. The data was not symmetric. It was uniformly compressed at the bottom with a long right tail. The boxplot made it look stable. It was not stable. The real issue was that the process had hit a constraint and the distribution was artificially flattened on one side. A boxplot alone would not have shown that clearly. I added a strip plot underneath it and the pattern became obvious immediately. This is why I always recommend pairing a boxplot with a raw data overlay when the sample size allows it. A strip plot or a beeswarm plot works well. You lose some of the statistical summary, but you gain visibility into actual data density. When you have fewer than 50 data points, the boxplot becomes almost decorative. It gives you a rough idea but the small sample means the quartile estimates are unstable anyway.
Counter-intuitive things beginners miss
One thing that catches people off guard is that a boxplot with a very small interquartile range does not automatically mean the process is precise. It means the middle 50 percent of observations are close together. The extremes could still be wildly inconsistent. I worked on a project where two vendors had nearly identical boxplots. Their Q1, median, and Q3 were almost the same. Their IQRs were essentially equal. But vendor B had a few extreme outliers that were three times worse than anything vendor A produced. The boxplot made them look equivalent at a glance. Only by looking at the individual outlier points could you tell the difference. This is another reason the outlier dots matter more than the box itself in many cases. Another thing is how skewed data behaves. When data is heavily skewed, the median line inside the box will appear off-center, closer to one edge. That is expected. People sometimes try to "fix" skewness by transforming the data before plotting it, but that is not always necessary. The boxplot is actually designed to handle skewness better than a histogram in some situations because it focuses on the middle fifty percent rather than the full density curve. You can read the direction and severity of the skew from the box position and whisker lengths without doing anything extra.
When a boxplot is the wrong choice
A box and whisker graph fails when you need to see the actual shape of the distribution. If your data is bimodal, meaning it has two peaks, the boxplot will obscure that entirely. It will show you one box, one median, and maybe some outliers. The two distinct modes will be invisible. In those situations, a histogram or a density plot is the better tool. I have seen reports where a team used boxplots to compare six different product lines, and three of them had bimodal distributions. The boxplots made all six look reasonably normal. The product quality issues in those three lines went unnoticed for months because the visualization did not reveal the second mode. Also, when you have many categories to compare, side-by-side boxplots become cluttered quickly. Beyond about ten groups on a single axis, readability degrades substantially. I usually switch to a notched boxplot for pairwise comparison or use a single grouped plot with careful color coding. The notched version adds a confidence interval around the median, which lets you do a rough visual test of whether medians differ significantly between groups. The notch should not overlap if the difference is likely real.

Common calculation pitfalls
The biggest source of confusion is that no single standard exists for how to compute quartiles. The M&M method, the exclusive method, the inclusive method, and several interpolation variants all exist. Python, R, Excel, and SPSS each pick different ones. If you are sharing results between teams or publishing them, always state which method you used. I learned this the hard way when two consultants produced conflicting boxplots for the same airline delay dataset and each blamed the other for being wrong. Both were technically correct for their chosen algorithm. The difference was subtle but it changed the reported median by about four minutes and moved two data points from outlier to non-outlier status. For reporting purposes, if you need consistency across platforms, the easiest workaround is to use the same library everywhere. If you are in an Excel-heavy environment and need to match Python results, consider using Python to generate the quartile values and paste them into Excel manually rather than relying on Excel's built-in boxplot function. It takes longer but it eliminates the interpolation mismatch.
A practical workflow that works
Start with your raw data in a spreadsheet or database. Clean it. Remove entries that are clearly data entry errors, not genuine outliers. A typo of 9999 hours where the unit should be seconds will destroy your plot. Then decide whether you need just the summary view or the summary with raw data overlay. Generate the plot. Check the outlier labels if your tool supports tooltips. Verify the quartile method against your documentation. Interpret the skew from the box position. Use the notch if comparing groups. Report the IQR and the fence values alongside the plot if the audience needs to reproduce it. That workflow takes about fifteen minutes for a standard dataset. The plot generation itself is usually under two minutes. The rest is cleaning and verification. Most of the time people spend on boxplots is spent arguing about which outlier definition to use, so just pick one and state it. The exact method rarely changes the practical conclusion unless your data sits right at the boundary of the 1.5 times IQR fence, in which case the interpretation genuinely depends on the choice you make.