Getting The Percentiles Right Is Where Most People Mess Up
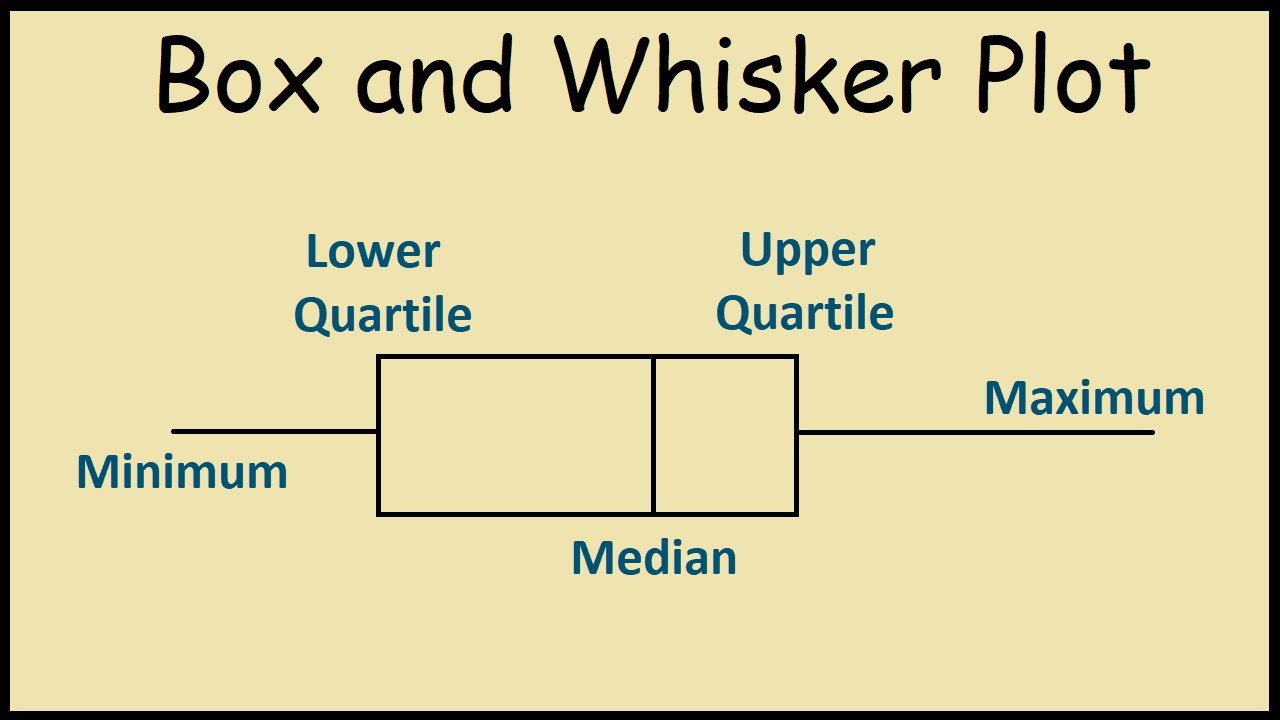
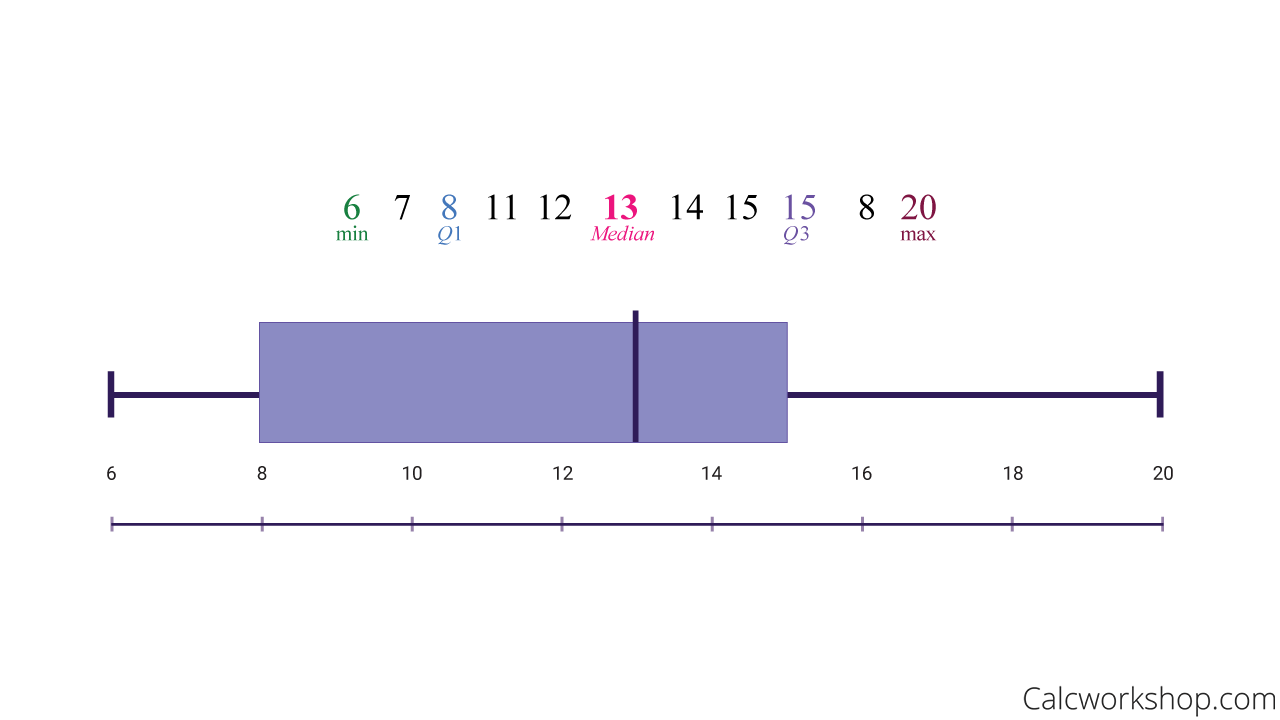
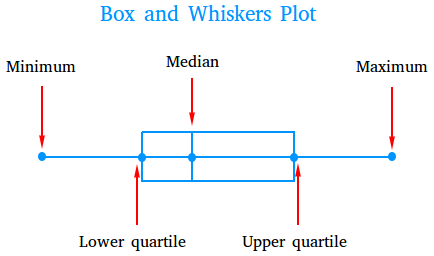
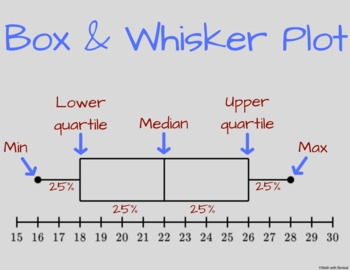
I spent about three weeks last year trying to debug why a client's box plots looked wrong across five different datasets. The math itself is straightforward. The issue was that nobody could agree on which method to use for finding quartiles, and different software packages default to different approaches. That's the real world of Box And Whisker Plot Math before we even get to drawing the thing. You start with your data. Sort it from smallest to largest. Then you find the median, which splits the dataset in half. Everything below the median is the lower half. Everything above is the upper half. The median of the lower half is Q1. The median of the upper half is Q3. The interquartile range, or IQR, is just Q3 minus Q1. That's the core of it. The rest is plumbing.
How To Actually Calculate Whiskers Without Guessing
The whiskers extend to the most extreme data points that are not outliers. The standard rule is anything below Q1 minus 1.5 times the IQR, or above Q3 plus 1.5 times the IQR, gets flagged as a potential outlier. Those outliers are plotted as individual points beyond the whiskers. The whisker itself stops at the last data point within that fence. Here's where it gets tricky in practice. What do you do when your dataset has an odd number of values and the median falls on an actual data point? Some textbooks tell you to include that middle point in both halves. Others tell you to exclude it. The difference is small with large datasets, but with something like n equals 11, it shifts your Q1 and Q3 by one or two values and changes your IQR enough to move the outlier fences. I stopped caring about which approach was "correct" and just made sure I documented which method I was using. Consistency matters more than purity here. Let me walk through a quick example. Say your sorted data is 4, 6, 7, 8, 9, 11, 12, 13, 14, 15, 22. The median is 9. The lower half is 4, 6, 7, 8, and the upper half is 11, 12, 13, 14, 15, 22. Q1 is 6. Q3 is 14. The IQR is 8. Lower fence is 6 minus 12, which is negative 6. Upper fence is 14 plus 12, which is 26. No outliers in this set. The whiskers go from 4 to 22.
Now change that last value to 42. Upper fence stays at 26. The 42 is now an outlier. The upper whisker stops at 15, the highest value within the fence. You plot 42 separately. That's the whole mechanics of it. I ran into a real problem once where a dataset had so many tied values near the boundaries that the 1.5 times IQR rule classified almost everything as an outlier. We were looking at test scores where half the class scored exactly the passing threshold. The IQR collapsed to nearly zero because Q1 and Q3 were extremely close together, and suddenly 1.5 times that tiny IQR produced fences so narrow they were useless. What I ended up doing was switching to a modified box plot approach and using percentiles at the 5th and 95th instead of the 1.5 IQR rule for that specific case. It gave a much more readable visualization for that skewed distribution.
Get the Full Details

When Box Plots Lie To You
A single box plot hides the shape of the distribution beneath the quartiles. Two datasets can have identical Q1, median, Q3, and IQR values but look completely different. One might be symmetric. The other could be heavily skewed. The box plot shows the same thing either way. If someone sends you a box plot and asks what the distribution looks like, the honest answer is you can't tell from the plot alone. You need the raw data or a histogram to see the actual shape. Another thing people miss is that box plots don't handle very small datasets well. With fewer than about 20 points, the quartile positions become unstable. A single value shift can jump Q1 or Q3 by a large percentage of the range. I usually tell people not to bother with box plots for sample sizes under 20. Just show a dot plot or list the statistics. The visual gain isn't worth the false precision. There's also the assumption problem. The 1.5 times IQR outlier rule was designed as a general purpose heuristic, not a statistical test. It works reasonably well for roughly symmetric data. For heavily skewed data, it flags too many points. For uniform data, it flags too few. There isn't a universally correct multiplier. Tukey settled on 1.5 because it produced about the right number of outliers for normal data, but real data is rarely normal. If you're working with skewed distributions regularly, consider using a logarithmic scale on the axis instead of chasing a different multiplier. It solves the underlying problem rather than the symptom.
For anyone who needs a quick reference or wants to generate these plots without building the calculations from scratch, there are free tools like Desmos or GeoGebra that have built-in box plot generators. You just paste your data and it handles the quartile calculation using whichever method the tool defaults to. Read the documentation to know which one. Excel also does it now if you go to Insert Chart and pick Box and Whisker. It uses the exclusive method for quartiles by default, which excludes the median from both halves when the dataset is odd. That's worth knowing because it differs from what some statistics textbooks teach. The takeaway is that the math behind Box And Whisker Plot Math is simple arithmetic, but the decisions around quartile calculation methods, outlier rules, and dataset size requirements are where the actual work happens. Pick your method, document it, and don't trust a single box plot to tell you the whole story about your data.