Box and Whisker Plots: What They Actually Show and How to Not Mess Them Up
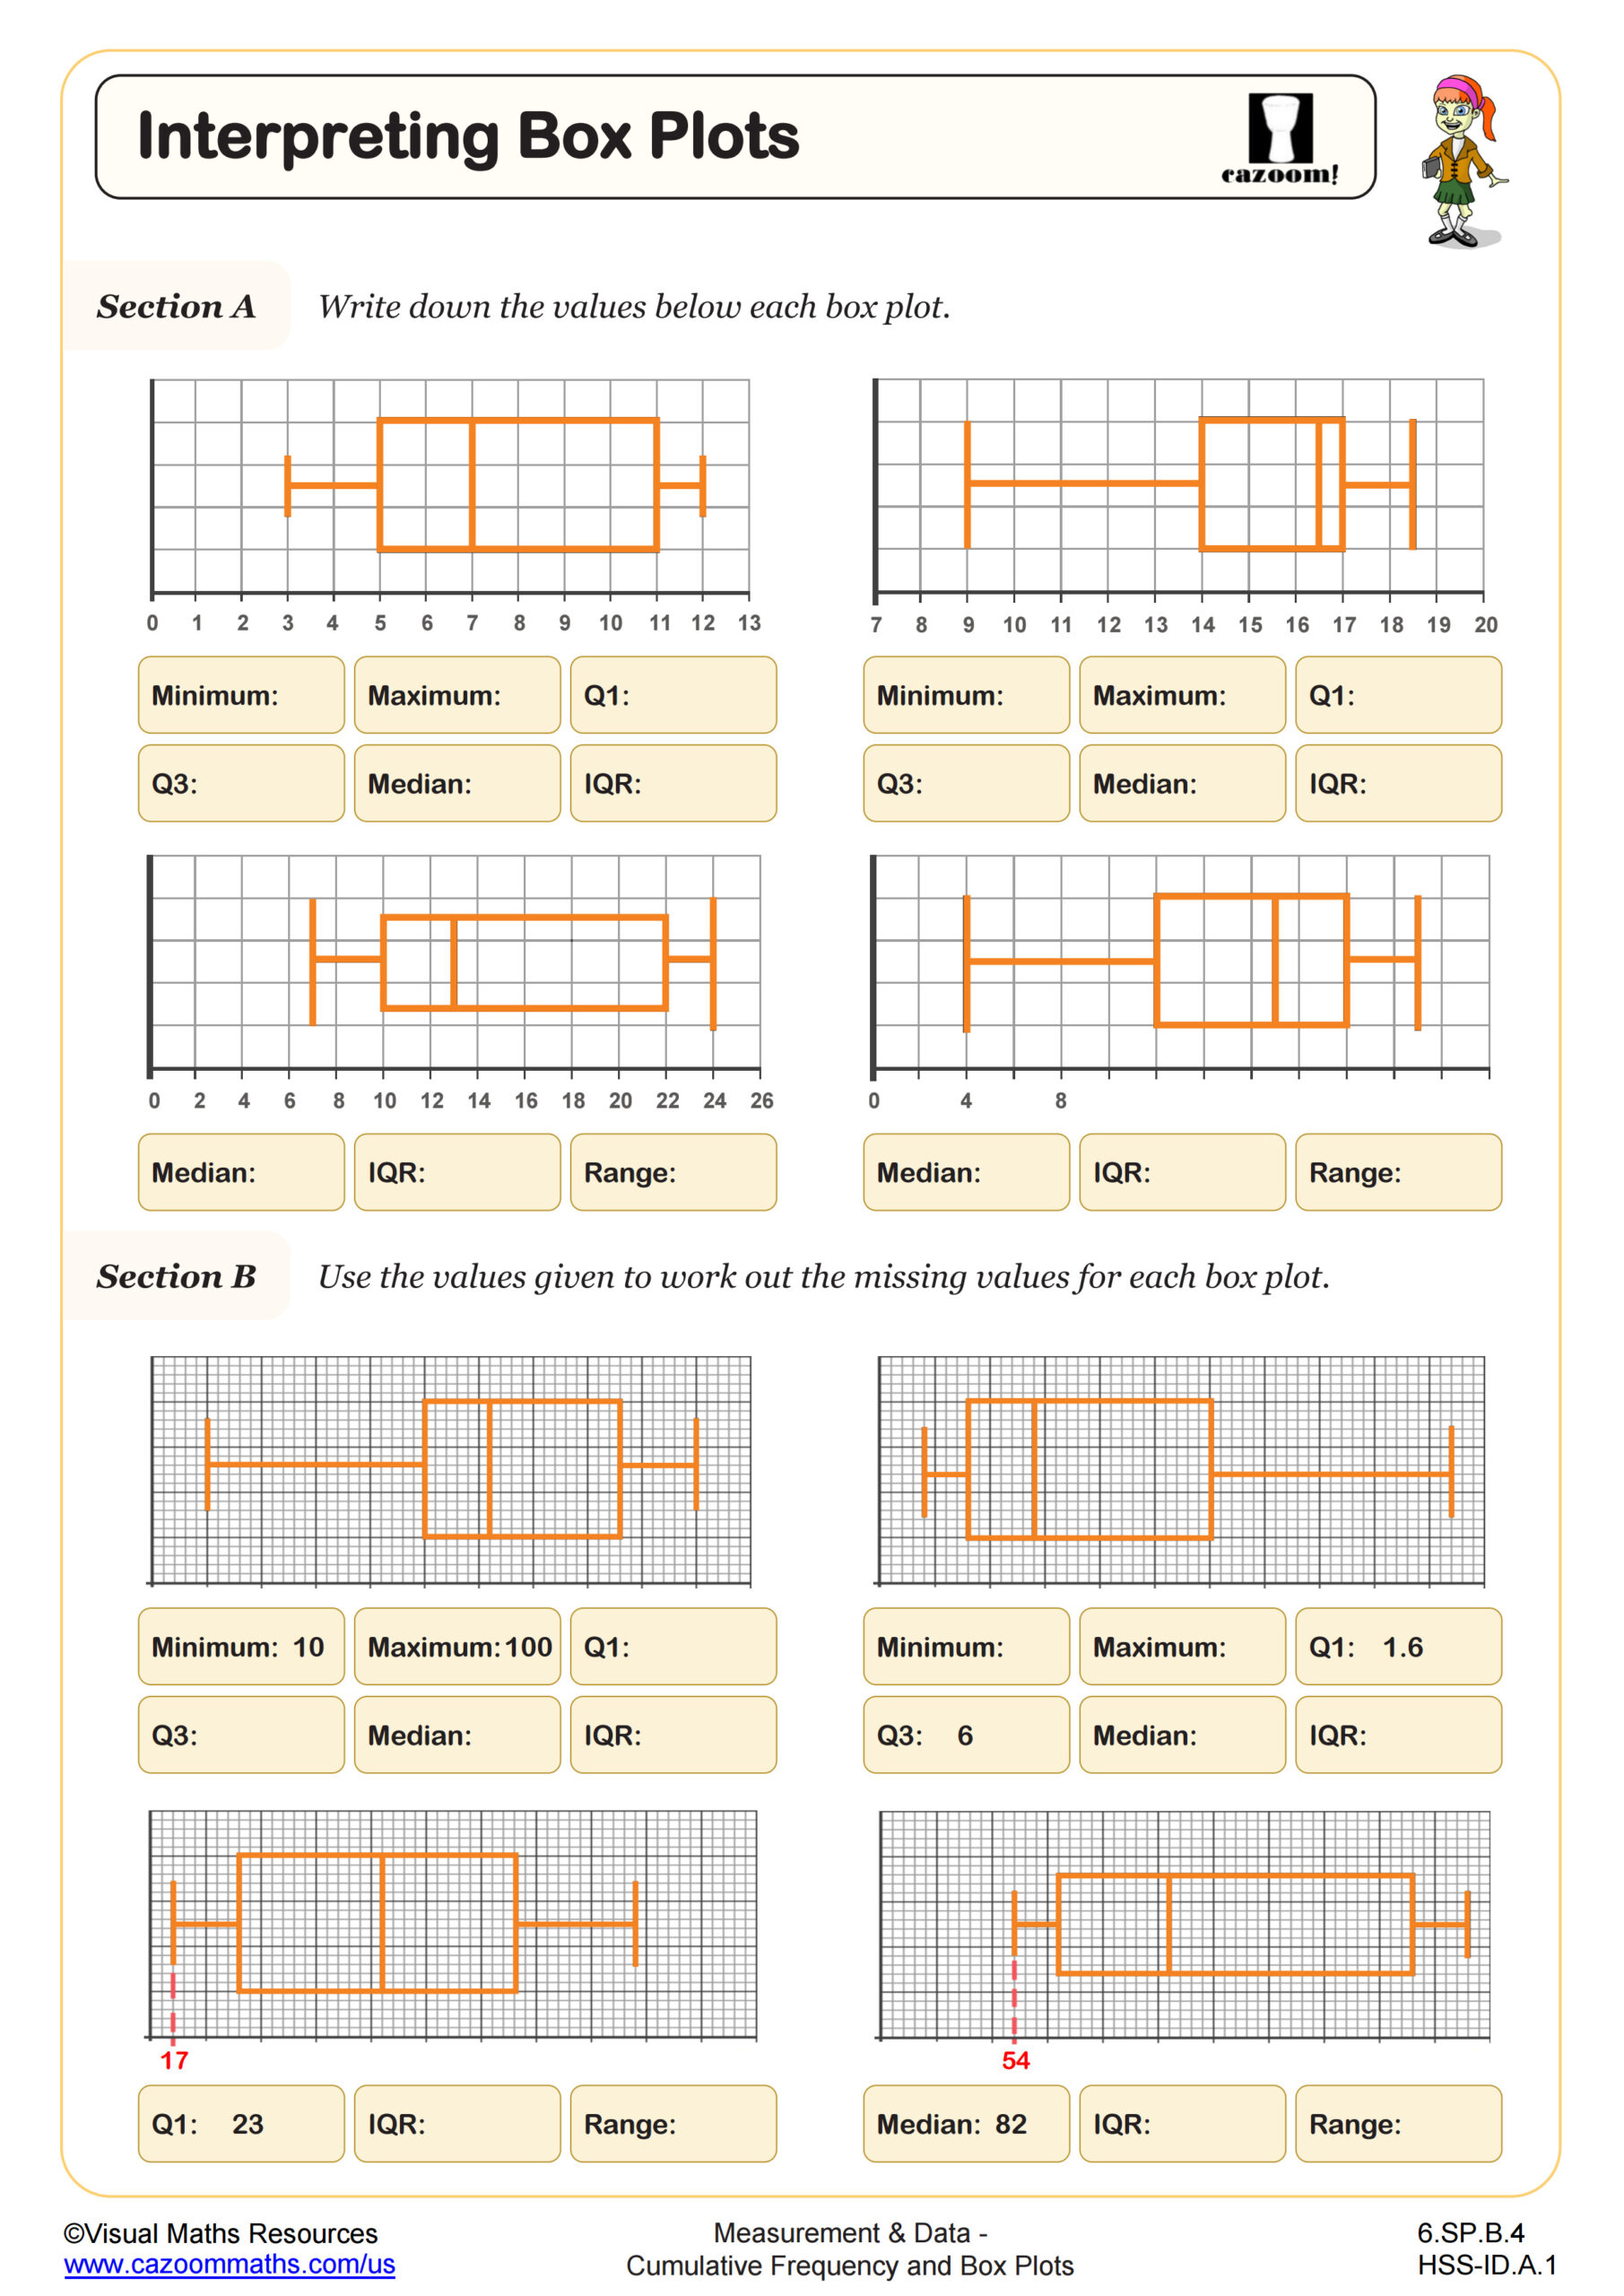
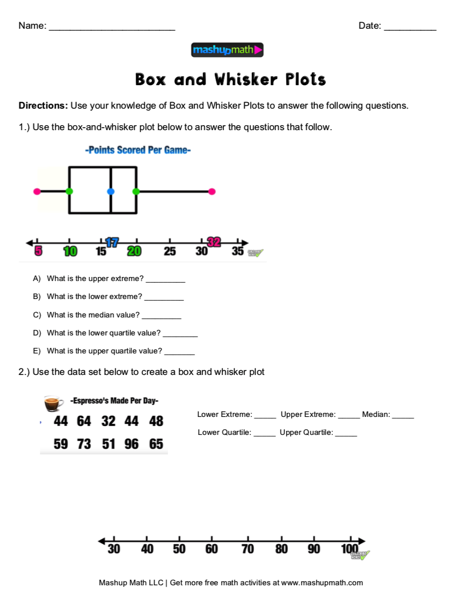
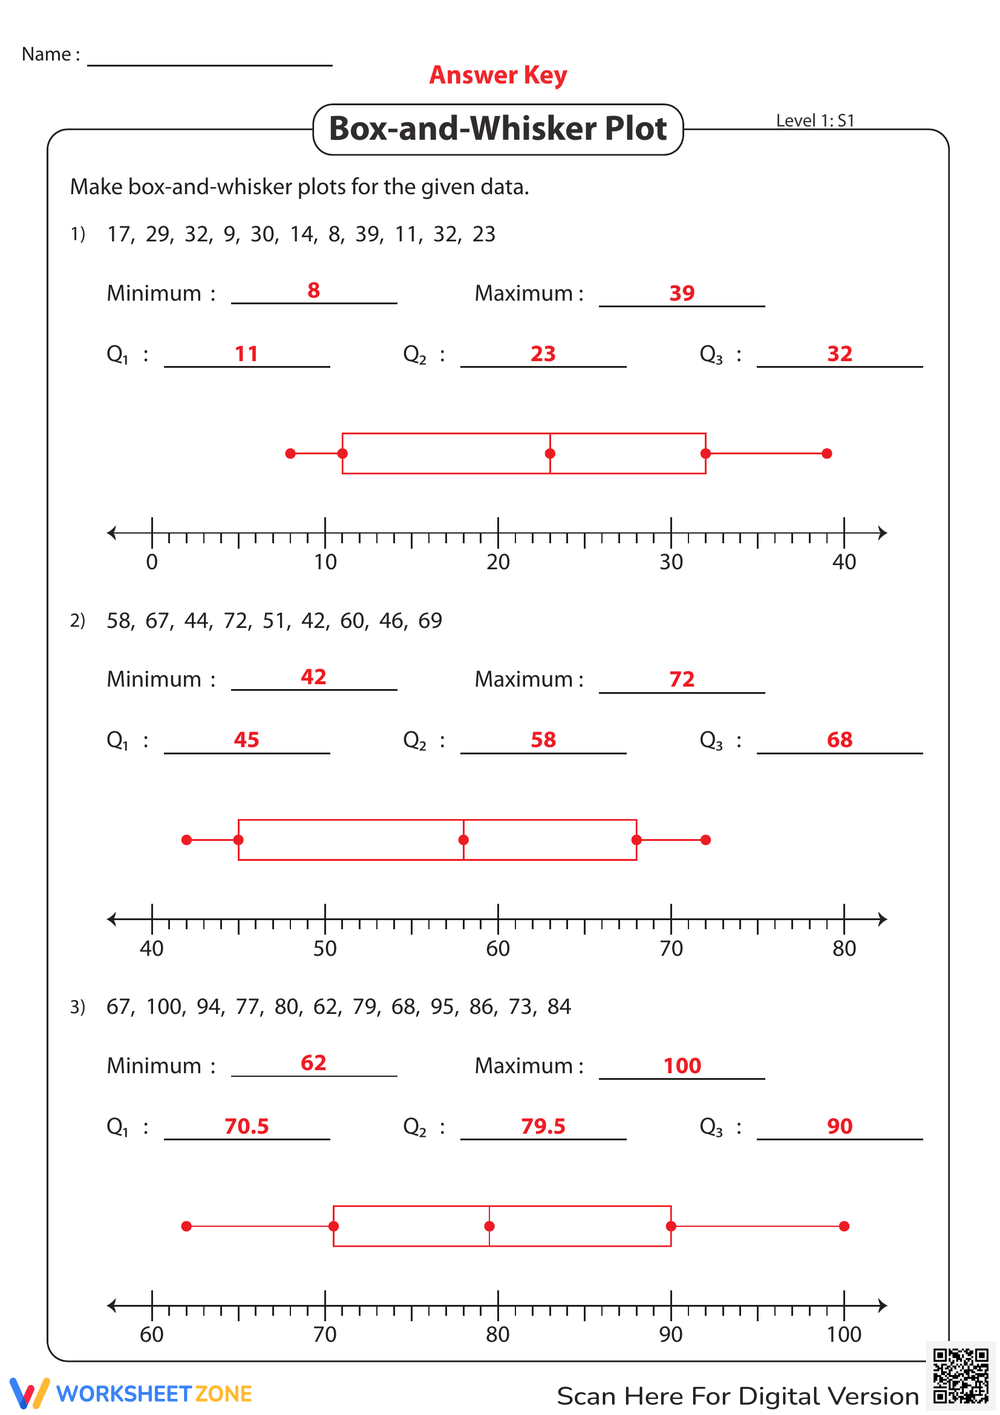
I spend most of my time working with messy operational data — sensor readings, support ticket volumes, supply chain delays. That means I build box plots constantly. They're one of those things that look simple and then immediately lie to you if you don't pay attention. A box and whisker plot (I keep seeing people call them boxplots, box-and-whisker diagrams, whatever) shows five summary statistics: the minimum, first quartile (Q1), median, third quartile (Q3), and maximum. The box itself runs from Q1 to Q3. The line inside the box is the median. The whiskers extend to the furthest data point within 1.5 times the interquartile range (IQR) from each quartile. Points outside that range get plotted individually as outliers. The IQR approach for defining outliers is standard but arbitrary. Tukey chose 1.5 because it worked well across many real datasets. It's not a law of nature. If you're dealing with data that naturally has a heavier tail than a normal distribution — and most operational data does — you will get a lot of points flagged as outliers that aren't actually errors. This is one of the first things I learned the hard way.
Common Box And Whisker Questions That Come Up
People ask me about these pretty regularly when they're trying to make sense of their first box plot. Here's what actually matters. How do you calculate Q1 and Q3? There are different methods and this trips people up. Excel's QUARTILE.EXC and QUARTILE.INC give different answers for the same dataset. R has seven different methods documented in its ?quantile help page. Python's numpy and pandas default to a specific interpolation method. If you're comparing box plots generated by different tools, they might not match even though the underlying data is identical. Always check which method your tool uses. What does the whisker length actually mean? It's not just min to max. The whisker ends at the most extreme value that is still within 1.5*IQR of the quartile. Everything beyond that becomes an outlier point. This means a short box with long whiskers and no outliers tells you something very different than a long box with lots of outlier points, even if the overall range is similar.
Why does my box look squished? Usually because your data is heavily skewed or you have a small sample size. With fewer than 20 data points, quartile estimation becomes unreliable and the plot can look misleading. I stopped making box plots for anything under 30 observations and just use a strip plot or a table of raw statistics instead. Here's a concrete example from something I dealt with recently. We were tracking incident resolution times across three support tiers. The box plots looked fine at first glance — tier 3 had a smaller median and tighter IQR, which suggested it was performing better. But when I dug into the outlier points, I found that tier 3 was quietly pushing difficult cases to tier 2 without documenting the handoff. The box plot alone wouldn't have shown that. The distribution shapes and outlier patterns were the clue. I ended up cross-referencing the outlier timestamps with our ticket routing logs to find the gap. A box plot got us to the right question but didn't answer it. This is the limitation most people miss: box plots summarize. They throw away information about the shape within each quartile. Two datasets can produce identical box plots and be completely different distributions. I once spent three weeks chasing an anomaly that turned out to be two perfectly valid but very different operational modes that happened to share the same quartile boundaries. A histogram or a kernel density estimate would have shown this immediately.
Get the Full Details

How should you handle tied values at the quartile boundaries? When your data has a lot of repeated values — which happens constantly with integer-scaled metrics — the quartile calculation can produce the same value for Q1 and the median, or the median and Q3. This makes the box look collapsed. In practice, I've found that adding a tiny amount of random noise (jitter) to break ties helps visually, but a better approach is just to supplement the box plot with a frequency table or a beeswarm plot alongside it so you can see where all those tied values actually sit. If you want to build these yourself rather than relying on whatever your BI tool spits out by default, the math is straightforward enough to implement in a spreadsheet or a short Python script. You need the sorted dataset, calculate the positions for Q1, median, and Q3 using your chosen interpolation method, compute the IQR, set the whisker boundaries at Q1 minus 1.5*IQR and Q3 plus 1.5*IQR, then flag everything outside those boundaries. Most people end up using seaborn or matplotlib in Python because writing the outlier detection and jitter logic from scratch isn't worth the five minutes you'd save. For quick comparison across many groups, box plots remain useful. Just remember what they're hiding. The box shows you where the middle 50% of your data lives. It doesn't tell you if that middle 50% is uniformly distributed or clustered at one end. It doesn't show multimodality. And it absolutely does not replace looking at the raw data when something looks off.