What the hell is a B-tree and why does everyone in the database world pretend it's obvious?
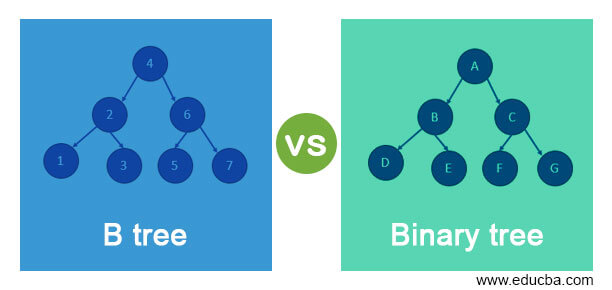
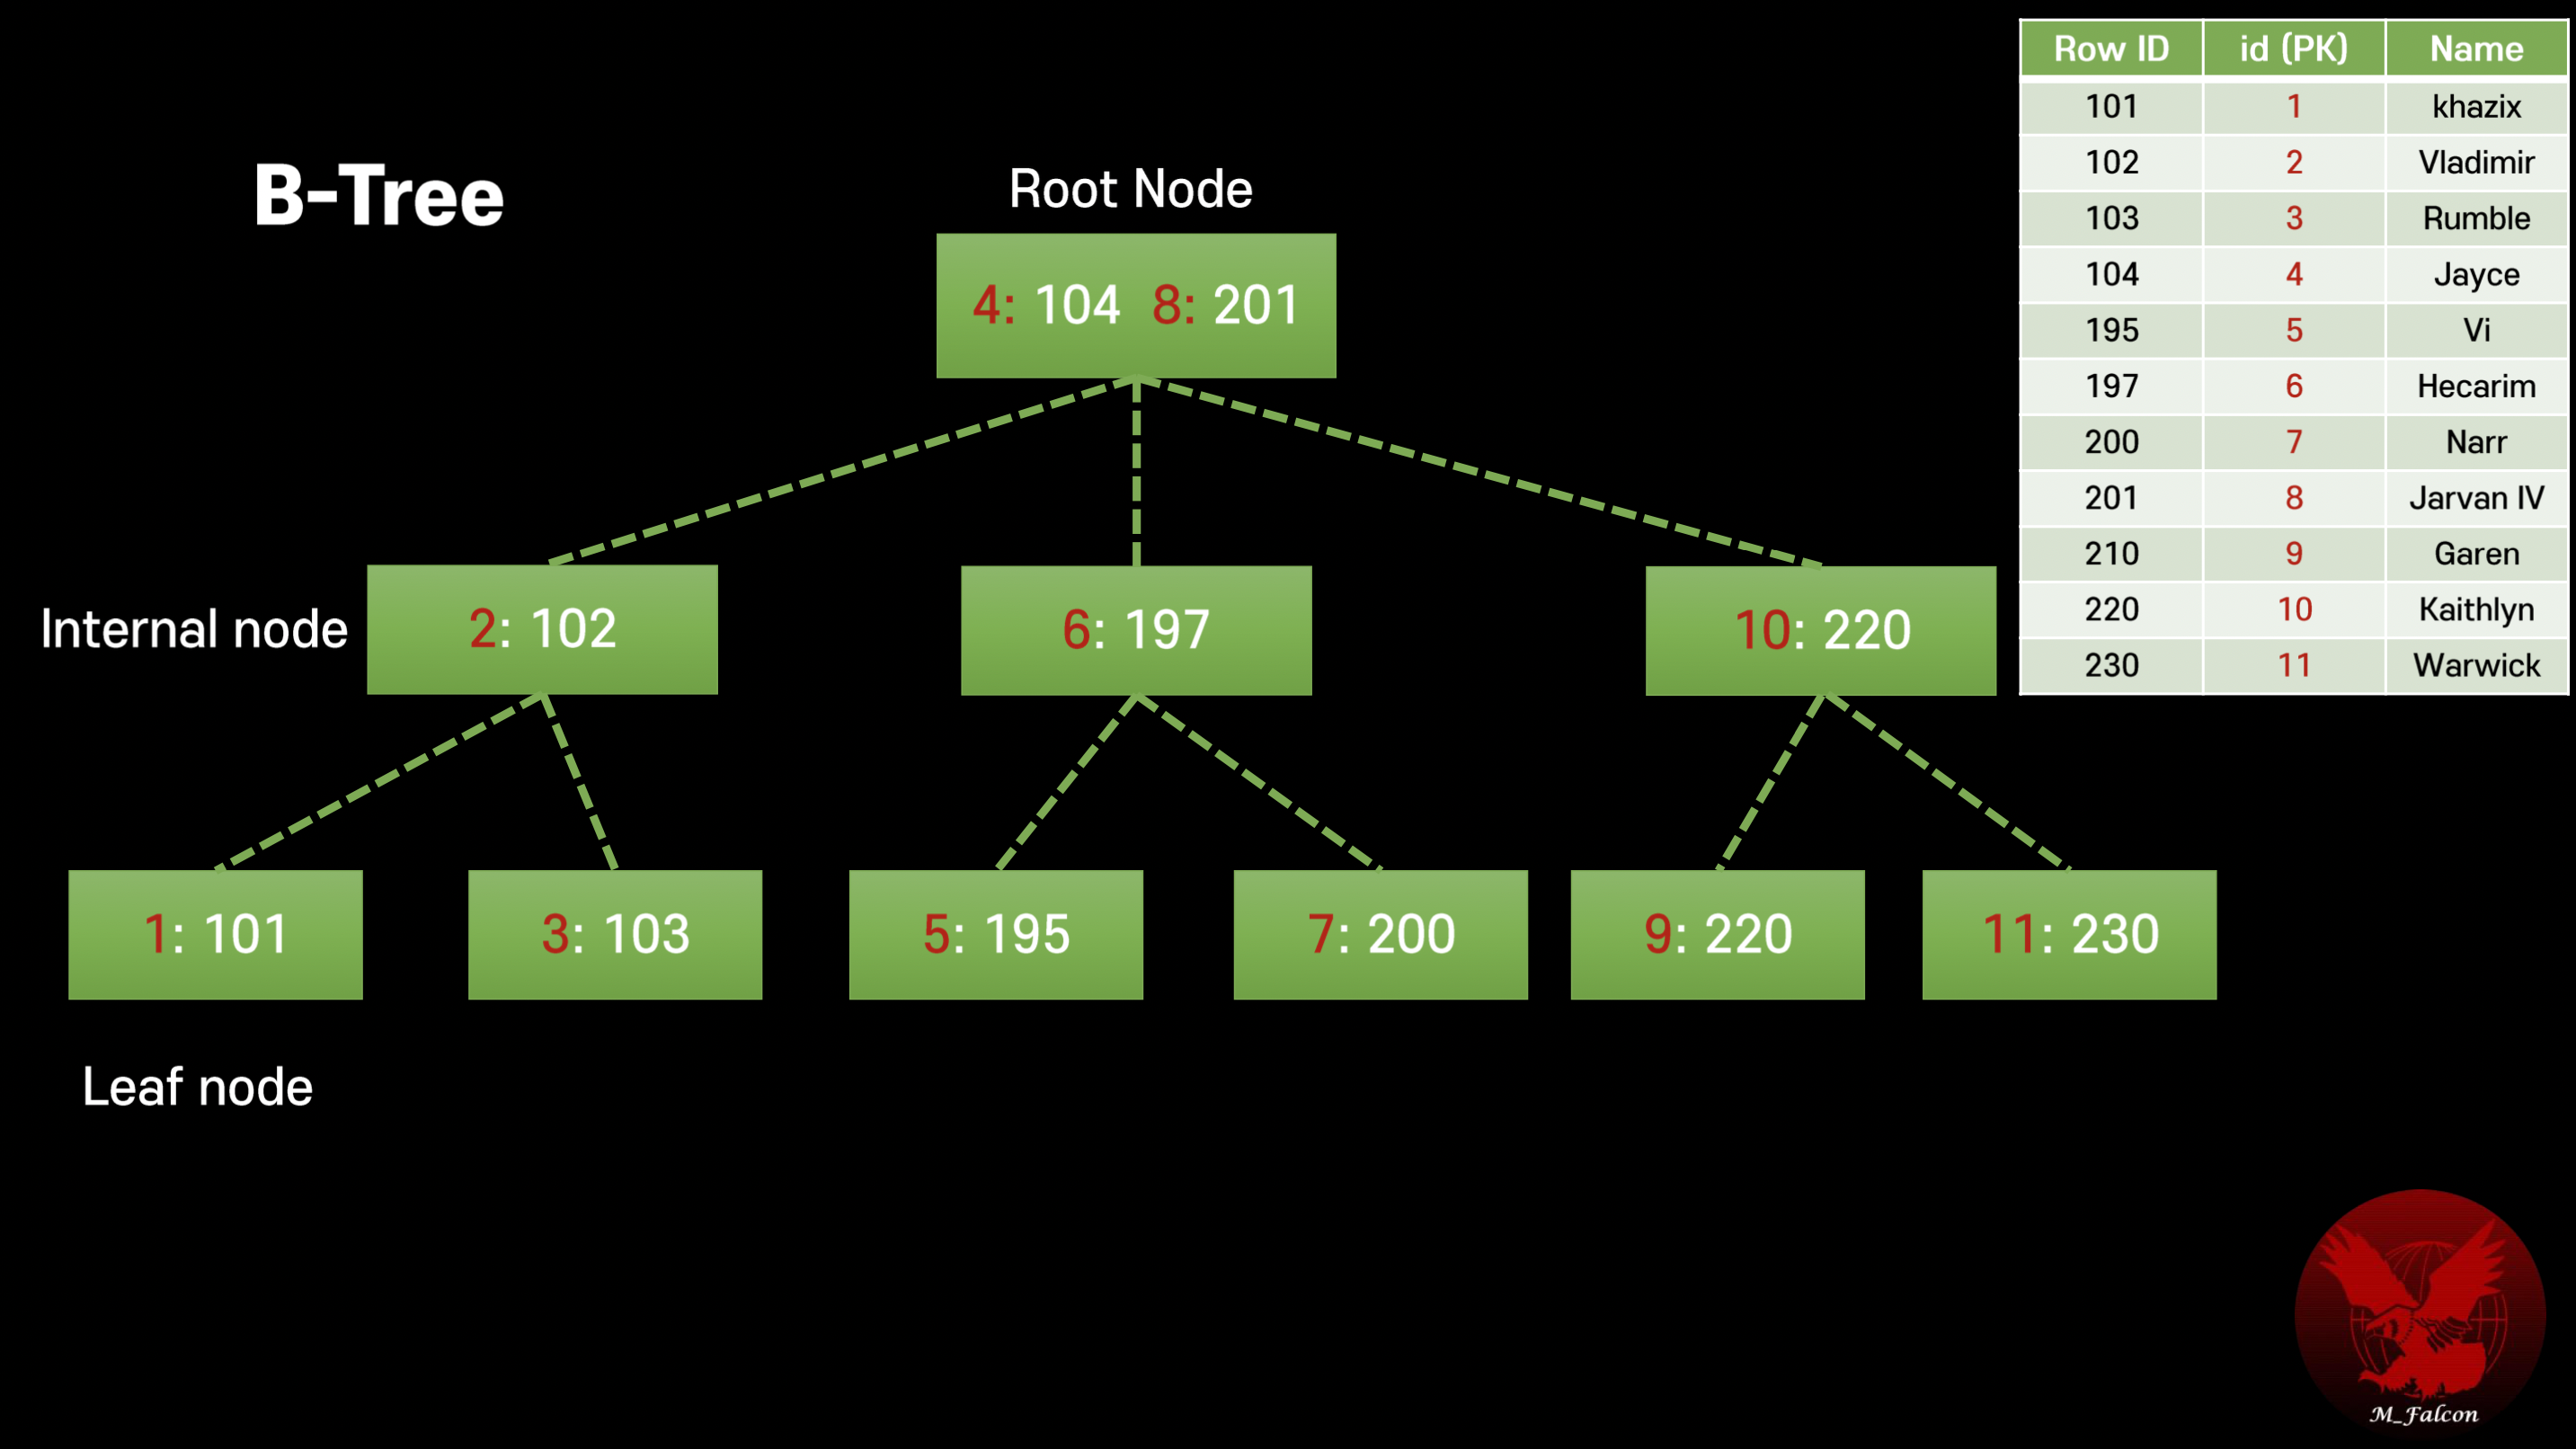
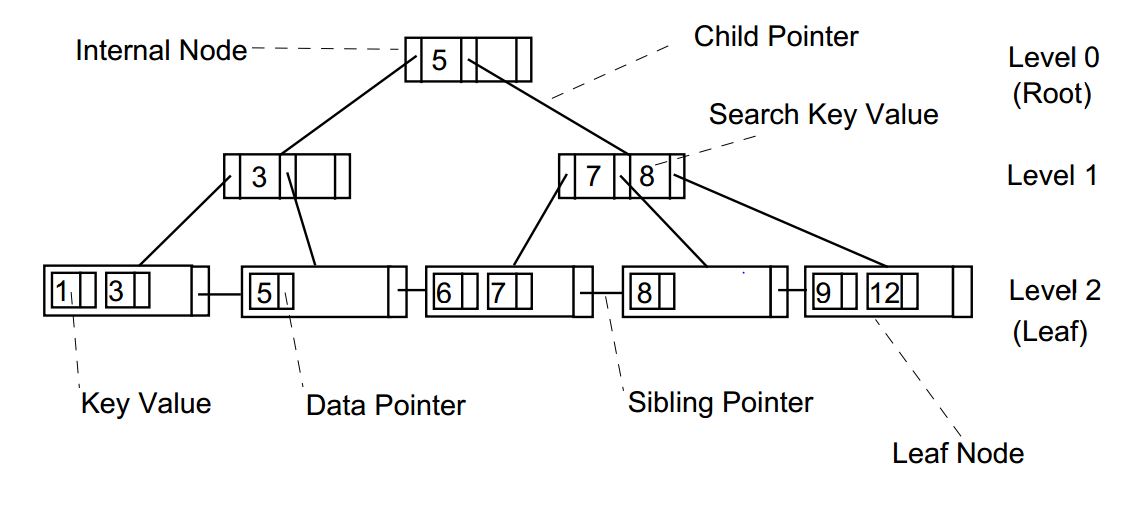
A B-tree is a self-balancing search tree designed for systems where data lives on disk rather than in RAM. That distinction matters more than most tutorials admit. When you're working with main memory, a binary search tree is fine because every node fits comfortably in cache. When you're dealing with disks, every read is an expensive operation, so the whole point of a B-tree is to minimize disk accesses by keeping the tree shallow and wide. Each node can hold dozens or hundreds of keys, which means fewer levels and fewer trips to the storage layer. The structure works like this. You have a root node, intermediate nodes, and leaf nodes. Every node contains sorted keys and pointers to child nodes. When you search for a value, you start at the root, compare the key against the entries, follow the appropriate pointer, and repeat until you reach a leaf. The tree maintains balance automatically through insertion and deletion algorithms that split and merge nodes as needed. A typical B-tree of order m allows each node to contain between ceiling(m/2) and m children, except for the root which can have as few as two.
Btree And B Tree: The practical reality of using them
I spent about three weeks debugging a query performance issue on a legacy inventory system where the B-tree index was actively making things slower instead of faster. The table had roughly 40 million rows, and the index was being built on a column with extremely low cardinality — something like a status flag with only four possible values. The query planner was choosing the B-tree index over a full sequential scan because it had stale statistics, and each lookup through the index required four to five times more I/O than just reading the table linearly. The workaround was running ANALYZE to refresh the statistics, but the deeper lesson was understanding that B-trees don't help when the selectivity is too low. An index is only useful when it can narrow down the result set significantly. Another thing nobody warns you about: B-tree insertions can trigger cascading splits that temporarily double the storage footprint of your index. When a node fills up past its capacity, it splits into two nodes, and if the parent node also fills up from the split, it splits too, propagating upward. In my experience with a high-throughput logging system, we saw B-tree index growth spike by approximately 60 to 80 percent above the final stable size during bulk insert periods before stabilization kicked in. The fix was batching inserts in controlled chunks of around 10,000 rows with periodic checkpointing rather than streaming them in continuously. Here's a counter-intuitive point about B-trees that most people get wrong. People assume that because B-trees are balanced, every search takes the same amount of time. That's technically true in terms of comparison count, but it ignores the reality of how modern storage works. A B-tree node that fits entirely within a single disk page will be read in one I/O operation. But if your node size is poorly chosen and spans across page boundaries due to fragmentation, you can end up with multiple I/Os for what should be a single logical read. Tuning your fill factor and node size to match your underlying storage's page size — usually 4KB or 8KB depending on the system — makes a measurable difference in large-scale deployments. I've seen query latency drop from around 200 milliseconds to under 40 milliseconds on a read-heavy analytics workload simply by adjusting the fill factor from the default 70 percent to 90 percent and aligning the node sizes to the filesystem block size.
When B-trees completely fail you
There are scenarios where reaching for a B-tree is the wrong call and you should consider alternatives instead. Write-heavy workloads with massive append operations tend to suffer because every write may trigger a node split and redistribution. Systems designed for this kind of load often use LSM-trees (Log-Structured Merge trees) instead, which batch writes into sorted runs and merge them periodically. Cassandra and RocksDB use this approach and handle write throughput that would make a B-tree implementation groan. Hash indexes are another alternative worth knowing about when your access pattern is primarily equality lookups rather than range queries. A B-tree excels at range scans because the keys are sorted, but if you're only doing point lookups with = operators, a hash index can be significantly faster since it gives you O(1) average-case lookups compared to the O(log n) of a B-tree. PostgreSQL supports hash indexes, though they don't support ORDER BY or unique constraints the way B-tree indexes do, which is why B-tree remains the default in most database engines. Space efficiency is another genuine limitation. B-trees consume noticeably more memory than the actual data they index because every key is duplicated in both the internal nodes and the leaf nodes. In a typical implementation, you're looking at roughly 30 to 50 percent overhead relative to the indexed data size. For datasets measured in hundreds of gigabytes or more, that overhead becomes a real budget item that affects your hardware planning.
Get the Full Details
Implementation and resources
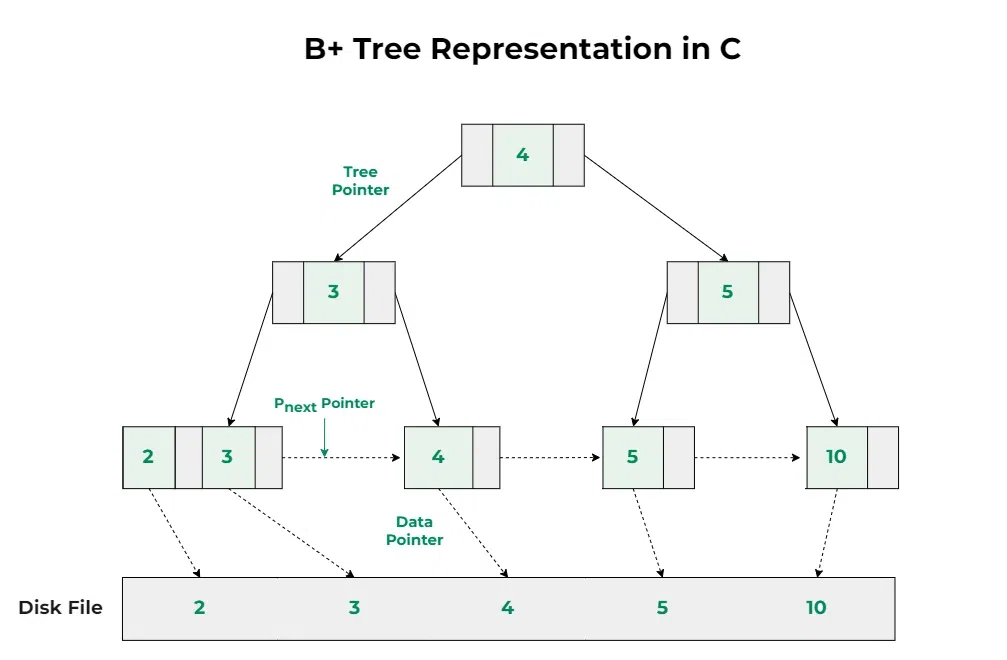
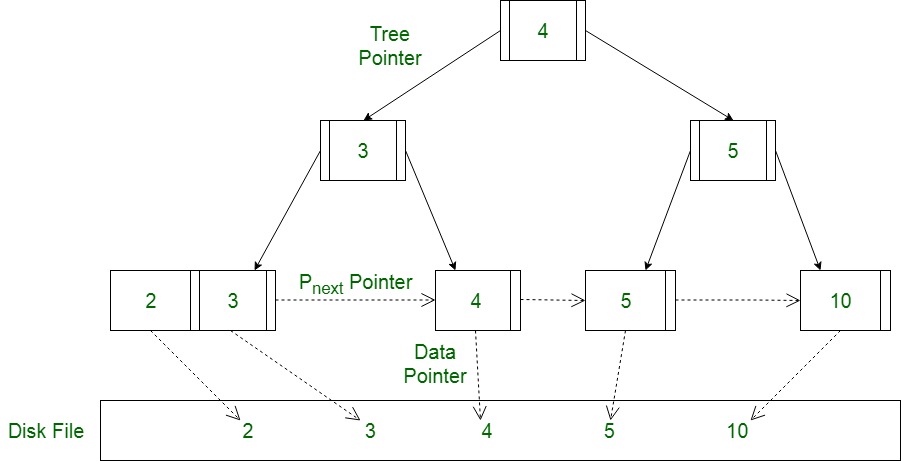
If you want to study a clean reference implementation rather than reading the CLRS textbook proofs, the PostgreSQL source code has one of the most battle-tested B-tree implementations available. The core logic lives in src/backend/access/nbtree/, and the code comments actually explain the reasoning behind design decisions, which is rare for production database code. For a lighter educational implementation, there's a solid Python version available at github.com/gaogaotiantian/bintrees that supports B-tree, BPlusTree, and other variants with a clean API. The GNU coreutils project also includes a basic B-tree library in lib/fstree that handles filesystem-level indexing, though it's more of a general-purpose toolkit than a focused data structure library. If you're building something from scratch for learning purposes, start with a B-plus-tree variant rather than a pure B-tree. The separation of data storage to leaf nodes only simplifies range queries considerably and is the design choice used by almost every production database system including SQLite, MySQL InnoDB, and PostgreSQL. One final note on maintenance: B-tree indexes degrade over time with heavy update and delete activity. Dead entries accumulate in nodes that get split and merged, and the tree becomes less efficient at occupying the originally allocated space. Most database systems handle this through autovacuum processes, but if you're working with a system that doesn't auto-maintain its indexes, you should expect to run reindex operations on a schedule that matches your write volume. In practice, that means anywhere from monthly for low-traffic tables to weekly for high-churn systems, and a full reindex of a large table can take several hours depending on the dataset size and available I/O throughput.