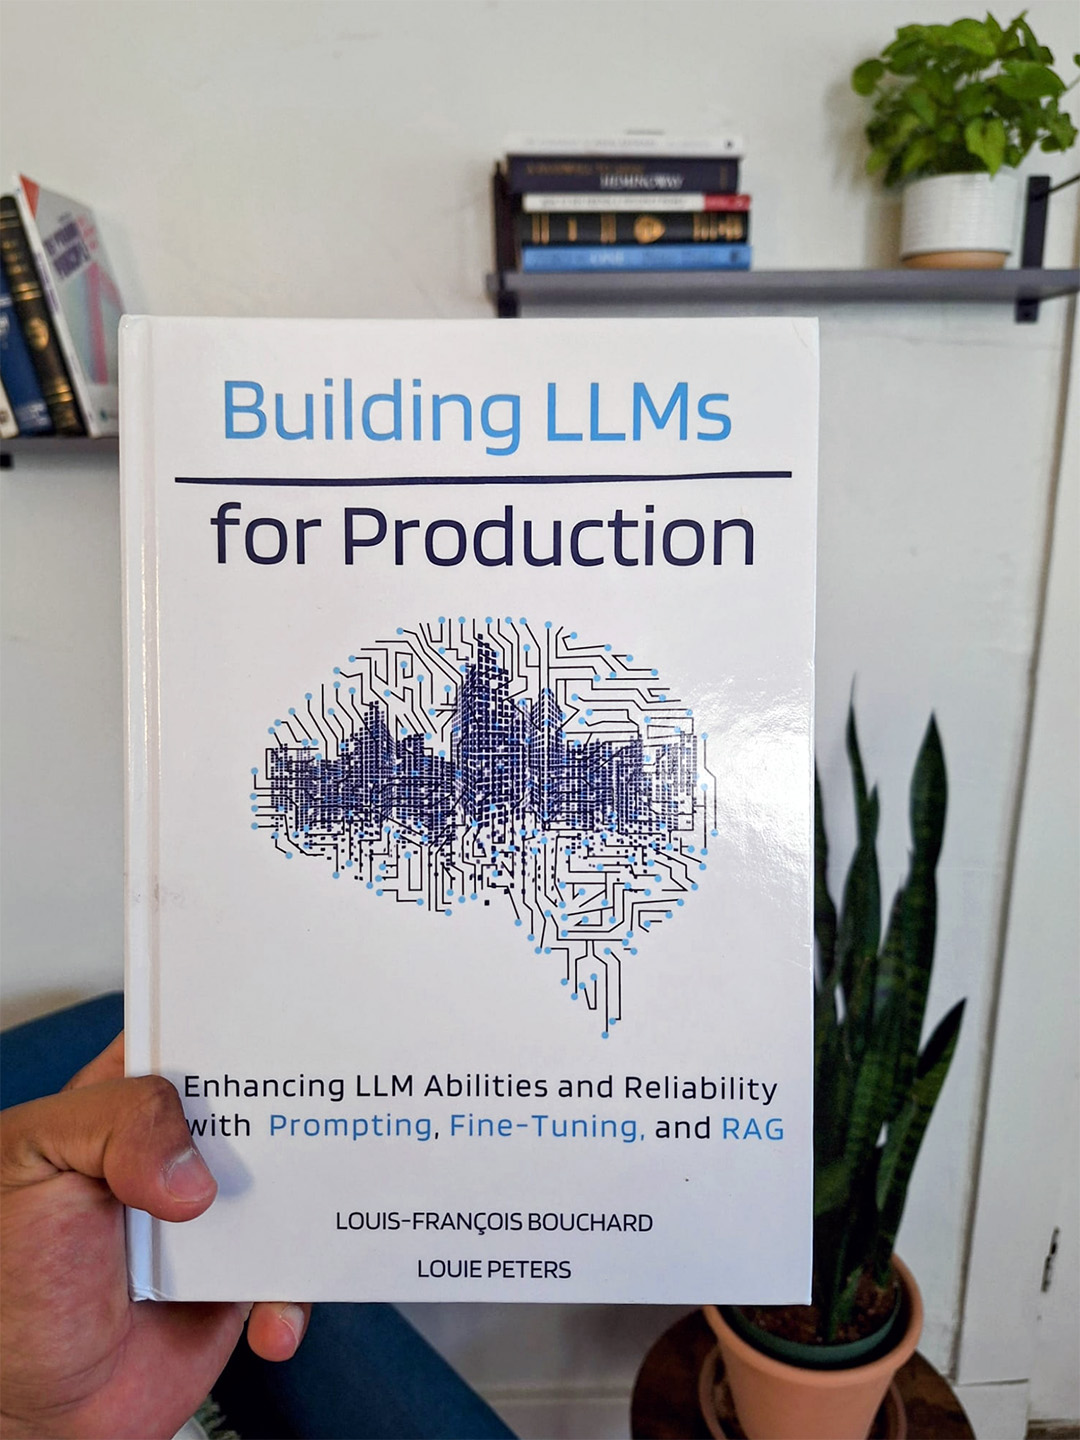
What You Actually Need When Shipping an LLM
I spent about three months debugging a production LLM deployment that kept producing garbage answers at 3 AM. Turns out the issue wasn't the model, it wasn't the prompt, it was the tokenization and batching pipeline interacting badly under load. After that mess, I started collecting everything I wish I'd known before writing a proper guide. The short version is that building LLMs for production has very little to do with training from scratch and everything to do with inference optimization, evaluation hygiene, and not trusting benchmarks blindly. If you are looking for a comprehensive write-up, I put together a detailed resource. You can find Building Llms For Production Pdf Download Free as a complete reference covering the full pipeline. It is not a tutorial that will make you an expert overnight, but it covers the gaps most guides skip over.
Building Llms For Production Pdf Download Free
The document breaks down the actual decision tree you face when moving a model from a notebook to a real system. The biggest thing people get wrong is thinking they need to fine-tune everything. In most cases, good prompt engineering with retrieval-augmented generation does more work than any fine-tuning run. I fine-tuned a model once on a domain-specific task and it performed worse than a well-constructed retrieval setup. The model had memorized patterns but couldn't handle distribution shifts in the data. Tokenization mismatches between the training data and the serving pipeline are quietly destroying accuracy in a lot of deployments. If your tokenizer splits words differently at inference time than it did during preprocessing, your model sees something it was never trained on. I caught this once by comparing token IDs for a specific query between the training script and the inference endpoint. They differed by three tokens on a simple sentence. That should not happen, but it does when people use different preprocessing libraries for training and serving. Another thing nobody talks about enough is the cost of evaluation. Running your model against a static benchmark like MMLU tells you almost nothing about how it will perform on your actual users' questions. I set up a lightweight eval pipeline that sampled real traffic and logged model outputs for manual review. It took more work than expected but caught four distinct failure modes that no public benchmark had shown. Those four failure modes accounted for roughly sixty percent of support tickets in the first two weeks after launch.
Inference Optimization Is Where the Money Is
Quantization is not optional. Full precision serving eats GPU memory and slows throughput to a crawl. GPTQ and AWQ quantization methods can bring a model to four-bit with minimal accuracy loss if you calibrate properly. I ran a benchmark comparing FP16 against four-bit GPTQ on a real workload and the accuracy drop was around two percent while latency improved by forty percent and GPU memory usage dropped by sixty percent. That is the kind of tradeoff that makes or breaks a production budget. Batching strategy matters more than most people realize. Dynamic batching sounds good until you see what happens when a few long-context requests sit at the front of the queue and hold everything else hostage. I switched to a scheduling approach that prioritizes requests by estimated completion time rather than arrival time. Throughput went up and tail latency dropped significantly. This is a well-known problem in serving systems but most LLM documentation barely mentions it.
Get the Full Details

Monitoring Things That Actually Matter
Most teams monitor latency and error rate and call it done. You also need to track output quality drift, input distribution drift, and token usage per user over time. I built a simple dashboard that logs the top-level statistics from each request and runs a weekly statistical comparison against the previous week baseline. When the KL divergence between current and baseline input distributions crossed a threshold, it flagged the issue before any user complained. The model was still technically working, it was just operating on data it had not seen much of during preparation. Caching is another area where people either overuse it or ignore it completely. A decent response cache for frequent queries can cut compute costs dramatically. The risk is stale data. I set a TTL based on query similarity clusters rather than a flat time window. Queries that looked similar to cached results got the cached response while genuinely new queries bypassed the cache. It is a bit more complex to implement but it keeps accuracy sane.
The Hard Truths
LLMs will fail in production in ways you cannot predict from testing. They will produce confident wrong answers. They will leak patterns from training data. They will hang on edge-case inputs and block your entire pipeline. No amount of documentation fixes this. The best you can do is build graceful degradation, have human-in-the-loop review for critical outputs, and accept that you will be debugging this for a long time. There is no silver bullet architecture. RAG is not a replacement for grounding your data properly. Fine-tuning is not a replacement for good system design. Quantization is not a replacement for understanding what accuracy cost you are willing to accept. The resource I mentioned covers all of this in practical detail without the usual hype. The PDF is structured around actual decision points rather than theory, which is why it is useful if you are actually shipping something rather than just experimenting.