What Actually Happens When Your Systems Go Down
I spent three years working in IT infrastructure before I realized most people think business continuity is about buying backup servers and hoping for the best. The reality is much drier and involves a lot more spreadsheets than anyone admits upfront. When the power goes out at 2 AM and your disaster recovery plan is a PDF sitting in someone's inbox from 2019, you learn very quickly what the gap looks like between theory and practice. Business continuity is the set of processes that keep a company running when something breaks. It covers everything from power failures and natural disasters to cybersecurity incidents and supply chain disruptions. The core question is simple: what happens next and how long can you survive without it.
Getting Started With Business Continuity For Dummies
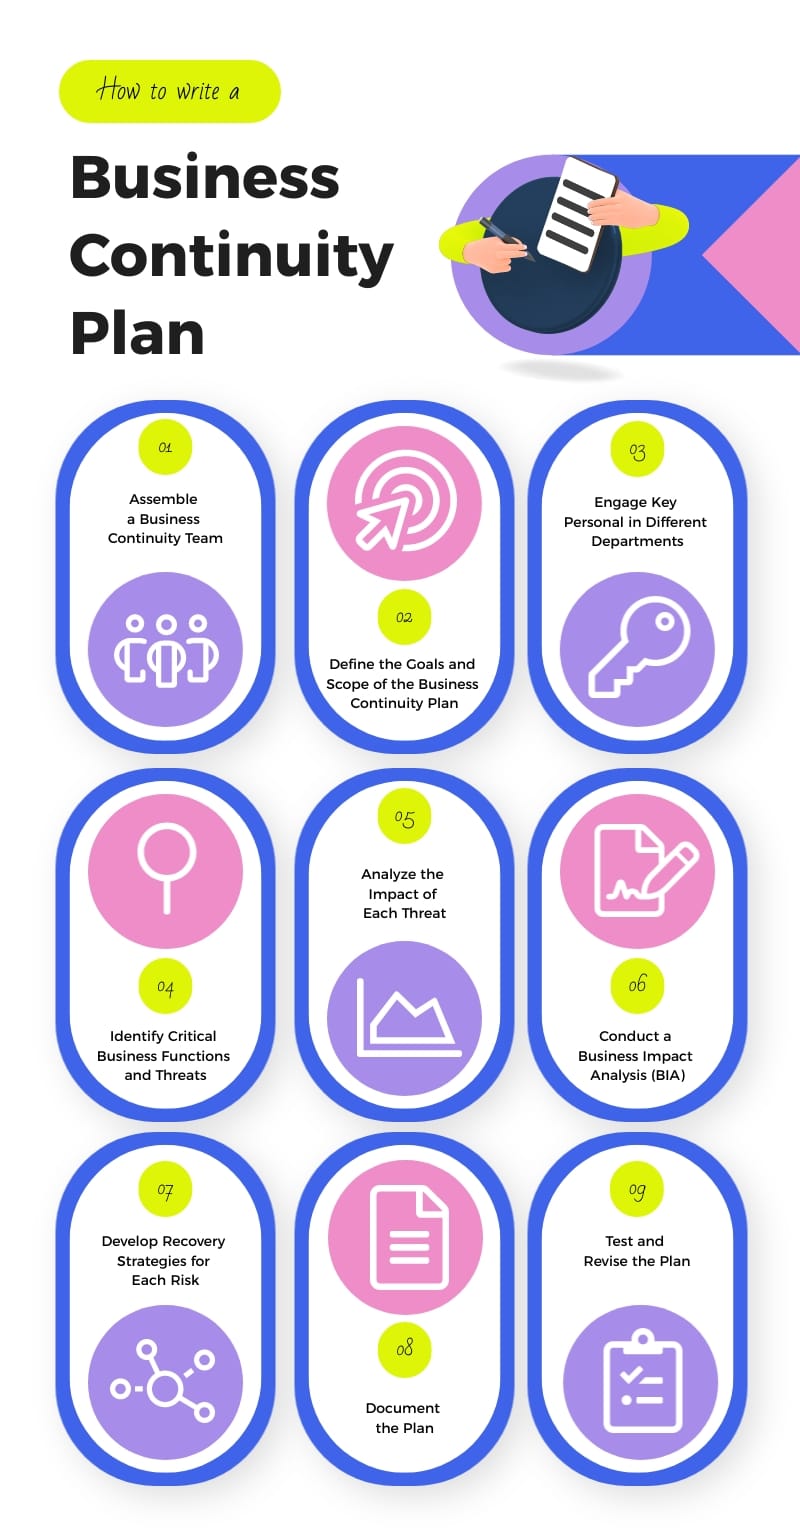
The entry point is a business impact analysis. You map every critical function, rank them by time sensitivity, and identify what breaks first when things go wrong. Most small businesses skip this entirely and jump straight to buying cloud backups, which is like putting a bandage on a broken leg and calling it treatment. Here is what a practical BIA looks like in my experience. I worked with a regional logistics company that thought their email server was their biggest risk. When we actually ran through the exercise, we discovered their payment processing system had zero redundancy and would stop working within four hours of a failure. The fix cost less than their annual email subscription and saved them from losing three million dollars in a single incident. The process takes about two weeks for a small business. You interview department heads, document critical workflows, calculate recovery time objectives, and identify single points of failure. The output is a living document that tells you exactly what to prioritize when things break.
The Counter-Intuitive Things Nobody Teaches
Most continuity guides tell you to build redundant systems for everything. That approach fails because redundancy creates complexity and complexity creates new failure modes. I learned this after a client spent forty thousand dollars on redundant servers that never got tested and became the very thing that caused their longest outage in 2021. The workaround is simpler and costs far less. You focus on the top five critical functions, build manual workarounds for each, and test them quarterly. Manual workarounds are processes that do not require technology. A restaurant can take cash orders on paper during a POS failure. A clinic can schedule patients using whiteboards when their system goes down. These workarounds buy you time while the technical team fixes the real problem. Another common pitfall is treating your disaster recovery plan as a document to write and forget. Plans decay. People leave. Systems change. The plan you wrote last year probably references software versions that no longer exist and contact names that nobody checks anymore. I recommend a quarterly review process that takes about thirty minutes per session and keeps the plan functional without requiring a full rewrite.
Get the Full Details
Building the Manual Workaround System
The core of any continuity plan is the manual workaround. This is what happens when technology fails completely and you need to keep operating without it. A retail store might use handwritten receipts during a network outage. A warehouse might use clipboards instead of their scanning system. These workarounds are ugly and slow but they keep revenue flowing while the technical team works on the real fix. I built a manual workaround system for a manufacturing client that reduced their downtime from an average of eight hours to about ninety minutes during the first year. The key was not buying better technology but creating checklists that anyone could follow without technical training. Each checklist took about five minutes to read and covered the top ten actions needed during a specific failure scenario. The process starts by identifying your critical functions. Rank them by revenue impact, calculate how long you can survive without each one, and build a manual workaround for the top five. The workarounds should not require technology, be testable in under an hour, and be documented in plain language that anyone can follow.
Testing Without the Theater
Most companies test their continuity plans by running a table-top exercise where everyone sits in a conference room and pretends something broke. This approach fails because it does not reveal the gaps that matter when something actually goes wrong. I learned this after a client passed three consecutive table-top tests and then failed completely during their first real outage in 2022. The workaround is to run unannounced tests once per quarter. Pick a random critical function, declare a failure without warning, and watch how the team responds. The test takes about two hours and reveals exactly where the gaps are without requiring a full-scale simulation. Most teams discover within the first ten minutes that their contact lists are outdated and their workarounds do not exist. I recommend starting with a food chain test that takes about two hours per quarter. Pick a random critical function, declare a failure without warning, and measure how long it takes the team to activate their manual workaround. The metric that matters is not whether the test succeeds but how long it takes to discover the gaps that would cost you the most during a real incident.
When Business Continuity Fails Completely
No continuity plan works in every scenario. Some failure modes are so large and so unpredictable that they break every assumption you built your plan on. The 2011 Japan earthquake and tsunami broke supply chains across multiple industries and revealed that most continuity plans assumed a local failure, not a regional collapse. If your business operates in a high-risk zone for natural disasters, you need an alternative approach. The standard continuity plan will not save you if the physical infrastructure is destroyed. I recommend building relationships with backup suppliers in different regions and maintaining an emergency cash reserve that covers at least three months of operating expenses. These measures are not glamorous but they work when everything else fails. The downside of any continuity plan is that it creates a false sense of security. People read the plan, nod their heads, and assume they are protected. The reality is that most plans contain outdated information, reference people who left the company, and assume a failure scenario that never actually happens. I recommend reviewing your plan every quarter and updating it based on what you learn from each test.

The Practical Steps That Actually Work
Start with a business impact analysis that takes about two weeks. Map your critical functions, rank them by time sensitivity, calculate your recovery time objectives, and identify single points of failure. The output is a living document that tells you exactly what to prioritize when things break. Build manual workarounds for your top five critical functions. These should not require technology, be testable in under an hour, and be documented in plain language. Test them quarterly using unannounced tests that take about two hours per session. The metric that matters is not whether the test succeeds but how long it takes to discover the gaps that would cost you the most during a real incident. If you operate in a high-risk zone, build relationships with backup suppliers in different regions and maintain an emergency cash reserve that covers at least three months of operating expenses. These measures are not glamorous but they work when everything else fails.
A Final Note on Business Continuity For Dummies
The hardest part of business continuity is not the technical work but the ongoing maintenance. Plans decay, people leave, systems change. The process that takes about thirty minutes per quarter and keeps your plan functional is reviewing and updating it based on what you learn from each test. Most companies skip this step and spend thousands on plans that become outdated within a year. I recommend starting with a single critical function, building a manual workaround, and testing it within thirty days. The time investment is about two hours total and the payoff is knowing exactly what happens when something breaks. Everything else is just scaling that same process up to your full operation.