Why Most Business Continuity Plans Fail Before They're Tested
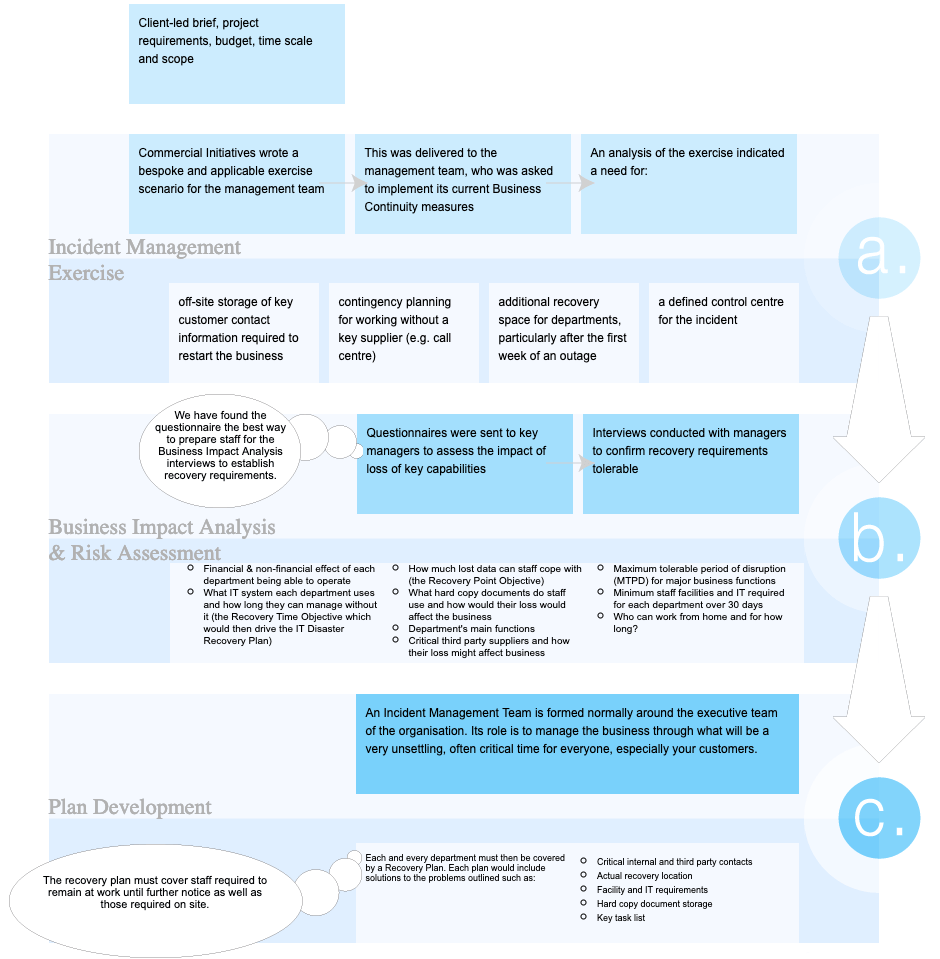
I spent three weeks last year rebuilding a client's disaster recovery sequence after their annual tabletop exercise exposed a single point of failure in their network failover. The plan looked perfect on paper. It was completely wrong in practice. This is what usually goes wrong and how to actually fix it. Let me walk you through one from my recent workload. A mid-size logistics company needed a BCP after a ransomware attack took them offline for eleven days. Their existing documentation was nine pages of corporate buzzwords. Nobody had updated it since 2019. I built them a new one from scratch over six weeks, running actual failover tests, not just desk reviews. The core methodology is straightforward even if executing it cleanly takes discipline. You start by mapping every critical business function, then identify what each one depends on — infrastructure, personnel, data, third-party services. After that you establish Recovery Time Objectives and Recovery Point Objectives for each function. Then you document the exact steps to get there. Most guides skip ahead to writing the document itself without doing the dependency mapping first. That's where things fall apart.
In the logistics case, their warehouse management system was the critical function. Everything else branched off that. But they had seventeen downstream dependencies they hadn't identified because the knowledge lived in three different people's heads. One had retired. Two were on vacation during the incident. I spent four days just interviewing staff and tracing system connections before writing a single recovery step.
The Dependency Mapping Stage You Can't Skip
Here's the part most people get wrong. A Business Continuity Plan Case Study isn't valuable because of the document format. It's valuable because of the dependency mapping process itself. You learn more by identifying what each system connects to than by writing elegant recovery procedures. Start with a functional Criticality Assessment. Rate each business process on a scale of one through five based on revenue impact, regulatory exposure, and customer-facing consequences. Revenue impact alone won't give you the full picture. Regulatory fines from a HIPAA violation in healthcare or a PCI DSS breach in payments can kill a company faster than lost sales. Factor that in from day one. Then map the technology dependencies for each rated function. I use a simple spreadsheet with four columns: business function, primary system, backup or fallback system, and estimated recovery time. When you can't fill in the backup column, that's your gap. In the logistics example, seventeen gaps showed up in that first pass. Seventeen places where recovery would have stalled completely.
Get the Full Details
The next layer is personnel dependencies. Who actually knows how to execute each recovery step? Not the person whose job title says they handle it. The person who shows up at 3 AM when the alert fires. I once found a plan where the designated IT recovery lead had taken a new role three months earlier. The document still listed his old phone number and email. This happens constantly.
Writing Recovery Procedures That Actually Work
Recovery procedures should be written for someone who has never worked at the company and has no institutional knowledge. That's the test. If a new hire can't execute your procedure without calling a colleague, rewrite it. Each procedure needs a clear trigger condition. Not "if the system is down." Something specific like "if the primary database fails to accept connections for more than ten minutes and the automated failover has not activated within five minutes of detection." Trigger conditions prevent panic decision-making during an actual incident. Communication procedures are where most plans are weakest. You need predefined message templates for different stakeholder groups — employees, customers, regulators, media. Write them before something happens. During a crisis, nobody has the mental bandwidth to compose legal-sounding customer notifications while also trying to restore email servers. I include templates for the top five communication scenarios in every plan I build. The logistics company alone needed six templates. Their ransomware incident triggered notifications to shipping clients, port authorities, insurance providers, and two regulatory bodies.
Here's a counter-intuitive insight that beginners miss. Your Recovery Time Objective should be shorter than your maximum tolerable downtime by at least twenty-five percent. Everyone wants to set aggressive RTOs to look prepared. But if your target recovery time equals your tolerance threshold, you're already behind schedule when you hit it. I always build in a buffer. The logistics company's system had a maximum tolerable downtime of forty-eight hours. Their RTO was set at thirty-six. The extra twelve hours bought them room for unexpected complications during actual restoration.
Testing Methods and What They Actually Reveal
There are five recognized testing methods. Checklist review, walkthrough, simulation, parallel testing, and full interruption testing. Most organizations do checklist review once a year and call it adequate. It isn't. Walkthroughs involve the team reading through the plan together. They reveal gaps in the documentation and identify people who don't know their assignments. This costs about two hours of staff time and catches roughly sixty percent of procedural errors. I recommend this as a minimum annual exercise for any organization under five hundred employees. Simulation testing runs the scenario without actually disrupting operations. You fake the outage and have people execute their recovery roles in real time. This is where I found the logistics company's biggest problem. During simulation, the backup server took forty-seven minutes to come online instead of the documented fifteen. The discrepancy came from a firmware update that had been pushed to production two months earlier without updating the recovery documentation. Fourteen people had signed off on the change. Nobody told the continuity team.
Parallel testing runs the backup systems alongside production without switching over. It validates that the backup environment actually works without risking business disruption. This usually takes one to two days and requires coordination with infrastructure teams. It catches configuration drift that simulation misses. Full interruption testing is the gold standard but also the riskiest. You actually take production offline and recover onto backup systems. I've done this twice in twelve years. Once for a financial services client during a planned maintenance window and once for a healthcare provider during an emergency patch deployment. Both revealed critical issues. The financial client's backup license had expired eighteen months earlier. The healthcare provider's restoration process would have failed because their backup encryption keys had rotated without documenting the new locations. These are exactly the kinds of failures that only full interruption testing surfaces.
Document Structure and Maintenance
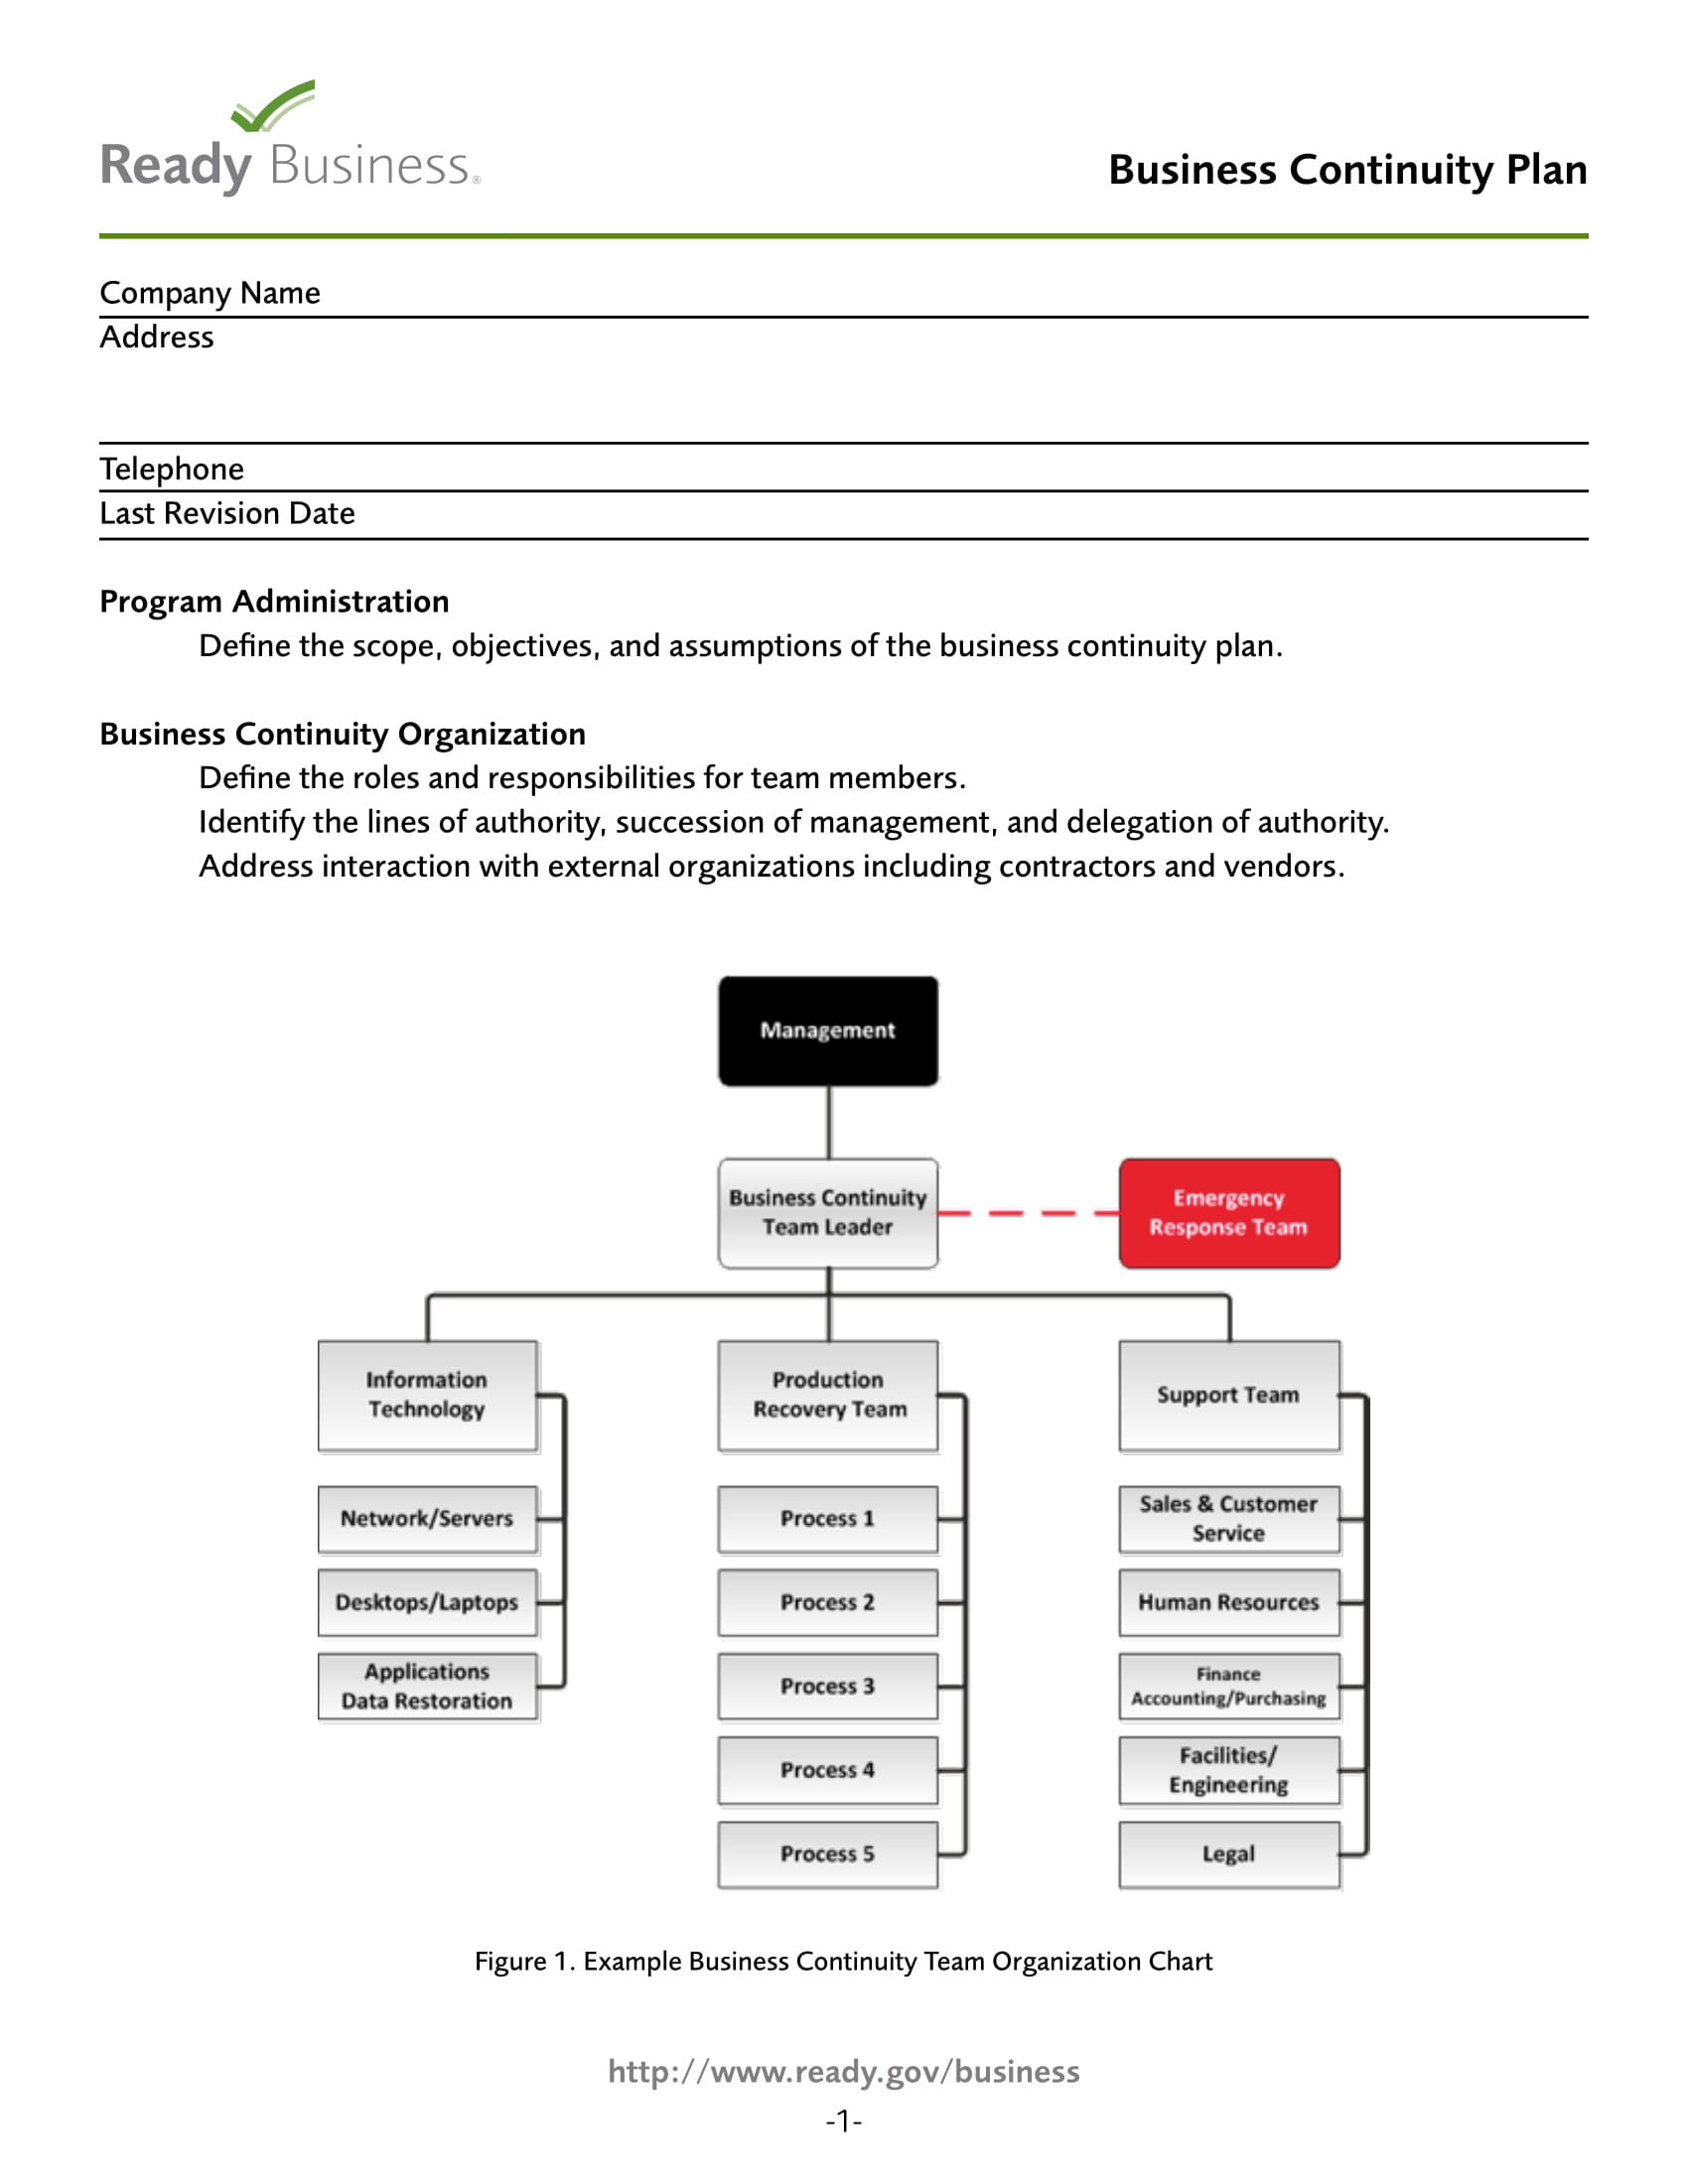
A working Business Continuity Plan Case Study document typically runs between forty and eighty pages for a mid-size organization. Structure it around these sections: purpose and scope, organizational structure and contact information, critical function analysis, recovery procedures by function, communication plan, resource requirements, and testing schedule with results tracking. Keep the contact section in a separate living document that gets updated weekly. I've seen plans where seventy percent of the phone numbers were wrong because the master document was static but personnel changed constantly. A separate contact list with a designated owner who updates it monthly makes a significant difference in execution speed during an actual event. Version control matters more than people think. Every change to the plan should have a dated version number, a change log entry, and a record of who approved the modification. When a new incident manager takes over, they need to understand what decisions were made and why. A plan without version history is just a guess dressed up as procedure.

Common Pitfalls and Where This Approach Falls Short
The biggest mistake is treating the plan as a compliance deliverable rather than an operational tool. If the plan exists only to satisfy an auditor, it will be outdated within six months. I've seen this repeatedly. Organizations budget for the initial BCP development and then neglect the ongoing maintenance cycle. The plan becomes a shelf document that provides false confidence. Another structural weakness is concentrating all recovery procedures on a single alternate site. Single points of failure exist in your continuity plan too. The logistics company had a secondary site in a neighboring city. That city experienced a regional power grid failure during our third simulation test. Neither site was operational simultaneously. They ended up with zero recovery capacity for a two-day period. I now require at least two geographically recovery options for any client in industries where continuity is time-critical. Third-party dependencies are the blind spot most organizations miss. Your plan might be solid internally but useless if your cloud provider, your payment processor, or your data center operator is also down. I add a dedicated third-party dependency assessment to every plan. It's a simple table listing each vendor, their SLA commitments, their own business continuity status, and escalation contact information. The logistics company had four vendors whose simultaneous failure would have made internal recovery irrelevant. Only one had current BCP documentation on file.
This approach has real limitations. It cannot account for cascading failures across multiple independent systems. It cannot predict novel threat scenarios. No BCP can. What it does is force structured thinking about worst cases and build institutional muscle memory for response. That muscle memory is what separates organizations that recover in hours from those that recover in weeks. The business continuity field keeps producing new frameworks and certification programs. I don't follow most of them closely. The methodology I described above has produced reliable results across healthcare, logistics, fintech, and manufacturing over the last eight years. The specifics change. The core process doesn't.


