The Gap Between Reports and Decisions
Most people think Business Intelligence Analytics And Data Science means building dashboards and watching charts spin. That is half the job. The other half is convincing people the chart actually matters. I learned this the hard way after shipping what I thought was a beautiful quarterly performance report. The CEO looked at it for exactly four seconds and asked, "So should we fire someone or hire someone?" I had spent three weeks on that visualization. I did not have a data-driven answer to that question.Business Intelligence Analytics And Data Science
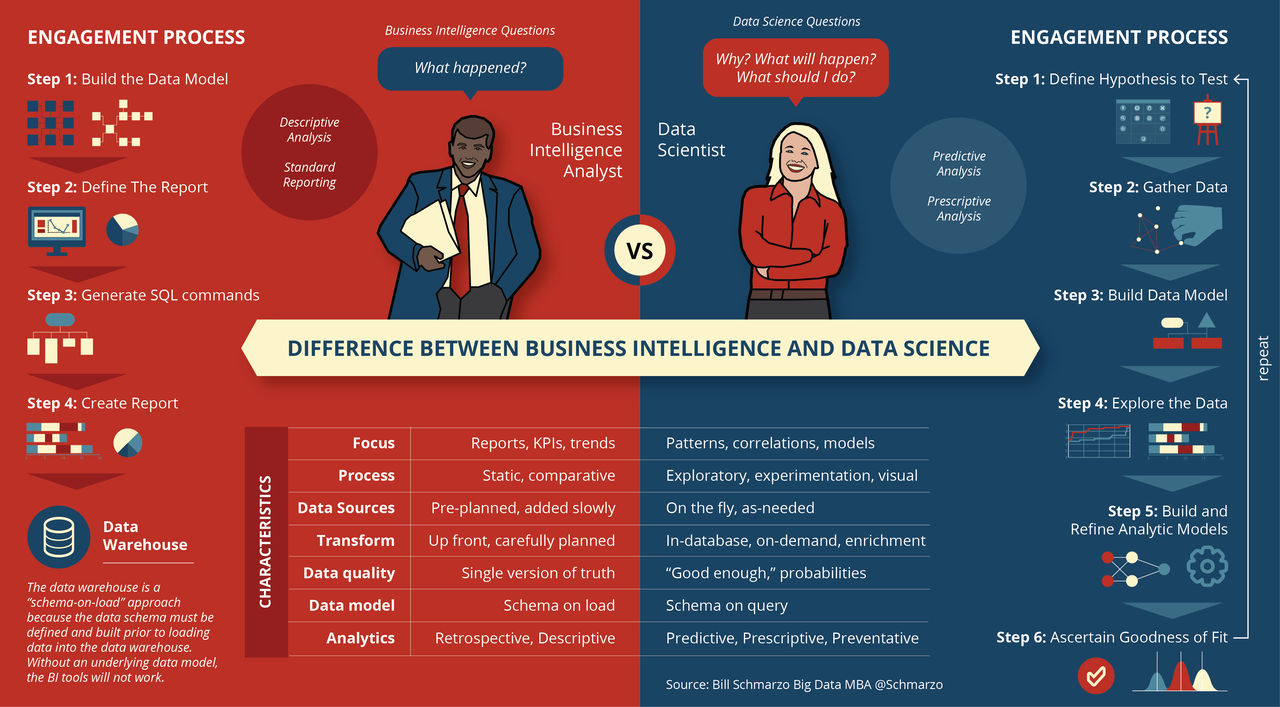
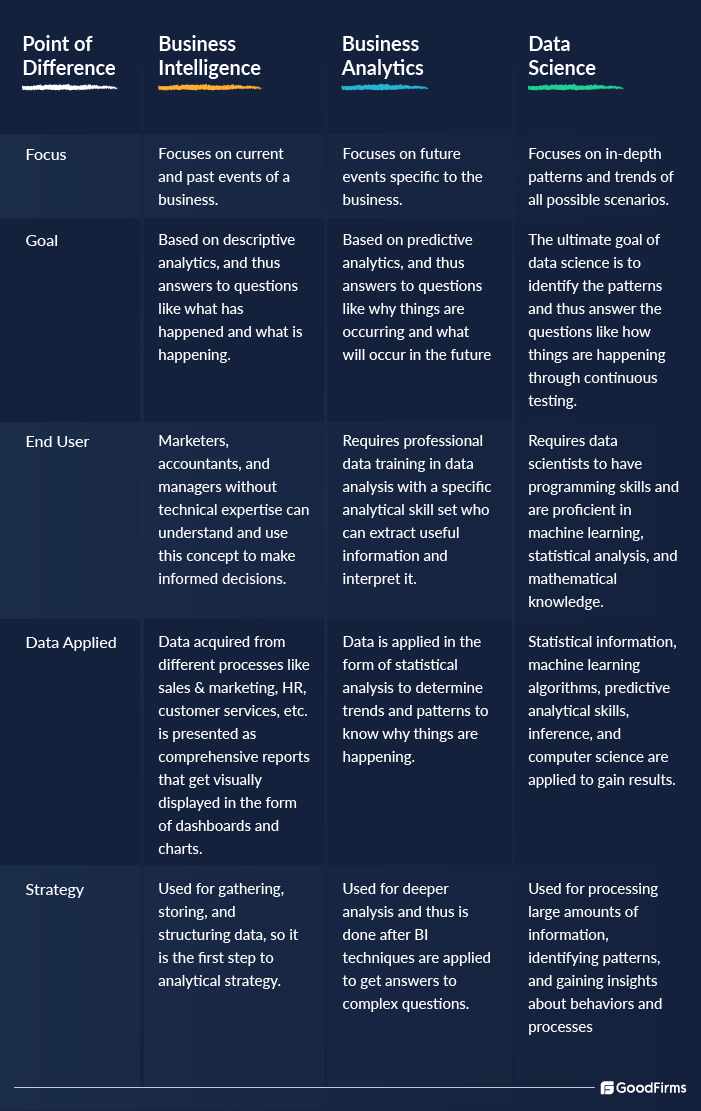
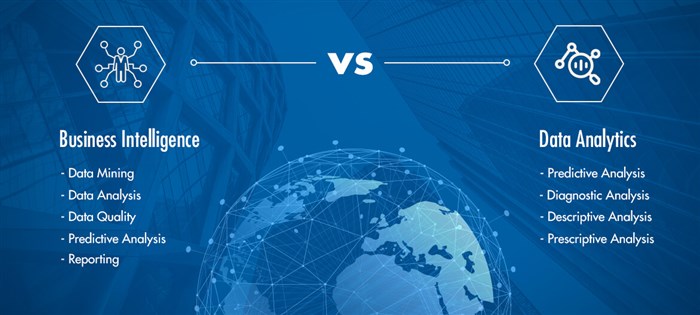
Business Intelligence Analytics And Data Science is not one discipline. It is two disciplines that overlap in practice but do not share the same daily goals. BI is about structured data, predefined queries, and answering questions that already have names. Data science is about unstructured data, statistical modeling, and finding questions you did not know to ask. The confusion starts when organizations treat them as interchangeable. I started in BI. I built ETL pipelines, wrote SQL, set up tabular reports in Tableau, and automated refresh schedules. It was straightforward work until the business outgrew the structured world. That is when I crossed into data science territory. The transition is not as clean as the job titles suggest.
What Actually Happens in a Real Project
Here is a concrete example. A mid-size e-commerce company wanted to reduce customer churn. The BI team had the transactional data. They could tell you what happened last month. They could tell you which segment had the highest churn rate. They could not tell you why a specific customer was about to leave next week. That is where the data science piece enters. I built a survival analysis model using the customer interaction logs, purchase frequency, support ticket sentiment, and price sensitivity over time. The model predicted a churn probability score. We fed that score back into the BI layer so account managers could see it in their daily workflow. The model itself was not the deliverable. The deliverable was a workflow change that reduced churn by 11 percent over six months. Most projects fail because they stop at the model. The model is cheap. Integration is expensive.
The Hard Parts No One Talks About
Data quality is the usual answer, but that is too vague. Let me give you a specific problem I encountered last year. We were building a unified customer view across three systems: Salesforce, Shopify, and a legacy ERP. The IDs did not match. Customer names were formatted differently. One system used uppercase, another used title case. Email addresses had trailing spaces. Phone numbers included country codes in some records and not in others. A simple merge produced 40 percent duplicates. The workaround was not fancy. I wrote a multi-stage deduplication pipeline. First, I normalized all emails and phone numbers using regex. Then I built a fuzzy matching layer with Levenshtein distance thresholds. After that, I used a rule engine for deterministic matches on hashed IDs. Finally, I had a manual review queue for borderline cases. This cut the duplicate rate from 40 percent to under 2 percent. It took three weeks of work that nobody sees in a presentation. The lesson is that identity resolution eats more time than modeling in most real-world projects. Plan for it.
Get the Full Details

Common Pitfalls That Waste Budgets
Pitfall one: optimizing for accuracy instead of usefulness. A model with 85 percent precision that nobody trusts is worse than a model with 72 percent precision that a sales team actually uses. I watched a team spend four months improving an A/B test recommendation engine from 72 percent to 85 percent. The sales team abandoned it because the confidence intervals were too wide for their taste. They went back to gut instinct. The 85 percent model delivered zero business value. Pitfall two: treating BI and data science as separate teams with separate roadmaps. This creates a handoff problem. The BI team builds dashboards based on static snapshots. The data science team builds models that require fresh data daily. The infrastructure does not align. The output becomes contradictory. I saw a marketing dashboard show one CAC number while the data science model calculated a different one. Neither team checked the other's methodology. The CFO got confused. No decision was made. Pitfall three: assuming more data solves the problem. Adding more features to a model without understanding which ones actually drive decisions increases complexity without improving outcomes. In one project, we added forty-two features to a propensity model. The feature importance analysis showed that eight of them explained 90 percent of the variance. The other thirty-four were noise. Removing them cut training time from twelve minutes to two minutes and improved deployment reliability.
Practical Steps to Build Something That Actually Works
Start with the decision, not the data. Write down the exact question a stakeholder needs answered. If you cannot name the decision, you do not have a project. You have a hobby. Build a minimal data pipeline first. Get structured data moving reliably before adding any machine learning. A clean source of truth beats a complex model every time. I recommend starting with a single source, one table, one refresh schedule. Validate the numbers against the source system. Once the foundation works, expand. Document the transformation logic. Every column should have a clear owner and a clear definition. When the marketing VP asks why a metric changed, you should be able to trace it back in five minutes, not five hours. I keep a living data dictionary in a shared document. It is not glamorous, but it prevents arguments that kill projects.
Test the output with the actual user. Before you build the full dashboard, build a prototype and send it to one person who will use it. If they need to export it to Excel to make sense of it, you have not solved their problem. Iterate until the tool sits inside their existing workflow.
Tools That Actually Matter
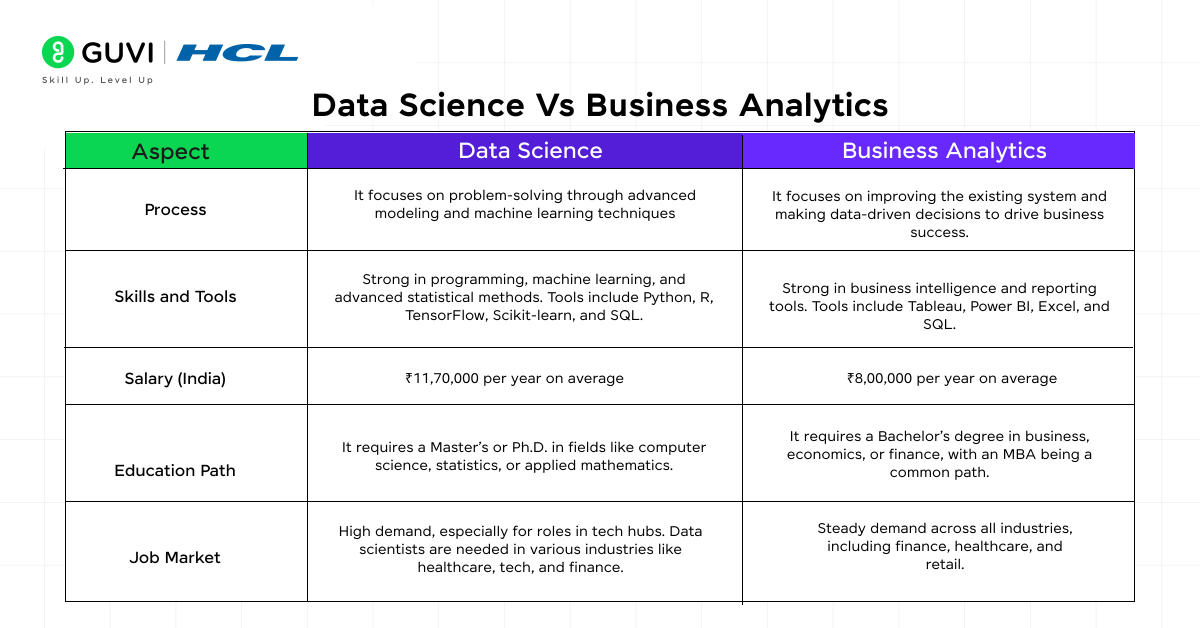
For BI, dbt paired with a warehouse like Snowflake or BigQuery is the modern standard. It keeps transformation logic version-controlled and testable. Without dbt, transformations become buried in undocumented SQL files. That does not scale. For data science work that feeds into BI, Python with pandas and scikit-learn remains the default. The ecosystem is large, the documentation is adequate, and the integration with production systems is well-supported. R is still valid for heavy statistical analysis, but most organizations need the broader tooling Python provides. For visualization and reporting, Tableau and Power BI are the two choices. Tableau handles complex visual analysis better. Power BI integrates more cleanly with Microsoft ecosystems. Pick based on your existing stack, not based on trends.
I also recommend Airflow or Prefect for orchestration. Scheduled jobs will break. You need visibility into failures before stakeholders ask why the numbers are missing. Automated alerts save relationships.
When This Approach Fails Completely
This methodology assumes you have access to historical data. If you are launching a brand-new product with zero traction data, predictive models will hallucinate patterns. In that scenario, qualitative research and rapid experimentation beat sophisticated modeling. I worked with a startup that tried to build a churn prediction model before they had ten thousand transactions. The model was nonsense. They replaced it with weekly customer interviews and saw actionable patterns within a month. The approach also fails when organizational incentives are misaligned. If the sales team is measured on volume and the marketing team is measured on leads, no amount of analytics will reconcile their definitions of "success." The data becomes a weapon rather than a tool. I encountered this at a company where both teams claimed ownership of the conversion funnel. The BI dashboards showed two different numbers for the same metric. Leadership chose the number that supported their preferred narrative. Analytics lost credibility because the culture did not support it.
A Reality Check on ROI
A well-implemented BI and data science setup typically cuts reporting time from days to hours. A team that used to spend two weeks per month on manual reporting found themselves spending less than ten hours after automation. That is a real savings. But the harder part is turning that saved time into better decisions. Companies that measure success only by dashboard usage often miss the actual outcome. I track two metrics now: how many decisions reference the data, and how often those decisions are corrected later. The first measures adoption. The second measures accuracy. Both matter. The field moves fast. New tools appear every quarter. The core problem has not changed in twenty years. It is always about turning raw data into a clear answer that someone acts on. Everything else is detail.