Why Your Social Media Data Is Worth Something If You Actually Process It
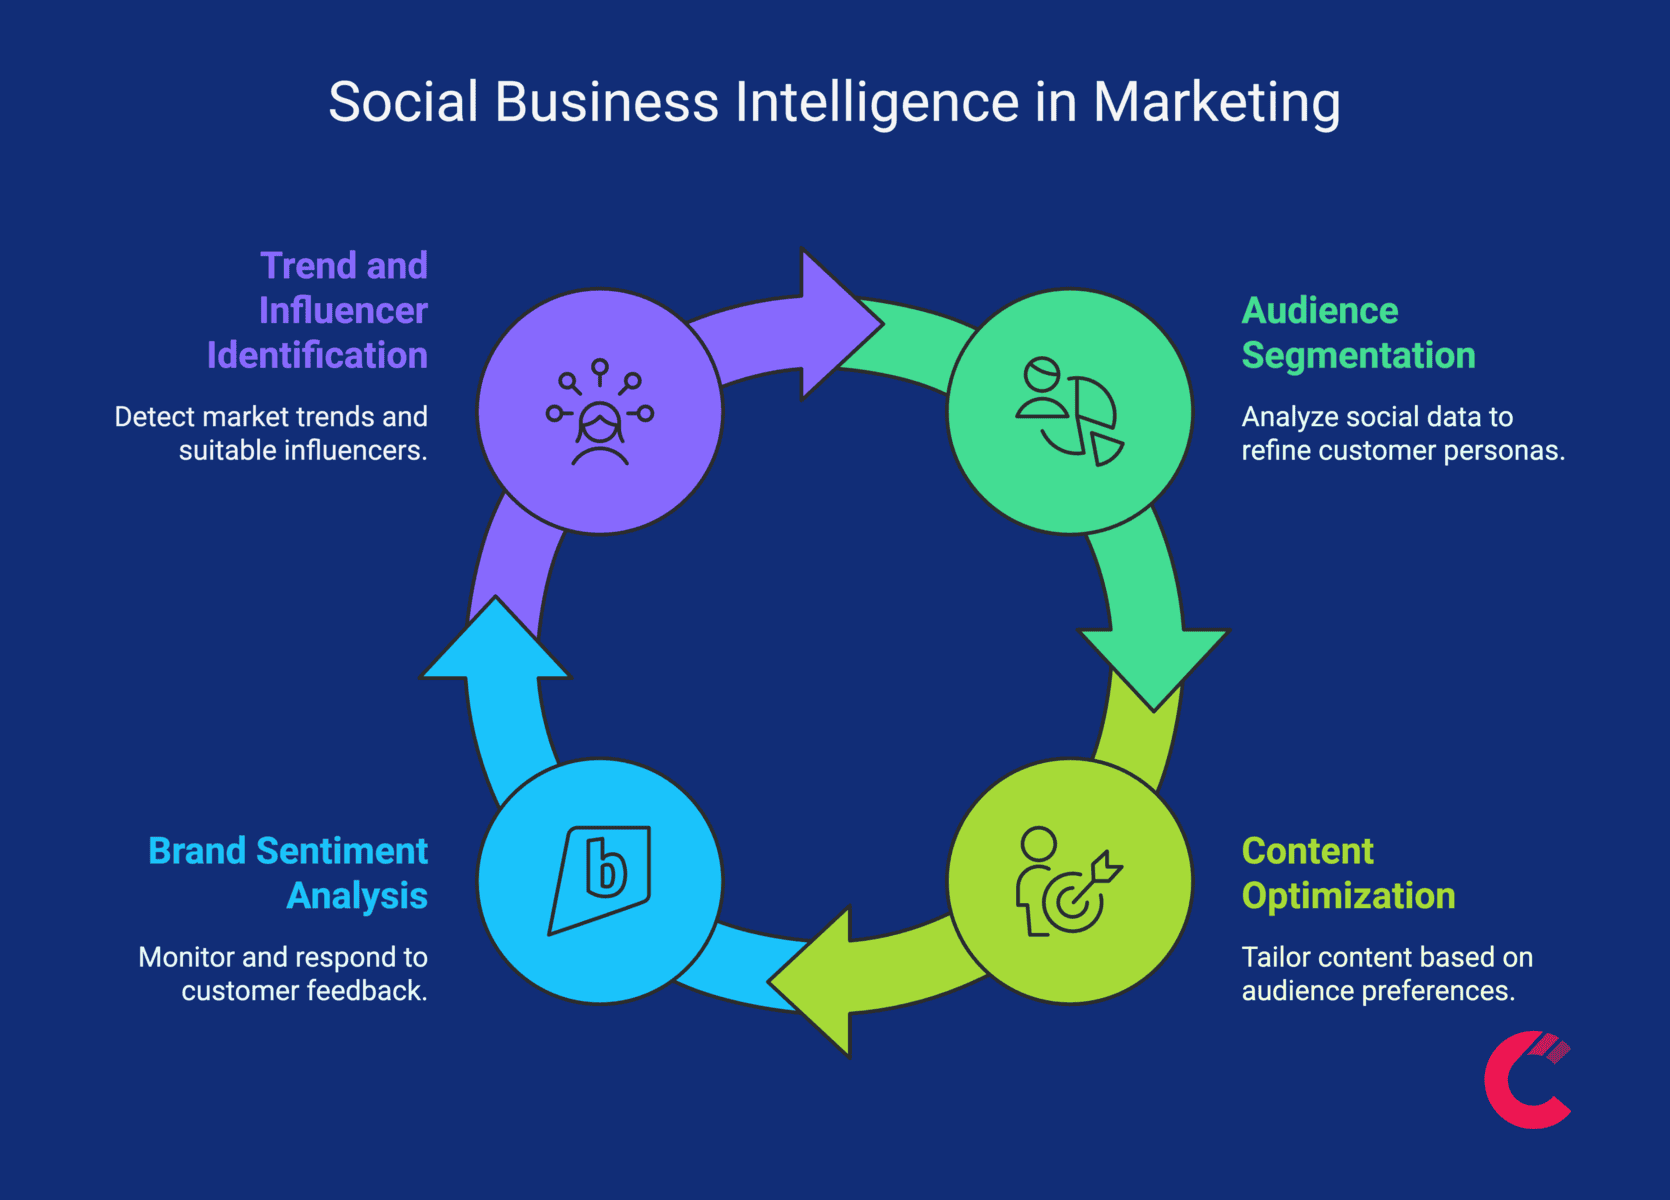
Most companies dump their social media exports into spreadsheets and call it analytics. They look at follower counts and post engagement rates, then make quarterly decisions based on nothing more than vanity metrics. This is why they miss actual market shifts while wondering why revenue is flat. Business Intelligence And Social Media is the process of taking raw engagement data, sentiment signals, audience demographics, and competitive mention patterns and turning them into decisions that actually move the needle. Not dashboards for the sake of having dashboards. Real intelligence, like you would get from sales figures or supply chain data, but sourced from platforms where people are actually talking about your brand unprompted.
The Core Problem With Most Approaches to Business Intelligence And Social Media
The biggest issue I see is that teams treat social media data like it's a single stream. It's not. You've got structured data from APIs — likes, shares, follower growth, reach numbers — and you've got unstructured data, which is literally everything else. Comments, replies, direct messages that get archived, hashtags, image alt text, even the timing patterns of when your audience is active. These two types of data require completely different processing pipelines and usually end up in completely different tools, which is why half the organizations trying this never get past the visualization stage. I spent about three weeks last year wrestling with a client who had 47 different social accounts across five platforms and wanted a unified view of their brand sentiment over the previous 18 months. The API exports gave them clean numbers but zero context. When they saw a 300% spike in mentions one Tuesday, they celebrated. The unstructured data showed it was because a competitor had a public data breach and everyone was tagging them in sympathetic posts. Their "win" was actually irrelevant noise. We filtered by keyword proximity and context scoring instead of raw mention volume and found the actual signal buried under the chatter.
What You Actually Need To Build This
Start with the data sources. Twitter/X API, Meta Graph API, LinkedIn API, Reddit's API, and whatever native analytics exports your platform gives you. Some of these are free tier, some will cost you. The X API changed its pricing model and effectively killed the free tier, so budget accordingly if that's your primary channel. LinkedIn's API access is restricted to enterprise partners. Reddit is surprisingly cooperative if you apply properly. You'll need a storage layer. A data warehouse like BigQuery, Snowflake, or Redshift works fine. For smaller operations, a properly indexed PostgreSQL database with JSONB columns can handle structured and unstructured data together without the overhead. The trick is normalizing the data on ingest so that a "like" from Instagram and a "heart" from Facebook both map to the same field. Otherwise you're comparing apples and notification bells six months later. For the processing side, you're looking at three main functions: sentiment analysis, topic clustering, and competitive benchmarking. Sentiment analysis tools like VADER, BERT-based models, or commercial offerings from MonkeyLearn and MeaningCloud will assign polarity scores to your text data. Topic clustering runs through TF-IDF vectors or LDA models to group mentions by subject matter. Competitive benchmarking is the part most people skip, and it's the most valuable. You're not just tracking your own numbers. You're tracking how your metrics move relative to your actual competitors, not the ones you picked because they're similar in size.
Get the Full Details
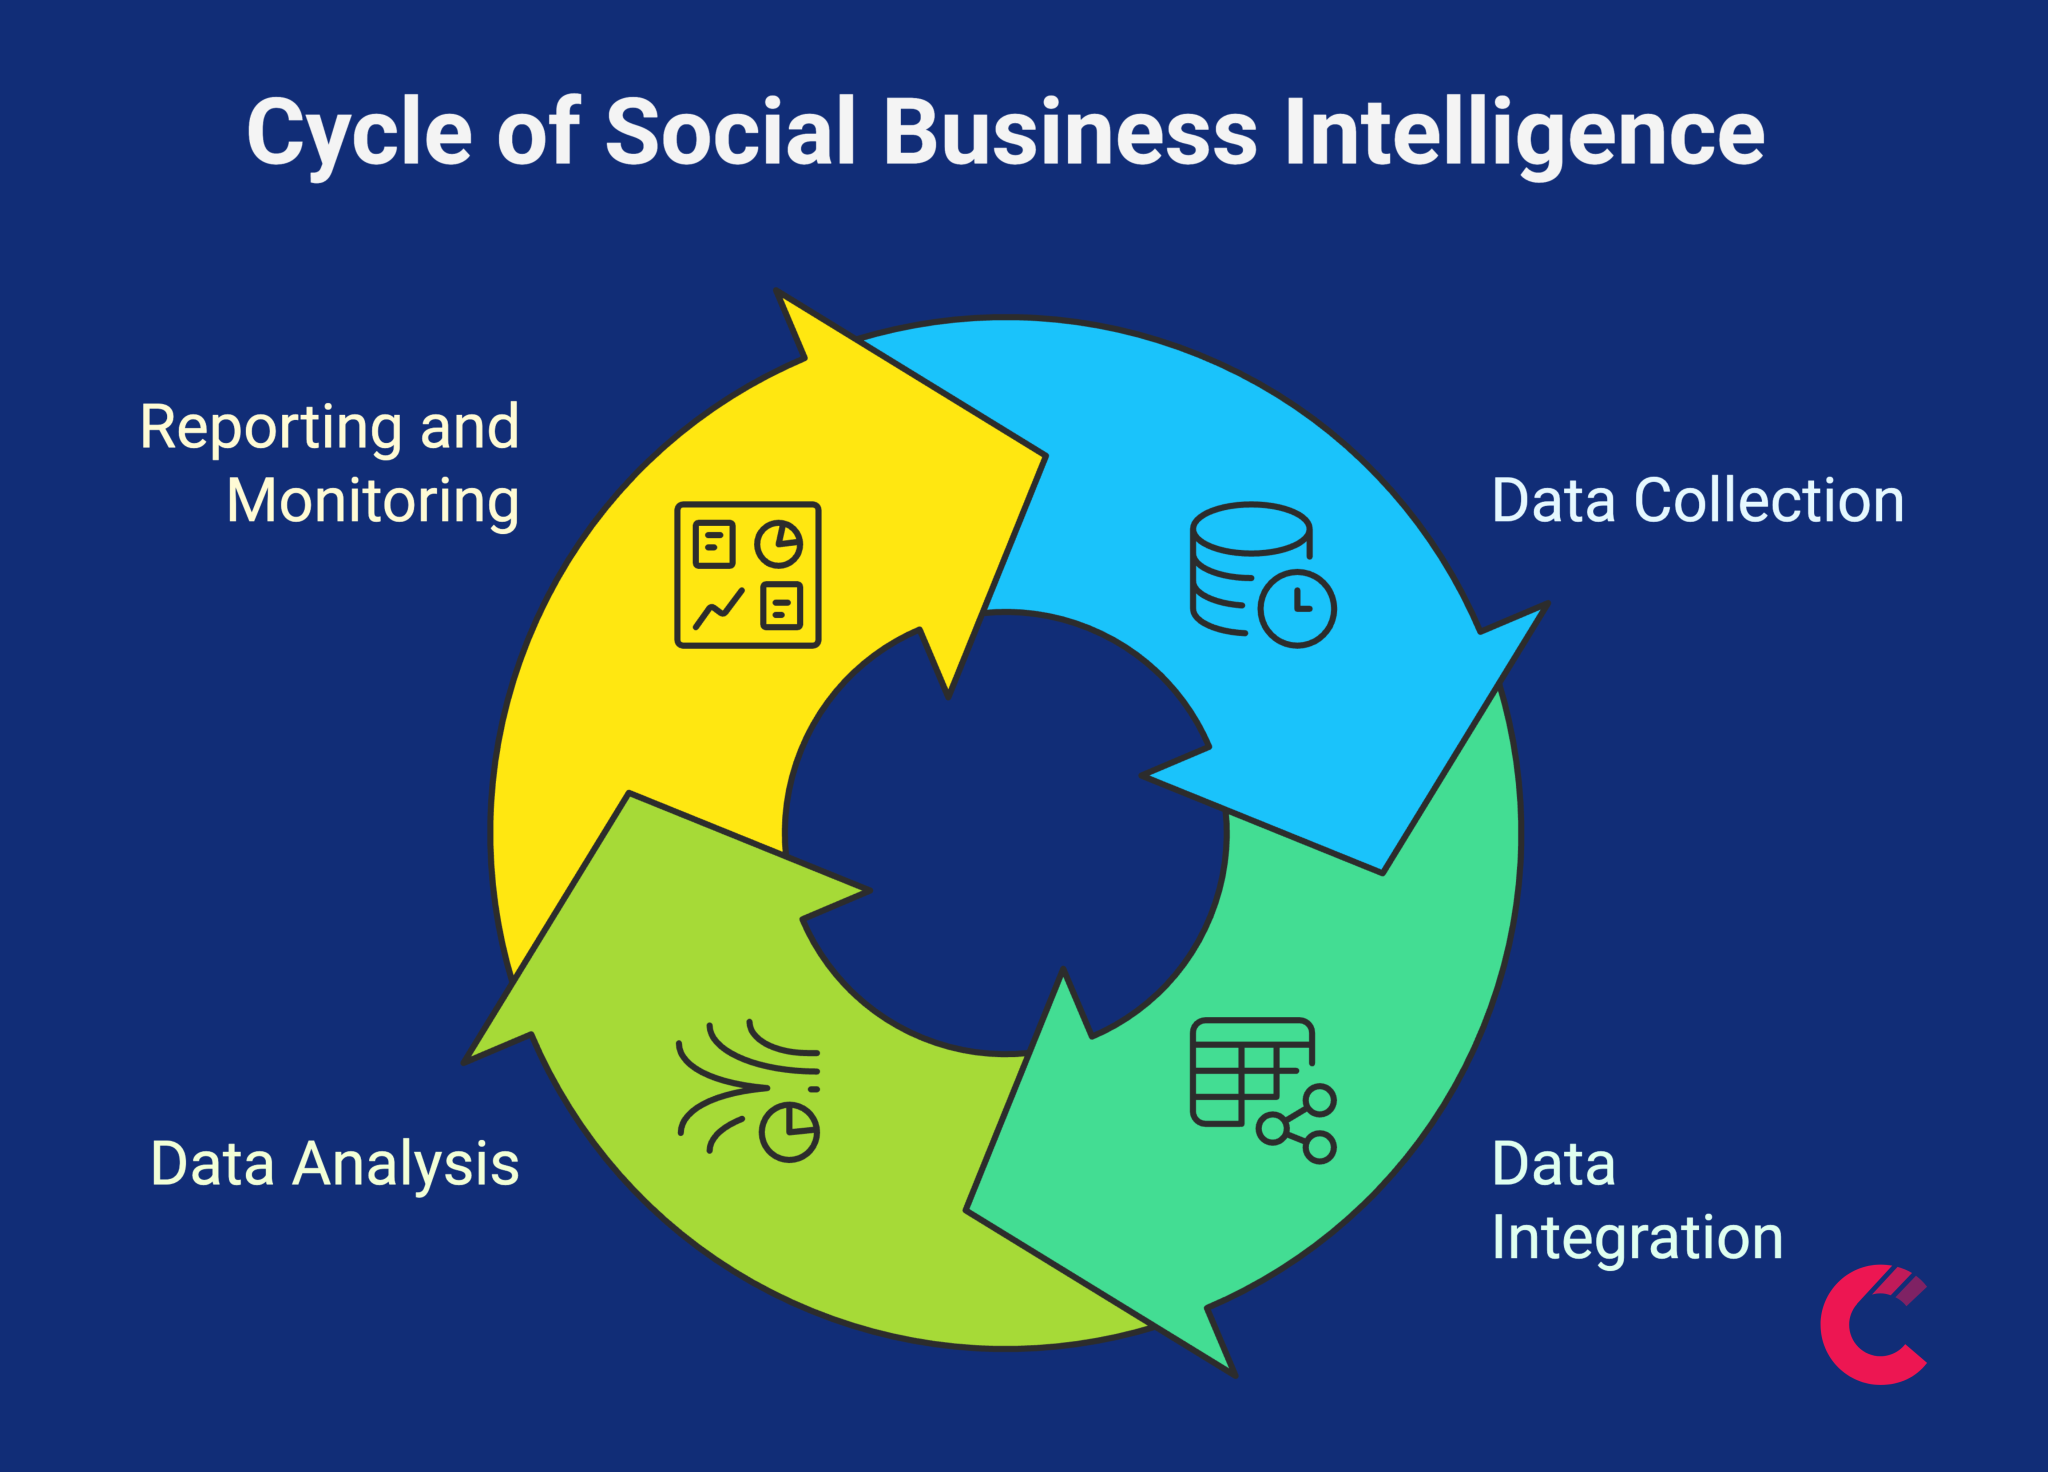
I once built a pipeline that pulled sentiment data every four hours, ran it through a fine-tuned BERT model we'd trained on our industry's specific language patterns, and pushed the results to a dashboard that flagged anomalies automatically. The anomaly detection caught a product quality issue three days before our customer support team did. A cluster of negative sentiment spiked around a specific feature mention that our own feedback channels hadn't flagged yet. That's the difference between reactive and proactive.
Common Pitfalls That Waste Months Of Work
Here's what beginners consistently miss. First, they don't account for platform algorithm changes. LinkedIn changed their feed algorithm in 2023 and engagement dropped 40% across the board for most businesses. Not because their content got worse, but because the distribution mechanism shifted. Any BI system you build needs baseline adjustments for these events or your trend lines become meaningless. Track reach and impressions separately from engagement rate. Engagement rate will lie to you during algorithm shifts. Second, attribution is a minefield. Social media touchpoints are rarely the last interaction before a conversion. The standard "last click" model doesn't apply. Multi-touch attribution in the social space is messy because people see your content, then search for you directly, then convert through a channel your social data can't see. I've seen teams build complex attribution models that turned out to be measuring their own bias rather than reality. Sometimes the answer is simpler: track branded search volume alongside social metrics. If social mentions go up and branded searches go up with a 2-3 day lag, you have a correlation that's useful even if you can't prove direct causation. Third, and this is the one that costs people the most money, they don't clean their data before analyzing it. Bot accounts, engagement pods, throwaway profiles, automated retweets — these inflate your numbers in ways that are hard to detect without looking at the underlying profile data. A single campaign can have 80% of its engagement come from accounts that were created three weeks ago, have no profile photo, and follow 4,000 accounts but have zero followers. Filter those out before you run any analysis. I use a simple heuristic: accounts with a follower-to-following ratio below 0.1, created within the last 90 days, and zero original content get excluded from sentiment calculations. It cuts noise by roughly 60% in most B2C environments and doesn't meaningfully impact the signal.
Practical Implementation Steps
Don't try to build the perfect system from day one. Start with one platform, one metric, and one business question. If your main concern is customer satisfaction, track sentiment on your primary platform and correlate it with support ticket volume. If your concern is product positioning, track topic clusters and see what language your audience uses when they mention you unprompted versus what language your marketing team uses. The mismatch between those two is usually where the biggest opportunities are. Set up automated data pulls. Manual exports are fine for a proof of concept but they don't scale. Schedule API calls during off-peak hours to avoid rate limits. Store everything, even if you don't plan to use it. Historical baselines are impossible to recreate once you've missed the data collection period. I learned that the hard way when a client realized six months into a project that they had no pre-campaign baseline for their biggest product launch. All the analysis was relative to other relative baselines, which is just a different way of saying you didn't actually know anything. Invest in the reporting layer last. Most people want the dashboard first because it's exciting. But a dashboard without a defined decision framework is just expensive decoration. Write down what decision each visualization will inform before you build it. If you can't answer "what would we do differently if this number went up or down," the metric isn't useful and you shouldn't visualize it.
The tools for this range from expensive enterprise platforms like Sprinklr and Brandwatch, which handle the infrastructure for you but charge accordingly, to building your own stack with Airflow for orchestration, dbt for transformation, and something like Metabase or Superset for visualization. The DIY route takes longer upfront but gives you control over exactly how data is cleaned and weighted. For most teams I work with, a hybrid approach works best: commercial API aggregators feeding into a custom warehouse where you do your own cleaning and modeling before sending results to a lightweight BI tool. There's also no point pretending this is a complete solution for business intelligence. Social media data has fundamental limitations. It skews toward louder demographics. It captures people who choose to post, not the silent majority. It reflects sentiment about your brand, not necessarily intent to purchase. It's best used as a leading indicator alongside traditional metrics, not as a replacement for them. When the data contradicts your sales figures, investigate both. Usually the sales figures are right and the social data is measuring something different than you thought it was measuring.