Getting From Raw Data To Something Managers Actually Understand
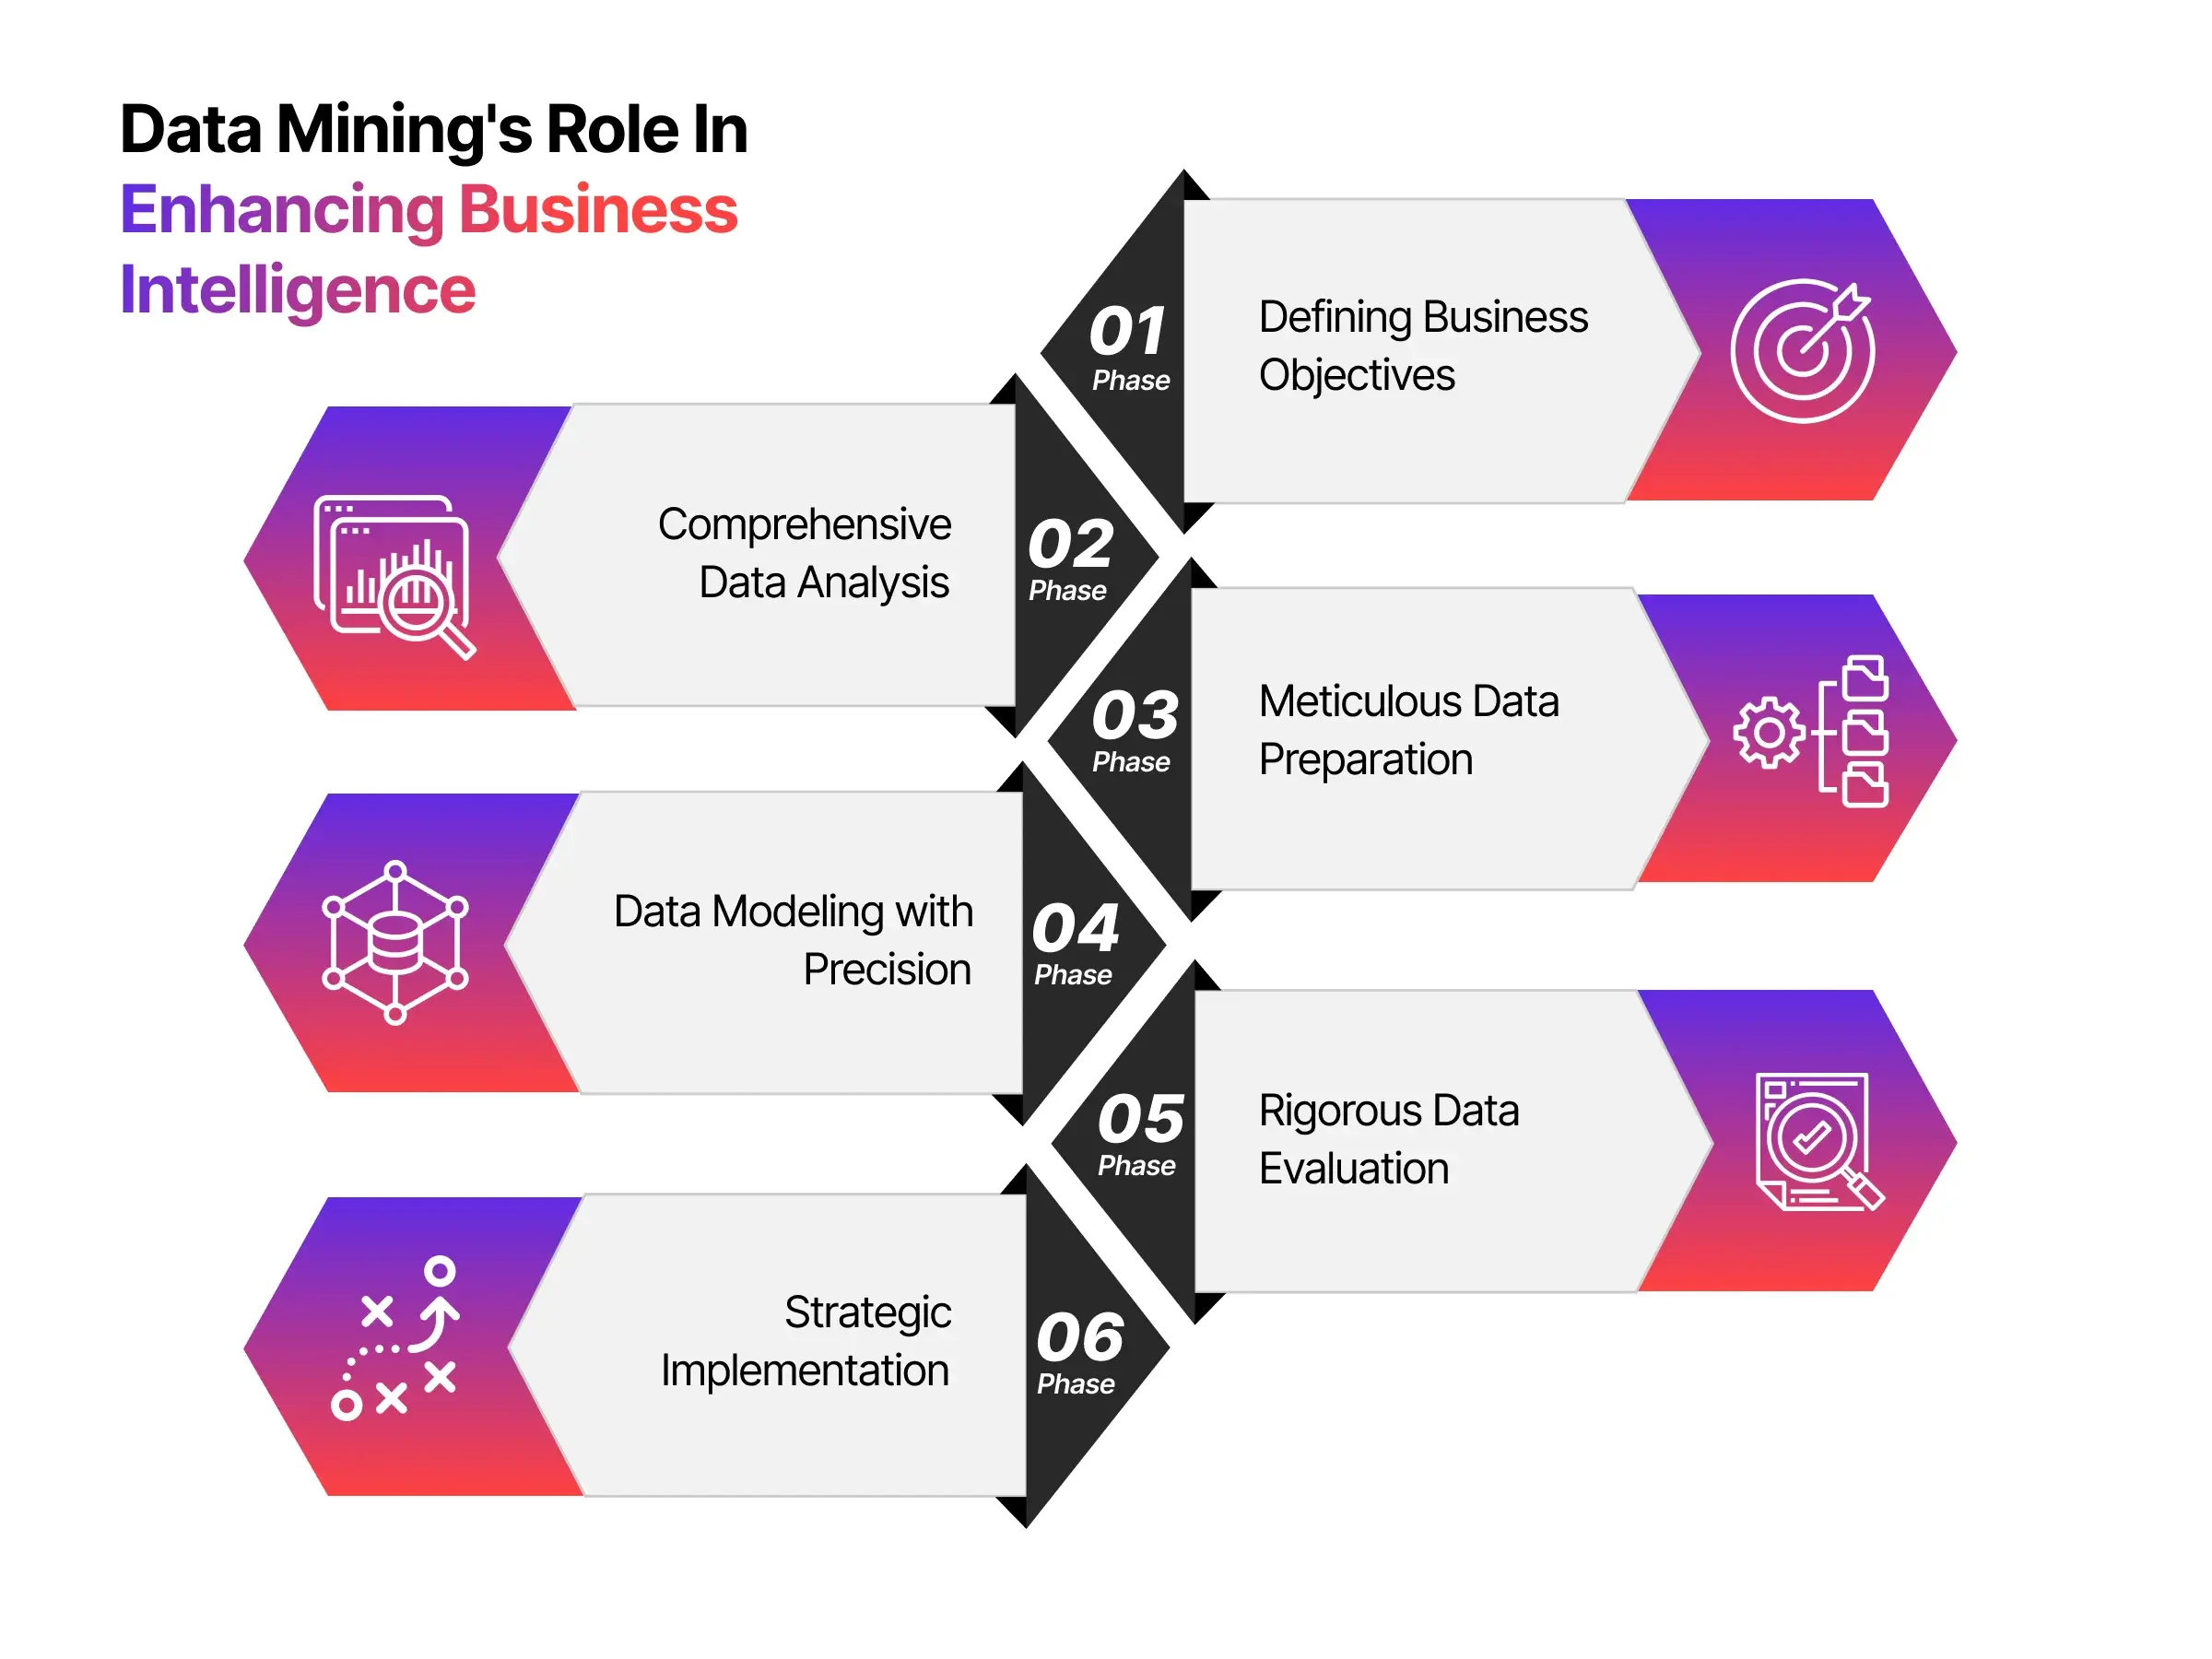
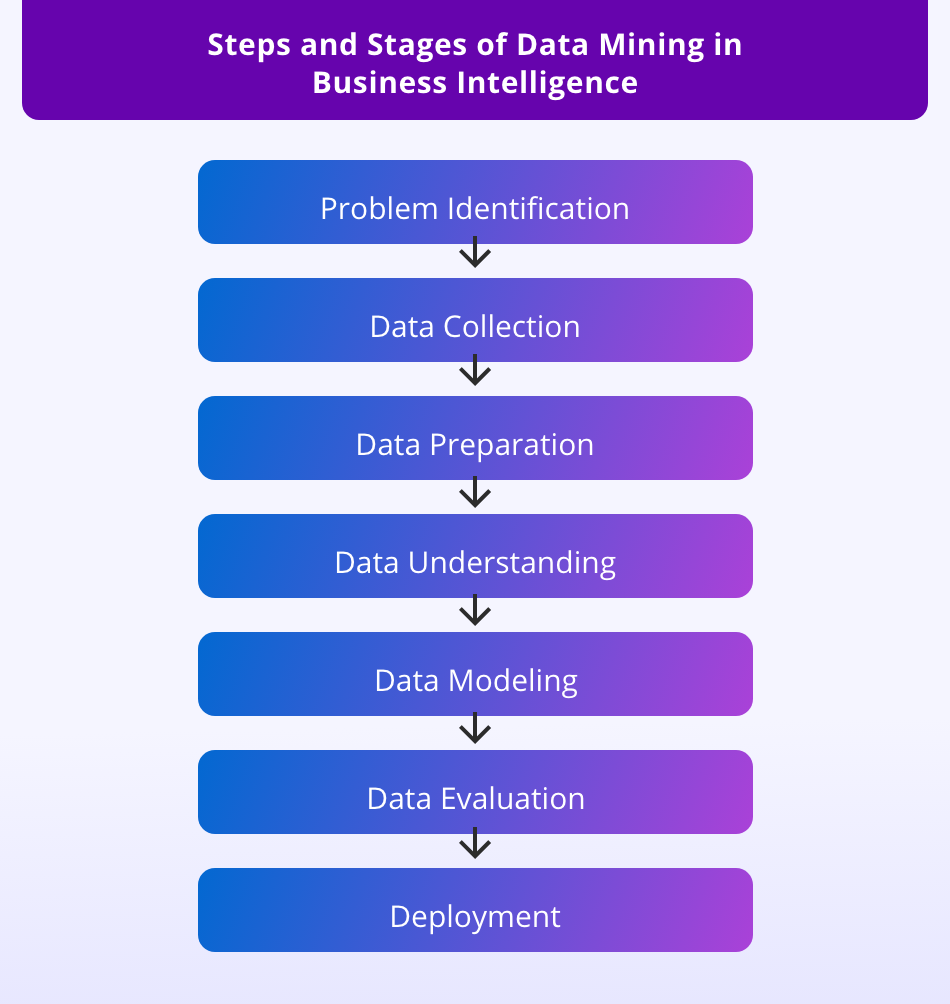
I used to spend weeks building models that nobody used. That stopped when I figured out the process actually matters more than the algorithms. This is how I approach Business Modeling And Data Mining now. Data mining is the mechanical process of extracting patterns from raw datasets. Classification, clustering, association rules, regression — these are the standard techniques. Business modeling takes those patterns and wraps them into a structure that maps to actual business decisions. Most people skip the first step and jump straight to making fancy dashboards, which is why their models fall apart. The CRISP-DM framework is still the most practical way to organize this. Cross-functional team, business understanding, data preparation, modeling, evaluation, deployment. It sounds corporate, but the reason it survives is that without it you spend six weeks building the wrong thing and then you do it again.
The Process I Actually Use
Start with the business question, not the data. I had a client who wanted a churn prediction model but never told me what they'd do differently for at-risk customers. I found that out eventually. They were going to send a discount email. The model ended up being useless because the best predictors turned out to be things discounts don't fix, like support ticket resolution time and onboarding quality. Here's the workflow I follow: Phase one: Nail down the decision. What specific action does this model enable? If the answer is "better understanding," you're not doing data mining, you're doing exploration. Those are different projects with different timelines and expectations.
Phase two: Get the data. Real data is never clean. Missing values, inconsistent formats, columns that changed meaning three quarters ago, duplicate records because someone merged two databases by accident. I budget two days of cleaning for every one day of modeling. If your dataset is bigger than a few gigabytes, you'll need Spark or some distributed processing tool rather than trying to load it all into pandas. That alone cut our typical ETL time from eight hours down to forty-five minutes on a mid-size retail dataset. Phase three: Feature engineering. This is where most models live or die. Raw columns are rarely predictive by themselves. Interaction terms, aggregations over time windows, lag features for sequential data — these matter more than model choice. I once spent three weeks tuning a gradient boosting implementation only to discover that adding a single derived feature, average session duration over the previous seven days, gave me better AUC than any hyperparameter sweep. Phase four: Model selection. Start simple. Logistic regression or a decision stump. Get a baseline. If it already solves the problem, great. Most of the time it doesn't, and then you move to random forests, gradient boosting, or neural networks depending on the data type and volume. I avoid deep learning unless I have structured tabular data with hundreds of thousands of rows or unstructured data like text and images. For standard business datasets, XGBoost or LightGBM handles the job faster and with less maintenance.
Get the Full Details

Phase five: Validation. Use stratified k-fold cross-validation. Don't do a simple train-test split on time-series data or you'll get garbage results because your test set leaks into your training set through temporal correlation. I learned that the hard way on a forecasting model for inventory. We validated using random splits and the model looked amazing. Deployed it and it failed within two weeks because seasonality patterns broke completely on the validation set.
A Specific Edge Case
One project involved customer segmentation for a SaaS company. Standard K-means clustering on usage metrics produced six segments, but when we mapped them back to actual revenue, two of the clusters were essentially the same customer behavior with different price tiers mixed in. The model was clustering on a proxy variable rather than the underlying behavior pattern. The workaround was to run hierarchical clustering first to understand the natural groupings in the data, then use those centroids as starting points for K-means. We also applied PCA to reduce the feature space before clustering. The resulting segments were smaller but actually actionable. What took us about three hours instead of the usual eight.
Common Pitfalls
Overfitting to historical noise. Models that perform well on training data but fail in production are the most expensive mistake you can make. Regularization helps, but the real fix is keeping your validation set completely separate and realistic. Ignoring class imbalance. Fraud detection, churn prediction, defect identification — these all have skewed distributions. Accuracy becomes meaningless. Use precision-recall curves, F1 scores, or AUC-ROC instead. SMOTE oversampling works but it can introduce synthetic artifacts. I've found that simply adjusting class weights in the model usually gives cleaner results for business datasets. Deployment complacency. Building a model is the easy part. Getting it to run in production, monitoring drift, retraining on schedule — that's where projects die. Set up automated retraining pipelines from day one, not after the model degrades. Model drift in production typically shows up within three to six months for most business datasets.

Chasing accuracy instead of value. A 94% accurate model that costs fifty thousand dollars to build and maintain might be worse than an 87% accurate model you can run on existing infrastructure with zero additional cost. Calculate the actual return, not just the metric.
Tools That Actually Work
For smaller datasets, Python with scikit-learn and pandas is fine. For larger scale, Spark MLlib or Databricks. I avoid heavy GUI tools for anything beyond basic exploration because they lock you into their workflows and you hit limits fast. If you need visualization, use a separate tool like Tableau or Power BI for the final presentation layer. Keep your modeling environment script-based. For the business modeling side, entity-relationship diagrams and process flow maps are essential before you write a single line of code. I spend at least a day mapping out what entities exist, how they relate, and what decisions each pattern should inform. This cuts model iterations significantly because you're not discovering structural problems during implementation.
The Hard Truth
Most business modeling projects fail not because the math is wrong but because nobody defined what success looked like before starting. Get that right. Everything else is just execution.