The Reality of Picking a Location Without Driving Every Corner
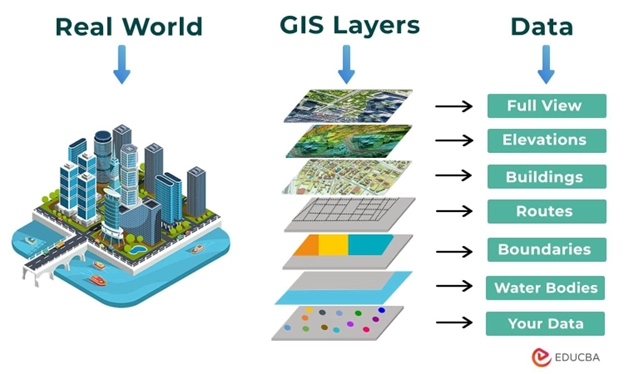
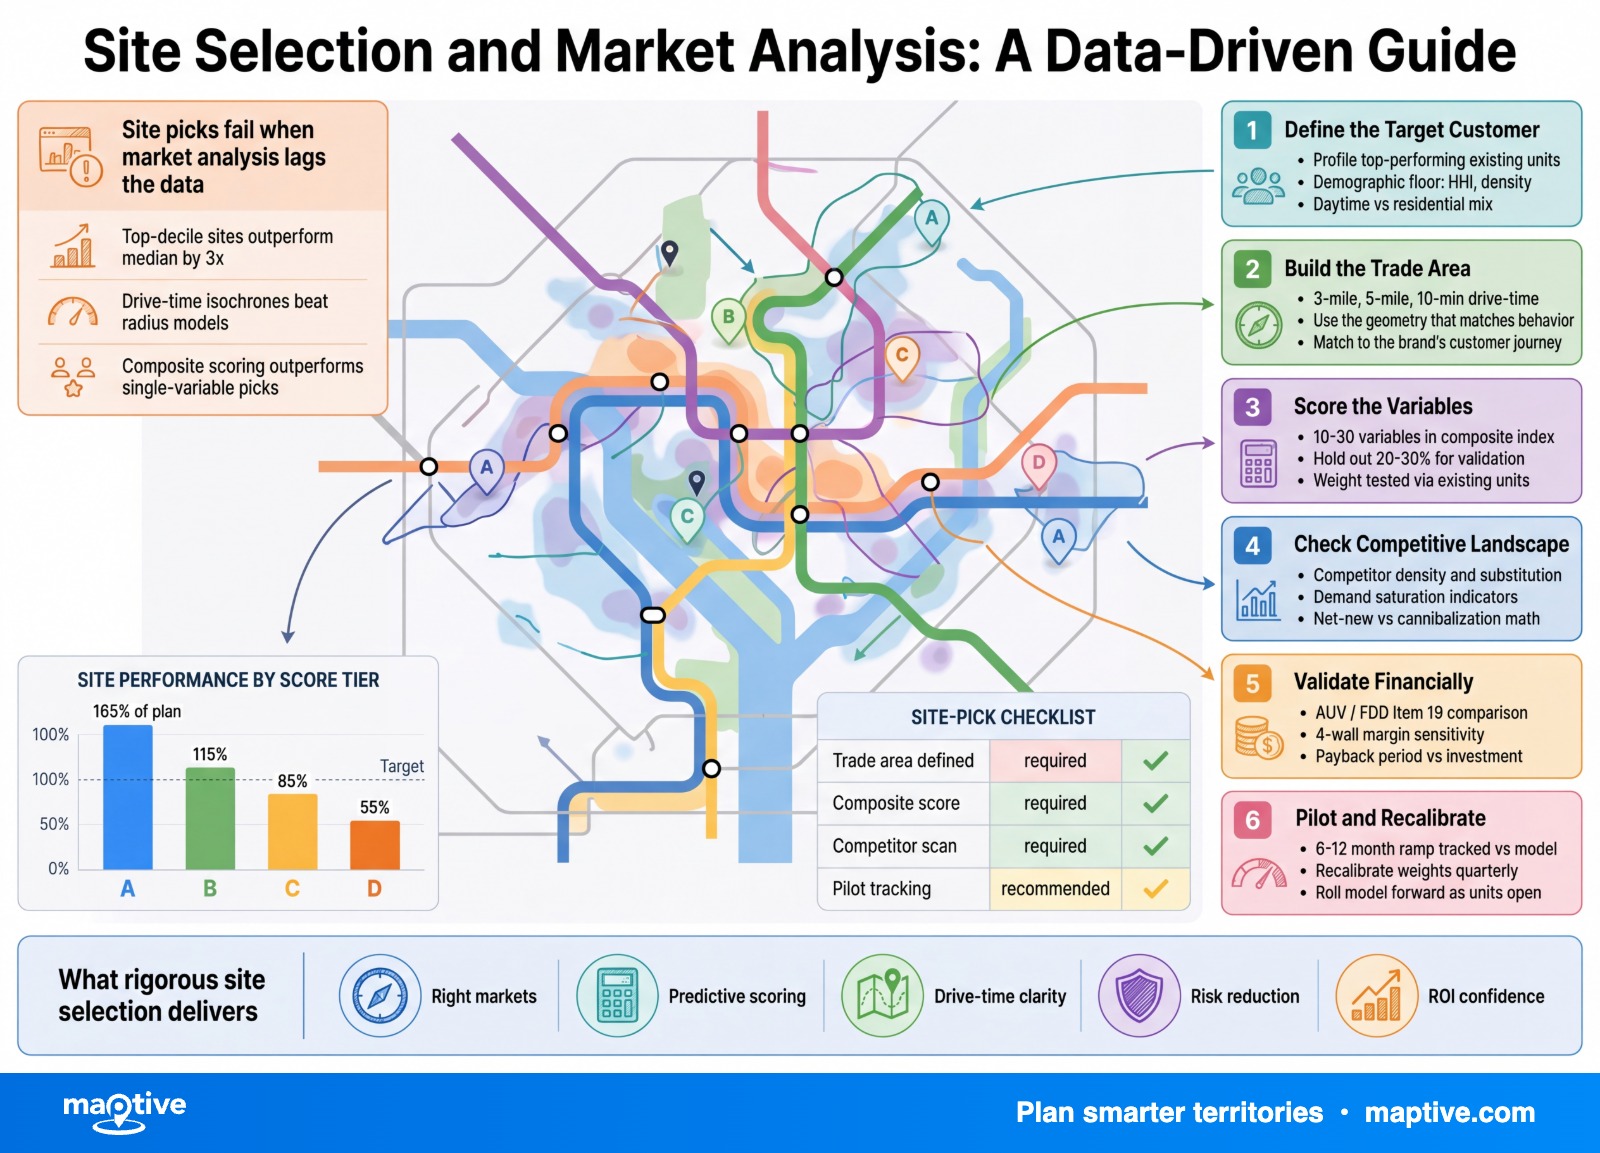
Picking where a business should open is usually done with a mix of gut feeling and half-remembered market research. That approach works fine for small decisions, but it breaks down fast when you are comparing three cities or evaluating dozens of trade areas. This is where GIS changes the conversation from speculation to measurable data. I have spent years building site selection models for retail, medical, and logistics clients, and the pattern is always the same. The people who understand GIS end up with a defensible recommendation. The people who skip it end up arguing in meetings about whether a neighborhood is "up and coming." At its core, this process combines geographic data with business metrics to answer a straightforward question. Which location delivers the best outcome for a specific type of business given real constraints? It is not about finding the cheapest plot of land. It is about finding the spot where demand, access, competition, and cost align. Most people start by loading a base map into QGIS or ArcGIS and then layer on demographic data from the Census or Esri. That is the easy part. The actual work happens when you start building buffers, calculating drive times, and filtering out places that look good on paper but fail under pressure. I recently worked on a project where the client wanted to open a urgent care facility in a mid-sized metro area. The initial model pointed to a suburban corridor because the population density numbers were strong and the median income was above average. We ran drive-time analysis and discovered the primary corridor had a single bottleneck intersection that added twelve minutes during peak hours. Patients considering urgent care care about time more than demographics. I reran the analysis with a network-based travel time layer instead of straight-line distance, and the top recommended site flipped to a different submarket entirely. The demographic numbers there were slightly weaker, but the accessibility was dramatically better. That decision saved the client from signing a lease in a location that would have looked good in a report but performed poorly in reality.
How the Analysis Actually Works in Practice
The first step is defining what success looks like for the specific business type. A grocery store cares about different variables than a warehouse or a coffee shop. You need to write down the factors that matter before you open any software. Typical variables include population within a drive-time radius, household income, age distribution, traffic counts, competitor proximity, visibility from the road, and lease or purchase cost. Once you have that list, you pull the relevant datasets and clean them. Data cleaning is where most projects stall because people assume the data is ready when it almost never is. Traffic count data is usually published at the county or regional level and does not align with the exact road segment you are evaluating. I have spent entire afternoons matching state DOT traffic reports to local street centerlines because the road names changed between datasets. The workaround is straightforward. You import the traffic data, join it to your road network using a consistent identifier like a route number or Functional Class code, and then interpolate values for missing segments using adjacent roads with known counts. It takes patience, but it prevents the model from assigning unrealistic traffic exposure to a site. Buffer zones are the most common tool in this workflow. You draw a ring around a candidate location and summarize everything inside it. A five-minute drive-time buffer for a quick-service restaurant will yield very different results than a one-mile walking buffer for a neighborhood pharmacy. The choice of buffer method matters more than most analysts realize. Straight-line buffers are fast but often inaccurate. Network-based buffers respect actual roads and intersections. They take longer to calculate, but they reflect what customers actually experience. If you are evaluating multiple sites, I recommend running network buffers first on your top candidates rather than the whole region. It cuts processing time significantly while still giving you reliable results for the decisions that matter.
Common Pitfalls That Cost Real Money
One issue I see repeatedly is over-reliance on demographic aggregates. Census tracts smooth out local variation. A tract might show strong household income, but the high-income households could be clustered on one side of a major highway while the candidate site sits on the other side in a completely different market segment. I learned this the hard way on a retail expansion project. The model recommended a site based on tract-level income data. The client drove past it during a weekend afternoon and immediately saw that the surrounding businesses served a different customer base entirely. The demographics were correct at the tract scale, but irrelevant at the parcel scale. The fix was to overlay consumer spending data at a finer geographic resolution and validate the model against actual point-of-sale records from nearby stores. That step took an extra day but eliminated the mismatch. Another frequent mistake is treating competitor data as a simple exclusion zone. People often draw a buffer around every existing competitor and mark anything inside it as undesirable. That logic works for some business types but fails for others. A shopping center strategy benefits from clustering. A standalone hardware store does not. The correct approach depends on whether the business is complementary or substitutive. I build a simple variable into my models that classifies competitors as attractive or repelling based on the business type, then weight their proximity accordingly instead of applying a blanket exclusion.
Get the Full Details

Tools and Where to Get Them
You do not need expensive software to run a solid site selection analysis. QGIS is free and handles most of the core functions. The process involves loading vector layers, creating buffers, performing spatial joins, and running basic statistics. For network analysis, you can use the Road Graph plugin or process data through OpenStreetMap and OSRM to generate drive-time polygons. If you are working in a corporate environment, ArcGIS Online provides built-in drive-time analysis tools that are faster to set up, though they require a subscription. Esri also publishes demographic datasets through ArcGIS Living Atlas, which integrate directly with their platform. For traffic data, state Department of Transportation websites are the standard source. Most publish annual traffic counts by road segment, though the formats vary wildly. I keep a spreadsheet tracking which states provide downloadable CSV files and which require contacting their GIS office directly. Pennsylvania and Ohio have relatively clean datasets. Some southern states still require a formal data request that takes three to six weeks to process. If you are on a tight timeline, flag that early and request access before you build the rest of the model.
What This Method Cannot Do Well
GIS models produce probabilities, not guarantees. The output is only as reliable as the input data, and demographic forecasts drift over time. An Esri forecast published in 2024 will look different from the actual 2026 counts, especially in areas experiencing rapid development or population decline. I treat model scores as directional guidance rather than absolute truth. When a client asks me to rank five sites, I give them the ranked list but I also point out the top two uncertainties and recommend a site visit to validate the assumptions on the ground. The method also struggles with informal or emerging markets. A neighborhood that is not yet captured in commercial demographic datasets might be growing fast due to a new transit line or a policy change. GIS will not predict that unless you feed it the underlying infrastructure data. In those cases, I supplement the model with planning department meeting minutes, building permit databases, and local news monitoring. Those sources are unstructured and time-consuming to parse, but they fill gaps that pure spatial analysis cannot reach. Finally, cost data is often the weakest link. Commercial lease rates, property taxes, and utility costs vary block by block and rarely exist in clean GIS-ready formats. I usually pull this from brokerage reports and municipal assessor databases, then merge it manually where automated joins fail. It is tedious work, but skipping it produces recommendations that look optimal on a map and fail during lease negotiation.