How to Actually Prepare for a Business Statistics Final
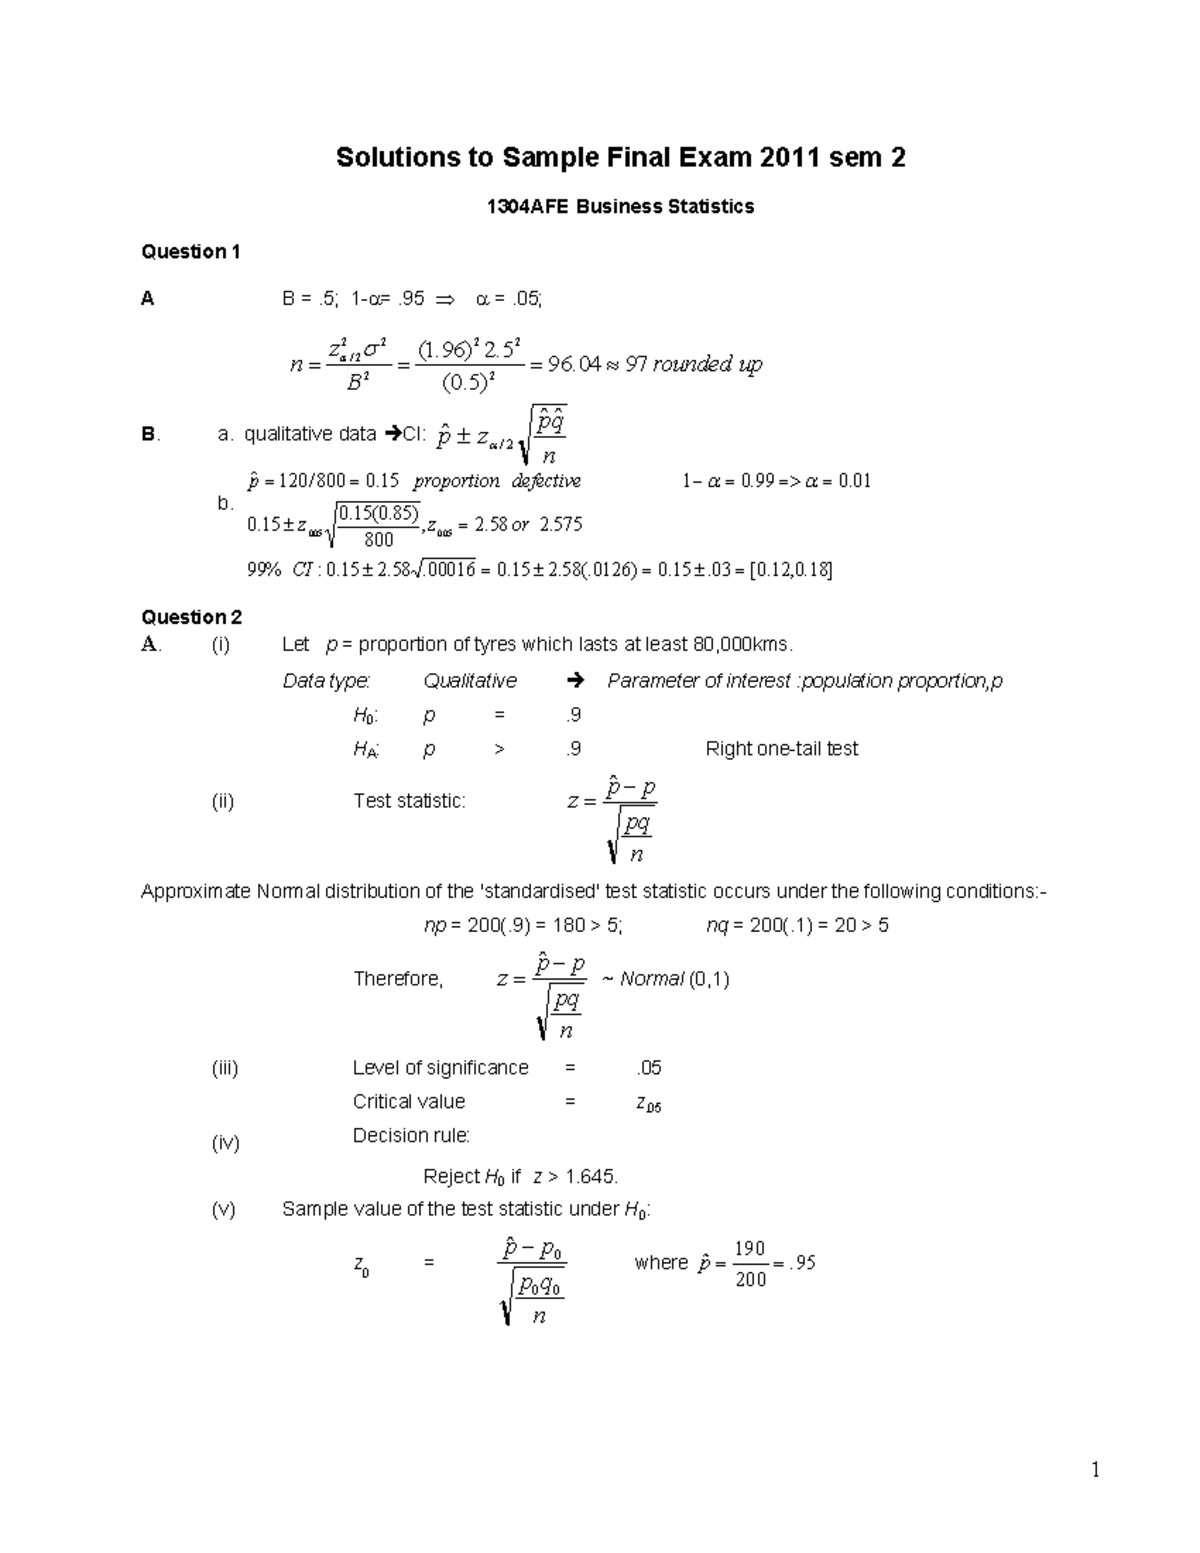
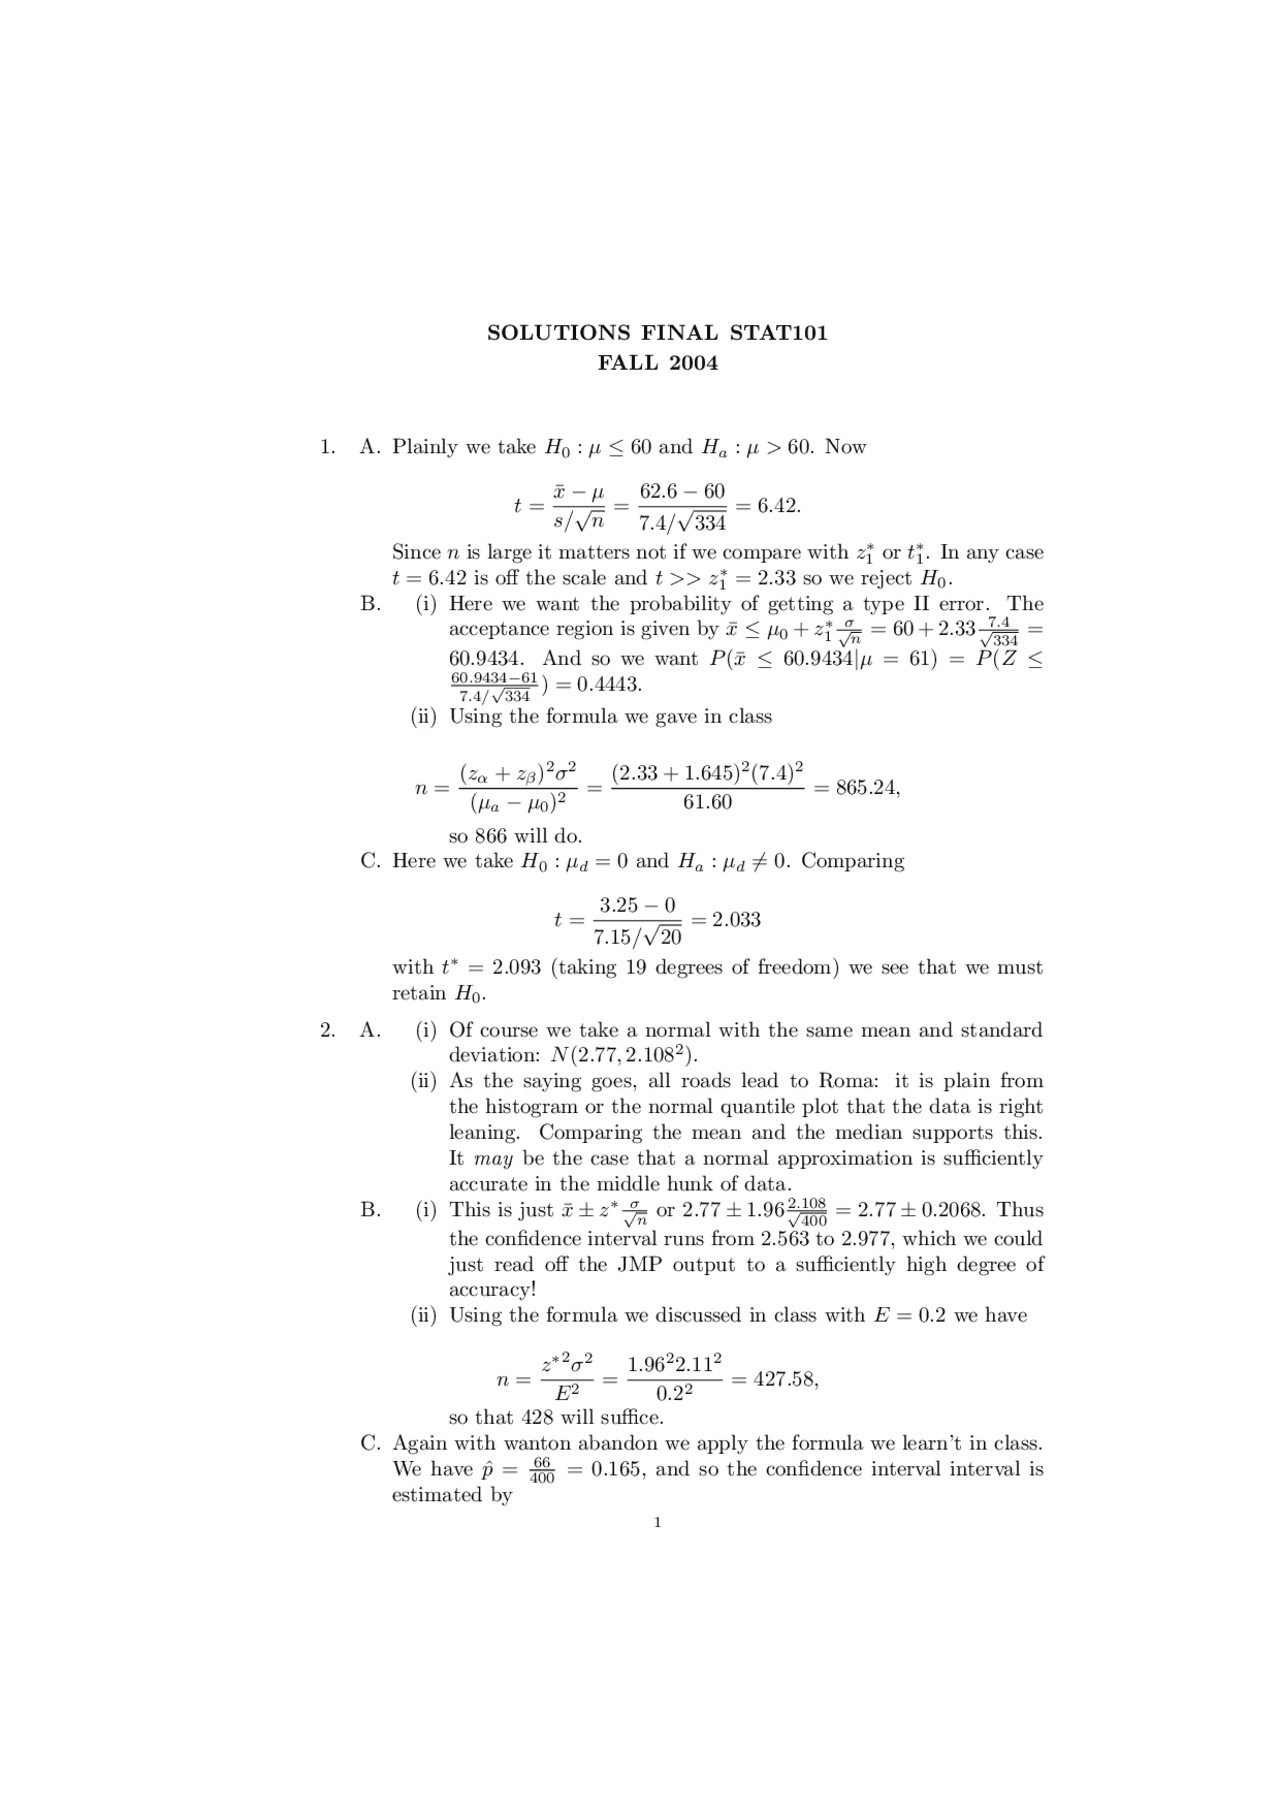
I spent years watching students fail the same exam over and over, not because the material was impossible, but because they were studying it wrong. The exam tends to test your ability to apply concepts under time pressure, not your memory of definitions. Most people memorize formulas and then freeze when a problem doesn't look exactly like the practice set. Here is how I would approach it if I had six weeks. You can find detailed walkthroughs for most standard curriculum topics on course-specific forums, university resource pages, and study platforms. The ones worth your time are the ones that show every computational step, not just the final answer. When I was helping people prep, I noticed the best solutions included notes on why a particular test was chosen over another. That distinction matters more than you would think on a timed exam. I will be honest about where this falls apart. A lot of the free solutions online are inaccurate or use outdated software outputs. SPSS, R, and Excel all report p-values slightly differently depending on version, and some posted answers copy-paste from older editions. I always recommend cross-checking any solution you find against at least two sources, or better yet, against your own calculation done by hand first. The only time I stopped checking was when a solution came from an official course repository or a professor's posted answer key.
One specific edge case I remember clearly involved a confidence interval problem where the textbook answer assumed a population standard deviation was known, but the problem statement actually gave you a sample standard deviation with n less than 30. The posted solution used a z-interval throughout. Using a t-interval instead changed the margin of error enough to flip the correct answer choice. I had three students each lose points on that exact question in different semesters. The workaround was simple: if n is under 30 and sigma is unknown, never default to z without explicitly confirming the problem statement gives you the population parameter. It is easy to miss in the noise of a long word problem.
What the Exam Actually Tests
Most business stats finals are built around a handful of core competency areas. Hypothesis testing, confidence intervals, regression analysis, and ANOVA make up the bulk of the score. What surprises people is how much weight is placed on interpreting results, not just computing them. You will get points for stating whether you reject or fail to reject, for explaining what that decision means in context, and for identifying the type of error you might have made. Skipping the interpretation section is the fastest way to bleed points. Regression questions tend to appear in two flavors. One asks you to run a multiple regression and interpret coefficients. The other gives you output and asks you to diagnose problems. The diagnostic version is where most students struggle. They know what R-squared means. They do not know what to do when residual plots show a funnel shape, which signals heteroscedasticity, or when the Durbin-Watson statistic comes back near 1.5 in time-series data, which suggests positive autocorrelation. Both of these will invalidate your standard errors if you ignore them. Here is something counter-intuitive that I see people miss repeatedly. A higher R-squared does not mean your model is better. It just means you are explaining more variance in the sample. If you add enough irrelevant predictors, R-squared will keep climbing while your adjusted R-squared drops and your predictions get worse out of sample. Professors love to include a question where you have to choose between two models based on adjusted R-squared, AIC, or cross-validation results rather than raw R-squared. Picking the wrong one because you defaulted to the highest R-squared is a common mistake.
Get the Full Details

Study Structure That Actually Works
The most efficient approach I have seen people use involves three phases over roughly four to six weeks. Phase one is skill drilling. You work through fifty to eighty problems covering each major topic, focusing on problems that mix concepts rather than isolating them. Phase two is simulation. You take a full timed exam under realistic conditions, no notes, no calculator apps that show steps. Phase three is gap analysis. You grade yourself harshly, identify which question types cost you points, and drill those specifically. When I did this with students who were behind, I usually had them start with hypothesis testing because it connects to everything else. Understanding the logic of null and alternative hypotheses, Type I and Type II errors, and power carries directly into ANOVA and regression significance tests. If you skip that foundation, later topics feel like memorization instead of application. One practical tip that saves real time: learn to read statistical tables quickly. Many exams still allow or require tables for t, chi-square, and F distributions. Being able to interpolate between degrees of freedom and find critical values without pulling out a formula sheet cuts several minutes off calculation-heavy sections. I timed myself doing this during practice and it shaved about eight minutes off a three-hour exam for most students.
Common Pitfalls and How to Avoid Them
The first pitfall is mixing up one-tailed and two-tailed tests. A one-tailed test only makes sense when your alternative hypothesis explicitly states a direction, like mu is greater than a value. If your hypothesis is just mu is not equal to something, that is two-tailed. Using a one-tailed critical value on a two-tailed problem halves your alpha incorrectly and increases your chance of a Type I error. I have seen this cost people entire sections on midterms and finals. The second pitfall is misunderstanding what a p-value actually tells you. A p-value of 0.03 does not mean there is a 3 percent chance the null hypothesis is true. It means that if the null hypothesis were true, you would observe data this extreme or more extreme in about 3 percent of repeated samples. Students who confuse these two statements tend to write incorrect interpretations on open-response questions and lose points even when their calculation is right. A third issue shows up with paired versus independent tests. When you have before-and-after measurements on the same subjects, you use a paired test. Treating those observations as independent inflates your sample size artificially and understates the standard error. I ran into this when a student analyzed a marketing campaign study where the same customers were surveyed before and after a price change. They ran an independent two-sample t-test and got a significant result. Switching to a paired test removed the significance entirely. The effect size was real but the variability within subjects was high enough to erase it.
Tools and Resources Worth Using
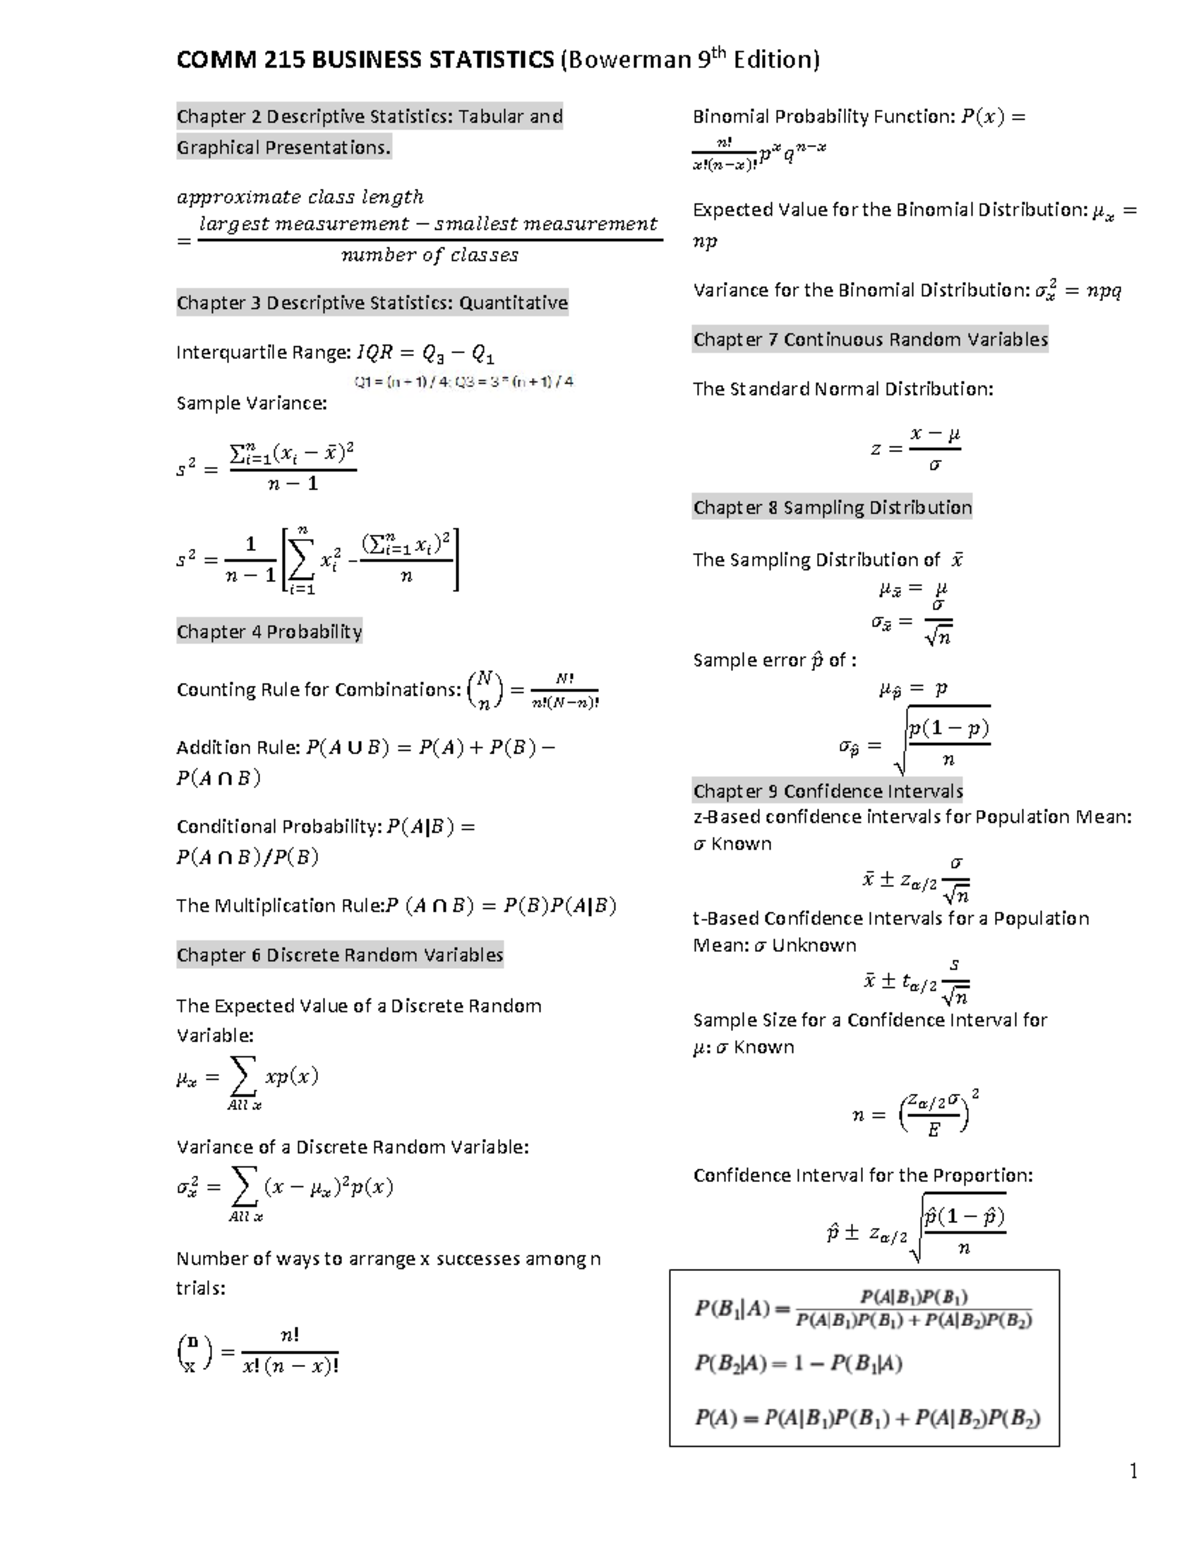
For computation practice, Excel with the Analysis ToolPak is fine for basic problems. R is better for anything involving regression diagnostics or bootstrapping. If your course uses SPSS, get comfortable navigating the output window and learning where to find significance values, confidence intervals, and effect size measures like eta-squared. Knowing where to look saves time during the exam if calculators are restricted. There are also free problem sets from open courseware programs at several universities. MIT OpenCourseWare and a few state universities post final exams with solutions. The MIT materials tend to be more math-heavy, so check whether your course aligns with that level. Some business stats courses are applied and light on proofs. Going too theoretical in your prep can waste time you need for practice problems. I also recommend keeping a formula sheet that you write yourself, even if you are allowed one during the exam. The act of writing it forces you to organize the formulas by use case rather than alphabetically, which makes retrieval faster under stress. Mine had columns for test type, assumptions required, formula, and a one-line note on when to use it. It took about two hours to build and probably saved me twenty minutes on exam day.
When Statistics Approaches Fail
Standard parametric tests assume normality, homogeneity of variance, and independence. Real data rarely satisfies all of these perfectly. If your sample size is small and your data is heavily skewed, a t-test may give misleading results. In those cases, a nonparametric alternative like the Mann-Whitney U test or the Wilcoxon signed-rank test is more appropriate. Exams sometimes include a question where the data clearly violates assumptions and you have to decide whether to proceed with the parametric test anyway or switch methods. Knowing the thresholds matters. For normality, Shapiro-Wilk is sensitive with large samples, so with n above 50 even minor deviations will reject normality. In those situations, the Central Limit Theorem often saves you for means-based tests if the sample is reasonably balanced. Heteroscedasticity is another area where standard approaches break down. If your residuals spread out as predicted values increase, your confidence intervals and p-values are unreliable. The fix is usually a transformation of the dependent variable or using robust standard errors. On an exam, you may only be expected to identify the problem and name a remedy, but recognizing the pattern in a residual plot is itself a skill that separates people who pass from people who memorize. Correlation does not imply causation, but exam questions sometimes present observational data and ask you to draw causal conclusions. This is a trap. If the study design is observational rather than experimental, you should flag confounding variables and note that causation cannot be established. Professors include these questions to catch people who are rushing through and treating every significant correlation as evidence of a causal link.
Final Thoughts on Preparation
The exam is manageable if you treat it as a skills test rather than a memorization test. Work through problems actively. Grade yourself honestly. Focus on interpretation and assumption checking more than computation speed. The people who do well are usually the ones who spent time understanding why a method works instead of just how to run it. Good luck with it.