What Human + Machine Actually Means for Your Organization
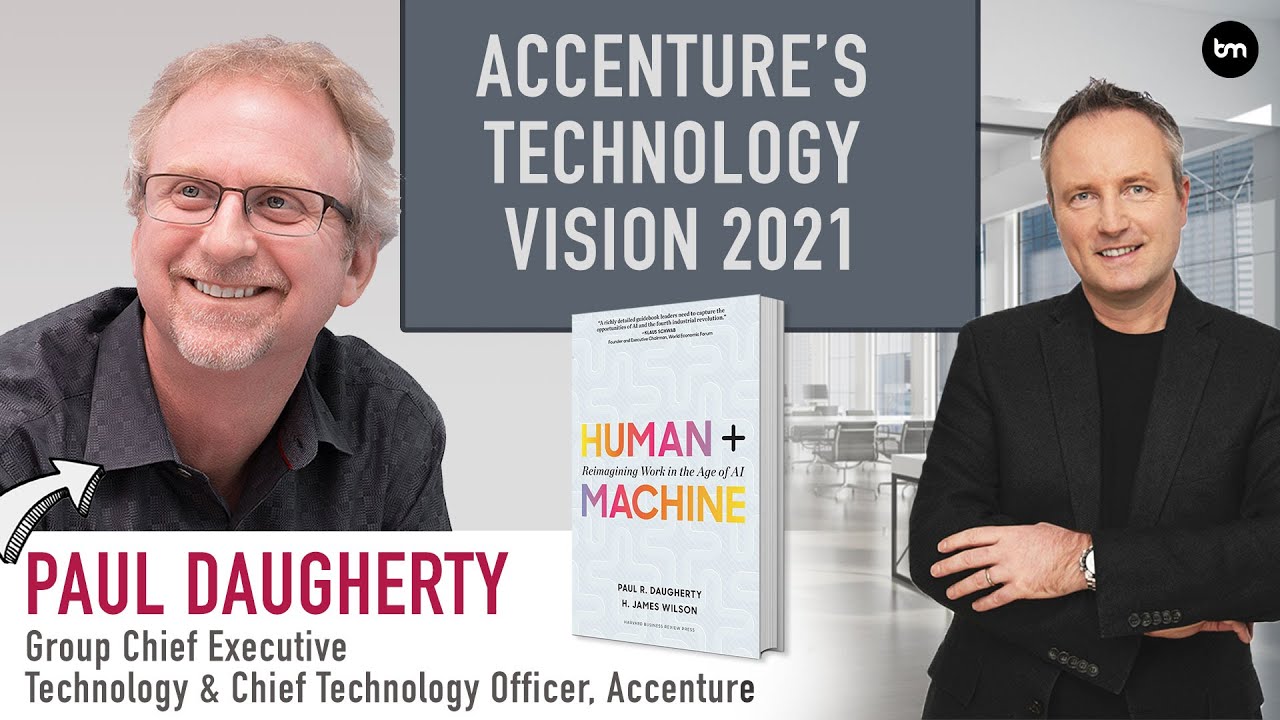
Mark Purdy and Paul Daugherty wrote Human + Machine: Reimagining Work in the Age of AI while at Accenture, and it was one of the earlier serious attempts to move past the hype cycle around artificial intelligence in enterprise settings. Their central argument is straightforward enough: AI won't replace humans wholesale, but it will reshape which tasks humans perform and how organizations structure work around machine capabilities. The framework they developed categorizes AI applications into four types of business outcomes: increased human productivity, deeper customer insight, new revenue streams, and improved operational efficiency. What makes this useful in practice is that most companies I've seen attempt AI projects without first deciding which outcome they're actually chasing. They buy the tool before they define the problem. Their concept of "intelligent augmentation" — the idea that machines should handle structured, repetitive cognitive work while humans take on ambiguous, empathetic, and judgment-heavy tasks — has held up reasonably well. It's not a new idea, but it gave enterprise leaders a vocabulary they could use internally when pushing back against both Silicon Valley-style replacement narratives and equally unrealistic utopian ones.
I spent a while working with a mid-size logistics firm that wanted to deploy AI across their operations based on a vendor pitch promising full automation. What they actually needed was a targeted augmentation strategy around claims processing and routing optimization. The vendor didn't care about that distinction. The framework helped us reframe the project, which cut the scope down to three real use cases instead of nine vague ones and saved them about fourteen months of failed pilot work.
How the Framework Works in Practice
The model suggests that organizations should map their work into "tasks" rather than "jobs" and then evaluate which tasks are better suited to machines and which remain human domain. Machines win on tasks that involve high volumes of pattern recognition, rapid computation, or data at scale. Humans retain advantage on tasks requiring contextual judgment, interpersonal dynamics, or novelty under uncertainty. This sounds obvious until you try to apply it. Most organizations don't actually break down work into discrete tasks. Their job descriptions are inherited from eras before these questions were even on the table. The real friction point is getting people to document what they actually do day-to-day versus what their org chart says they do. One specific issue I ran into involves the measurement problem. You can't evaluate whether a task is better handled by a human or machine without baseline performance data for both. I found this repeatedly in client engagements where leadership assumed AI would improve accuracy without existing error-rate baselines. We ended up running a sixty-day manual tracking exercise before we could make any credible case for automation, and most of those initial automation proposals collapsed under that scrutiny. The ones that survived usually delivered measurable gains within ninety days of deployment.
Get the Full Details

Common Misunderstandings
There are a few misconceptions that keep coming up whenever this framework gets discussed in executive rooms. First, the framework is not a technology selection tool. It doesn't tell you which platform to buy or which algorithm to implement. It tells you where to look for opportunity. Buying decisions come later and require entirely different evaluation criteria. Second, the human-plus-machine proposition isn't permanent. As models improve, tasks that once required human judgment shift into machine territory. The framework anticipates this but doesn't provide a built-in mechanism for tracking that shift over time. You need a separate governance process to revisit those task assignments periodically, typically on a quarterly basis in fast-moving domains.
Third, there's a tendency to treat this as a top-down initiative. In practice, the most durable implementations I've seen started with individual teams identifying their own augmentation opportunities rather than receiving mandates from a central AI office. Central coordination helps with standardization and scaling, but it rarely surfaces the ground-truth task breakdowns that make the framework useful.
Where It Falls Short
The framework has limitations that aren't always acknowledged. It was developed primarily from technology-sector and professional-services contexts, so its task-automation assumptions don't translate cleanly to highly regulated industries where compliance constraints dominate decision-making. A bank's credit approval workflow, for instance, isn't just about accuracy and speed. Regulatory requirements create structural barriers that pure efficiency frameworks don't account for. The framework also underplays the integration cost. Getting a machine-learning model to interact reliably with legacy systems, existing data pipelines, and established workflows is often ten times harder than the model development itself. Organizations that skip this reality tend to accumulate a graveyard of proof-of-concept projects that never reach production. If you're looking for a more operationally detailed guide, the original paper and subsequent Accenture research publications cover implementation pathways in more depth than the popular book version does. The book is better suited for leadership orientation. The technical reports are where you go if you're actually building something.

What to Do With This Information
The practical starting point is a task inventory. Pick one business function, document every discrete task within it, and rate each task on two axes: how much pattern-recognition work it involves versus how much contextual judgment it requires. Don't do this across the entire organization at once. Start small, validate the methodology, then expand. A function with a few hundred discrete tasks is a realistic starting scope for a first pass. From there, identify the highest-volume pattern-recognition tasks that also have available labeled data. Those are your earliest candidates for augmentation. Skip everything else until you have production results from those. The framework gives you a lens. It doesn't replace the actual work of building, testing, and iterating on specific use cases.