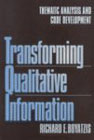
Working Through Boyatzis's Coding System in Practice
I spent three solid weeks trying to get my coding to match what Boyatzis describes before I actually understood what the book was asking you to do. Most people skim past the mechanical part and jump straight into examples, but the mechanical rules are where everything either works or falls apart. I had a dataset of about 40 interview transcripts on professional development and I kept getting codes that looked good on the surface but collapsed under scrutiny because I wasn't tracking the transformation properly. The core idea is straightforward enough. You take qualitative data — interview transcripts, field notes, open-ended survey responses — and you transform it into something structured enough to analyze systematically. The transformation happens through a cycle: describing, categorizing, and thematic analyzing. You start with raw descriptions, you assign codes to pieces of text, you group those codes into categories, and then you look for broader themes that connect across categories. It sounds simple because the concept is simple. The execution is where people waste time. The book gives you a very specific workflow. First, you go through your data and produce exhaustive descriptions of whatever phenomenon you're studying. Not interpretations yet — just descriptions. Then you code those descriptions. Each code should be distinct and mutually exclusive where possible. After that, you cluster codes into categories based on shared properties. Finally, you identify themes that emerge from the relationships between categories.
Here's what the book doesn't emphasize enough: the difference between a code and a category. I learned this the hard way. Early on, I was treating every code as if it were already a category. My codes were things like "frustration with management" and "desire for more autonomy." Those aren't codes — those are almost-themes. Real codes should be smaller, more granular units of meaning. Something like "employee expressed dissatisfaction with top-down decision-making" would be a code. "Frustration with management" is what you get when you skip the descriptive stage and jump straight to interpretation. The mutual exclusivity rule is another thing people get wrong. Boyatzis insists that codes shouldn't overlap, but in practice, almost every code will overlap with something else at some point. What he really means is that each code should have a clear definition and decision rules for when it applies and when it doesn't. I spent two days reworking my codebook because I hadn't written definitions for any of my codes. Once I added them, the whole analysis became ten times faster because I stopped second-guessing whether a particular excerpt belonged in one category or another. One specific problem I ran into: I had a section of transcript where the participant kept circling back to the same topic but using different language each time. "It was hard," "I didn't know what to do," "Nobody helped me." I wanted to code all three differently, but they were clearly the same underlying phenomenon. The workaround was to create a parent code called "perceived lack of institutional support" and then subsume those three phrases under it with clear inclusion criteria. That's the mechanical discipline the book pushes for — define before you generalize.
The thematic analysis stage is where the method shows its real value. You're not just listing categories anymore. You're looking for connections between them. This is where you find out whether your data actually supports the story you thought it was going to tell. I had a case where two categories I was convinced were related turned out to be largely independent in the data. That meant rewriting my entire analysis framework. Uncomfortable, but correct. A counter-intuitive point: the more detailed your initial descriptions, the faster your later stages go. It feels backwards. You want to get to the coding and thematic part quickly because that's where the interesting work is. But skimping on descriptions creates a backlog of ambiguity that slows everything down. I compared my first round of coding, where I'd rushed the descriptions, against a second round where I slowed down and wrote proper descriptions for a subset of the data. The second round took less total time and produced significantly cleaner categories. The upfront investment paid off within about forty-five minutes per transcript. The mechanical cycle Boyatzis describes — describe, categorize, theme — is really the only thing you need to remember. Everything else is just applying it consistently. Go through your data multiple times. Don't force categories that don't exist. Let the themes emerge from the data rather than imposing them from the top down. These are obvious in isolation but easy to abandon when you're tired, which is most of the time during a real analysis.
Get the Full Details

Limitations are worth being honest about. This approach doesn't scale well to very large datasets. I tried applying it to over two hundred transcripts and the mechanical cycle became impossible to maintain without losing accuracy. For larger projects, you need to either sample strategically or pair this with a more quantitative approach. The method also assumes you're comfortable sitting with raw data for a long time without jumping to conclusions. If you're the type who needs to produce preliminary findings quickly to justify continued effort, this process will feel painfully slow. There's no shortcut around that. Another gap: the book assumes a certain level of familiarity with qualitative research terminology. Terms like "coding," "categories," and "themes" are used in fairly specific ways that won't match how they're used in other methodology traditions. If you've worked with grounded theory or content analysis before, you'll need to unlearn some habits and relearn others. The mechanics are the same but the definitions shift slightly, and that causes friction if you're not aware of it. I don't have a download link for the book — it's a published academic text you'd pick up from a retailer or library. What I can say is that the first edition is still the authoritative version on this particular method. Later editions exist but the core mechanical framework hasn't changed. If you're going to use this approach, read the chapters on the coding process slowly and then go back and apply them to a small subset of your data before committing to the full dataset. You'll save yourself a lot of rework.
The method works. It's not glamorous and it won't make your analysis look impressive on its own, but it produces results that hold up under scrutiny. That's usually what matters in the end.