Setting Up a Combined C and SQL Development Environment
I spent years maintaining a codebase where C programs talked to PostgreSQL databases using the libpq library. The setup was messier than most tutorials suggest because everything depends on your platform, compiler version, and whether you want static or dynamic linking. I will walk through the approach I ended up using after two days of fighting with missing symbols and header path nightmares. C gives you direct control over memory, sockets, and system calls. SQL gives you structured persistence. When you combine them, you are essentially building the kind of application layer that most ORMs abstract away. Understanding both means you can spot why a query is killing performance instead of just throwing more indexes at the problem. It also means you stop treating your database as a black box and start understanding what happens between your application and the storage engine. First, make sure you have a C compiler that actually works on your system. For Linux users, gcc or clang with the development headers installed handles everything. For Windows, MinGW-w64 or MSYS2 gives you a realistic toolchain without fighting Visual Studio's build system. On macOS, Xcode command line tools are sufficient.
The critical step most people skip is installing the database client library headers. If you are using PostgreSQL, you need the libpq headers. On Ubuntu or Debian, that means running: sudo apt install libpq-dev On Red Hat systems:
sudo dnf install postgresql-devel For SQLite, which does not require a separate server process, you usually already have it. Check with pkg-config by running pkg-config --cflags --libs sqlite3. If that returns flags, you are good to go. When compiling, pass the include path and library flags directly. For PostgreSQL:
Get the Full Details

gcc program.c -o program $(pkg-config --cflags --libs libpq) This one command resolves the include directory and links the library. Do not try to manually type out the paths unless something is genuinely broken. Using pkg-config prevents the kind of silent mismatch where your code compiles against one header version but links against a different library version at runtime.
A Real Example That Actually Works
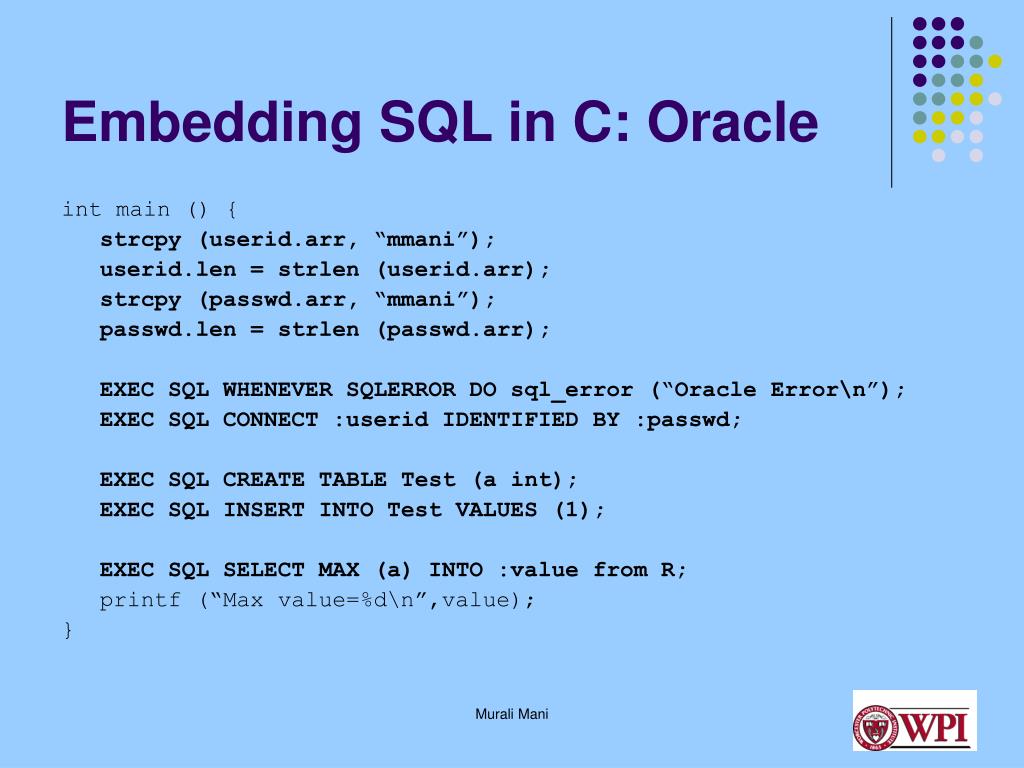
Here is a minimal C program that connects to a PostgreSQL database, runs a parameterized query, and prints results. I am showing this because the parameterized part is where most beginners get burned. The code looks like this: #include <stdio.h>
#include <stdlib.h>
#include <libpq-fe.h>
int main(void) {
const char *conninfo = "dbname=mydb host=localhost user=myuser password=mypass";
PGconn *conn = PQconnectdb(conninfo);
if (PQstatus(conn) != CONNECTION_OK) {
fprintf(stderr, "Connection failed: %s\n", PQerrorMessage(conn));
PQfinish(conn);
return 1;
}
PGresult *res = PQexecParams(conn,
"SELECT id, name FROM users WHERE age > $1",
1, NULL,
"25", NULL, NULL, 0);
if (PQresultStatus(res) != PGRES_TUPLES_OK) {
fprintf(stderr, "Query failed: %s\n", PQerrorMessage(conn));
PQclear(res);
PQfinish(conn);
return 1;
}
int nrows = PQntuples(res);
for (int i = 0; i < nrows; i++) {
printf("%s | %s\n",
PQgetvalue(res, i, 0),
PQgetvalue(res, i, 1));
}
PQclear(res);
PQfinish(conn);
return 0;
}
The key thing to notice here is PQexecParams instead of string concatenation for the query. Building SQL strings with sprintf or string concatenation is how injection bugs happen, and fixing them after the fact costs far more than doing it right the first time.

The Edge Case That Took Me Three Hours
Once, I deployed a program that worked perfectly on my machine and then failed in production with a silent data truncation. The issue was that I was using PQexecParams with a text-format query but the production database had a column defined as NUMERIC(10,3). When I fetched the result with PQgetvalue, PostgreSQL was returning the number in a format that included trailing zeros beyond what my display logic handled. The data was correct in the database but displayed wrong because I was treating all columns as plain strings. The workaround was straightforward once I found it: use PQftype to check the SQL type of each column before processing, and use strtod or atof for numeric columns instead of just printing the raw string. I wrapped the fetch logic in a small helper function that inspected the type OID and routed the conversion accordingly. This added about thirty lines of code but eliminated the entire class of silent data corruption bugs.
Common Pitfalls That Beginners Miss
The first pitfall is assuming that PQfinish closes the connection immediately. It sends a close request and frees the connection struct, but under heavy load or with certain connection pooling setups, the actual TCP teardown can be delayed. If you are running a batch process that creates and destroys connections rapidly, you will hit the database server's max_connections limit faster than expected. The fix is to reuse connections rather than opening and closing them per operation, or to use a connection pool like PGBouncer in front of your database. The second pitfall is ignoring error codes from PQresultStatus. Returning PGRES_COMMAND_OK for a SELECT query and PGRES_TUPLES_OK for an INSERT are different statuses, and treating them the same way leads to logic bugs. I used to check only for non-ok statuses and assume success, which meant I missed cases where a query returned zero rows but was still technically valid. Now I explicitly check the result status against the expected type for each operation. A third issue that deserves mention is the handling of NULL values. PQgetvalue returns a zero-length string when a column is NULL, not a NULL pointer. If your code dereferences the return value without checking PQgetisnull(res, row, column), you will get subtle bugs where NULL values appear as empty strings and your string processing logic treats them as legitimate data. This is easy to miss because the program runs without crashing, which makes it harder to diagnose than an outright segfault.
When This Approach Breaks Down
Hand-writing C code to talk to a database directly is not scalable for large applications. You will spend more time writing connection management, error handling, and type conversion code than you would using a mature ORM or query builder. For a small utility, a command-line tool, or a performance-critical service where you need to avoid the overhead of an abstraction layer, writing this by hand is reasonable. For anything with a complex schema or frequent schema changes, the maintenance cost adds up quickly. Also, C has no built-in support for async database operations. If your application needs to handle multiple concurrent requests while waiting on database responses, you will need to manage your own event loop or use a library like libevent alongside libpq. This adds significant complexity. For most modern web applications, a higher-level language with async database drivers is the more practical choice.
Learning Resources That Are Actually Useful
The official PostgreSQL documentation at postgresql.org/docs is the single best reference for C and SQL programming languages when working with libpq. The section on the C programming interface covers every function in detail with examples. For SQLite, the documentation at sqlite.org/docs has a clean API reference that is easier to digest if you are just getting started. Do not rely on tutorial videos for this. The interface changes relatively rarely, and written documentation stays current. When you do run into an issue, checking the source code of libpq itself or looking at how established open-source projects like PostGIS implement their C bindings tends to give you more accurate answers than any blog post will. Start by writing a small program that connects to a local database, runs a few different types of queries, and handles errors properly. Then add parameterized queries. Then add connection reuse. Each step introduces a new concept that compounds quickly if you skip ahead. The whole process from nothing to a working connection typically takes about two to three hours on a fresh setup, assuming your compiler and headers are already installed.