Working with quartiles in real data
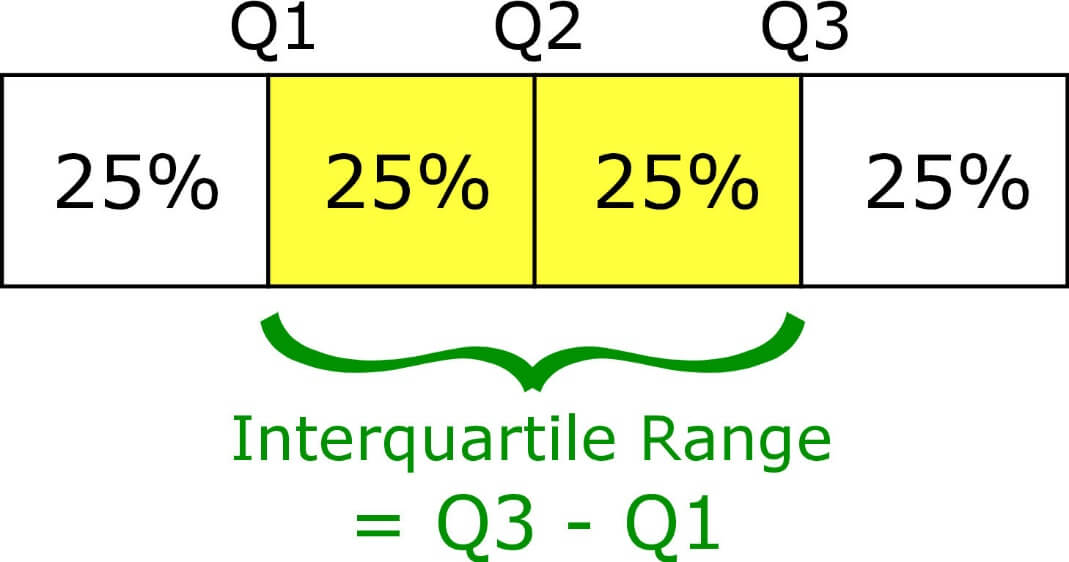
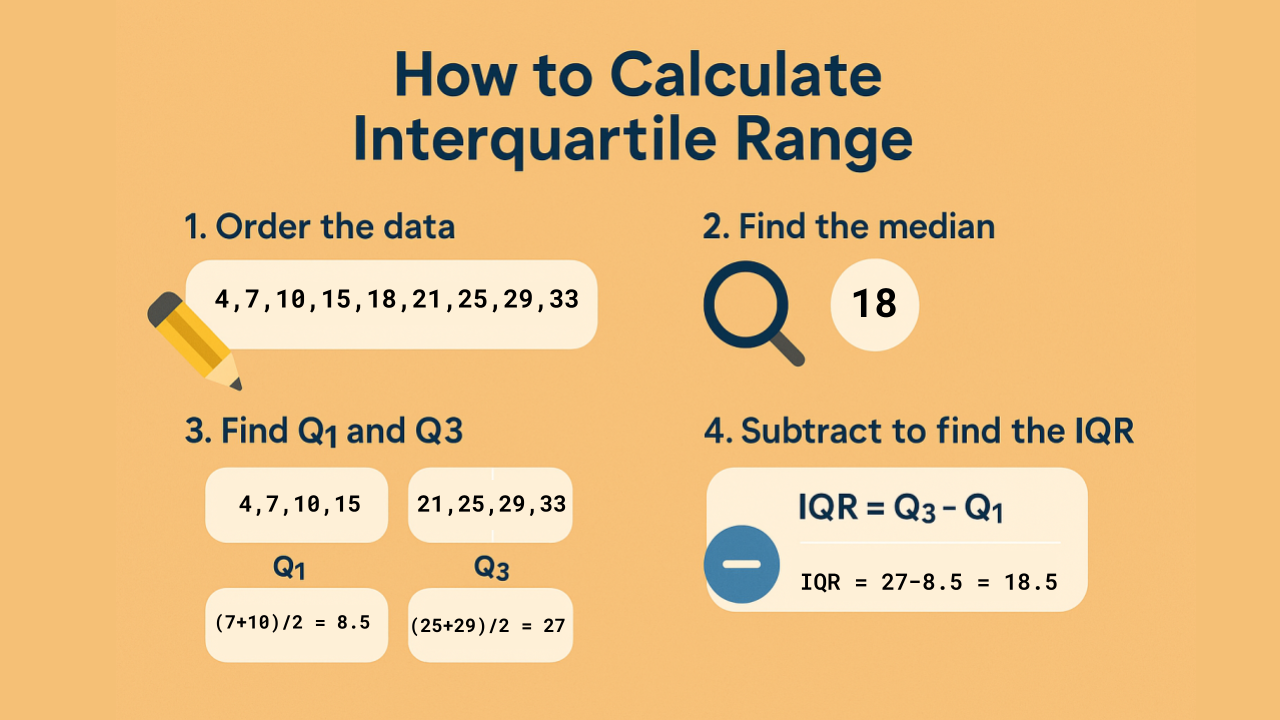
Most people learn the Inter Quartile Range in stats class and then never think about it again until they're looking at a messy dataset with outliers that are screwing up their analysis. The concept is straightforward enough, but the actual execution is where things get annoying. I need to walk through this the way I actually use it in practice, because the textbook version doesn't always match what happens when you open a spreadsheet or a SQL query. First, sort your data. This sounds obvious but it's the step most people skip when they're trying to do it quickly, and everything falls apart after that. Once sorted, you need Q1 and Q3. Q1 is the median of the lower half of the data, Q3 is the median of the upper half. The IQR is simply Q3 minus Q1. That's the whole thing. Here's where it gets messy though. What counts as the "lower half" when you have an odd number of observations depends entirely on which method you're using, and different tools handle this differently. Excel, Google Sheets, R, Python, SQL — they don't all agree. I learned this the hard way in 2019 when I was cleaning sales data for a client and the IQR they got from my Python script didn't match the one they computed in Excel. We spent three hours tracking down the discrepancy. It came down to method selection in how each tool interpolates quartiles with small datasets. I ended up writing a custom function that explicitly uses the exclusive method (method=2 in R terminology, type=2 in Python) because it matched what their finance team had been using in their model for years. That was a week I'd rather not get back.
Let me give you a concrete example with actual numbers. Take this dataset: 3, 7, 8, 12, 15, 19, 23, 27, 31, 35, 40. That's eleven values. Sorted. The median is 19, which sits right in the middle. Now the lower half is 3, 7, 8, 12, 15 and the upper half is 23, 27, 31, 35, 40. Using the exclusive method, Q1 is the median of the lower half — that's 8. Q3 is the median of the upper half — that's 31. The IQR is 31 minus 8, which equals 23. Any value below 8 minus 1.5 times 23 (so below -26.5) or above 31 plus 1.5 times 23 (above 65.5) would be flagged as an outlier. In this particular dataset there are no outliers, obviously, but the fence points are useful to know when you actually have real data that includes things like -$500 refund errors or $2 million one-off purchases. Here's something most tutorials don't tell you: the IQR is not a symmetric measure. It treats the upper and lower quartiles independently, which means you can have a very wide spread on one side and a tight cluster on the other and the IQR alone won't show you that imbalance. You should always look at Q1 and Q3 separately, not just their difference. A common mistake I see is people reporting only the IQR value and pretending it tells the whole story. It doesn't. It tells you the spread of the middle 50 percent, nothing more. Another thing that bites people: when you have duplicate values at the quartile boundaries, different interpolation methods will give you different results. The Minitab method, the Excel method, the Tufte method — they all handle ties slightly differently. If you're sharing results between teams using different tools, this inconsistency shows up as silent data quality problems. Someone flags a value as an outlier in one system and it's perfectly normal in another, and nobody notices because the IQR looks similar on the surface.
The bigger limitation with IQR is that it assumes your data has some spread. If you have a dataset where 80 percent of the values are identical — say, a survey where everyone answers "4" on a five-point scale — the IQR collapses to zero and becomes meaningless. You can't compute meaningful fences from a zero IQR. In those cases, look at the full distribution, use standard deviation if the data is roughly normal, or just accept that the metric you're analyzing has very low variance and move on. For practical use, here's what I usually do. I pull the data into Python with pandas, specify the method explicitly rather than relying on defaults, and print out Q1, Q3, the IQR, and both fence values in one shot. That way I can see the actual numbers and verify they make sense before I start flagging outliers. Taking five extra seconds to dump those values prevents hours of debugging later when someone asks why a legitimate data point got trimmed out.
Get the Full Details
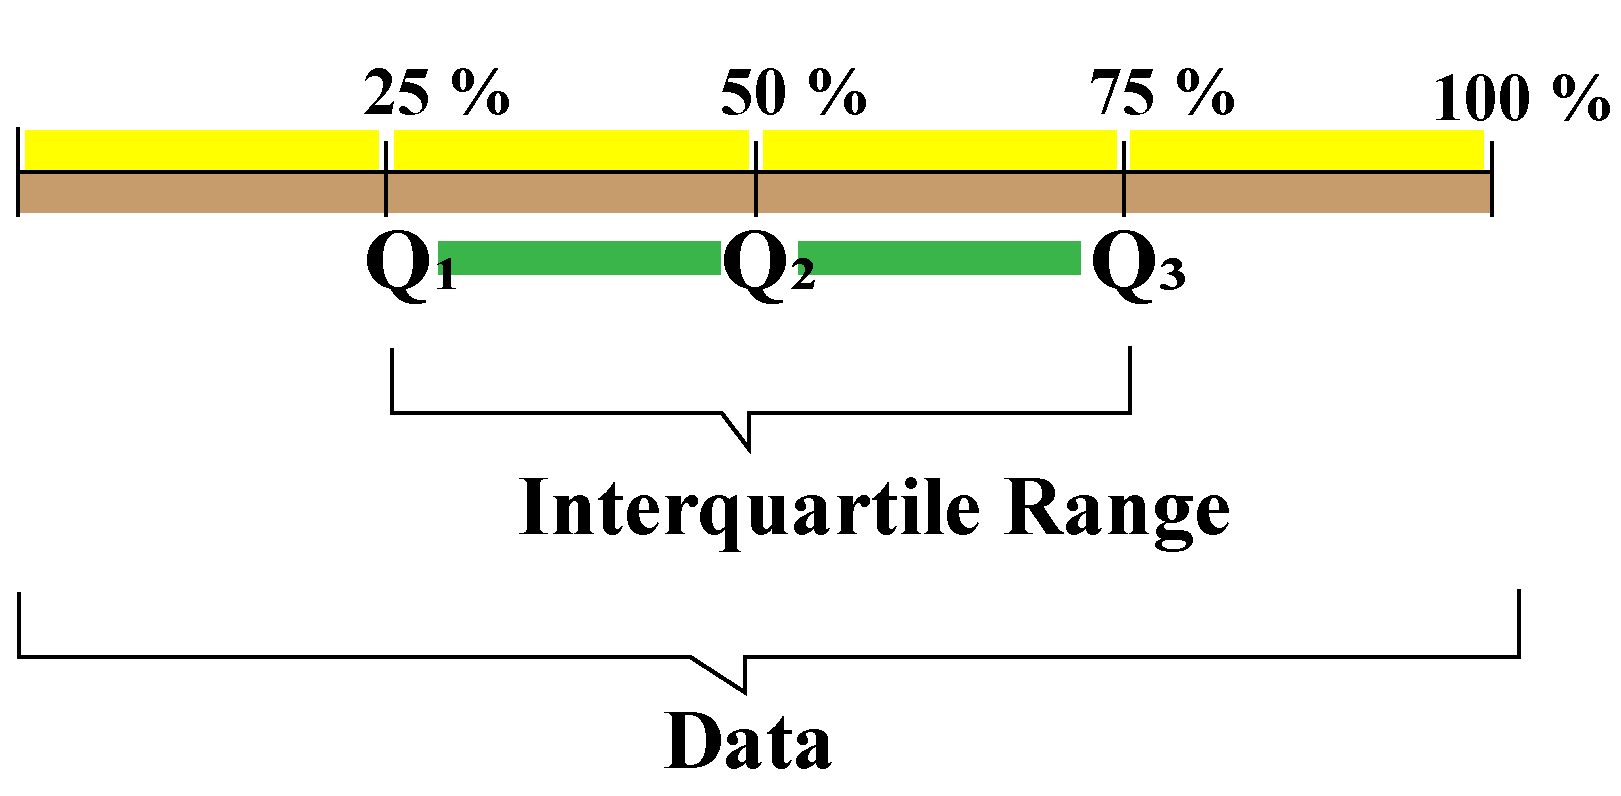
When the IQR breaks down
Binary data, heavily censored data, and small samples are where IQR stops being useful. With fewer than twenty observations, the quartile positions are so approximate that the result is barely more reliable than a guess. With censored data — say, survival analysis where many subjects haven't experienced the event yet — the upper quartile may sit in the censored region and the whole calculation loses its meaning. In those situations, parametric methods or bootstrapped confidence intervals give you something more defensible. The IQR is still one of the best quick diagnostic tools you have for identifying outliers without assuming a distribution. It's robust, it's fast, and it works on ordinal data where mean and standard deviation make no sense. Just be aware of where it's fragile and don't let the convenience of a single number convince you that you understand your data well.