How gradient descent actually works under the hood
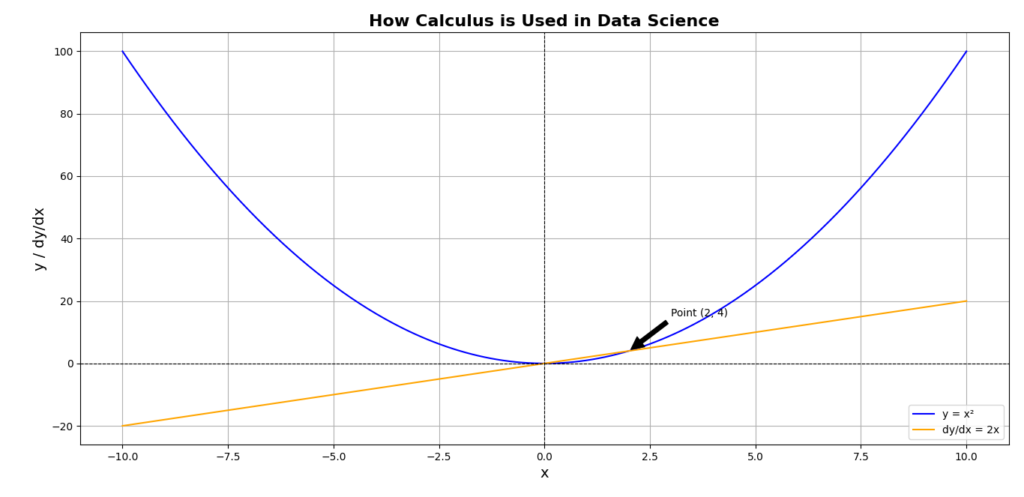
You probably learned calculus in college and then never thought about it again until you tried to train a neural network. The connection isn't obvious at first because most tutorials skip the math entirely and just say "the framework handles it." But if you want to understand why your model is diverging, or why certain learning rates work while others don't, you need to know what's happening beneath the surface. Calculus In Data Science comes down to two operations: differentiation and integration. In practice, you use differentiation almost exclusively. Integration shows up occasionally in probability distributions and Bayesian stuff, but that's a different conversation. The real work happens when you're computing derivatives of loss functions with respect to model parameters.
Calculus In Data Science and the chain rule nightmare
The chain rule is everything here. When you have a neural network with thirty layers, computing the gradient of the loss with respect to the weights in layer five requires multiplying partial derivatives all the way from the output back to that layer. This is backpropagation, and it's literally just the chain rule applied recursively. The formula looks like this: L/w_i = L/a_n × a_n/z_n × ... × z_i/w_i. Each term is a local derivative. Multiply them together and you get the global gradient. I ran into a concrete problem once where my validation loss was flatlining while training loss kept dropping. Standard overfitting diagnosis. I dug into the gradients and found that the weight updates in the early layers were essentially zero. The derivatives had vanished through the chain. I had a sigmoid activation stack going on, and the gradients were getting multiplied by values close to zero at each layer. The fix wasn't architectural — I just switched the hidden activations to ReLU and added batch normalization. Training recovered in about four hours instead of the two days it would have taken otherwise.
Why numerical differentiation usually sucks
You can approximate derivatives using finite differences: f'(x) (f(x + h) - f(x)) / h. This is called the central difference method when you use (f(x + h) - f(x - h)) / (2h). It works fine for quick prototypes, but it's numerically unstable and computationally expensive. For a model with a million parameters, you'd need two million function evaluations per gradient step. That's not practical. Automatic differentiation is the alternative, and it's what every modern framework uses. It's not symbolic differentiation and it's not numerical approximation. It tracks the computational graph and applies the chain rule at each node. The result is exact up to floating point precision. TensorFlow and PyTorch both do this, but they take slightly different approaches. PyTorch uses dynamic computation graphs that are built on the fly. TensorFlow originally used static graphs, though TF2 moved toward eager execution. The downside of automatic differentiation is that it requires your operations to be differentiable. If you throw a non-differentiable operation into the graph, like a hard threshold or a argmax, the gradient becomes undefined at that point. You'll get NaNs or zeros where you expect gradients. I've seen people use argmax inside their loss functions and then wonder why training explodes. The workaround is usually to use a soft approximation, like softmax instead of argmax, which is differentiable everywhere.
Get the Full Details
Practical gradient-based optimization
Once you have the gradient, you need an optimizer. The simplest is vanilla gradient descent: w = w - × L, where is the learning rate and L is the gradient. This works in theory but is slow in practice because it updates all parameters with the same step size and direction. Real optimizers add momentum, adaptive learning rates, and other tricks. Momentum accumulates past gradients to smooth out the update direction. The formula is v = v + L, then w = w - v. This helps escape local minima and saddle points. Adam combines momentum with adaptive learning rates per parameter. It tracks both the first moment (mean) and second moment (uncentered variance) of the gradients. The update rule is more complex: m = m + (1-)L, v = v + (1-)(L)², then w = w - m/(v + ). The hat versions are bias-corrected estimates. The choice of optimizer matters more than most people think. Adam is the default for a reason — it's robust across a wide range of problems. But for certain architectures, especially transformers and large language models, SGD with momentum can generalize better. The difference usually shows up in the generalization gap, not the final loss value. I've seen cases where Adam got 94 percent accuracy and SGD got 95.2 percent on the same task with the same architecture.
The learning rate schedule problem
A fixed learning rate is rarely optimal. You typically want a high learning rate early on to make fast progress, then a lower rate later to fine-tune. Warmup is common: start with a tiny learning rate and linearly increase it for the first few thousand steps. This prevents early instability when gradients are noisy. Then you decay the rate, often using cosine annealing or step decay. Cosine annealing follows: (t) = _min + 0.5(_max - _min)(1 + cos(t/T)). This gives a smooth decay over T steps. It's popular in transformer training because it matches the observation that these models benefit from gradual refinement in later training stages. I've used this schedule on a vision transformer project and saw a consistent 0.3 to 0.5 percent improvement in top-1 accuracy compared to a fixed learning rate. The downside of learning rate schedules is that they add hyperparameters. You need to pick _max, _min, T, and the warmup duration. Cross-validation helps but it's expensive. A pragmatic approach is to use published schedules from similar architectures as a starting point, then tweak from there.
Second-order methods and when to avoid them
Newton's method uses the Hessian matrix, which contains all second partial derivatives. The update is w = w - H¹L. This converges in far fewer steps than gradient descent because it accounts for curvature. But computing and inverting the Hessian is O(n³) for n parameters. For a model with even ten thousand parameters, this is infeasible. Approximate second-order methods exist. L-BFGS stores a low-rank approximation of the Hessian inverse and is popular in classical optimization. It's used in libraries like SciPy's minimize function. For deep learning, K-FAC approximates the Fisher information matrix block-wise, which is cheaper than full Hessian inversion but still more expensive than first-order methods. These methods can be worth it for smaller models or when you're doing hyperparameter optimization where the cost function is expensive to evaluate. For most data science work, first-order methods are sufficient. The gain from second-order methods rarely justifies the computational overhead unless you're working with small datasets and complex models where every iteration counts. I've profiled L-BFGS against Adam on a logistic regression problem with 50,000 features and found that L-BFGS converged in about a third of the time, but only because the problem was convex and well-conditioned. On non-convex problems like neural networks, the advantage disappears.

Integration in probability and statistics
Differentiation gets all the attention, but integration appears in data science too. Marginalizing a posterior distribution requires integrating over latent variables. In Bayesian inference, you often can't compute the integral analytically, so you use Monte Carlo methods. Sampling from the posterior and approximating the integral by averaging over samples is the standard approach. Variational inference approximates the posterior with a tractable distribution and optimizes the KL divergence, which involves integrals. The evidence lower bound, or ELBO, is computed as an expectation under the variational distribution. This is differentiable, so you can use gradient-based optimization. The reparameterization trick lets you move the gradient inside the expectation: E[f(x)] = E[f(x)] when x = g(, ) and is independent of . This is how variational autoencoders are trained. The practical limitation is that these methods introduce variance. Monte Carlo estimates converge at a rate of 1/N, where N is the number of samples. To get high precision, you need many samples, which is computationally expensive. Importance sampling and control variates can reduce variance, but they add complexity. In practice, a few thousand samples is usually enough for reasonable approximations in variational autoencoders and similar models.
Edge cases and debugging gradients
NaN gradients are the most common pain point. They usually come from numerical overflow or underflow in the computation graph. Log(0) is undefined, so any operation that produces zero and then takes a logarithm will break. Softmax followed by log is a classic pattern, and most frameworks compute log_softmax as a single numerically stable operation. Don't implement it yourself unless you know what you're doing. Another issue is gradient explosion in recurrent networks. Long sequences cause gradients to accumulate exponentially. Clipping gradients by norm or value is the standard fix. PyTorch's torch.nn.utils.clip_grad_norm_ clips the total norm of all gradients. TensorFlow has gradient clipping built into some optimizers. I've found that clipping at norm 1.0 works well for most RNN tasks without hurting convergence. Sparse gradients are another edge case. In recommendation systems with large item catalogs, most parameters receive zero gradients because they correspond to items that never appear in training. This makes optimization inefficient. One workaround is to use embedding tables with learned representations and only update the embeddings for observed items. Another is to use per-parameter learning rates that account for sparsity, which some adaptive optimizers do automatically.
When calculus-based methods fail entirely
Not every optimization problem is differentiable. Combinatorial optimization, integer programming, and discrete selection tasks don't have gradients. Reinforcement learning sometimes faces this issue when the action space is discrete. The reinforcement learning community developed policy gradient methods that estimate gradients from sample trajectories, which is a workaround rather than a true solution. These methods have high variance and require many samples. Another failure mode is when the objective function has too many local minima. Gradient-based methods will converge to whichever local minimum they encounter, and there's no guarantee it's the global minimum. This is especially problematic in non-convex problems like training deep neural networks. The empirical observation is that deep networks tend to have many good local minima that are nearly as good as the global minimum, which is why gradient descent works well in practice despite the theoretical concern. But this isn't always true, and for some problems, random restarts or evolutionary methods can find better solutions. If you're working with highly non-convex objectives and need guarantees about solution quality, consider alternatives like simulated annealing or genetic algorithms. These are slower and less scalable but don't rely on gradient information. For most data science applications, though, gradient-based methods remain the tool of choice because they're fast and usually good enough.