The Math Behind the Question
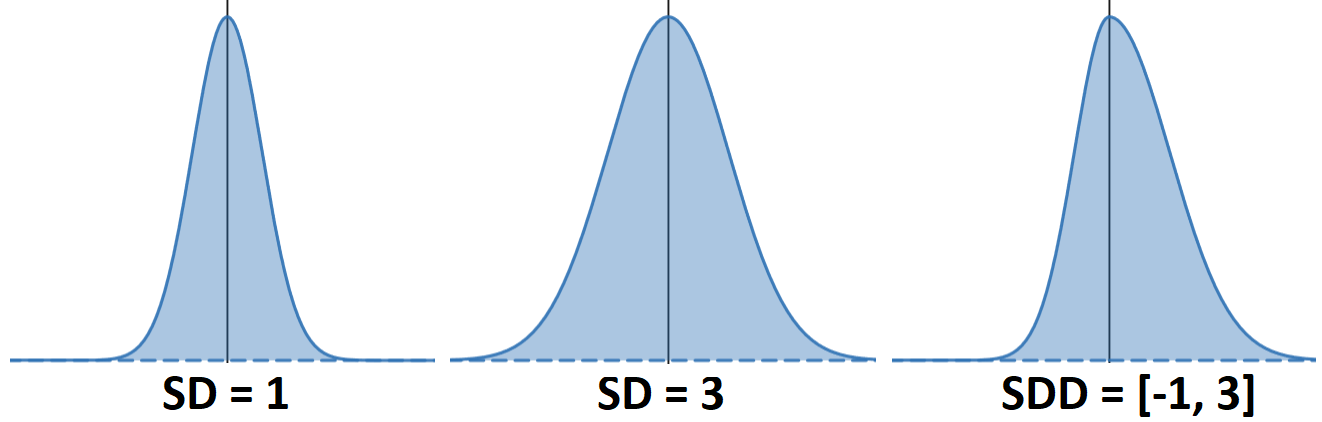
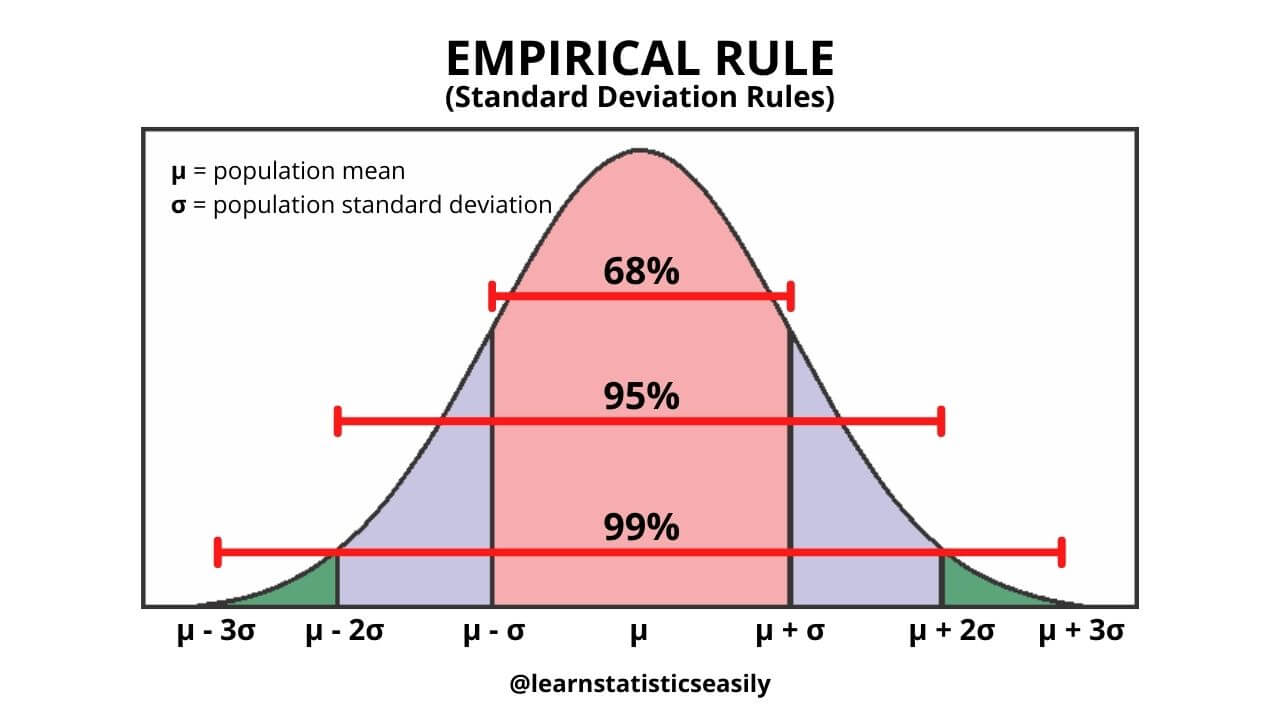
Standard deviation measures how spread out a set of numbers is from the average. It's calculated by taking the square root of the variance, and variance itself is the average of the squared differences from the mean. Since you're squaring differences before averaging them, every term in that calculation is either positive or zero. You cannot get a negative number from that process. Then you take the square root, which by mathematical definition returns the non-negative root. The result is always zero or positive. The direct answer is no. It cannot be negative. This comes up constantly in introductory statistics courses and in practical data work, usually because people confuse standard deviation with other metrics that do dip below zero. Correlation coefficients range from -1 to 1. Z-scores can be negative. But standard deviation sits at zero or above, always. I ran into this when a junior analyst on my team once fed a dataset into a forecasting model and the output showed a standard deviation of -2.4. He was convinced something was wrong with the algorithm. It turned out he had accidentally subtracted the mean before squaring instead of calculating the deviations first, and then applied the square root to the wrong intermediate result. The fix was straightforward, but the real problem was that nobody on the team had stopped to think through what the formula actually represented. We added a validation step that flags any negative standard deviation in the pipeline. It hasn't fired since.
There are a few edge cases worth noting that most textbooks gloss over. One is when you're working with complex-valued data. In that scenario, the concept of "negative" breaks down entirely because you're dealing with imaginary components, and the standard deviation becomes a complex number rather than a real number. You'll rarely encounter this outside of signal processing or quantum mechanics, but it's worth knowing that the familiar rule of non-negativity assumes you're in the real number domain. Another thing beginners miss is the difference between population standard deviation and sample standard deviation. Both are non-negative, but they use slightly different denominators in the variance calculation. The population version divides by N, the sample version divides by N-1. That Bessel's correction doesn't change the sign of anything, but it does change the magnitude, and people sometimes misinterpret a smaller sample standard deviation as somehow being "less real" than a population standard deviation. It's not. Both are valid for their intended purpose. Here's a practical note from experience. When I'm validating statistical outputs in R or Python, I always run a quick assertion right after computing standard deviation. Something like checking that the result is greater than or equal to zero and finite. This catches data entry errors, coding bugs, or corrupted input files far more reliably than staring at the numbers. I've seen negative results pop up from numerical instability in extremely skewed distributions where floating-point precision became an issue. The workaround was switching from the naive two-pass algorithm to Welford's online algorithm, which is numerically stable and avoids the intermediate overflow that can happen with large sums of squares.
So if you ever get a negative standard deviation, the issue is in your calculation or your data, not in the mathematics itself. The answer to whether standard deviation can be negative is definitively no, and any result that violates that should trigger an investigation into your pipeline rather than a reconsideration of the formula.
Get the Full Details