How CAPM Actually Works When You Stop Reading the Textbook
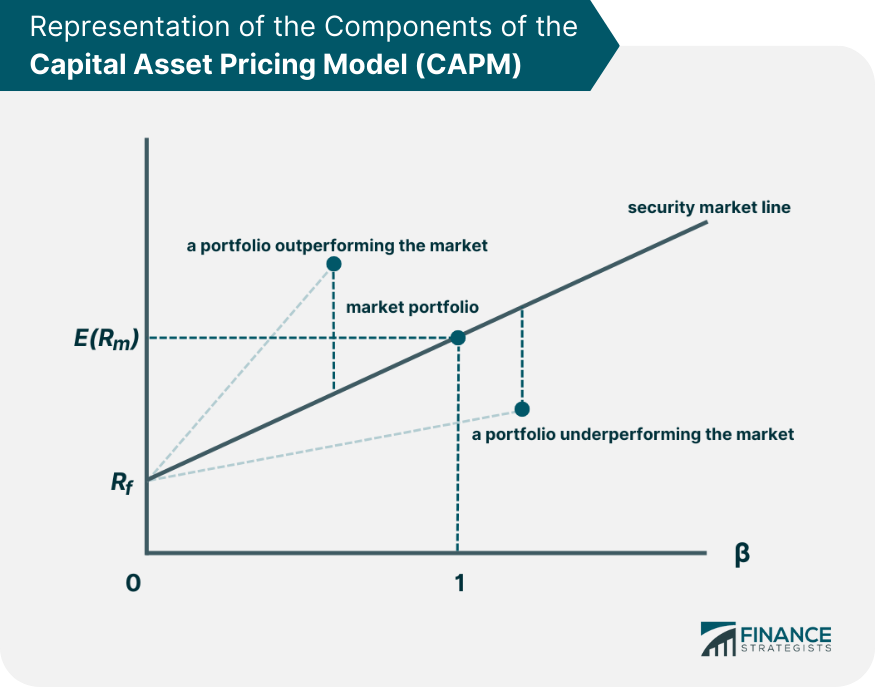
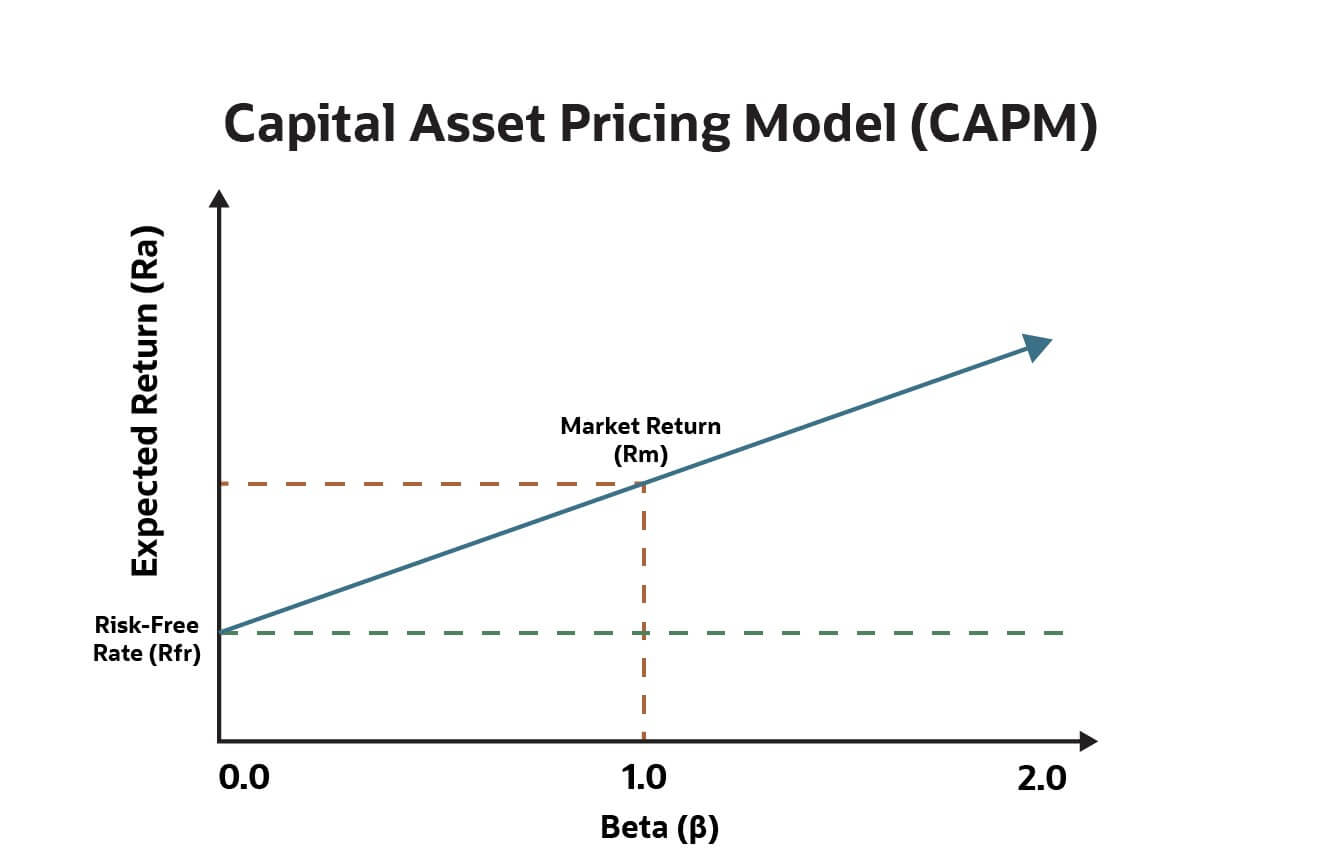
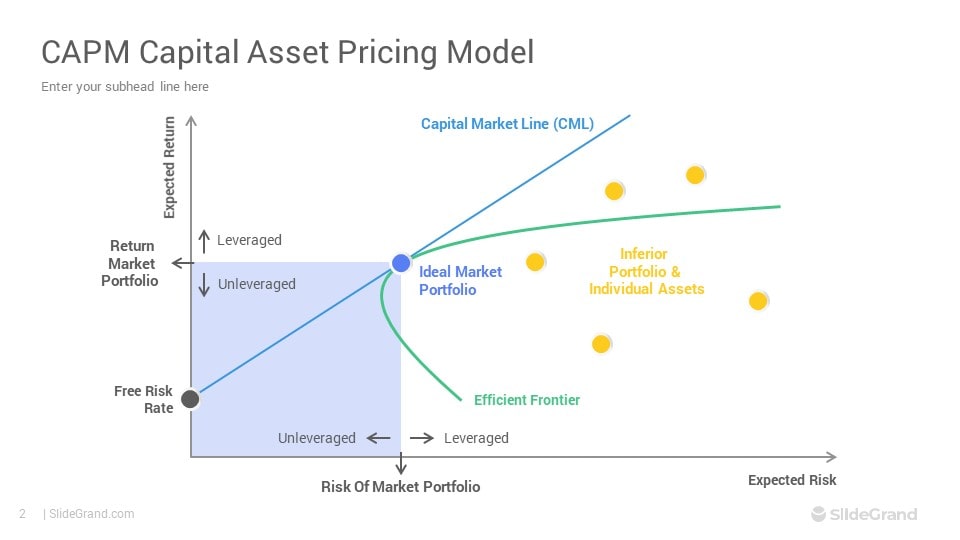
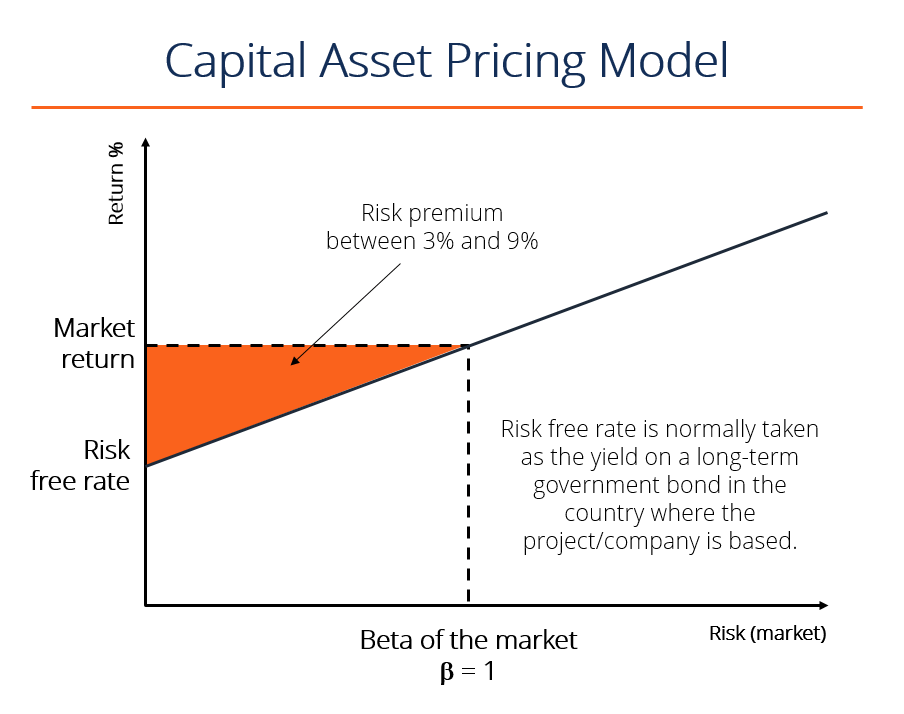
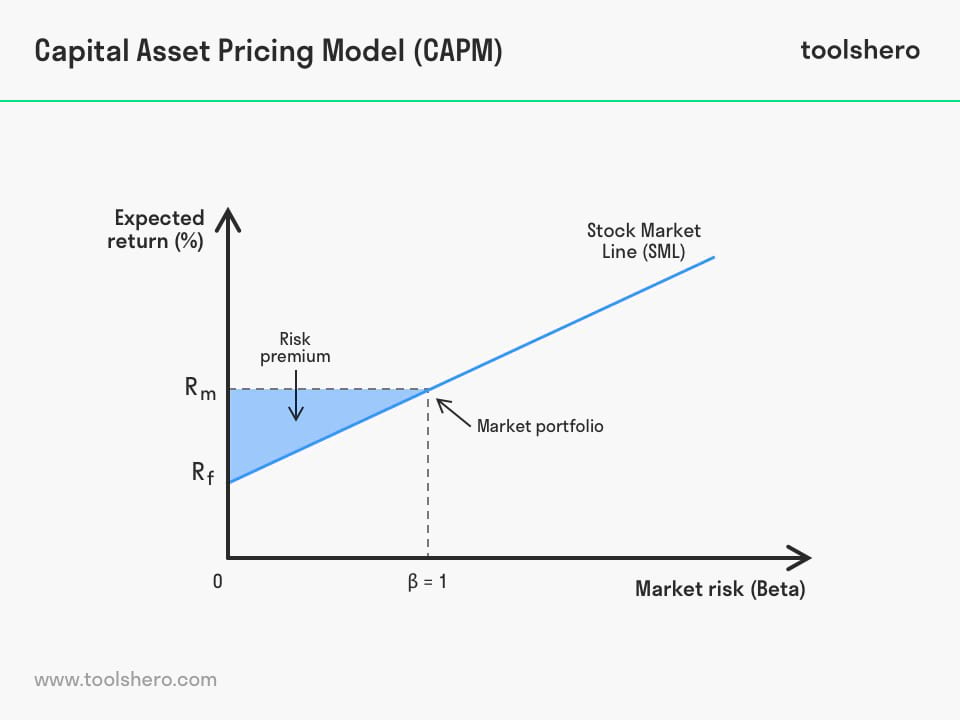
The formula is simple enough that people underestimate it. Expected return equals the risk-free rate plus beta times the market risk premium. That is Rf plus beta times Rm minus Rf. You plug in your numbers and get a percentage. But the hard part is never the arithmetic. It is figuring out which numbers actually belong in the formula when you are working with real data and real portfolios. At its core the model says the only compensation an investor should expect for taking on extra risk is systematic risk. That is the stuff you cannot diversify away. Unsystematic risk gets priced to zero over time because anyone holding an idiosyncratic position can shed it for free by buying index funds. What remains is the market beta, a measure of how sensitive a single asset moves relative to the broader market. If a stock has a beta of 1.4 it should theoretically outperform the market by 40 percent more on any given move up or down. Here is the part most people gloss over. The CAPM is not a pricing theory that works perfectly in practice. It is a benchmark. A starting line. You use it to ask the question "am I being paid enough for the risk I am taking?" Not to answer it with total confidence. The Sharpe-Sortino crowd will tell you otherwise, and they have some valid points, but CAPM remains the default framework in corporate finance, portfolio construction, and cost of equity calculations for reasons that have nothing to do with mathematical elegance and everything to do with convention and availability of data.
I spent three years building discounted cash flow models for mid-cap companies and the CAPM was in almost every single one. The frustrating part was how much variation two analysts could produce using the same inputs. I had a colleague who used a 20-year monthly history for his beta regression and another who used weekly data over five years. Both claimed to be "correct." Both were wrong in different ways. The 20-year monthly beta was overly smooth and ignored structural shifts in the business. The 5-year weekly beta was noisy and reflected temporary market regime changes rather than the company's actual risk profile. My workaround was practical and I still use it. I run the beta regression using monthly returns over the most recent three to five years, then I adjust toward one depending on the stability of the company's business. Stable utility or consumer staples get pulled toward one. Cyclical or high-growth companies stay where the regression puts them. I also check the r-squared of the regression. If it is below 0.4 I treat the beta as barely informative and lean more on comparable company analysis instead.
The Inputs and What They Actually Mean
The risk-free rate is usually the yield on a government bond matching your investment horizon. Ten-year Treasury yield in the US context. Some people argue for shorter durations. The Fama-French papers showed that term structure matters more than textbooks admit. But for most corporate applications the ten-year is the standard and you should stick with it unless you have a specific reason not to. The market risk premium is the harder input. Historical averages sit somewhere between 4 and 6 percent annually for US equities. But forward-looking estimates from Damodaran and other practitioners often land in the same range with different justifications. The difference is mostly semantic if you are doing a quick model. It becomes meaningful when you are valuing a company at the edge of acceptable return thresholds and a half-percent swing in the premium changes your buy-sell recommendation. Beta itself is a trailing statistic dressed up as a forward-looking measure. That contradiction is the whole problem with CAPM. You are using past covariance with the market to predict future required returns. Markets reprice. Business models shift. A beta estimated during a low-volatility regime will systematically understate risk when volatility returns. I learned this the hard way in 2020 when several of my tech positions had betas of 0.8 to 1.0 and they dropped harder than anything with a beta of 1.5. The market beta had compressed during the late-2010s bull run and failed to capture the tail risk that materialized when COVID hit.
Get the Full Details
The workaround there was simple enough. I supplemented the CAPM-derived cost of equity with a size premium and an idiosyncratic volatility adjustment. It is not part of the original model but nobody who actually uses CAPM for real work sticks to the pure version. You add a small-cap premium from dimensions like those in Fama-French or Carhart. You tweak for company-specific volatility if the stock has a history of earnings surprises or revenue shocks. The resulting required return is defensible in a boardroom even if it strays from academic purity.
When CAPM Completely Breaks Down
Let me be blunt about the situations where this model gives you a false sense of precision. It fails for private companies because there is no publicly traded beta to estimate. You have to find comparables, un-lever and re-lever betas, and hope the peer group is actually relevant. It fails for non-equity assets because the beta framework assumes a single-market equilibrium that does not exist for real estate, infrastructure, or private credit. It fails for assets with embedded options because optionality creates non-linear payoffs that beta cannot capture. A biotech stock with a binary outcome is not a CAPM problem. It is a decision tree problem. It also struggles with assets in emerging markets where the "market" is not well-defined. The MSCI Emerging Markets index is a composite, not a true market portfolio. Using it as the benchmark introduces measurement error that compounds through the entire calculation. I worked on a project valuing an Indonesian infrastructure company where the local equity index had an r-squared of 0.23 against the MSCI EM benchmark. The beta was essentially random. We switched to a country-risk-adjusted approach using sovereign spreads and defaulted to a build-up method for the cost of equity instead.
A Practical Walk-Through
Let me walk through a real example with current-ish numbers. Suppose you are evaluating a mid-cap US industrials company. The ten-year Treasury yield is around 4.2 percent. The equity risk premium is 5.0 percent. The raw beta from a three-year monthly regression is 1.15 with an r-squared of 0.58. The company has a market cap of $8 billion, which puts it in the lower end of mid-cap. The annual idiosyncratic volatility is 22 percent compared to the market's 16 percent. The CAPM cost of equity comes out to 4.2 plus 1.15 times 5.0, which is 9.95 percent. That is the baseline. Now you consider adjustments. The size premium for an $8 billion company is roughly 0.5 percent based on standard factor premiums. The idiosyncratic volatility suggests adding maybe 0.3 to 0.5 percent as a liquidity and specificity adjustment. Your final cost of equity lands around 10.7 to 10.95 percent. Not dramatically different from the raw CAPM number but more honest about what the risk actually is. If you are doing this for a single project valuation and need to move fast, the raw CAPM at 9.95 percent is close enough. The adjustments matter more when you are doing sensitivity analysis across multiple scenarios or when the deal structure depends on staying below a certain hurdle rate. A 0.5 percent difference in cost of equity can swing an NPV by tens of millions on a large transaction.
Implementation Notes That Matter
Most spreadsheet implementations of CAPM are straightforward. You pull the risk-free rate from a financial data provider. You calculate returns as log returns rather than simple returns for better statistical properties. You align your date ranges so that the beta estimation period and the valuation period do not overlap in a way that creates look-ahead bias. You also remember to un-lever and re-lever betas when comparing companies with different capital structures. The Hamada equation does this, and skipping that step introduces systematic error into your peer comparisons. The data sources you use matter more than most people admit. Bloomberg and Refinitiv handle the cleaning and adjustment automatically but they apply their own methodologies for beta estimation. If you build your own regression from raw price data you will get different numbers. Neither is wrong. They are just different estimators. Pick one and be consistent across your coverage universe. Mixing sources is how you get inconsistent cost-of-capital figures within the same portfolio. One thing I wish more people understood is that CAPM is not obsolete despite all the academic criticism. Fama-French multi-factor models exist. Build-up methods exist. Option-pricing approaches exist. But none of them have displaced CAPM in actual practice because CAPM occupies a sweet spot between simplicity and usefulness. It forces you to think about beta and market risk explicitly. It produces a single number that stakeholders understand. And when you add sensible adjustments for size, liquidity, and specific risk, it gets close enough to the right answer that the marginal improvement from a more complex model rarely justifies the added complexity.