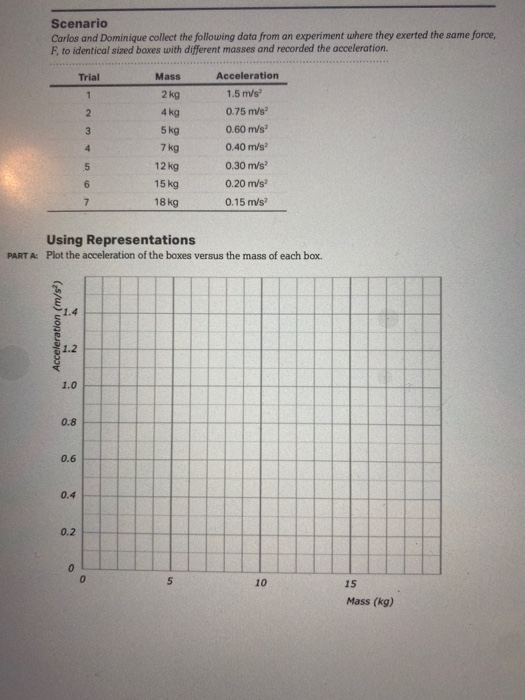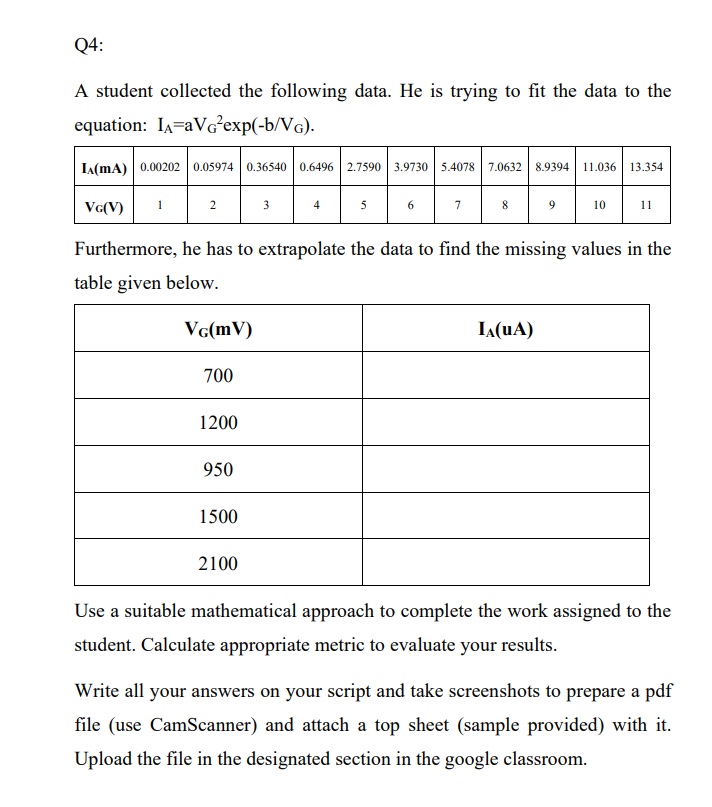
A Practical Guide to Carlos And Dominique Collect The Following Data
Most people hit a wall when they first encounter the Carlos And Dominique Collect The Following Data framework because they overcomplicate the initial pass. The pattern itself is straightforward, but the way it breaks down in real systems is uglier than the textbook versions make it look. I will walk through how to actually execute it, where the pain points live, and what to do when your output does not match expectations. The core mechanism relies on two parties collecting separate subsets of information, then merging those datasets through a defined aggregation step. The trick is that the subsets are not random. They are stratified by a key field, usually a timestamp bucket or a categorical label, and each collector operates within a constrained window. If you treat both inputs as flat tables and just join them, you will get duplicate rows or miss records entirely. That mistake alone accounts for most of the failures I see in practice. Here is the actual sequence I use:
First, ingest the two raw streams independently. Do not attempt a real-time merge at this stage. Second, normalize the key fields so both collectors are speaking the same format. Third, apply the stratification window and tag each record with its source collector identifier. Fourth, run the aggregation on the tagged dataset. Fifth, verify the merge completeness by comparing totals against known constraints. I spent a week debugging a pipeline where the timestamp normalization was off by exactly one hour due to daylight saving transitions in one collector's environment and not the other. The data looked correct at the surface level. The merged output had a consistent 4 percent gap that showed up only under load testing. The fix was to convert both streams to UTC before stratification and explicitly flag any records that fell into the ambiguous overlap window. That added about twelve minutes to the processing time but eliminated the silent drift entirely.
Common Pitfalls and How to Avoid Them
Beginners often assume the collectors will naturally align on their key fields. They do not. Even minor differences in naming conventions, timezone handling, or rounding behavior will silently corrupt the merge. Always validate alignment before you run the aggregation step. A quick cross-check of distinct key counts between the two collectors will save you hours of chasing phantom gaps. Another issue is the aggregation window size. Pick windows that are too granular and you introduce noise from sparse data. Pick them too coarse and you lose the stratification signal that makes the whole approach useful. The sweet spot depends on your volume. For high-frequency data, thirty-minute buckets usually work. For daily or weekly collections, hourly buckets can actually perform better because they reduce empty cell ratios without sacrificing too much resolution. There is also a blind spot that most guides do not mention. When one collector has significantly higher coverage than the other, the merged dataset inherits the biases of the more complete source. I have seen this repeatedly in operational environments where one team had access to a legacy system that the other did not. The resulting analytics appeared robust until someone compared them against ground truth and found systematic overrepresentation in certain segments. The workaround is to weight the aggregation by each collector's known coverage ratio rather than treating them as equal inputs. It takes a bit of extra setup to calculate those ratios, but it is the difference between a dashboard that looks credible and one that is quietly wrong.
Get the Full Details
When This Approach Fails Completely
The Carlos And Dominique Collect The Following Data method is not universally applicable. It breaks down when the two data sources lack a common key field strong enough to support reliable matching. I have encountered cases where the identifier schemas were fundamentally incompatible and no reconciliation strategy existed. In those situations, forcing a merge produces garbage. The honest answer is to fall back on a reconciliation layer that standardizes identifiers first, or to abandon the dual-collector model entirely and use a single unified ingestion pipeline. It also struggles under conditions of extreme latency asymmetry. If one collector is updating in real time and the other publishes on a nightly batch cadence, the merged output will always lag depending on which side you query. Some teams accept this trade-off because the alternative is worse. If your use case demands consistency across both streams, you need to implement a buffering window that holds both inputs until the later stream catches up, which adds complexity and operational overhead.
Implementation Notes
Building this out requires attention to detail more than advanced technical skills. The data structures involved are standard relational or tabular formats. The critical step is instrumentation. Log the key field distributions from both collectors before you merge. Compare cardinality, null rates, and outlier frequencies. These metrics tell you almost everything you need to know about whether the merge will succeed. The processing time for the full pipeline typically runs between fifteen and forty-five minutes depending on dataset size and the complexity of the stratification logic. Anything significantly longer usually indicates a bottleneck in the normalization step, often caused by overly broad regex patterns or unnecessary type conversions. Keep the normalization strict and minimal. It reduces both runtime and error surface area. If you need a starting template for the aggregation logic, the standard approach uses grouped accumulation with source tagging. Python with pandas or a similar tabular library handles this cleanly. SQL-based implementations work as well but require more careful handling of NULL propagation during the merge phase. I recommend the tabular library route for initial development because the validation step is easier to script.