Getting Case Study Data Analysis Right Without Losing Your Mind
I used to think case study data analysis was mostly about picking the right software and formatting everything pretty. It took me about three years of struggling with messy real-world datasets to realize that's the opposite of what actually matters. The hard part is deciding what question you're even answering before you look at a single number. The core approach here is straightforward enough in theory. You take a bounded set of information -- a company, a project, a specific event -- and you examine it in depth. The tricky part comes when you're trying to connect scattered evidence into something coherent. Most people skip the coding stage and jump straight to narrative, which is why so many case studies feel like they were written to prove a point rather than discover one.
Case Study Data Analysis: The Practical Workflow
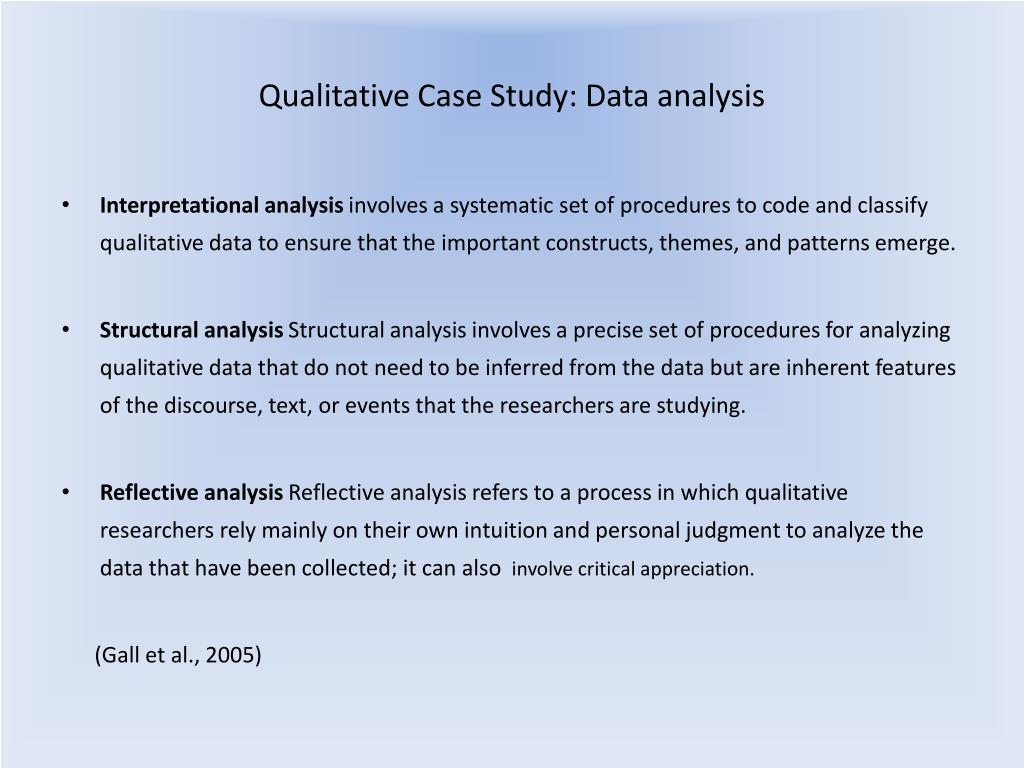
Start by pulling together every piece of data you can find. That means interview transcripts, financial reports, internal emails, observational notes, whatever exists. Dump it all into one folder or tool. Don't organize it yet. I keep everything in a structured directory with folders for raw files, cleaned versions, and my own notes, but that's just for my own sanity. From there, you code the data. This means going through systematically and labeling segments with tags that represent themes, patterns, or concepts. Deductive coding uses a pre-built framework based on your research question. Inductive coding lets themes emerge from the data itself. Most people I see doing this mix both approaches, starting inductively and then applying a deductive lens once they spot recurring patterns. Once the coding is done, you look for relationships between themes. What connects? What contradicts? This is where the actual analysis happens rather than during the coding phase, which is more mechanical. I spend maybe 20 percent of my time coding and 80 percent looking at how the codes interact with each other.
Triangulation is essential here. That means cross-referencing multiple data sources to verify findings. If an interview says one thing and the financial records say another, you don't just pick one. You investigate the gap. The gap is usually where the actual insight lives. I ran into a specific problem a few years back that illustrates this. I was analyzing a mid-size logistics company's transition to a new routing system. The interview data showed strong employee satisfaction with the change, but operational metrics told a completely different story. Delivery times had worsened by 18 percent in the first quarter after launch. I initially thought the employees were just being diplomatically positive in their interviews, but that didn't hold up under scrutiny. The workaround involved going back to the raw data with a different lens. I pulled shift-level performance logs and cross-referenced them with interview timestamps. It turned out the satisfied employees were mostly senior staff who had already adapted to the new system within the first two weeks. The people struggling with the transition -- delivery drivers with less tech experience -- rarely got scheduled for interviews because the company conveniently had them on modified duties during that period. This selection bias completely flipped my initial reading of the case. The "successful" transition was successful only for a subset of the workforce.
Get the Full Details
That's the kind of thing you catch when you treat your data as flawed rather than authoritative. Most beginners treat case study data as if it were inherently truthful and just need to be organized. It's not. Every source has blind spots.
Common Mistakes and Why They Matter
The biggest mistake I see is confirmation bias dressed up as rigorous analysis. You come into a case study with a hypothesis, and then you unconsciously weight evidence that supports it while glossing over contradictions. This isn't deliberate manipulation. It's usually just how human pattern recognition works. You see what you expect to see. Another frequent error is overgeneralizing from a single case. One company's experience with a particular strategy doesn't mean that strategy works generally. It means it worked in that specific context with those specific constraints. If you present it as a universal finding, you've missed the point of doing a case study in the first place. Case studies also struggle with time. They capture a moment or a period, but organizational dynamics shift. A case study on a company's digital transformation in 2022 might look very different if replicated in 2025. This isn't a flaw in the method. It's a feature that most people ignore until it bites them.
There's also the issue of scale. Case study data analysis is inherently labor-intensive. A single well-done case can take weeks or months depending on the depth required. You're reading transcripts, verifying facts, cross-referencing sources, and rewriting your analysis as new information emerges. You cannot automate this. Tools like NVivo or Dedoose help with organization, but they don't replace the analytical work. I've tried faster alternatives like basic spreadsheet-based analysis, and they consistently produce shallower results that miss nuance in ways you only notice after the fact. What I usually recommend instead is keeping a reflexive journal alongside your analysis. Write down your assumptions, your hunches, and the moments where you feel uncertain. Revisit those entries after a few weeks. You'll often catch yourself being wrong about something you were genuinely confident about. It's a small habit that significantly reduces the confirmation bias problem without requiring any special training. The bottom line is that case study data analysis works best when you treat it as an exercise in controlled curiosity rather than a tool for proving things. The method rewards people who are willing to follow evidence wherever it leads, even when that means overturning their initial assumptions.