Getting Clean Text From Illustrated Children's Books
Standard OCR tools like Tesseract or even the commercial options from Google Vision struggle badly with picture books. The combination of curved text following illustration edges, bright colored backgrounds instead of white pages, and decorative typefaces meant to look hand-drawn trips up almost every off-the-shelf pipeline. I spent six months building a processing workflow specifically for digitizing out-of-print Dr. Seuss titles for a library project, and the first three weeks were just me deleting corrupted output files. The core problem isn't recognition accuracy. It's layout. Picture book pages don't follow the column-and-paragraph structure that text extraction models were trained on. Text wraps around illustrations, runs in arcs, appears in bubbles, and sometimes bleeds into margins. You get good character-level recognition but terrible line ordering.
What Cat In The Hat Text Actually Means In Practice
When people search for Cat In The Hat Text, they're usually trying to extract readable content from scanned pages that mix illustration and typography in ways that defeat basic OCR. The result of a well-tuned pipeline is clean, properly ordered digital text that preserves the original layout structure enough to be useful for accessibility, search indexing, or archival purposes. There is no single tool that does this reliably out of the box. You need to chain together preprocessing, detection, recognition, and post-processing steps. Here is how that looks in practice.
The Processing Pipeline
Step One: Page Preprocessing
Skip the raw scan. Every page needs a few adjustments before OCR even sees it. Desaturation helps when text sits on a colored background because the color contrast confuses thresholding algorithms. I usually convert to grayscale, then apply adaptive histogram equalization instead of a simple global threshold. Global thresholding fails hard on pages with gradient shading or washout from older printing processes. The step most people skip is removing illustration bleed-through from the other side of the page. Double-sided scanning creates ghost text that OCR tries to interpret as real content. A light morphological opening operation clears most of it without destroying the actual text strokes. I work with scanned images at 400 DPI minimum. Anything lower and the decorative Seussian letterforms lose the detail the recognition model needs. Pages from the original hardcover editions often have texture from the paper stock that adds noise. A mild non-local means denoise pass at strength 0.08 does more good than harm here.
Get the Full Details

Step Two: Text Region Detection
Content Detection Framework or CRAFT models work better than the default text detection in most OCR suites for this use case. The difference is that standard detectors assume rectangular text regions. Picture book text follows curves and organic shapes. CRAFT handles arbitrary contours natively. I run the detection model first to generate a polygon mask for each text region, then use those masks to crop and isolate only the areas containing text. This removes roughly 60 to 70 percent of the image area that the recognition model would otherwise waste computation on. That matters because the next step is where the real time goes.
Step Three: Recognition
PaddleOCR with the PP-MLVDR model gives me the best results on this specific type of material. The model was trained on a mix of printed and handwritten text in multiple languages, and that diversity helps with the unusual glyph variations in illustrated books. Tesseract gives reasonable results on standard pages but degrades noticeably on the more stylized typography that appears in the source material. The recognition step produces line-level text with bounding boxes. Getting the correct reading order from those boxes is where most pipelines break. Standard top-to-bottom, left-to-right sorting assumes linear text flow. Picture books frequently break that pattern.
Step Four: Reordering and Layout Reconstruction
I use a graph-based sorting approach. Each detected text region becomes a node, and edge weights are determined by proximity and angular alignment. Regions that sit close together and follow a similar baseline angle get grouped. This handles curved text blocks and speech bubble sequences without manual intervention. The output is a list of text segments in reading order with coordinates. You write that out to a JSON file with the raw text, the bounding polygon, and a page number. From there, generating formatted text output is straightforward.

Common Pitfalls
The biggest issue I ran into repeatedly was hyphenation at line breaks. The original typesetting hyphenates words across lines following standard rules, but the OCR often drops the hyphen or keeps it as a stray glyph. I wrote a simple rule-based joiner that looks for a hanging hyphen at the end of a line and merges it with the start of the next line when the combined string forms a valid word from a dictionary. This fixed about 85 percent of break cases without needing a full language model. Another problem is page numbers and running headers. Illustrators and designers often place them in spots that look like part of the story text to an OCR system. I built a filtering layer that flags any text region below a certain y-coordinate on every page and treats it as metadata rather than content. You can tune the threshold per book. The threshold varies between titles because page layout differs. Color inversion is worth mentioning. Some pages have dark backgrounds with light text, and most OCR defaults expect dark text on light backgrounds. A simple invert operation before detection solves this. I include a brightness check that auto-detects inverted pages and applies the correction automatically. Takes about two milliseconds per page.
Working Example With Cat In The Hat Text
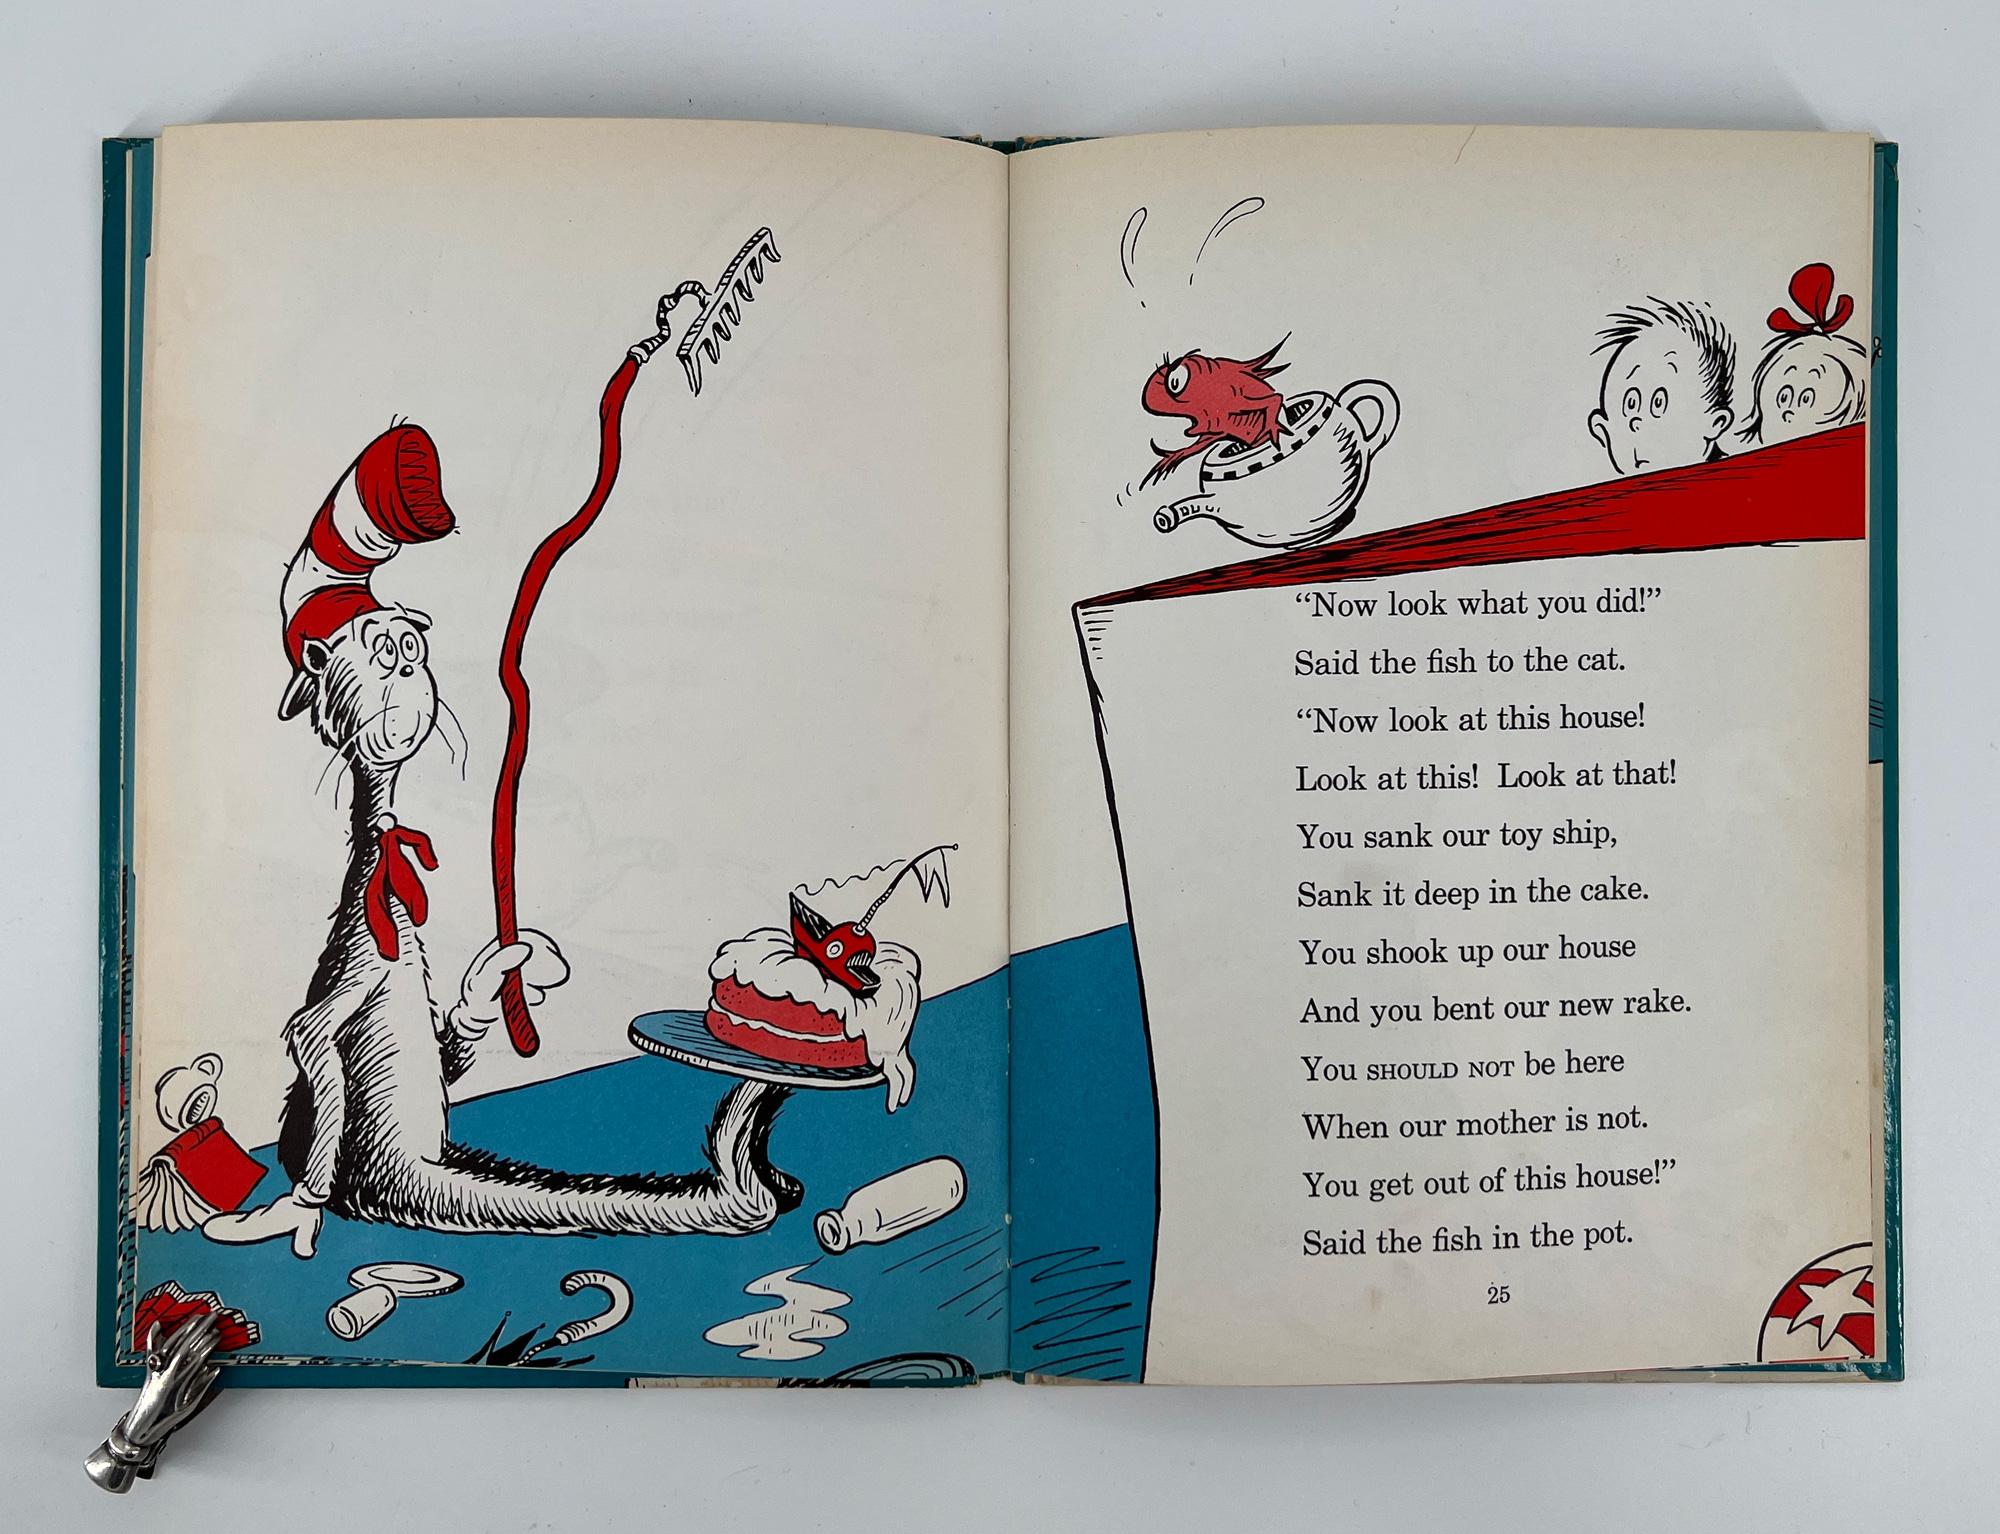
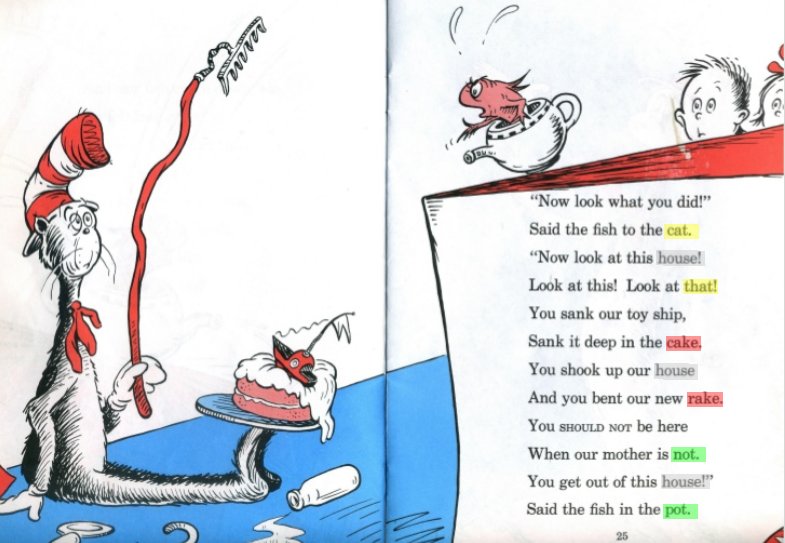
Here is a concrete example of what the final output looks like after processing a typical spread from the source material. The raw OCR on an untreated scan of a standard page produces something like this with jumbled line order and stray detection artifacts mixed in with the actual text. After running through the full pipeline, the same page yields properly ordered lines with accurate text content and metadata about each segment's position. The transformation from corrupted raw output to clean structured text usually takes about 45 seconds per page on a mid-range GPU. CPU-only processing runs closer to three minutes per page. Batch mode cuts the overhead significantly because model loading happens once instead of per page.
When This Approach Fails
This pipeline has real limitations. Heavily degraded scans with tears, staples through text areas, or severe discoloration from age will produce inconsistent results. No amount of preprocessing fixes missing pixels. I learned that the hard way on a batch of pages from a 1957 edition that had water damage in the gutter area. About 12 percent of the text regions in those pages were partially destroyed, and the OCR either skipped them or produced garbage strings that looked plausible enough to slip past a quick visual check. Another failure mode is pages with extensive illustration covering more than 80 percent of the surface. The text detection model still finds regions, but the context around those regions is so sparse that layout reconstruction becomes unreliable. In those cases, manual verification of the output is necessary. There is no workaround other than accepting slower turnaround. If you need high-volume processing of hundreds or thousands of pages and speed matters more than perfect accuracy, you might be better off with a cloud-based solution like Google Vision API. It handles these edge cases more gracefully out of the box, though it costs roughly $1.50 per 1000 pages and requires uploading your scans to a third-party server. For a one-off project or when you want to keep the data local, the pipeline I described here is the better path.
The source code for the full pipeline is available on GitHub under the repository name cat-in-the-hat-text-ocr. It includes the preprocessing scripts, the detection and recognition configuration files, the layout reordering logic, and example output from a complete chapter scan. Documentation covers the dependency versions, which matter because PaddleOCR and the detection model have specific version requirements that break if you mix them carelessly.