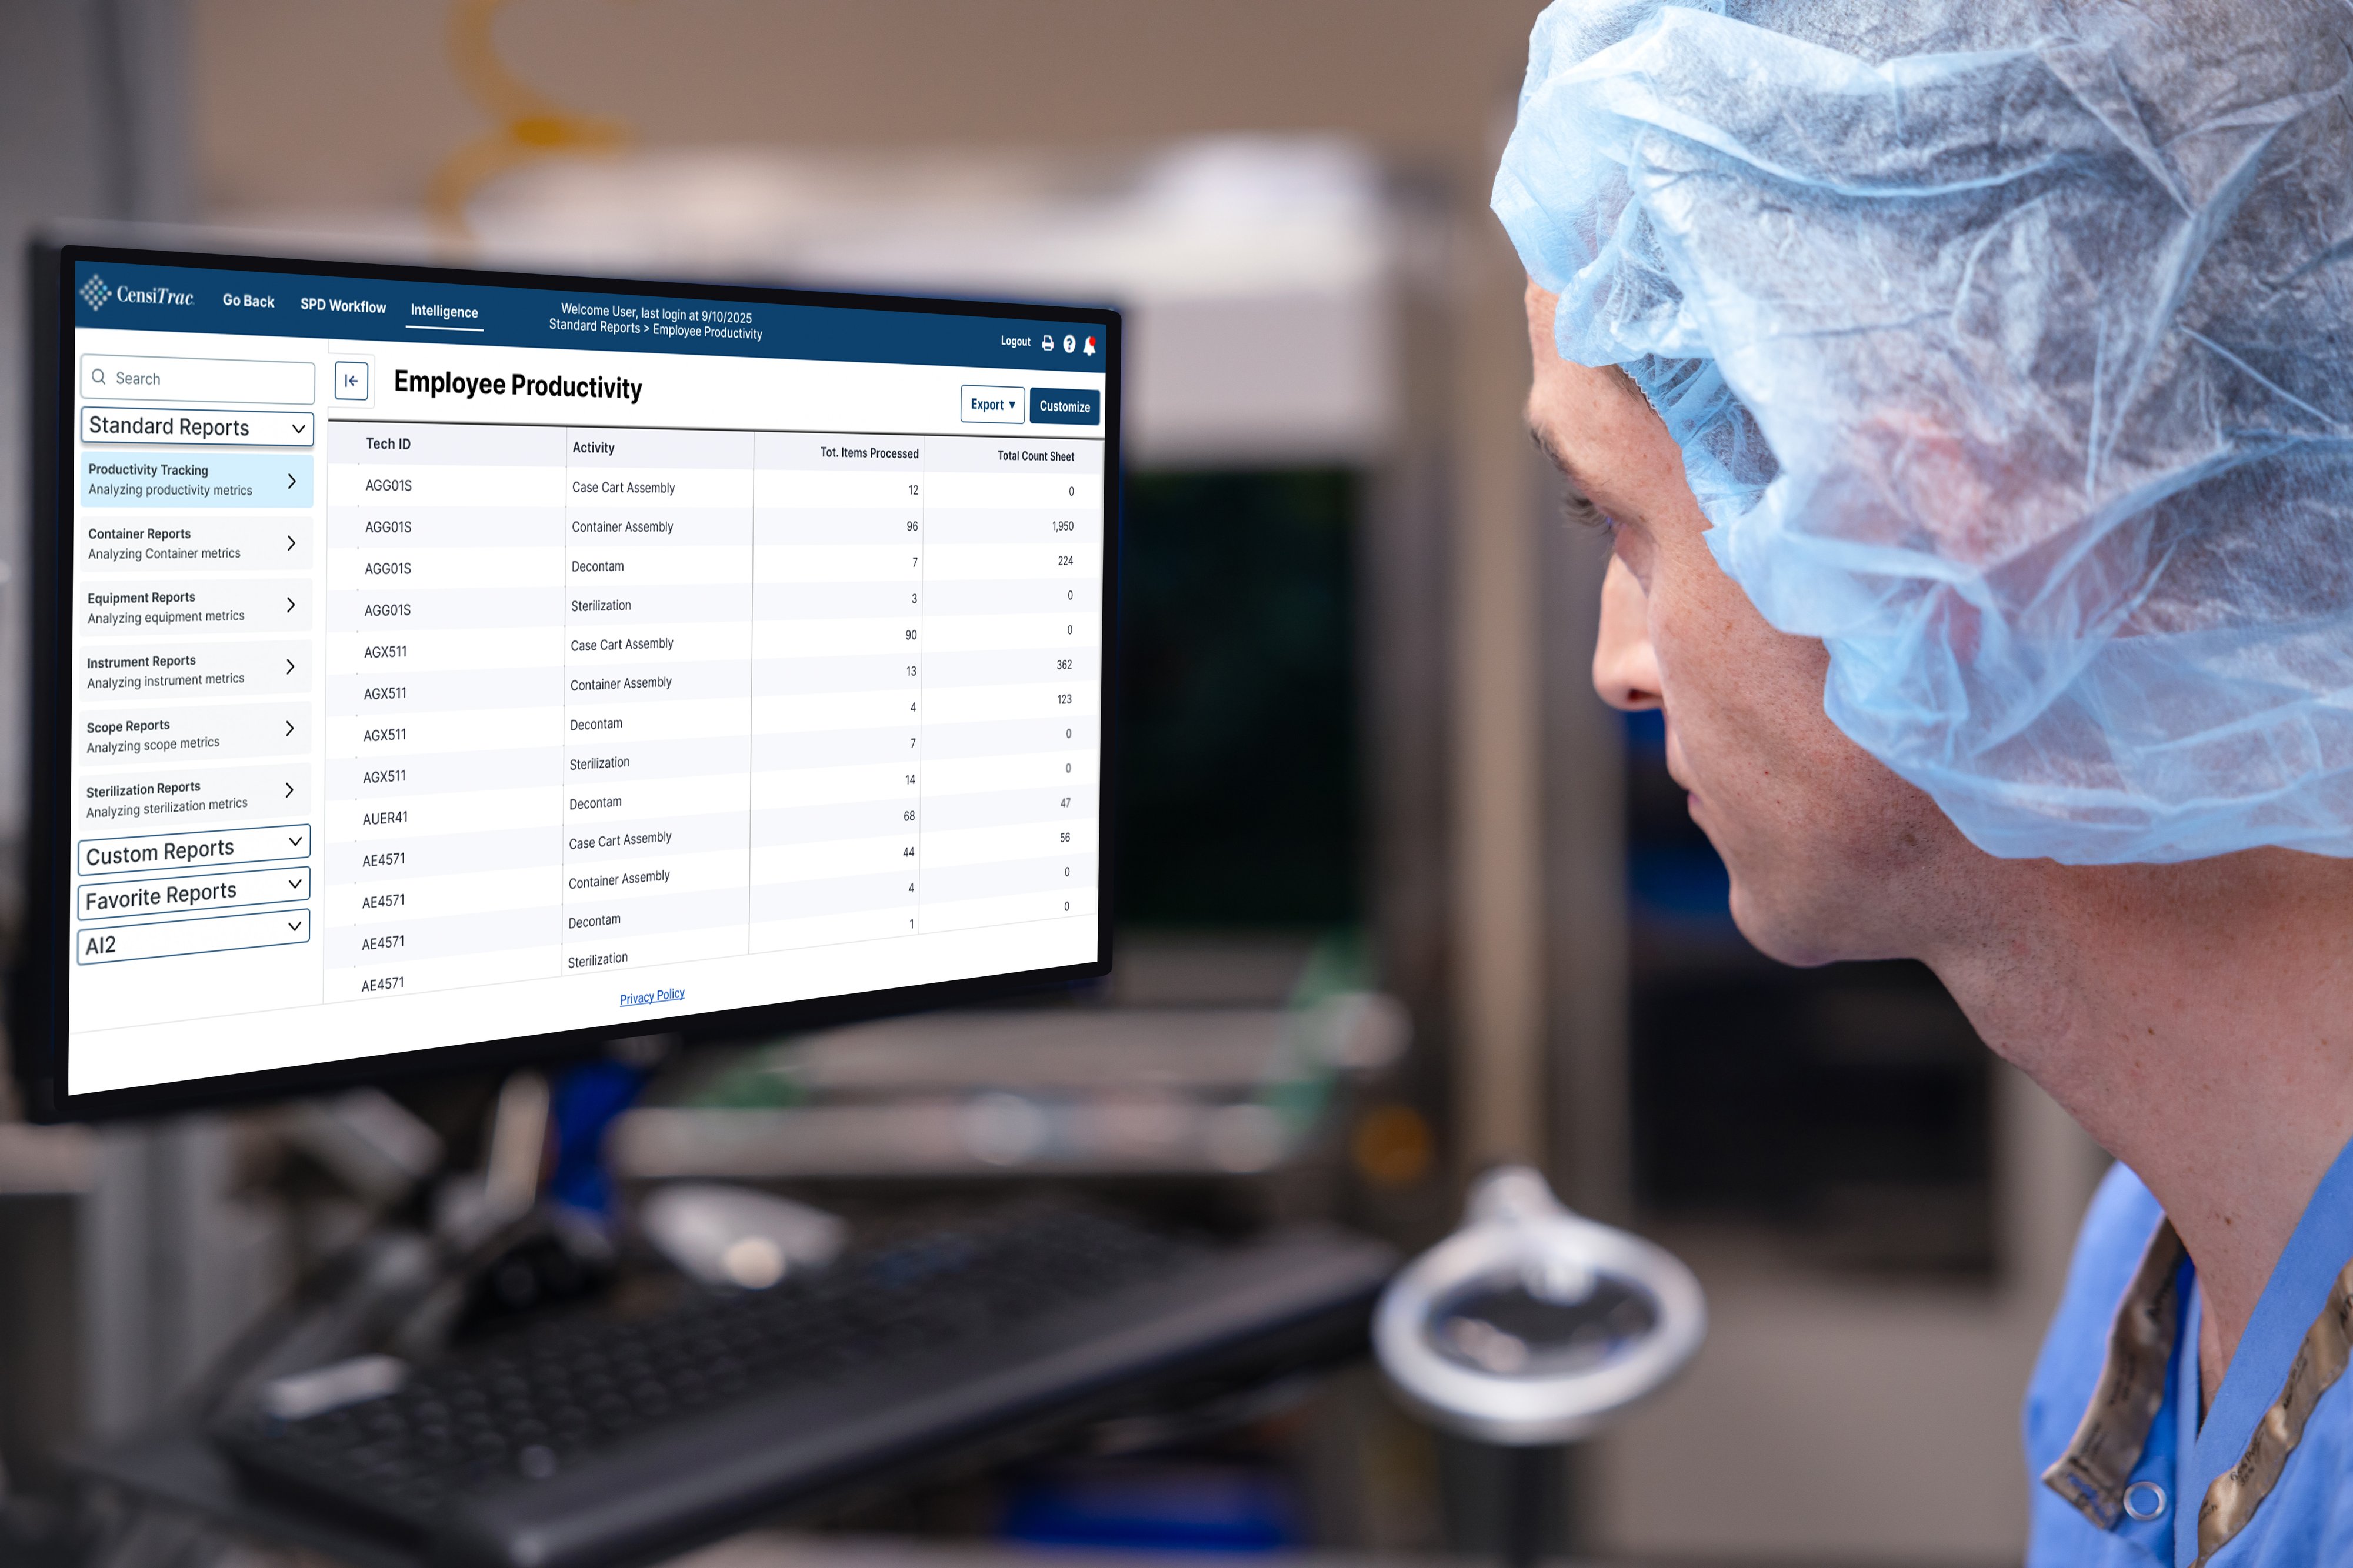
What Censitrac Actually Is
Censitrac is a mobile data collection platform built for large-scale surveys, censuses, and population registration projects. It runs on Android devices, syncs to a central server, and gives field teams structured forms, GPS tracking, and offline capability. That is the summary most vendors would give you. The reality is more detailed.Censitrac User Manual
Getting started with the software involves understanding its architecture before you try to deploy it. The system has three main parts: the web-based administrator console, the Android application used in the field, and the backend database that stores everything. You set up projects through the admin portal, design forms using a visual editor or XML definitions, assign enumerator accounts, then distribute the app to phones via APK install or a managed device system. I ran into a specific problem during a rural census rollout in 2023 where over two hundred enumerators were collecting household data. The issue came down to how the sync queue handled conflicts when multiple devices reconnected after being offline for extended periods. The default conflict resolution setting was set to last-writer-wins, which caused duplicate households to appear across different devices in ways that were nearly impossible to trace afterward. I had to switch the project configuration to use a server-side merge rule based on a unique identifier field we built into the form, then manually deduplicated about forty records that had slipped through. The workaround involved exporting the problematic dataset, running it through a script that compared household IDs against the master reference table, and re-importing the cleaned records back into the project.
Form Design Considerations
The form builder supports skip logic, conditional display, geo-fencing triggers, and photo capture fields. Most users treat these as separate features, but they interact in ways that can break your field workflow if you do not plan them together. A skip logic branch that depends on a location check will only evaluate correctly if the GPS coordinate is actually captured first. If your device is in airplane mode when the question triggers, the logic branch will either skip unexpectedly or throw a validation error depending on your offline settings. There is also a common misunderstanding about how validation rules work on the device versus on the server. Field-level validation runs locally and prevents submission, but format validation like numeric ranges or regex patterns only applies when the data reaches the server. This means an enumerator can submit a form with obviously wrong data that passes every local check, and you will only discover the problem after the fact during quality review. I learned this the hard way when a project collected age values above one hundred fifty because the regex pattern was defined on the server side only. The fix was to duplicate all critical validation rules at both the field level and the server level.
Offline Sync Behavior
Offline operation is one of the main reasons organizations choose this platform, and it works well until it does not. The app caches submitted forms locally and attempts background synchronization when connectivity returns. The default sync interval is ten minutes, which is fine for urban areas with reliable signal but problematic in remote locations where a single sync attempt might take twenty minutes or more and then fail. A practical setup adjustment is to increase the sync interval to thirty or sixty minutes for projects operating in low-connectivity zones. This reduces failed attempts and conserves battery. You should also enable compressed data transfer in the project settings, which typically cuts sync payload size by roughly sixty percent without affecting data integrity. The tradeoff is that initial upload of large datasets with many images takes longer because compression happens on the device first. I generally recommend disabling image compression for projects where photo verification is secondary, and enabling it only when storage costs on the server become a concern.
Get the Full Details
Enumerator Management
Managing field staff efficiently requires understanding how role permissions cascade through the system. Administrators can create roles like data entry operator, supervisor, and auditor, each with different access levels to viewing, editing, and deleting records. A typical mistake is granting the supervisor role editing access to submitted records, which compromises audit trails. The platform logs edits but does not flag them prominently in the standard interface. If your project requires audit compliance, you need to add a custom column or export to a dedicated log table to track modification history. Account provisioning through bulk import using a CSV template is the fastest method for large deployments. The process usually takes less than fifteen minutes for a team of three hundred people. Make sure your CSV includes the required fields in the correct order before uploading, or the system will silently skip unrecognized columns. I have seen projects waste half a day debugging provisioning failures that turned out to be a simple column header mismatch in the template.
Limitations You Should Know About
The platform is functional for mid-scale projects up to roughly five hundred thousand records per collection cycle without significant performance degradation. Beyond that threshold, query response times increase noticeably, especially when running custom reports through the admin console. The reporting engine is not designed for complex multi-table joins or large aggregations. If your project needs advanced analytics, you should export raw data to a proper data warehouse rather than relying on the built-in dashboard. Another limitation is the lack of native integration with popular statistical packages like SPSS or R. You can export to CSV and SPSS sav formats, but you lose metadata such as skip patterns, validation rules, and coded response labels during the export. This means you spend additional time recoding variables after export. I recommend building a codebook export routine within the admin console or writing a post-processing script that maps form field definitions to the exported dataset automatically. The support model is ticket-based with average response times between four and twelve hours during business days. For projects running in time-sensitive environments like election monitoring or emergency response, this delay can be a real constraint. In those cases, budgeting for a premium support tier that offers faster response windows is worth the cost. The regular tier assumes you have internal technical capacity to handle most issues yourself.
When to Consider Alternatives
If your project involves real-time data streaming, multi-language support beyond fifty languages, or integration with existing GIS infrastructure through web services, you might evaluate other platforms like KoboToolbox, SurveyCTO, or CommCare. Censitrac works well as a standalone solution for population surveys and census operations where offline reliability and simple form logic are the priorities. It is less suited for projects requiring complex branching across hundreds of questions, automated data quality algorithms, or deep integration with external databases. Knowing your actual requirements before purchasing a license will save you from reconfiguring everything after deployment.