Why your sample means keep converging even when the underlying data looks like garbage
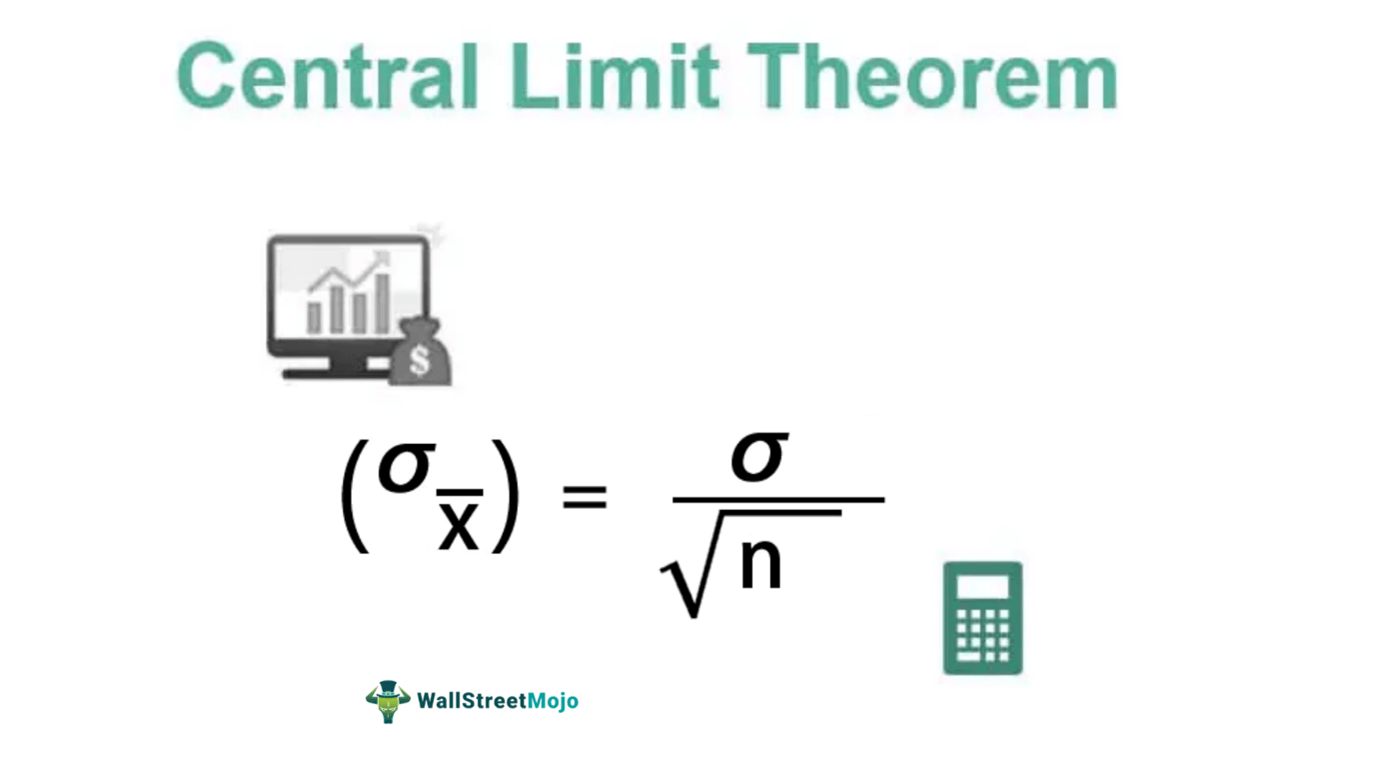
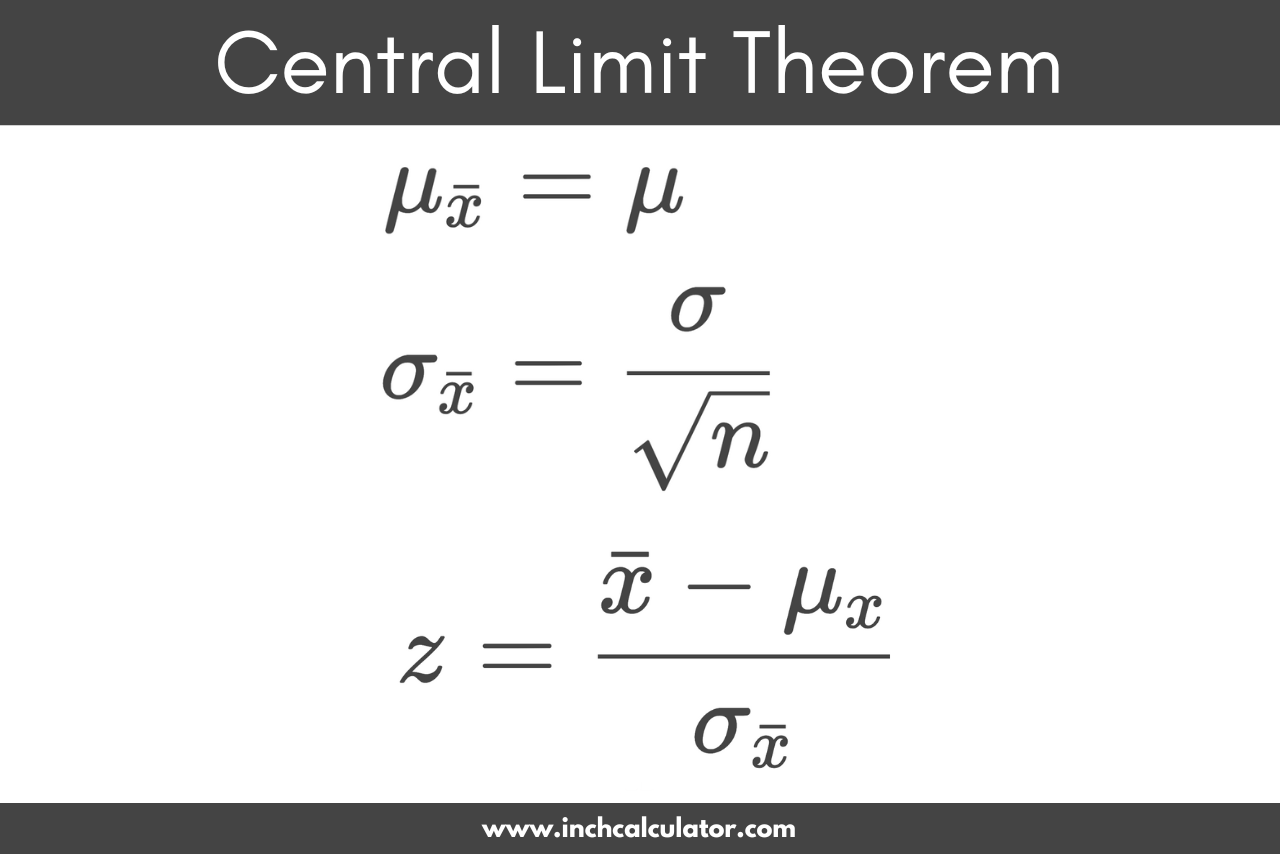
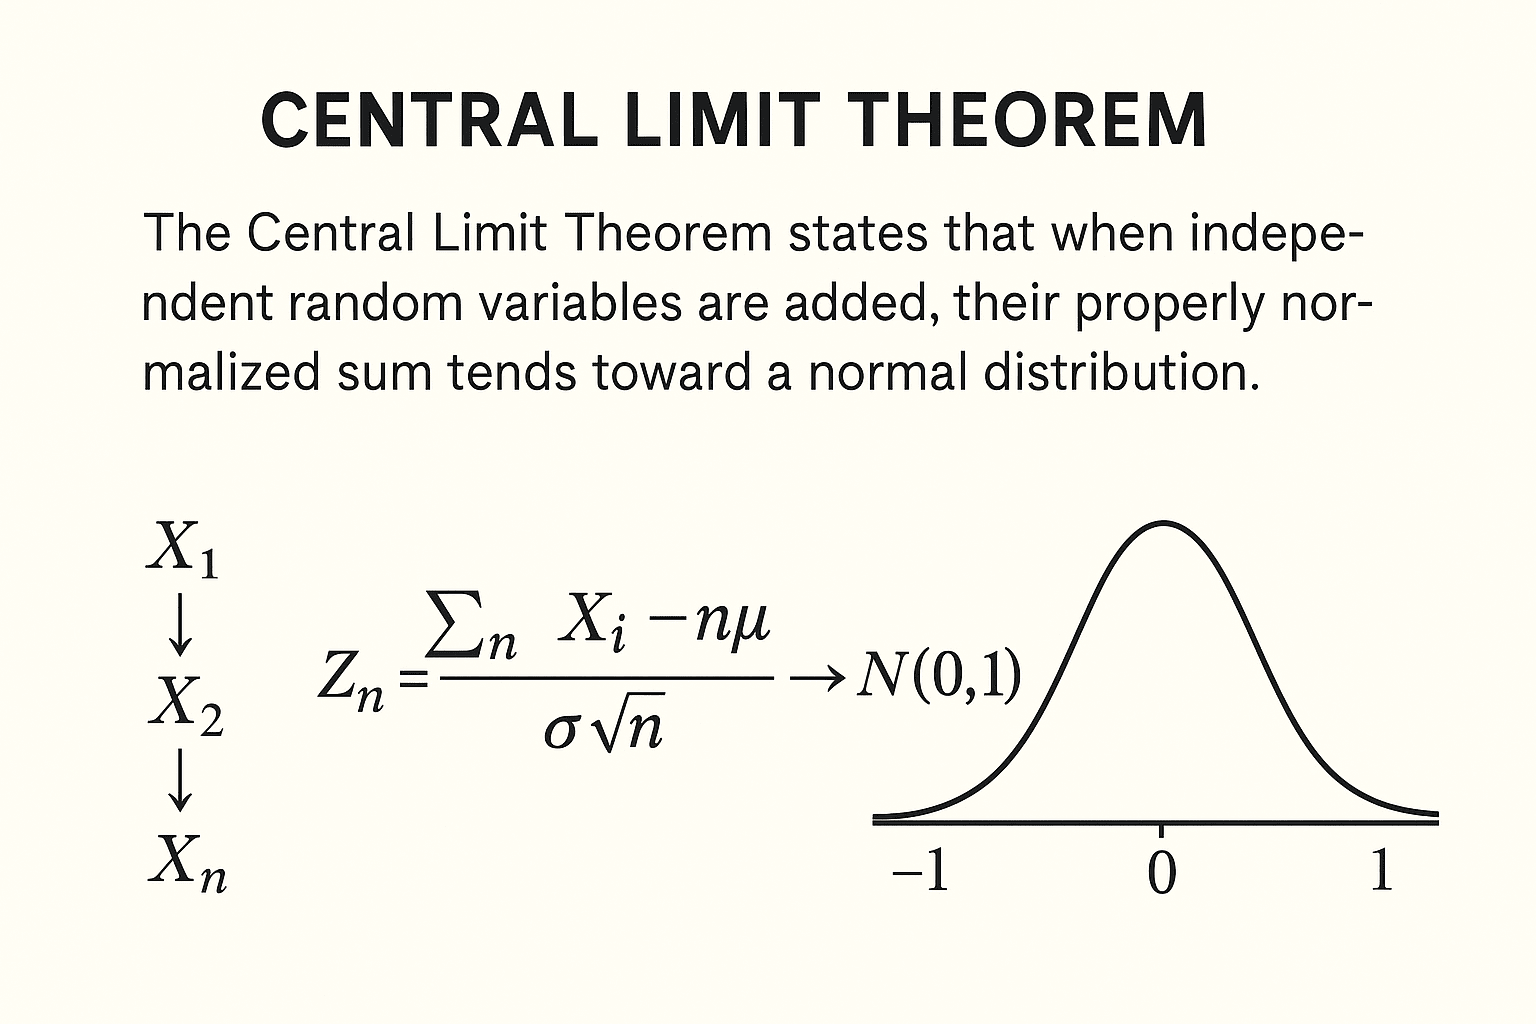
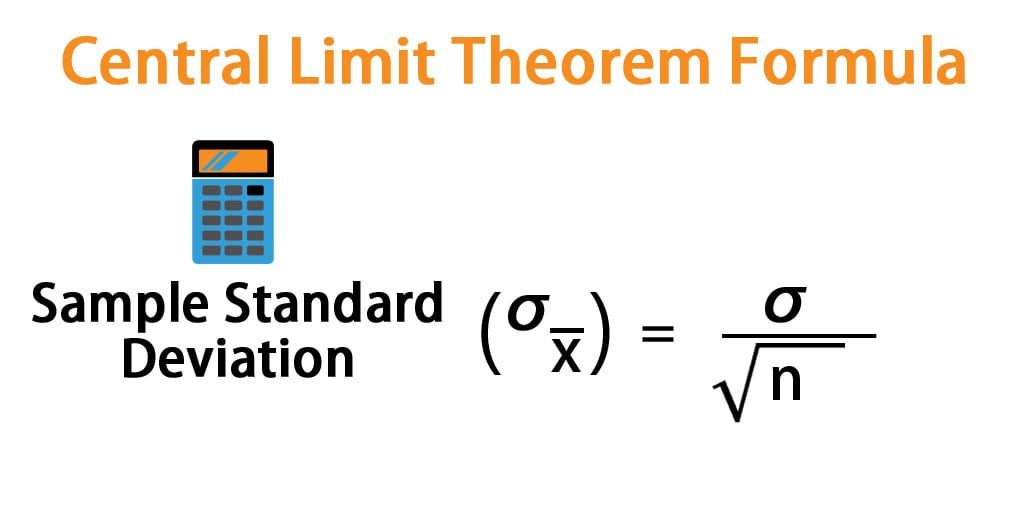
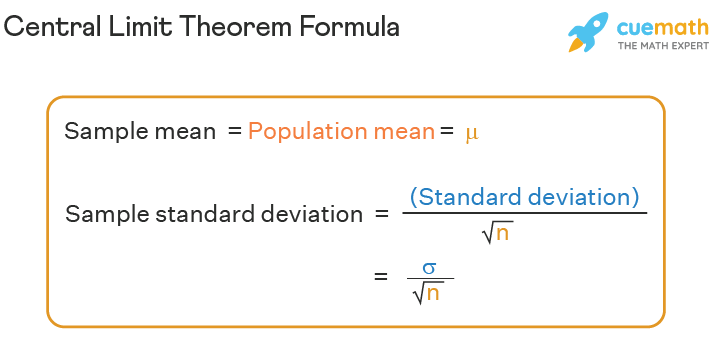
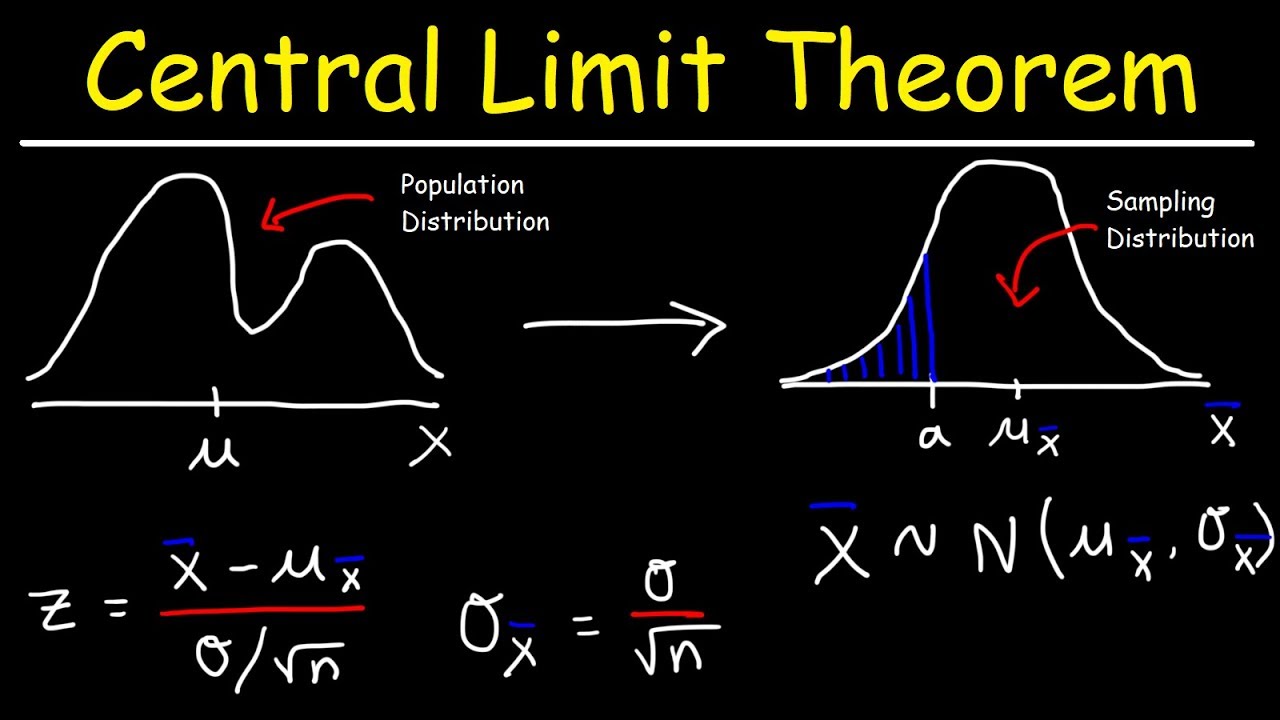
I spent about three weeks debugging a quality control pipeline last year where the standard deviation estimates were wildly inconsistent across shifts. The raw data was uniform, bimodal, and occasionally rectangular depending on which machine logged it. I kept getting different variance numbers from the same production line. That's when I went back and actually applied the Central Limit Theorem Formula instead of trying to model the population distribution directly. It saved the project. The core formula is straightforward enough that people overcomplicate it. If you take repeated samples of size n from any population with mean and standard deviation , the sampling distribution of the sample means will approximate a normal distribution with mean and standard deviation /n. That /n term is the standard error, and it shrinks as your sample size grows regardless of what the original population looks like. Here's how you write it out in practice:
_x = _x = / n Where x represents the sample mean, is the population mean, is the population standard deviation, and n is your sample size. When is unknown, which is almost always the case in real work, you substitute the sample standard deviation s and use the t-distribution instead of the normal distribution. The difference matters more than most people think when n drops below 30.
I used to skip that distinction. Wrong.
Get the Full Details
How to actually use this in a real analysis
Let me walk through the steps the way I actually do them, not the way textbooks present them. First, grab your data and verify you're working with independent observations. That sounds obvious but I've seen it fail repeatedly when time-series data gets treated as i.i.d. If your measurements have autocorrelation, the effective sample size is smaller than n, and your standard error estimate will be too narrow. Run a quick Durbin-Watson test or plot the autocorrelation function before proceeding. Second, determine what you're actually estimating. Are you building a confidence interval for a population mean? Testing a hypothesis? Calculating a probability for a sample mean? The formula application changes depending on the question.
Third, calculate the standard error. Take your sample standard deviation and divide by the square root of your sample size. With n=100 and s=12, your standard error is 1.2. Not 12. Not 120. One point two. This is where most junior analysts make arithmetic errors because they forget the square root. Fourth, pick your critical value. For a 95% confidence interval using the normal approximation, that's 1.96. If you're working with smaller samples and don't know the population standard deviation, look up the t-critical value for your degrees of freedom. With n=25, that's t(0.025, 24) 2.064 instead of 1.96. The gap is small at n=25 but grows substantially as n shrinks. Fifth, compute the interval: x ± (critical value × standard error). That's it. The whole procedure takes maybe twenty minutes once you've done it a dozen times. Before I automated it, a single analysis across multiple product lines took roughly two hours of spreadsheet manipulation.
Where the theorem actually breaks down
The Central Limit Theorem is powerful but it is not universal. There are distribution families where convergence is genuinely slow or effectively absent. Heavy-tailed distributions with infinite variance, like certain Pareto or Cauchy setups, will not produce a converging sampling distribution no matter how large n gets. The standard error formula simply does not apply. I encountered this once when analyzing failure times on a semiconductor process where the tail behavior followed a power law. My confidence intervals were shrinking toward zero as I added more samples, which should have been an immediate red flag. Switched to bootstrapping for that project and got estimates that actually made physical sense. Bernoulli proportions are another edge case. The rule of thumb is that both np and n(1-p) should exceed 5, ideally 10, for the normal approximation to be reliable. When p is near 0 or 1 and your sample is modest, the sampling distribution stays skewed and the symmetric normal approximation gives you misleading intervals. Use the Clopper-Pearson exact method or a Wilson score interval instead. Dependence between observations is the third major failure mode. Clustered data, repeated measures, spatial autocorrelation — all of these violate the independence assumption and invalidate the /n formula. I worked on a customer satisfaction study where respondents were grouped by region, and ignoring the cluster structure inflated my effective sample size by roughly 40%. The confidence intervals were far too tight and my conclusions were overconfident.
A practical workaround that saved me weeks
When I hit the heavy-tail problem with the semiconductor data, I didn't have the luxury of waiting for convergence. I resorted to a bootstrap approach: resampling my observed data with replacement thousands of times, computing the mean for each resample, and using the empirical quantiles of that bootstrap distribution as my confidence interval. It ran in about eight minutes on a standard laptop using R's boot package, versus the two weeks I'd been spending trying to find a parametric model that fit the tail behavior. The bootstrap doesn't care about the underlying distribution. It only requires that your sample is representative and your observations are independent, which was satisfied in my case. The tradeoff is computational cost and the fact that bootstrapping still struggles with extreme tails because you can't resample information that isn't in your data. If your sample has zero observations above a certain threshold, your bootstrap distribution will also have zero observations above that threshold, regardless of how many resamples you draw. Parametric methods, when applicable, are more efficient. But when the assumptions are violated, bootstrap is usually the safer bet.
Common mistakes I see in production code
People confuse the standard deviation of the population with the standard error of the mean. They are related but not the same. describes spread in the data. /n describes spread in the sampling distribution. Using instead of /n in your confidence interval calculation will make your interval roughly n times wider than it should be. With n=100, that's a factor of 10 error. Another frequent error is applying the normal approximation to the sampling distribution of the median or other robust estimators without adjusting the formula. The CLT still applies to the median under regularity conditions, but the asymptotic variance is different: ²/(2n) instead of ²/n. Using the wrong variance formula gives you intervals that are too narrow by a factor of about 1.25. And yes, some people still treat the CLT as a guarantee that their data will look normal. It doesn't. Your data can be anything. The theorem only says the distribution of sample means approaches normality as n increases. A sample of 30 from a highly skewed exponential distribution will still produce skewed sample means. The approximation improves with larger n, but "large" depends on the degree of skewness. For moderate skew, n=30 is usually adequate. For extreme skew, you might need n=100 or more before the normal approximation is reliable enough for decision-making.
When to just trust the math and when not to
The Central Limit Theorem is one of those results that feels almost too good to be true because it is. It works for continuous distributions, discrete distributions, mixed distributions, and most things you encounter in engineering and operations research. The convergence rate varies. The formula is simple. The implications are enormous. But it has boundaries. Infinite variance distributions are one. Extreme dependence is another. Tiny samples from highly asymmetric populations are a third. Know your data before you apply the formula. A five-minute exploration of your distribution — histogram, Q-Q plot, skewness and kurtosis values — will tell you whether the CLT is safe to invoke or whether you need a different approach entirely.