Understanding the Multivariable Chain Rule
The chain rule in three variables shows up constantly in physics simulations and engineering work. Most people learn it as a formula to memorize for exams, but actually computing one manually is a different problem entirely. I spent years running these calculations by hand before writing scripts to automate them, and the gap between theory and practice is larger than most textbooks let on. The notation gets messy fast when you stop thinking in one variable. Here is what you are actually working with: If z = f(x, y) where x = g(t) and y = h(t), then dz/dt = (f/x)(dx/dt) + (f/y)(dy/dt).
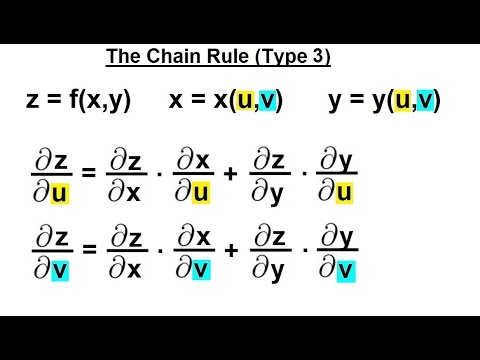
That is the simple version. The moment you add a third intermediate variable or nested functions, the tree diagram approach becomes essential. Draw every dependency from top to bottom, then trace every path from the outer variable to the innermost one. Each path gives you one term. Multiply along the path and sum the terms. That is all it is mechanically. I remember working on a heat transfer model where temperature depended on two spatial coordinates, each of which depended on time and on each other through a coordinate transform. The problem had x(t, s) and y(t, s) feeding into T(x, y). Computing dT/ds required tracking four partial derivative terms instead of the usual two. I drew the dependency graph on scrap paper first. Missing just one path in that diagram meant the final gradient was wrong by a factor of two. It took me forty minutes to catch the error. The Jacobian form handles this more cleanly when you have many variables. If u = f(x, x, ..., x) and each x depends on parameters t, t, ..., t, the chain rule says the partial derivative u/t equals the dot product of the gradient of f with the j-th column of the Jacobian matrix J. Writing it out as matrix multiplication avoids the path-tracing confusion entirely for larger systems.
This is where beginners typically go wrong. The most common error is assuming that partial derivatives commute with substitution in a way that simplifies the expression before differentiating. If f(x, y) = x² + xy and you substitute x = sin(t) and y = t² first, then differentiate the resulting single-variable expression, you get the right answer. But if you try to cancel terms across partials without careful bookkeeping, you will lose factors. I once saw a graduate student's simulation fail silently because they dropped the dy/dt term entirely, treating y as independent when it clearly depended on t through the coordinate mapping. Another pitfall appears when using the chain rule with implicit dependencies. Suppose you have a constraint equation like x² + y² + z² = R² and you need dz/dt while x and y both vary with time. You cannot solve for z explicitly in every case, so you differentiate the constraint implicitly while applying the chain rule to each term. This gives you 2x(dx/dt) + 2y(dy/dt) + 2z(dz/dt) = 0, which rearranges to dz/dt = -(x·dx/dt + y·dy/dt)/z. The formula looks straightforward until z approaches zero at the equator of the sphere. At that boundary, dz/dt blows up numerically. In practice I handle this by switching to a parameterization like spherical coordinates near the singular points rather than trying to push through with implicit differentiation. Directional derivatives are essentially the chain rule in disguise. If you want the rate of change of f in the direction of vector v at point p, you compute f(p) · v. This is identical to parameterizing the line through p in direction v as r(t) = p + tv, composing f with r, and differentiating with respect to t at t = 0. Recognizing this equivalence saves time because it lets you convert directional derivative problems into familiar single-variable chain rule problems on the fly.
Get the Full Details
For numerical work, automatic differentiation libraries handle these compositions without symbolic manipulation. The trade-off is that you lose visibility into which derivative term is causing numerical instability. When my finite element mesh started producing unreasonable stress values near a curved boundary, the autodiff output looked correct locally but the global result was off by orders of magnitude. Tracing back through the chain rule terms revealed that a second-order derivative was being approximated with insufficient grid resolution. Switching to an adaptive mesh near that boundary fixed it, but only after identifying the problematic term manually. The implicit function theorem provides the theoretical foundation for when you can safely treat implicitly defined variables as functions of your parameters. It guarantees local solvability when the relevant Jacobian determinant is nonzero. In application, this means checking that your constraint surface is not degenerate at the point you are evaluating. If the determinant vanishes, the chain rule framework still applies but you may need to switch to a different coordinate patch or use Lagrange multipliers instead. For most coursework and applied problems, drawing the dependency tree and writing out every path term is sufficient. The Jacobian matrix formulation becomes necessary when you have more than three or four intermediate variables. Beyond that, you are usually writing code rather than doing it by hand, and the matrix notation is what your computation library expects anyway.