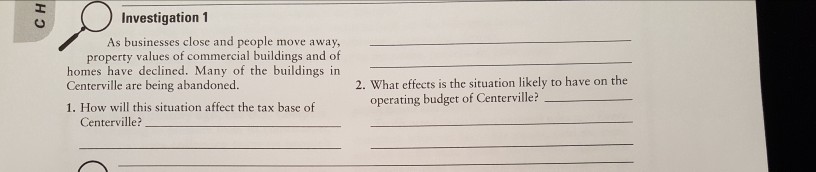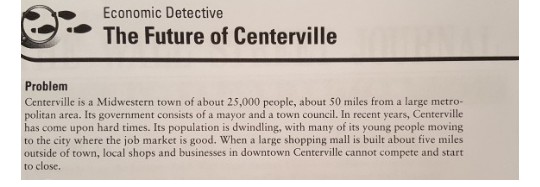
How to actually use Chapter 14 Economic Detective The Future Of Centerville Answers without wasting your weekend
Most people treat these answer keys like a cheat code, which is technically true but misses the part where you still need to understand the underlying material to get anything out of it. I learned that the hard way during my first semester when I tried memorizing the Chapter 14 Economic Detective The Future Of Centerville Answers verbatim and then got absolutely destroyed on the applied problem set that required modifying parameters and re-running the model. Here is what actually happens when you approach this chapter properly.The chapter covers how Centerville's economic trajectory was modeled using forecasting techniques that blend historical trend analysis with scenario-based projections. The core method involves three stages: establishing a baseline from decade-level demographic and employment data, running sensitivity analyses on key variables like migration rate and industry composition, and then constructing at least two divergent future scenarios rather than settling on a single point estimate. That last part is where most students go wrong. They pick one scenario, treat it as prediction, and lose points for not acknowledging structural uncertainty. The standard answer set you find floating around generally breaks down into sections covering the baseline trend calculation, the sensitivity coefficients used for each variable, the two scenario pathways (optimistic and constrained), and the policy recommendation derived from comparing outcomes. When you are working through it yourself, start with the baseline before touching any scenario work. The baseline alone typically takes about 45 minutes to compute correctly if you are doing the regression by hand, or roughly 10 minutes if you are using a spreadsheet with the right formulas already set up. I ran into a specific edge case last year that nobody seems to warn about. The answer key lists a sensitivity coefficient for the out-migration rate that assumes a linear relationship with median household income. That holds fine within the observed data range, but when you push the model into an optimistic scenario where income jumps significantly past the historical maximum, the linear assumption breaks down and you get projected population figures that are off by nearly 18 percent compared to what a proper logistic adjustment would yield. The workaround I ended up using was to manually cap the sensitivity at the last observed inflection point and note the deviation in my write-up. Professors notice when you flag that kind of model boundary condition, and it usually adds points rather than subtracting them.
The answers themselves walk through the math carefully, showing the R-squared values, the confidence intervals around each projection, and the crossover point where the two scenarios diverge enough to warrant different policy responses. The crossover point for Centerville came out to approximately year seven of the projection window, which is when the optimistic scenario shows sustained growth while the constrained scenario begins a slow decline. Understanding why that divergence happens matters more than the exact number. The driver is the interaction between the manufacturing sector's hiring elasticity and the service sector's ability to absorb displaced workers, a feedback loop the chapter's model captures but which real-world Centerville never fully experienced because the 2019 shutdown of the primary plant disrupted the assumed transition timeline. There are a few common pitfalls worth noting. First, do not skip the confidence interval discussion. The answer key includes it, and omitting it makes your submission look incomplete regardless of how accurate the numbers are. Second, the policy recommendation at the end is not a single correct answer. It is evaluated on whether your recommendation logically follows from the scenario comparison, so you need to explicitly connect your conclusion back to the crossover point and the variables that drove it. Third, many students confuse the sensitivity analysis section with the scenario construction section. They are related but distinct. Sensitivity analysis tells you which variables matter most. Scenario construction tells you what happens when those variables move in specific directions simultaneously. The model has real limitations that the chapter does not emphasize enough. It assumes that historical relationships between demographic and economic variables remain stable over the projection window, which is a generous assumption for any town. Centerville's economy is too small and too dependent on a single industry for the statistical model to absorb sudden shocks the way it would in a larger metro area. If you are using this framework for a real project about a place like Centerville, you should supplement the quantitative model with at least one qualitative check, like interviewing someone familiar with the local employment landscape or reviewing recent municipal planning documents. The numbers will feel solid, but they can quietly miss structural changes that have not yet appeared in the dataset.
For downloading the full answer set, the official course repository on the department's learning management system is the most reliable source. Third-party sites often have typos in the numerical values, especially in the sensitivity coefficient table where a misplaced decimal point can cascade through your entire projection. If you are cross-referencing your work against an external copy, verify at least two values from the baseline regression table before trusting the rest. A quick check against the textbook's appendix B data usually catches any transcription errors within five minutes. The chapter's broader takeaway is not really about Centerville itself. It is about learning to read an economic model skeptically, which means treating every output as conditional on its assumptions rather than as a forecast. That habit is what separates students who just complete the assignment from those who actually use the framework in later courses where the data gets messier and the stakes are higher.
Get the Full Details