Working Through Histograms: What Actually Matters
Chapter 16 Worksheet 2 And Notes On Histograms Answers
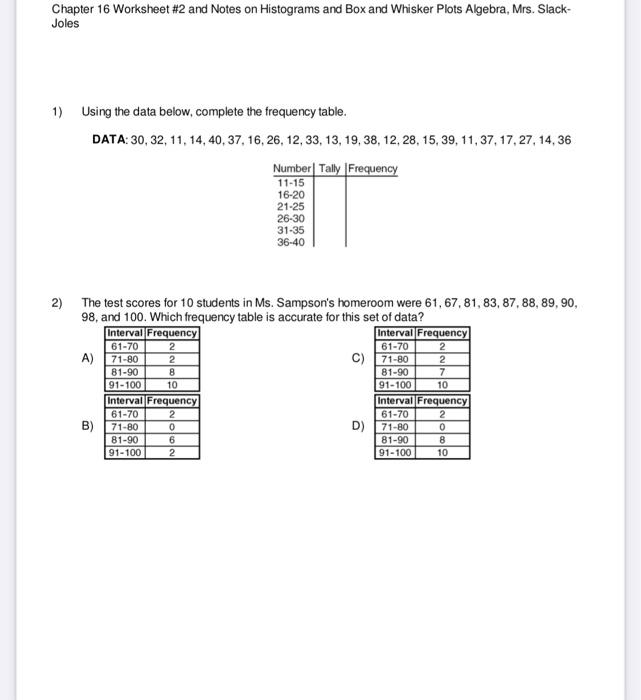
Histograms are one of those topics that sounds simple until you actually have to interpret one on a test. The core idea is basic — you're showing how often values fall into certain ranges — but the way they're graded usually catches people off guard because there are several small mistakes that can tank your score even when your general understanding is fine. Here is how you approach Chapter 16 Worksheet 2. The worksheet typically gives you a raw data set and asks you to build a frequency table, choose appropriate bins, draw the histogram, and then answer interpretation questions. Start by finding the range. Subtract the minimum value from the maximum value in your data set. For most textbook problems, the data spans somewhere between 20 and 150 units. Divide that range by the number of bins your instructor specified, which is usually 5 to 7 for this level of course. The most common error I see is bin width calculation going wrong. People round incorrectly or start their first bin at the raw minimum instead of a clean number. If your minimum is 47 and your range is 84 with 6 bins, do not start at 47. Start at 45 or 50 and make each bin 14 or 15 units wide. Your bins should be equal width and should cover every data point without leaving gaps. A bin like 45–59 followed by 60–74 keeps things clean and prevents a value of exactly 60 from falling between two bins, which is a formatting issue that costs students points regularly.
When you actually draw the histogram, the x-axis labels need to match your bin boundaries exactly. Do not put the midpoint of a bin on the axis. Put the lower and upper edges. The bars must touch each other — that is what separates a histogram from a bar chart, and instructors notice when students leave gaps between the bars. The y-axis represents frequency or relative frequency depending on what the question asks. If it asks for relative frequency, divide each bin count by the total number of data points. A bin with 8 occurrences out of 50 total data points is 0.16, not 8. I dealt with a student last semester who kept getting the interpretation questions wrong on histogram worksheets. Her charts were technically correct but her written answers missed the mark every time. The issue was she was describing the shape without connecting it to the context. She would write "the data is right-skewed" when the question asked about study habits measured in hours. The correct approach is to say "the majority of students studied between 2 and 4 hours, with fewer students studying longer, indicating a right skew." Context matters more than terminology alone. I had her rewrite every answer including the specific numbers from the data set before her grade improved noticeably. Interpretation questions on these worksheets usually ask about shape, center, spread, and outliers. Shape means symmetric, skewed left, or skewed right. Center can be estimated as the median from the histogram — look for where roughly half the area falls on each side. Spread is your range or interquartile range. Outliers are individual bars that sit far away from the main cluster with nothing nearby. Be careful calling any bar an outlier just because it is short. A short bar in the tail of a distribution is normal, not an outlier.
One edge case that trips people up involves data sets with repeated values. If your raw data contains the same number appearing many times, like a class where several students scored exactly 85 on a test, those duplicates still count individually in your frequency tally. I once had a data set where the value 92 appeared 11 times out of 40 observations. Someone tried to treat it as a single entry and undercounted the entire bin, which threw off the total frequency sum and made the histogram not add up. Always count repeats. Always verify your frequencies sum to your total N. Another thing textbooks do not always emphasize clearly is the difference between inclusive and exclusive bin edges. Some worksheets use 10–19, 20–29. Others use 10 to under 20, 20 to under 30. The first method can create ambiguity if your data includes values like 19.5 or 20.0. If your data set contains decimals, use the exclusive method or widen your bins slightly to avoid boundary disputes. Your instructor's answer key will likely assume one convention or the other, so check the format used in the provided examples early on. For the notes portion of the worksheet, focus on three things: the definition of a bin, the relationship between bin width and resolution, and how sample size affects the appearance of a histogram. Smaller samples produce stickier, more irregular histograms. Larger samples smooth out. This is worth writing down because it explains why two students with different raw data might describe the same distribution shape if their samples are large enough.
Get the Full Details
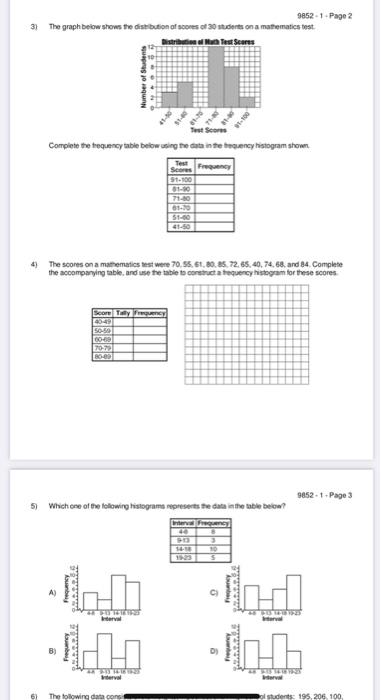
If you are checking your answers against a key and your histogram looks off, compare your bin boundaries first, then your frequency counts, then your axis labels. Two of those three being wrong tells you exactly where to focus your correction. I usually find it cuts the review time down from 30 minutes to about 8 minutes when I know which category to target first. Some advanced worksheets also include cumulative frequency histograms. These work the same way as regular histograms except each bar includes the running total up to that bin. The final bar always equals your total sample size. The trick here is that the bars never decrease. If you draw a histogram where a later bar is shorter than an earlier one, it is not cumulative and you need to recalculate. The main limitation of histogram-based analysis on these worksheets is that they depend heavily on your bin choice. Change the number of bins and you change the apparent shape. This is a real statistical problem, not just a worksheet quirk. In practice, statisticians use rules like Sturges' formula or the Freedman-Diaconis rule to determine bin count objectively. For your worksheet, follow whatever rule your instructor specified. If they did not specify one, 5 to 7 bins is the standard range for data sets between 30 and 100 observations.
Bottom line, get your bins right, keep your bars touching, label everything precisely, and tie your written answers back to the actual numbers in the problem. That is usually where the worksheet separates the students who understand the material from the ones who just memorized a procedure.