Getting Your Head Around Central Tendency and Spread
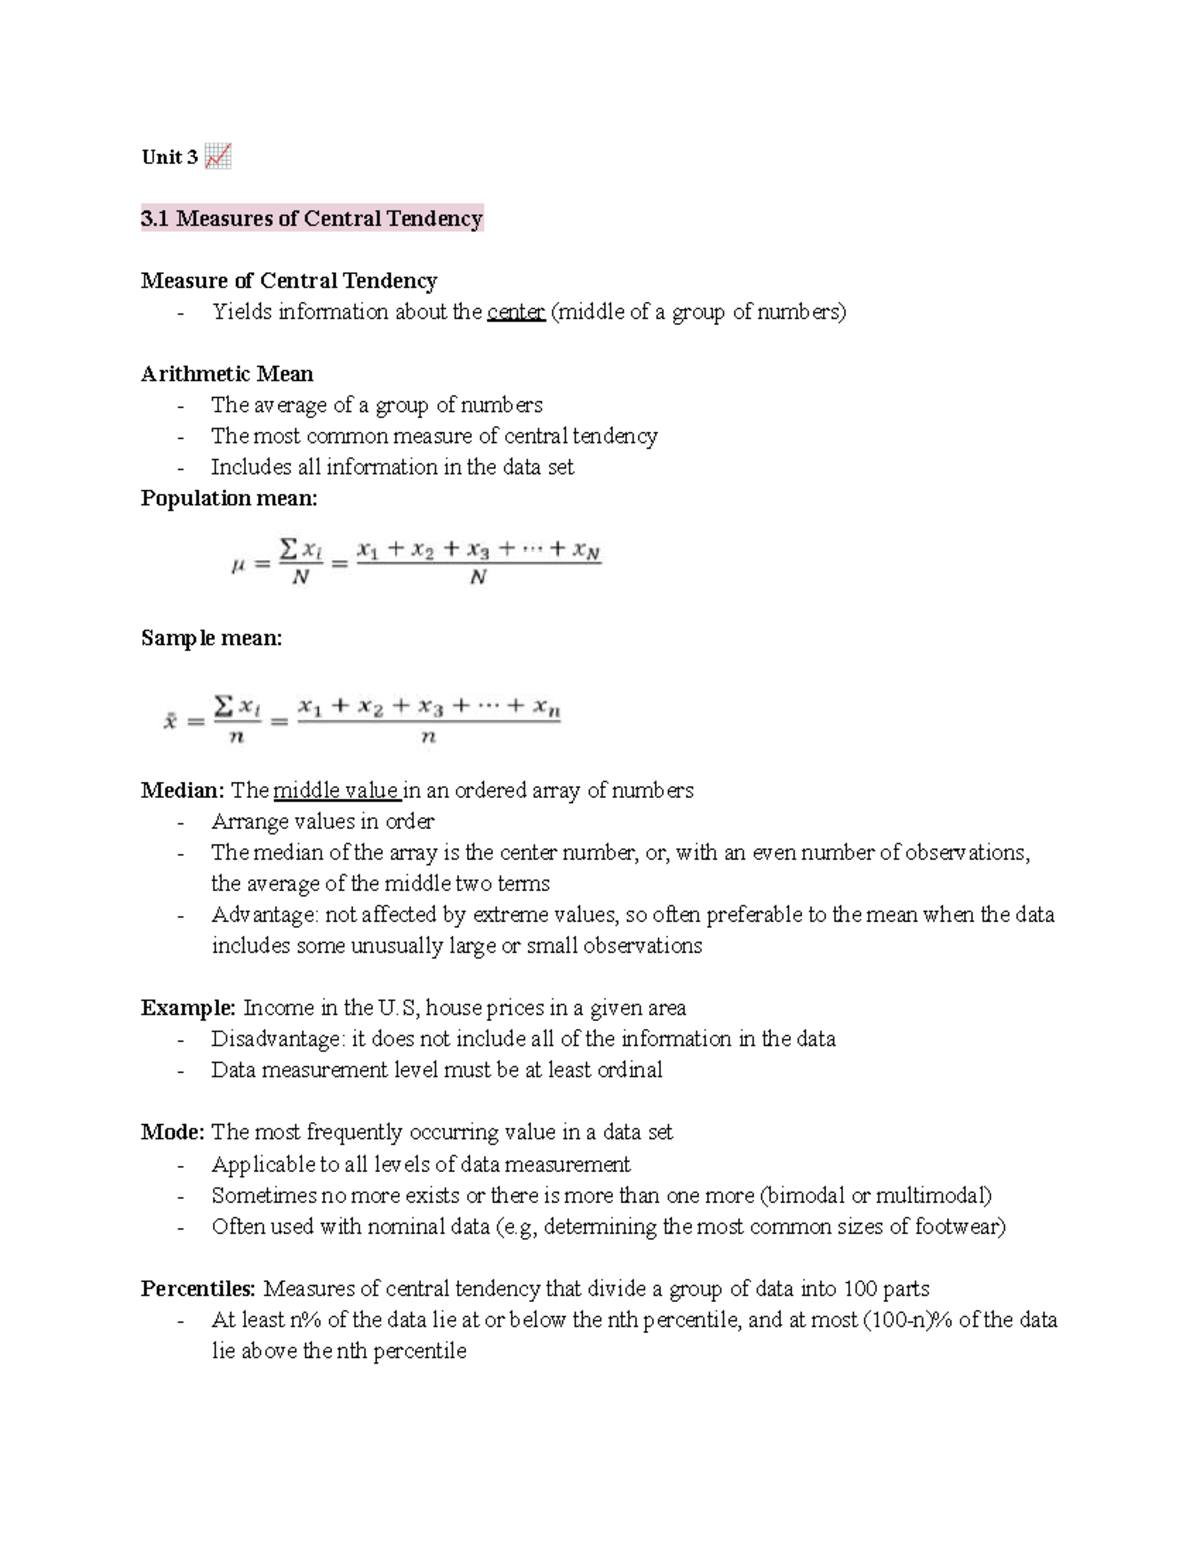
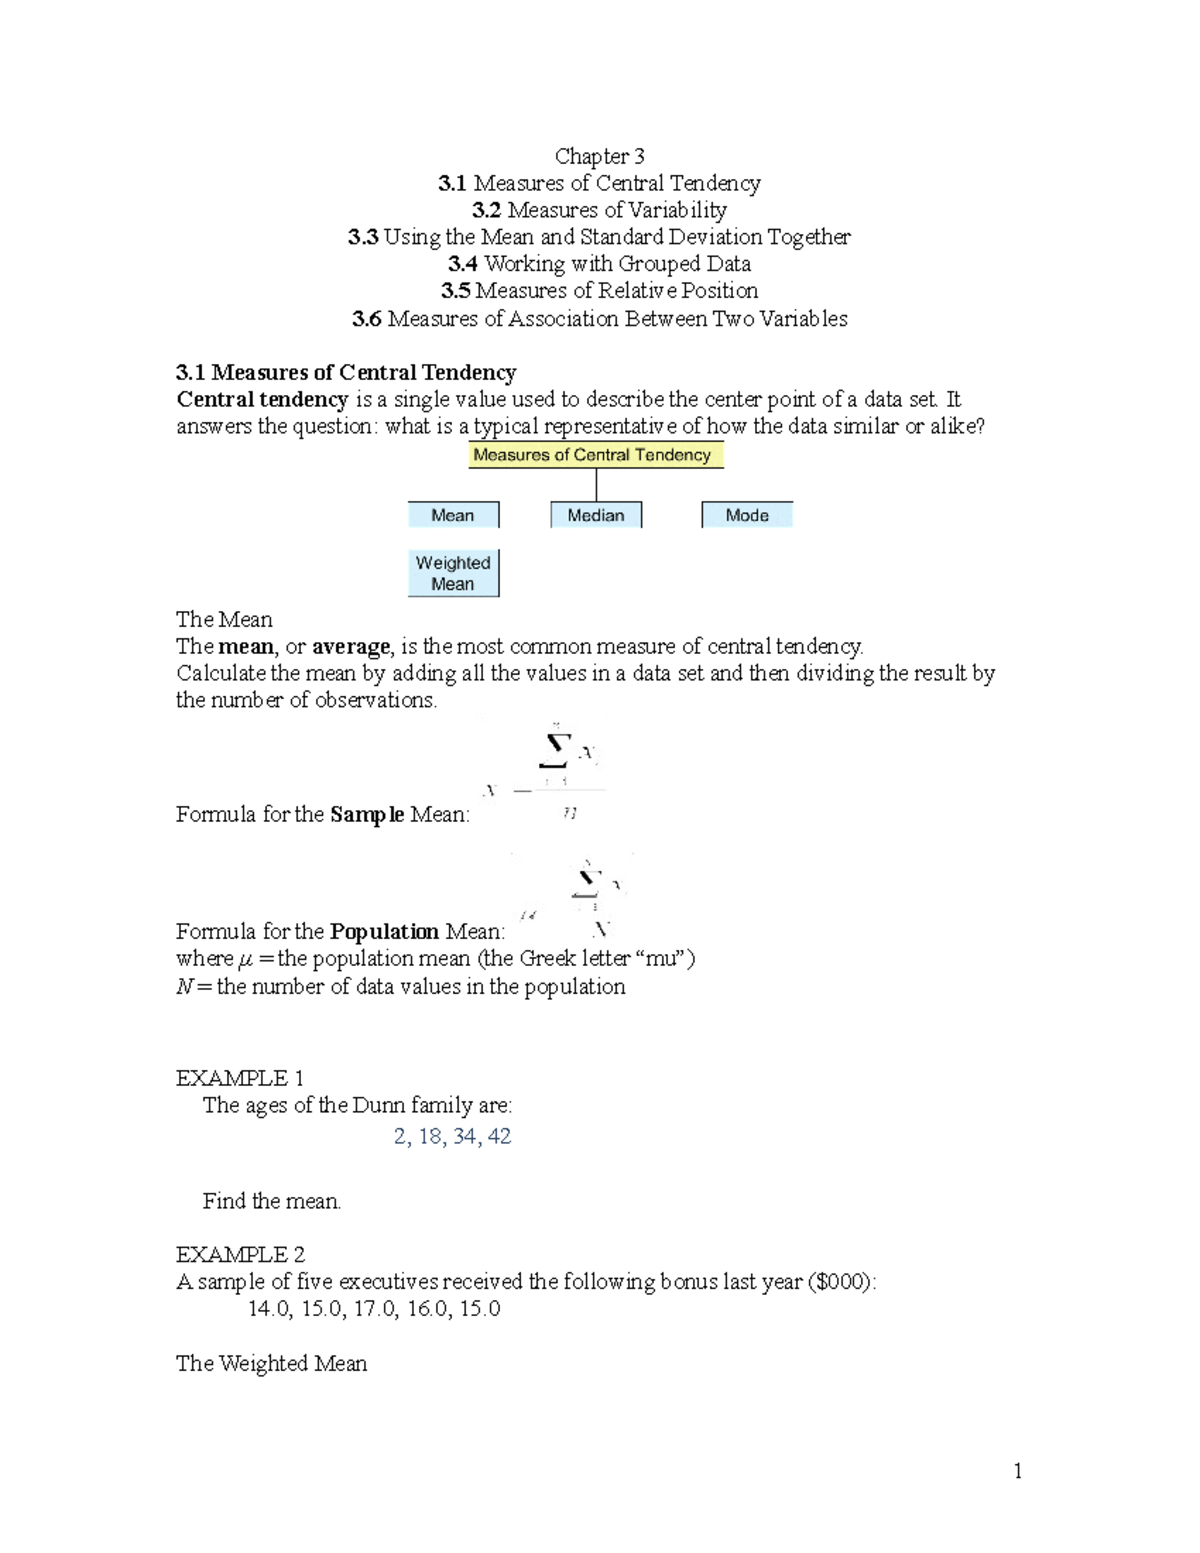
When you first open a stats textbook to the chapter on measures of central tendency and variability, everything looks clean. Mean, median, mode, range, variance, standard deviation. Five formulas, a couple of rules, and you move on. The problem is that real data never obeys the rules. I learned that the hard way during my second semester when I was analyzing survey responses about workplace satisfaction, and the dataset had a handful of people who marked every question as a 1 out of 5 while everyone else clustered between 4 and 5. The mean came out to about 3.2, which somehow made it look like opinions were evenly split. They weren't. The median was 4.5. That single gap between mean and median told me the story the average was hiding. Central tendency is just a fancy way of saying "what number represents this bunch of data." There are three main ways to do it, and picking the wrong one is the most common beginner mistake I see. The mean is what people call the average. Add everything up and divide by the count. It's sensitive to outliers. One extreme value can pull it in a direction that makes it misleading for the rest of your data. That's not a flaw in the math. It's a feature you need to respect.
The median is the middle value when everything is sorted. Half the data sits above it, half below. It doesn't care about extremes the way the mean does. If you're dealing with income data, housing prices, or anything where a few massive numbers skew the picture, the median is usually the one you want. The mode is the most frequently occurring value. It sounds simple but most people forget when it's actually useful. Bimodal distributions show up more often than textbooks admit, and the mode is the only measure of central tendency that can reveal that. A dataset about commute times might have one peak for people who work downtown and another for remote workers. The mean would land somewhere in between that nobody actually experiences. Variability measures tell you how spread out the data is. Range is the easiest but also the least useful on its own because it only looks at the highest and lowest values. A dataset of test scores ranging from 42 to 100 tells you almost nothing about what happened in the middle.
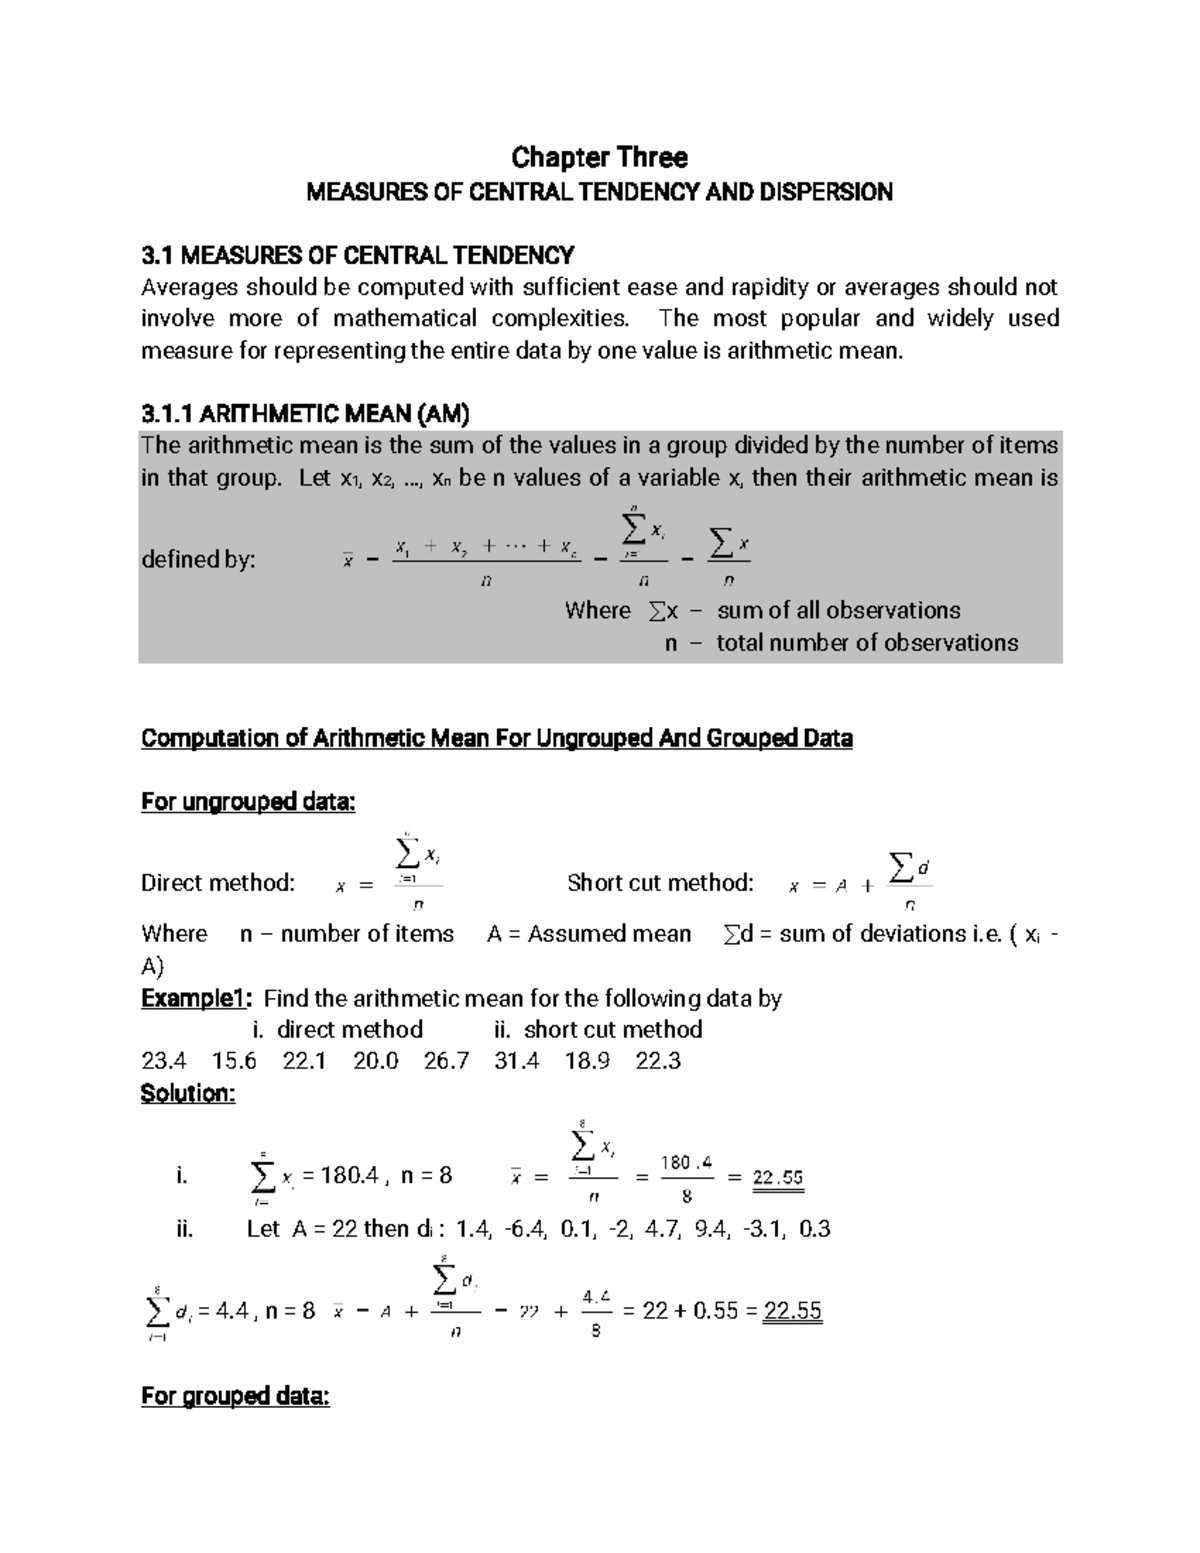
Variance is the average of the squared deviations from the mean. Squaring the differences makes everything positive and penalizes outliers more heavily. The formula is straight forward but the result is in squared units, which is why nobody reports variance by itself. Standard deviation is the square root of variance. It brings the number back into the original units so it's interpretable. A standard deviation of 7 points on a test means something. A variance of 49 points squared means nothing to a human being. I once spent three days debugging what I thought was a data entry error because my standard deviation output looked wrong. The numbers were correct. What I had missed was that I was calculating population standard deviation when I should have been using sample standard deviation. The difference is dividing by n versus n minus 1 in the variance formula. Using n for a sample underestimates the true variability. Bessel's correction exists for that reason, and skipping it quietly corrupts every downstream analysis including confidence intervals and hypothesis tests.
Get the Full Details

Interquartile range is another variability measure worth knowing. It's the difference between the 75th percentile and the 25th percentile. It ignores the top and bottom quarters of your data, which makes it robust to outliers. When I'm cleaning data quickly, I calculate IQR first. If the outliers are beyond 1.5 times the IQR above Q3 or below Q1, I flag them. That's the standard Tukey fence method and it catches the obvious problems without requiring a decision about whether to trim, cap, or delete. Skewness is where things get interesting. A distribution can have the same mean and median but completely different shapes. Right skewed data has a long tail stretching toward higher values. Salary data works this way. Left skewed data trails off toward lower values. Age at retirement might look like that. Skewness matters because the mean gets pulled toward the tail while the median stays put. If someone reports that the average salary at their company is $85,000 but the distribution is right skewed, the median is probably significantly lower. Always check both. Kurtosis measures the heaviness of the tails relative to a normal distribution. High kurtosis doesn't mean the peak is sharper. That's a common misconception. It means there's more probability mass in the tails, which translates to more extreme outliers than a normal curve would predict. Low kurtosis means lighter tails and fewer outliers. Most real world datasets are either leptokurtic or platykurtic, and treating them as normal when they're not breaks a lot of statistical procedures.
Here's something people rarely get told in intro classes: standard deviation is only meaningful for symmetric distributions. If your data is skewed, reporting standard deviation alongside the mean gives a false impression of precision. In those cases, report the median and interquartile range instead. Nobody complains about it, and anyone who knows statistics will respect you for it. Another thing that trips people up is the difference between population and sample parameters. Population standard deviation uses the Greek letter sigma and divides by n. Sample standard deviation uses s and divides by n minus 1. Population variance and sample variance follow the same pattern. Mixing these up is easy when you're working with spreadsheet software because Excel's STDEV.P and STDEV.S functions exist, but they don't label themselves obviously. Excel also has VAR.P and VAR.S for variance. If you're using Google Sheets or Python, the function names are different again. Double check which one you're calling. Range is technically the simplest measure of spread but it's also the least stable. Add or remove a single data point and the range can jump dramatically. I've seen range fluctuate by thousands when comparing two samples from the same population just because of one unusual observation in each. For that reason, range is mostly useful as a quick sanity check. If your range is zero, something is wrong with your data entry. If your range is implausibly large, you probably have a unit mismatch or a duplicate column.
Coefficient of variation is another tool that doesn't get enough attention. It's the standard deviation divided by the mean, expressed as a percentage. It lets you compare variability across datasets with different units or very different scales. A standard deviation of 50 dollars on a $1,000 average and a standard deviation of 50 dollars on a $10,000 average describe completely different levels of relative spread. The coefficient of variation makes that comparison explicit. The downside is that it breaks down when the mean is close to zero, since you're dividing by a small number and the percentage explodes. I've run into that exact problem when analyzing defect rates in manufacturing processes where the average defects per unit was less than one. For grouped data, the calculations change slightly. You work with class midpoints and frequencies instead of individual values. The mean formula becomes the sum of midpoint times frequency divided by total frequency. Variance follows the same logic but applied to the grouped format. It's an approximation because you lose the exact values inside each class, but with reasonable class widths the error is usually small enough to ignore. The bigger issue is when class widths vary. Unequal class widths distort the midpoint assumption, and the resulting measures become unreliable. I've corrected this by recoding the data into equal width classes before running the analysis. Percentiles and quartiles deserve a separate mention because they're not measures of central tendency but they're closely related to how we interpret spread. The 90th percentile tells you the value below which 90 percent of observations fall. Quartiles divide the data into four equal parts. Deciles into ten. Percentiles into hundred. Understanding where your mean and median sit relative to these markers gives you a much clearer picture than any single number ever could. If the mean is above the 75th percentile, your distribution is heavily right skewed and the mean is not representative of the typical case.
When you're presenting these results, don't just dump a table of numbers. Report the measure of central tendency and the measure of variability together. Mean with standard deviation. Median with IQR. The combination matters. A mean of 50 with a standard deviation of 5 tells a very different story than a mean of 50 with a standard deviation of 30, even though the central tendency is identical in both cases. The variability determines whether that central value is useful for making predictions or decisions.