Breaking Down the Korean Writing System
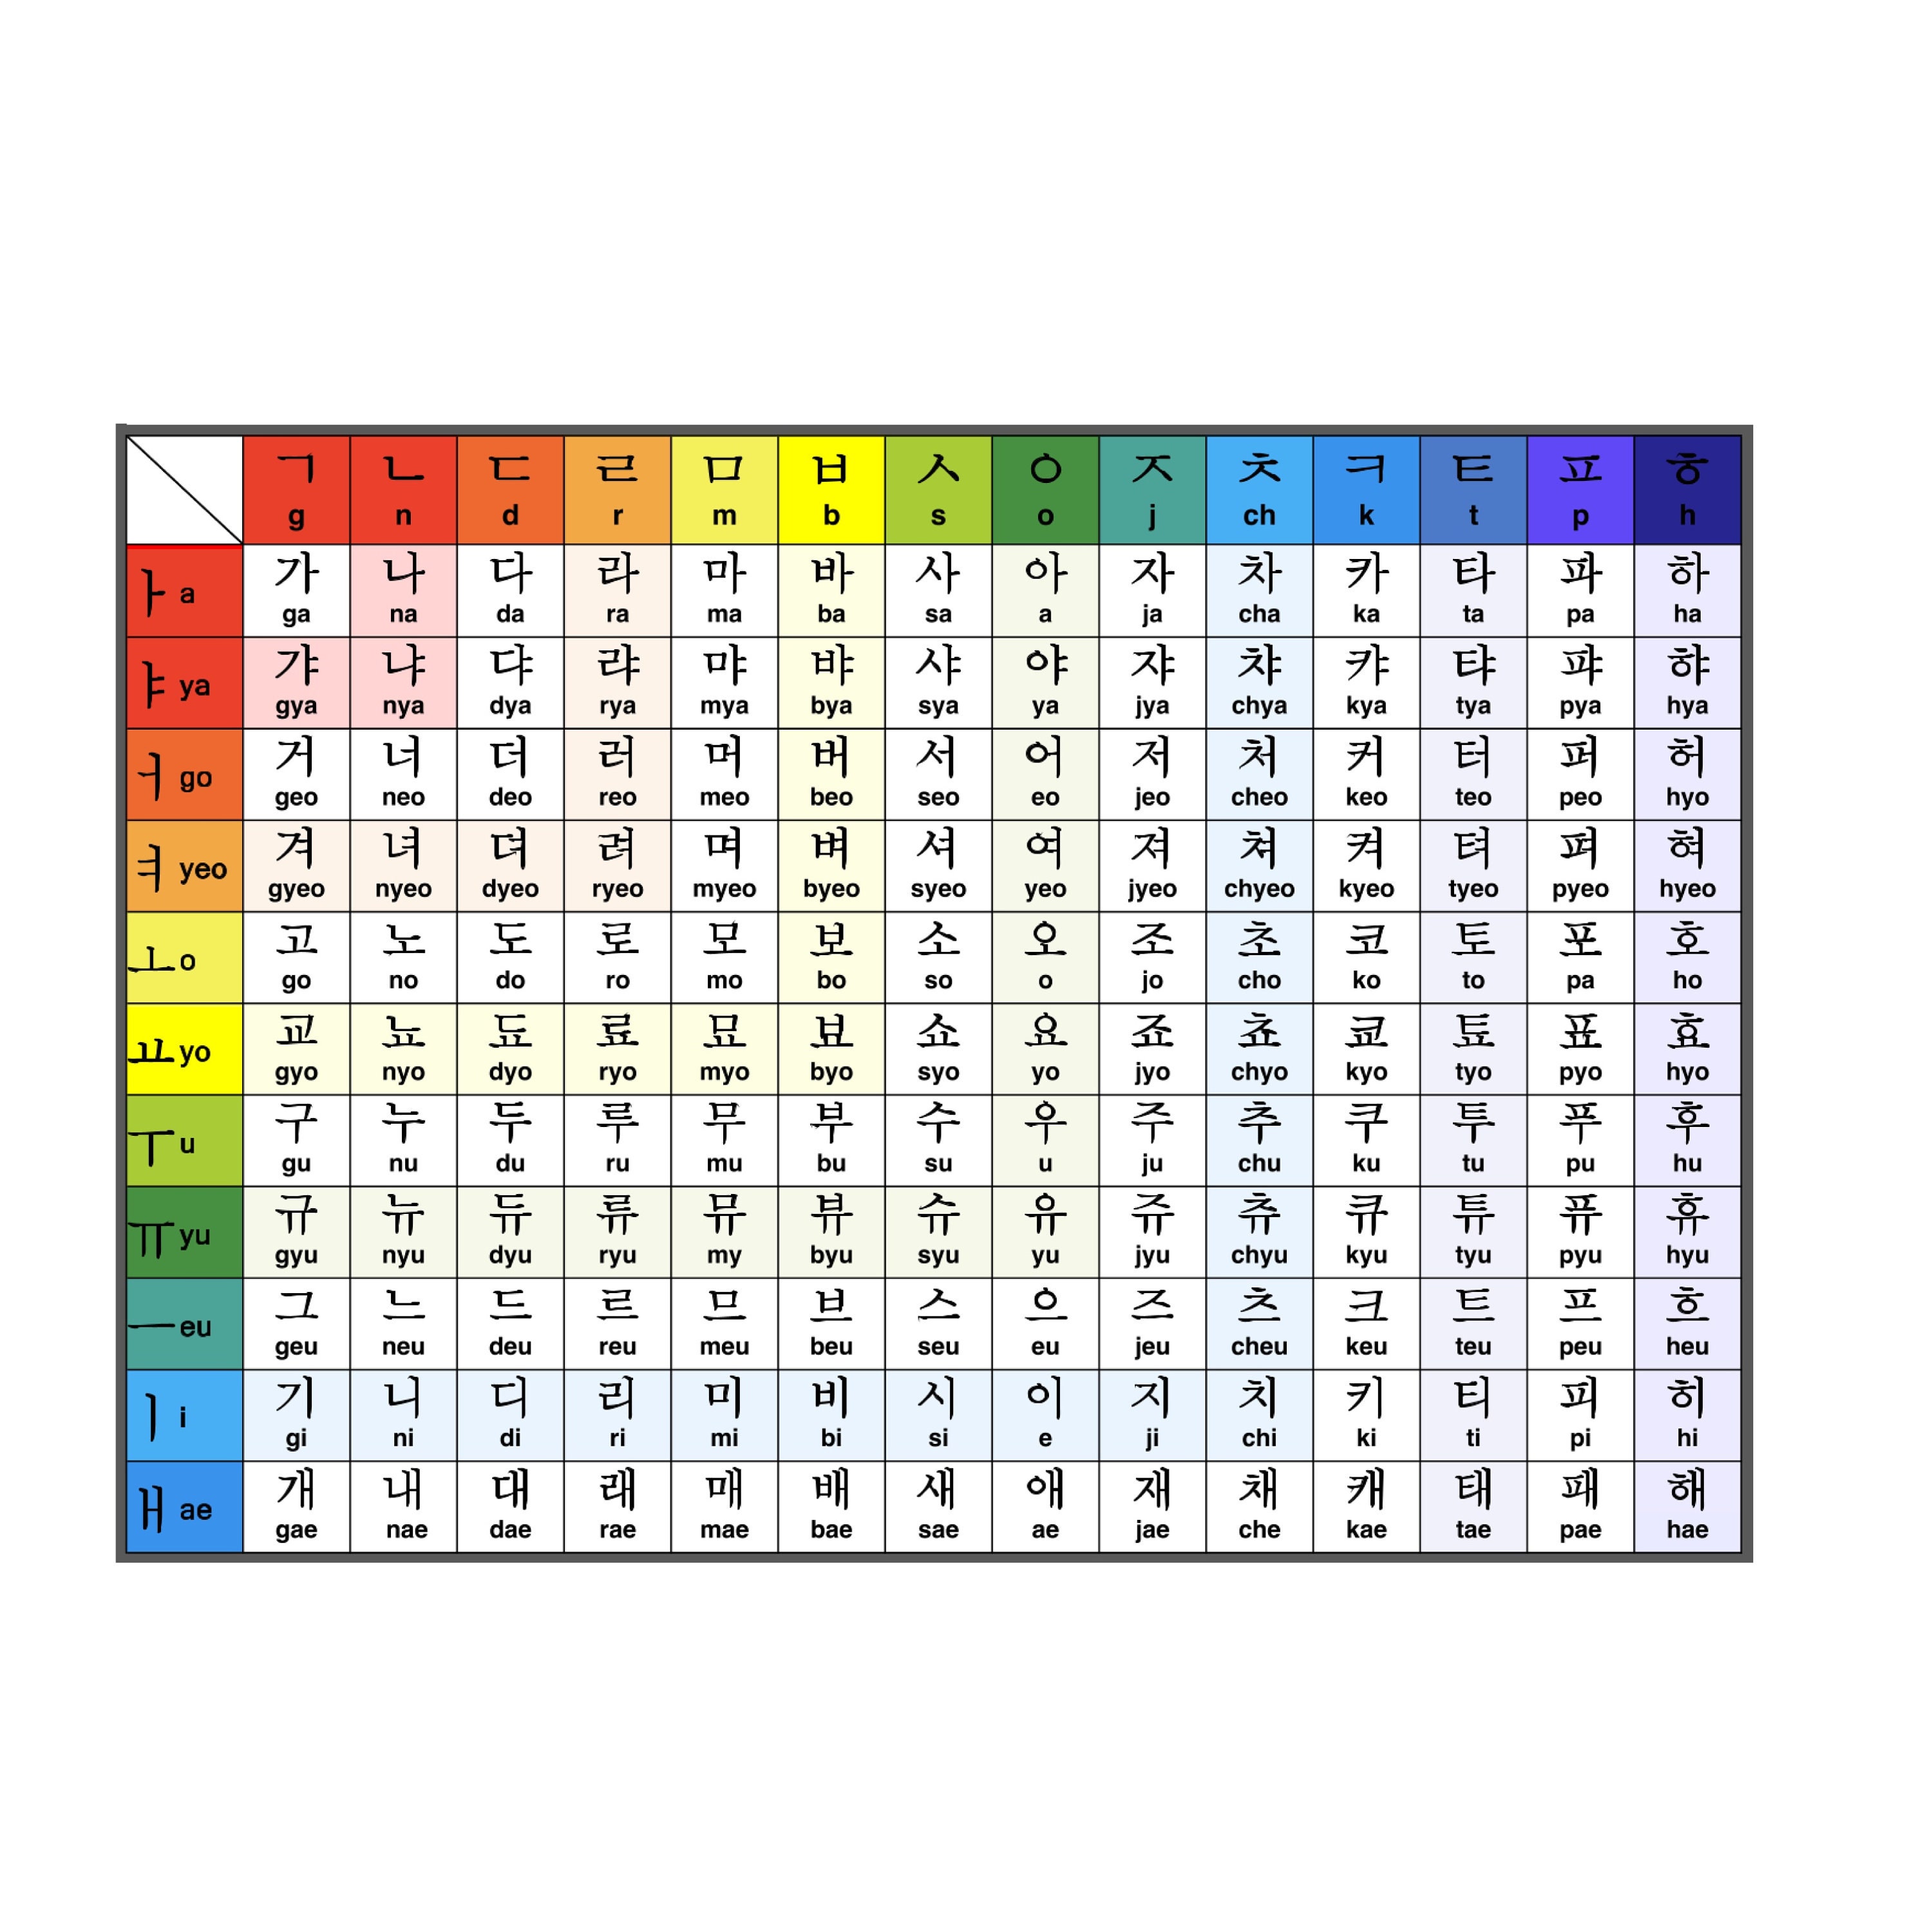
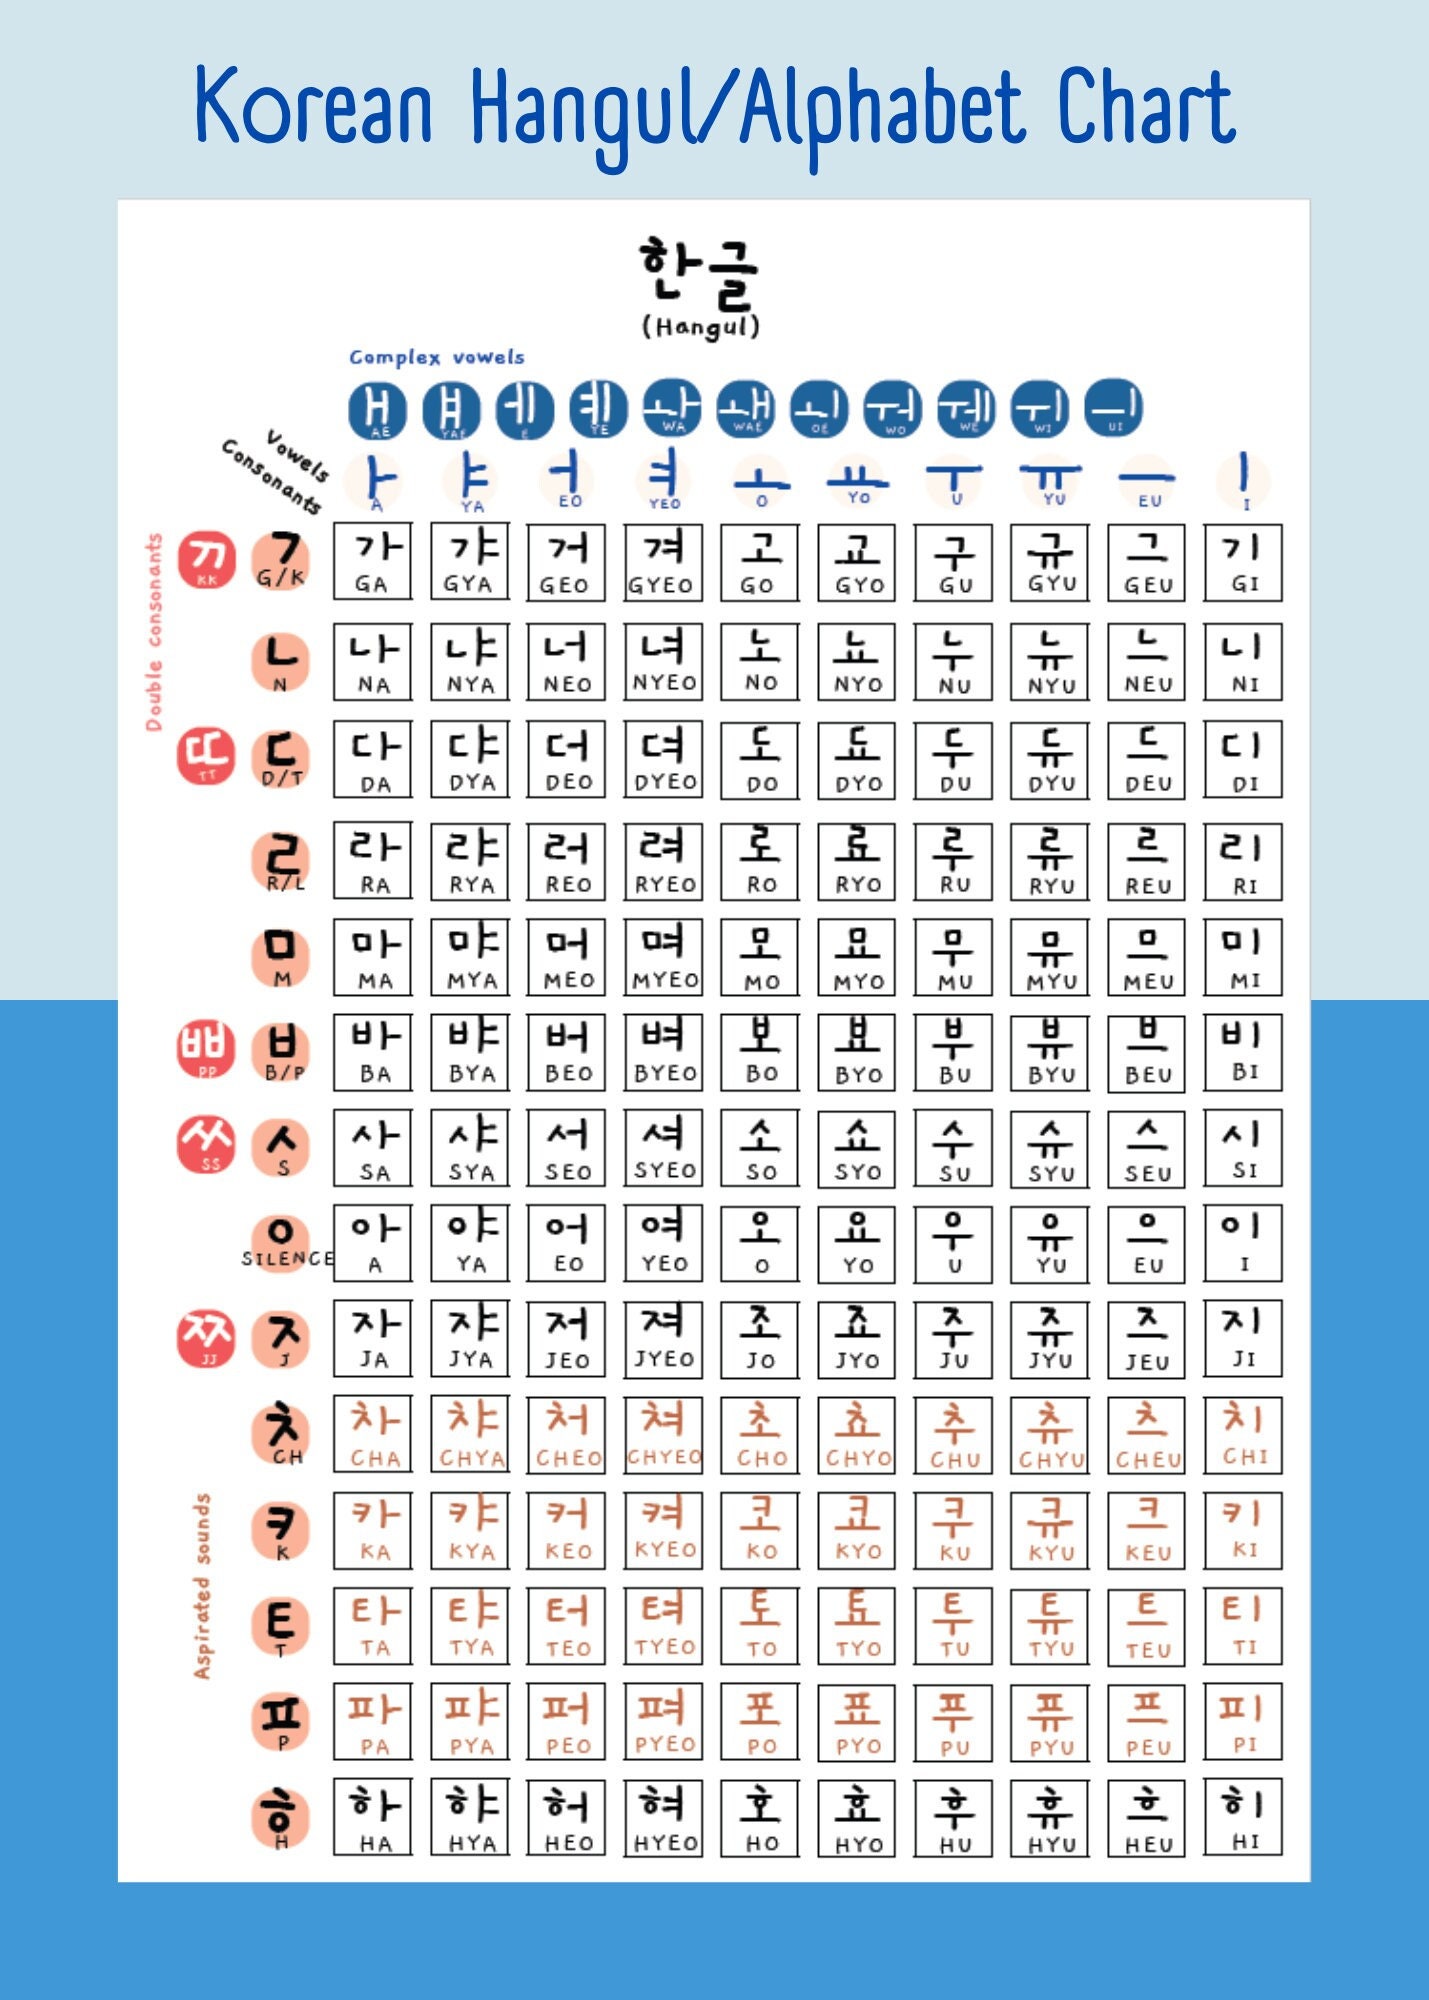
The Korean alphabet, officially called Hangul, was created in 1443 during the reign of King Sejong the Great. It is a featural writing system where letters are arranged into syllabic blocks. Each block represents one syllable, and the shapes within that block show exactly which consonants and vowels are used and where they sit relative to each other. The system itself is highly logical, but actually working with it in practice introduces a few quirks that nobody tells you about until you run into them. Here is how the core chart looks when you strip away the decorative explanations and just map the components. Basic Consonants (14)
/ / / / / / / / / / / / / Basic Vowels (10) / / / / / / / / /
Doubled Consonants (5) / / / / Complex Vowels (11)
Get the Full Details
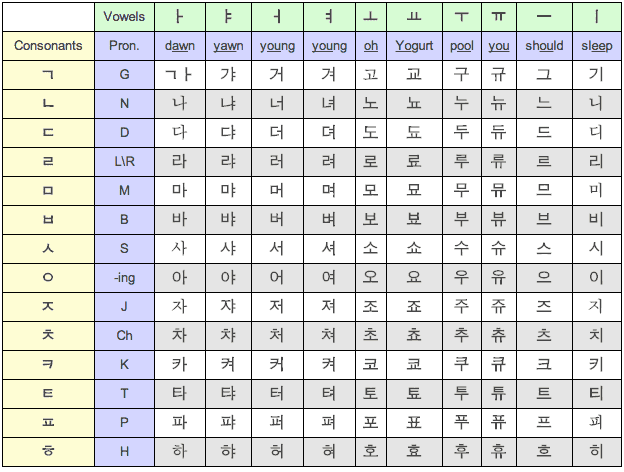
/ / / / / / / / / / / Final Consonants (Jongseong) (7) The basic consonants double as final consonants with a few additions: / / / / / / / / / / / / / / / /
That is roughly the full set you will encounter in standard modern Korean. The system uses 24 basic letters combined into square blocks. One block equals one syllable. A two-syllable word like is two blocks sitting side by side, not a continuous script that flows like Arabic or cursive handwriting.
How the Blocks Are Constructed
The way you read these blocks matters more than memorizing the characters in isolation. Each block follows a positional pattern: a consonant goes on the left or top, a vowel follows on the right or bottom, and if there is a final consonant it tucks underneath the whole group. The vowel choice determines whether the consonant sits to the left or above it. Vertical vowels like , , , , and stack to the right of the consonant. Horizontal vowels like , , and sit below it. Take the syllable . The consonant is on top, the vowel runs down the right side, and there is no final consonant here. Now take . The is on the left, the is on the right, and the sits below the entire block. That under-position is the jongseong slot. You will see it constantly, and it is where most beginners stumble because they try to read it like a linear alphabet instead of a spatial layout.

Practical Application and Common Problems
I spent months dealing with a specific issue when I first started building tools that processed Korean text. I was working on a system that needed to split compound words at syllable boundaries for tokenization, and I kept getting wrong results on words with batchim, the final consonant position. My regex would match any Hangul block and assume the last character was a vowel, which failed whenever a syllable had a true final consonant like in where the last block ends with , not a vowel on its own. The real problem was deeper than a simple character check. I needed to look at whether the Unicode code point had a jongseong value embedded in it, which meant decomposing each character with Unicode normalization (NFD) and checking the decomposition map. The workaround was to stop treating Hangul blocks as single opaque characters and start using Python's unicodedata module to decompose them. Once I mapped each block to its constituent jamo components, the splitting logic worked cleanly. I ended up writing a small helper function that returned the initial consonant, medial vowel, and final consonant for any given syllable. That cut our error rate from about 18% down to near zero on Korean-only text. The fix took me roughly three hours to implement and test after I had wasted about two days chasing the wrong approach.
Counter-Intuitive Details Most Beginners Miss
One thing that does not come up often enough is how the silent works. It has two roles depending on where it appears in a block. At the beginning of a syllable it is completely silent and acts as a placeholder to give the vowel a home, so starts with sitting alone and the is invisible in pronunciation. But in the final consonant slot it represents the sound /ŋ/, the same sound as the ng in sing. This dual behavior trips people up because it looks like the same letter but functions as two entirely different things. Another thing worth noting is that the official romanization system, the Revised Romanization of Korean from 2000, does not map 1-to-1 with pronunciation. and both romanize close to ae and e respectively, but in many dialects they sound nearly identical. The chart you study will show them as distinct, and that distinction matters for spelling but rarely for listening comprehension in casual speech. The Featural design is elegant for learning the characters, but it is not perfectly suited for all technical work. One real bottleneck is the difference between Jamo and syllabic blocks in Unicode. The Hangul syllables occupy a huge range of code points from U+AC00 through U+D7AF. If you try to iterate character by character expecting single letters, you will hit blocks that contain multiple phonetic components encoded into one code point. Some systems handle this by forcing decomposition, which works fine for most cases but can corrupt composed forms that are intentionally pre-composed for legacy data. Another limitation is that the alphabet chart alone does not cover honorific and casual speech markers, verb conjugation patterns, or the way certain final consonants change pronunciation depending on the following sound. You can memorize every block in the chart and still struggle with reading natural text at speed because the actual written form hides a lot of the phonological variation that happens in real speech. If you need reliable processing of Korean text for anything beyond basic character recognition, I would recommend pairing your knowledge of the chart with a proper segmentation library like Mecab or Komoran rather than rolling your own splitter. Those tools handle the morphological complexity that the alphabet chart simply does not encode. The chart is a foundation, not the whole building.
How to Use This in Practice
Start by learning the basic consonants and the ten core vowels in isolation, then move quickly into block construction. Practice writing blocks by placing the consonant first, then adding the vowel in the correct position based on whether it is vertical or horizontal. After that, add the final consonant slot and work through simple words until the spatial logic becomes automatic. The initial phase usually takes two to three weeks of daily practice if you spend about twenty minutes per session. After that, reading speed improves quickly because the blocks start functioning as visual units rather than sequences of individual letters. The biggest mistake people make is treating Hangul like a phonetic alphabet where every character has one fixed sound regardless of position. It does not work that way. The same jamo shifts slightly depending on whether it is an initial, medial, or final position, and some sounds change entirely before certain other sounds. The chart you study is accurate for citation forms, but real Korean text demands awareness of those positional variations. Knowing that exists saves you from wasting time wondering why something sounds different from what the chart promised.