Using Chat GPT for Data Science Work
Data science projects involve a lot of repetitive coding work, and Chat GPT has become a practical tool for handling portions of that workload. I don't use it for everything, but I rely on it for specific tasks where speed matters more than originality. The trick is knowing what to delegate and what to keep under your own control. Most people treat it like a magic code generator. That approach works until it doesn't, and then you're debugging hallucinated functions at 11 PM. Here's what it actually feels like. You have a messy CSV file, a thousand rows, columns with inconsistent formatting, and a deadline tomorrow morning. You paste the problem into Chat GPT and ask it to write a Python script using pandas to clean the data. It gives you something that runs, maybe, but the column names are slightly wrong or the date parsing fails on a edge case from 2019. You fix those issues yourself. That's the realistic workflow. It cuts setup time roughly in half but still requires someone who knows what they're doing to verify the output. I remember a project last year where I was building a feature engineering pipeline for a churn prediction model. I asked Chat GPT to generate the code for encoding categorical variables with high cardinality. It gave me a standard one-hot encoding solution, which would have created nearly four hundred new columns. That would have blown up memory and training time. Instead, I used target encoding with smoothing, which I had to describe explicitly in my prompt. The model itself has no sense of when a solution is wasteful, only when it's structurally correct.
Where It Actually Helps
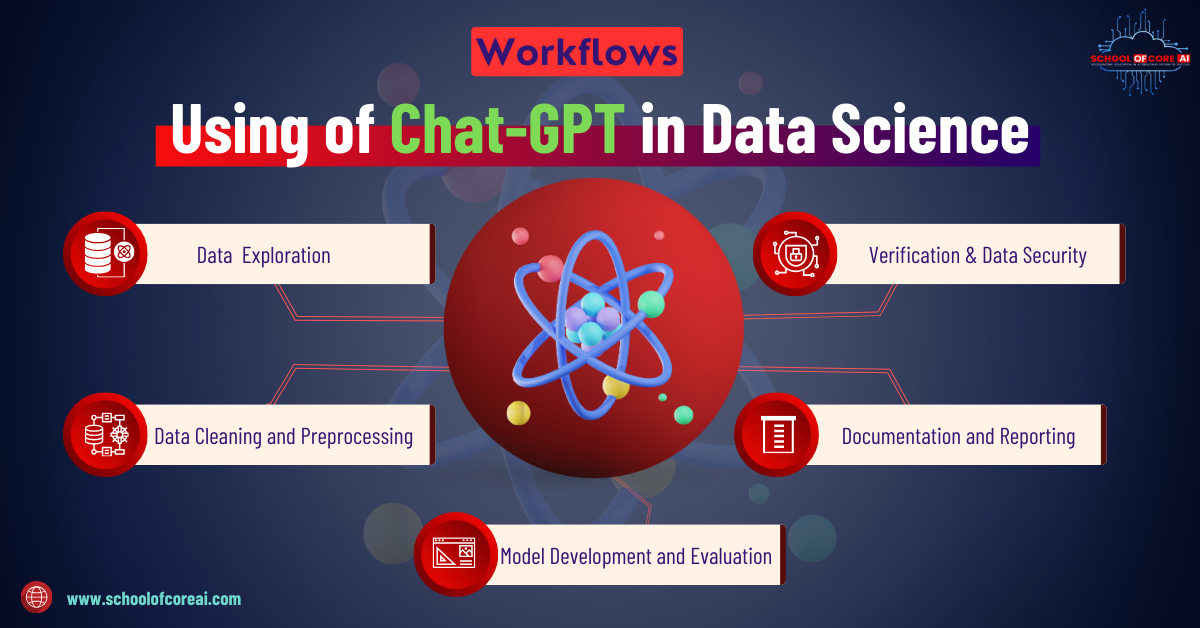
Writing boilerplate code is the low-hanging fruit. If you need a standard data validation check, a quick EDA notebook scaffold, or a basic visualization, Chat GPT can produce working code in seconds that would normally take fifteen to twenty minutes to write from scratch. For someone going through five hundred lines of regression output to extract coefficients and p-values, it can format that into a clean table much faster than manual copy-paste. Debugging is another area where it saves time. Paste an error traceback, describe what you expected to happen, and it will often identify the issue within a couple of prompts. I've had it catch off-by-one errors in indexing, mismatched DataFrame shapes, and forgotten import statements. The cost here is that you still need to understand the error well enough to confirm the fix is correct, otherwise you're just replacing one broken thing with another. Documentation and explanation are surprisingly useful. When a junior on the team asks what a particular algorithm does, or when you need to write a brief explanation of your methodology for a stakeholder report, Chat GPT can draft something reasonable that you then edit down to accuracy. It won't replace your judgment on technical content, but it moves you from a blank page to a starting point.
Where It Fails Completely
It cannot reliably handle novel data problems without significant human guidance. Every dataset is slightly broken in its own way. Column headers with special characters, missing values encoded inconsistently across sheets, dates in multiple formats within the same column, and so on. The model generates code based on patterns it has seen before, not on an actual understanding of your data. If you feed it a non-standard format without describing the specifics, it will confidently produce incorrect results and you won't know until the model starts training and the loss curve looks wrong. It also has a tendency to invent libraries, parameters, and functions that don't exist. I've seen it suggest a pandas function called df.normalize() that was completely fabricated. It sounds plausible. The documentation it generated for it was internally consistent. It doesn't exist. You have to verify anything that looks unfamiliar against actual documentation, which defeats some of the time savings if you're spending more time fact-checking than writing the code yourself. Sensitivity to version changes is another issue. Code that worked on Python 3.9 and pandas 1.5 may break on newer versions, and Chat GPT sometimes writes code assuming a specific environment without mentioning it. If you're working in a constrained production environment, always test generated code in that exact environment before integrating it.
Get the Full Details
A Practical Workflow That Works
Start by isolating the sub-problem. Don't paste an entire notebook and ask it to fix everything. Break your task into discrete steps and prompt for each one separately. Give it the schema of your data, specific column names, known edge cases, and the exact output format you need. The more context you provide upfront, the fewer iterations you'll need. Always run generated code in an isolated cell first. Jupyter notebooks make this easy. Verify each block produces what you expect before moving on. If something fails, paste the error message back into the model along with the relevant code. Two or three turns usually resolves most issues, but if you're stuck after five attempts, step away and write it yourself. You'll be faster. For anything involving sensitive data, don't paste raw customer information or proprietary datasets into any chat interface. Anonymize or synthesize your data first. I use a quick script to replace real values with representative fake data, then feed that to the model. It takes about three minutes and eliminates a real risk.
Keep a personal library of prompts that work for your common tasks. Over time you'll notice patterns in how you describe problems and what level of detail gets good results. A well-crafted prompt for generating SQL queries from a schema will look very different from one asking for a random forest implementation. Treat prompt engineering as part of the workflow, not an afterthought. The bottom line is that Chat GPT Data Science workflows are most effective when you treat the model as a junior colleague who knows a lot of patterns but occasionally makes confident mistakes. You provide the direction and the verification. It handles the parts that are repetitive and tedious. Together, you finish faster than either of you would alone, but the responsibility for correctness stays with you.