
The actual mechanics behind making LLMs hold a conversation
Most people treat chat optimization as if there's some magic parameter you flip and suddenly your model starts behaving. It's not like that. There are distinct training stages, each serving a different function, and getting them mixed up is the most common mistake I see when teams try to build a production chat system. Let me start with what I learned the hard way. A few months back I was tuning a model for a customer support pipeline and noticed something weird — the model would give excellent single-turn answers, but by turn three of a conversation, its formatting would collapse entirely. It started ignoring system instructions, repeating itself, and occasionally dropping lowercase headers mid-sentence like it had forgotten its own structure. We spent two days chasing template issues before someone suggested the problem wasn't the prompt at all. It was that the base model had never been exposed to multi-turn dialogue during fine-tuning. The fix was simpler than expected but expensive: we restructured the training data to include 60% multi-turn examples instead of single-turn, which added about two weeks to our training pipeline and roughly $4,000 in compute. The behavior stabilized after that.
Understanding Chat Gpt Optimizing Language Models For Dialogue
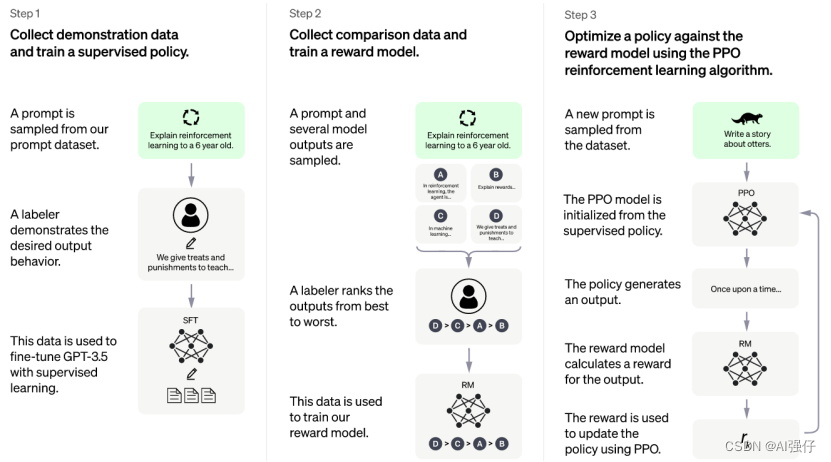
Optimizing for dialogue really comes down to three separate steps, each addressing a different failure mode. Instruction tuning is the foundation. This is where you take a base model and train it on input-output pairs formatted as instructions. You feed it thousands or millions of examples like "Write a Python function that sorts a list" paired with the correct function. The model learns the pattern of following directions rather than just predicting the next word. Without this step, any system prompt you write is fighting against a model that has no concept of being instructed. This stage typically requires around 10,000 to 100,000 high-quality examples depending on model size, and you can expect inference latency to increase by 15 to 30 percent compared to the raw base model. Conversational fine-tuning builds on that by teaching turn-taking behavior. The model learns that a response is an ending, not a midpoint, and that it should wait for the next user input. This is where you address the specific problem I described above. The data format changes from single instruction-response pairs to sequences like user-turn, assistant-turn, user-turn, assistant-turn. The key detail most people miss is that you should include the full conversation history in the training samples, not just the last exchange. If you only show the final turn, the model won't learn to reference earlier context properly. A typical dataset for this stage runs 50,000 to 200,000 examples for a small model and scales up from there.
RLHF and its alternatives come last. This is where you teach preference alignment — not just whether a response is correct, but whether it's the kind of response you actually want. The traditional approach involves collecting human ratings of model outputs and training a reward model on those ratings, then using PPO or a similar algorithm to shift the language model toward higher-reward responses. The alternative that has gained traction is DPO, or Direct Preference Optimization, which skips the separate reward model entirely and directly optimizes the policy model using preference pairs. DPO typically converges faster and requires less computational overhead than full PPO-based RLHF, though it can struggle with certain types of preference data that contain conflicting signals.
Get the Full Details

The stuff that actually matters in practice
Here is what the textbooks leave out. The biggest factor in conversational quality is rarely the algorithm you choose for fine-tuning. It's the quality and structure of your training data. I've seen teams spend weeks tuning hyperparameters on mediocre data and get worse results than a quick fine-tune on clean, well-curated examples. The rule I follow is that one high-quality example is worth roughly fifty low-quality ones. By high-quality I mean examples where the response demonstrates reasoning, handles edge cases correctly, stays within the requested format, and doesn't hallucinate facts. By low-quality I mean examples that are either too simplistic, contain errors, or don't match the actual use case you're building for. Another counter-intuitive point: more context isn't always better during dialogue optimization. When I've fine-tuned models with extremely long conversation histories in the training data — say, 20 or 30 turns — the model actually becomes worse at maintaining coherence in shorter conversations. It starts over-explaining and padding responses because it learned to expect extended back-and-forth. The sweet spot for most production systems is training on conversations that average five to twelve turns. Anything longer introduces noise that doesn't translate to your actual deployment scenario.
There's also the issue of catastrophic forgetting, which is exactly what it sounds like. When you fine-tune a model heavily for dialogue, you can degrade its general reasoning capabilities. I've seen models that became excellent at holding conversations but lost their ability to perform basic math or logical deduction. The typical mitigation is to mix your dialogue data with a portion of general-purpose training data — somewhere between 20 and 40 percent — so the model retains its foundational skills while learning conversational behavior.
When it doesn't work and what to do instead
Optimizing language models for dialogue through fine-tuning has real limitations. It is expensive. A well-executed fine-tuning pipeline for a mid-sized model can cost between $5,000 and $50,000 in compute depending on model size, dataset scale, and number of training iterations. It is also fragile to distribution shifts. If your training data covers formal customer service interactions and your production system encounters users writing in casual slang with heavy abbreviations, the model will still respond formally and often incorrectly, because it was never exposed to that variation during training. Another hard limit: fine-tuning cannot fundamentally increase a model's knowledge. If your base model doesn't know about a specific topic area, fine-tuning won't teach it. The model can learn to talk about the topic more conversationally, but it can't generate accurate information it never had access to. For knowledge gaps, you need retrieval-augmented generation, not fine-tuning. If your budget or timeline doesn't support full fine-tuning, there is a viable alternative that handles many dialogue optimization needs without the compute cost. You can achieve significant conversational improvement through prompt engineering alone — specifically by crafting system prompts that define conversational style, response length, formatting rules, and behavioral constraints. Combined with a well-structured few-shot prompt that includes three to five example dialogues demonstrating the desired behavior, this approach can approximate much of what fine-tuning provides at a fraction of the cost. The main limitation is that prompt-based optimization struggles with nuanced style transfer across diverse conversation topics, whereas fine-tuning internalizes the behavior more robustly.

What to watch for after deployment
The conversation doesn't end when the model ships. Dialogue-optimized models tend to exhibit drift over time, particularly when users discover new ways to interact with them that weren't in your training data. I recommend tracking conversation length distribution, response format adherence rates, and a simple satisfaction metric on at least a sample of interactions. If you see response lengths trending upward or format compliance dropping below 80 percent, that usually indicates the model is encountering novel conversation patterns it wasn't trained for, and you may need to update your fine-tuning data with real conversation samples from production. For implementation, the typical workflow involves preparing your dataset in the appropriate format for your chosen framework — Alpaca format, ShareGPT format, or instruction-tuning format depending on whether you're using tools like Hugging Face's TRL library or a custom pipeline. You then split the data, run the fine-tuning job, evaluate on a held-out set of conversational examples, and deploy. The evaluation step is critical and frequently skipped. Without testing on examples that weren't in your training set, you have no way of knowing whether the model actually generalized or simply memorized the training data.
.jpg "ChatGPT: Optimizing Language Models for Dialogue | OpenAl Tool | ChatGPT Usage step by step")
